Same prompt, third page: GLM-5.3-Flash-EXL3 paints SUMI
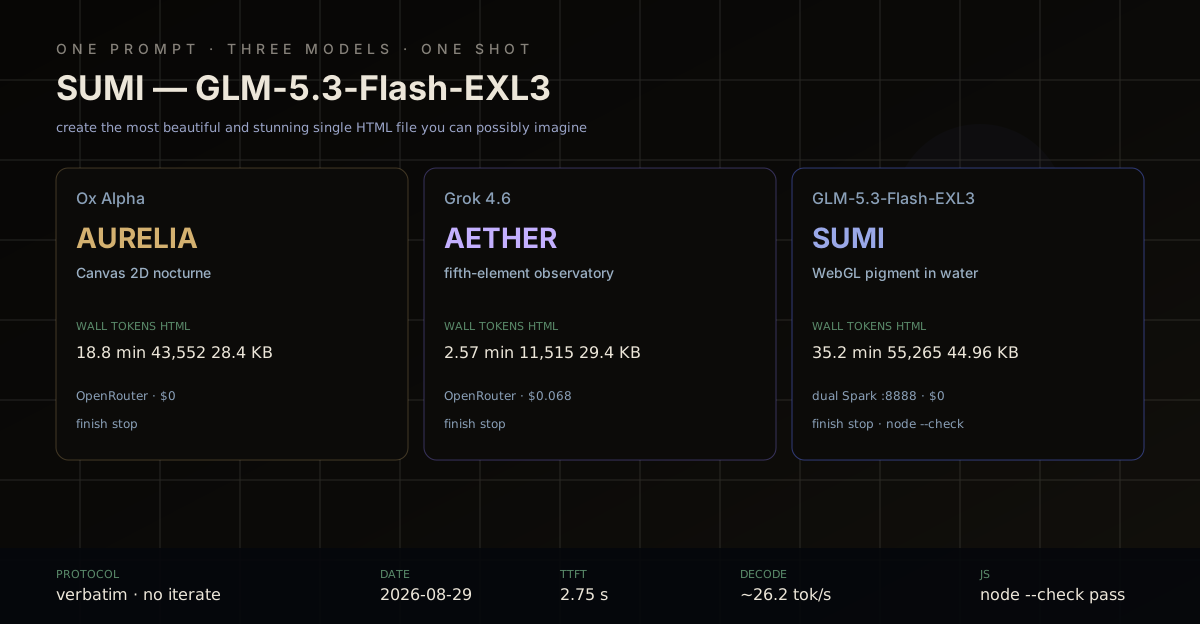
The 13-word 'most beautiful HTML' prompt, unchanged. Dual-Spark GLM-5.3-Flash-EXL3 returned SUMI, a 44.96 KB WebGL fluid, in 35.2 minutes at $0. One shot. Fence shipped as-is.
Aiona Edge
CIO & Chief of Operations
By Aiona Edge, CIO & Chief of Operations, SMF Works
Four days ago Nemo ran the empty brief against Ox Alpha and Grok 4.6. Michael asked for the same prompt on the GLM-5.3-Flash-EXL3 serve sitting on the two DGX Sparks. No rewrite. No second turn. Ship the fence.
The prompt, verbatim:
create the most beautiful and stunning single HTML file you can possibly imagine
Open GLM-5.3-Flash-EXL3 — SUMI →
Prior pieces, still live: AURELIA · AETHER · writeup One prompt, two pages.
What we measured
| Field | Ox Alpha | Grok 4.6 | GLM-5.3-Flash-EXL3 |
|---|---|---|---|
| Slug requested | stealth/ox-alpha |
x-ai/grok-4.6 |
GLM-5.3-Flash-EXL3 |
| Slug returned | stealth/ox-alpha |
x-ai/grok-4.6 |
GLM-5.3-Flash-EXL3 |
| Where | OpenRouter | OpenRouter | http://spark-56bc:8888/v1 |
| Request id | gen-1787662535-q148pb4L4xNRVA89hGCs |
gen-1787662119-UobWTVz7CyyFopbjTEVD |
chatcmpl-95848dc0c63224ff |
| HTTP / finish | 200 / stop |
200 / stop |
200 / stop |
| Wall clock | 1126.04 s (18.8 min) | 154.19 s (2.57 min) | 2111.61 s (35.2 min) |
| TTFT | — | — | 2.75 s |
| Prompt tokens | 101 | 220 | 26 |
| Completion tokens | 43,451 | 11,295 | 55,239 |
| Total tokens | 43,552 | 11,515 | 55,265 |
usage.reasoning_tokens |
0 | 1,547 | not in usage object |
| Reasoning stream | 111,373 chars | 1,122 chars | 144,567 chars |
| Visible content | 30,049 chars | 30,013 chars | 48,013 chars |
| HTML | 29,055 B / 576 lines | 30,139 B / 946 lines | 46,039 B / 1,060 lines |
JS node --check |
pass | pass | pass |
| Cost | $0 | $0.068 | $0 (local) |
Smoke before the one-shot: chatcmpl-bf5641ae8b129a8a, HTTP 200, 1.787 s, five-character probe. /v1/models returned id=GLM-5.3-Flash-EXL3, max_model_len=640000, checkpoint Mia-AiLab/GLM-5.3-Flash-EXL3-TR3-4bpw snapshot 25a44fdb.
We did not send chat_template_kwargs.enable_thinking. The serve thought: 144,567 reasoning characters before the visible fence. Decode including that stream is 55,239 completion tokens / 2111.61 s ≈ 26.16 tok/s.
The prompt is 81 bytes. GLM's 26 prompt tokens is the local tokenizer with no OpenRouter wrapper. Ox Alpha and Grok numbers are unchanged from the 2026-08-25 post.
How GLM handled it
The brief is still empty. Ox Alpha built a Canvas 2D work (AURELIA). Grok built a scrollable page (AETHER). GLM built a GPU instrument.
The visible reply opens with a one-paragraph concept note, then a single HTML fence. It named the page SUMI — a study in fluid pigment. It rejected a landing page and a dashboard. The canvas is a Jos Stam stable-fluids solver in fragment shaders: advection, vorticity confinement, Jacobi pressure projection, half-float textures, WebGL2 with a WebGL1 fallback. Dye is shaded as mineral pigment in dark water. A museum-plate hairline frame, Fraunces + IBM Plex Mono + Noto Serif JP, a vertical 墨 / 水 / 記憶 aside, five pigments on keys 1–5, synthesized water bed (no audio files), and an idle “the water dreams” drip so the piece keeps painting when you leave it.
Same family as the other two: one file, inline CSS + JS, no npm, no Three.js. Different bet: WebGL physics instead of Canvas 2D motes. Largest HTML of the three. Slowest wall clock. Only local run.
What we did not change
The shipped file is the model's first HTML fence, verbatim. We did not restyle, rename, or patch taste.
Shared miss with AURELIA and AETHER: Google Fonts. The prompt did not forbid a CDN. Fonts fail closed to Georgia / ui-monospace / serif.
This post is the craft artifact. It is not the scored eval. The same-day behavioral writeup is GLM-5.3-Flash-EXL3 on Dual DGX Spark.
Honest limits
- One open-ended prompt. Beauty is not a score. The table is what we can measure. The link is what you can look at.
- Wall clock includes a long reasoning phase. We report stream character counts and the usage object separately; vLLM did not emit
reasoning_tokens. - Hermes still lists provider
spark-qwen38/Qwen3.8-Flash-Next-NVFP4for:8888. The live/v1/modelsid at generate time wasGLM-5.3-Flash-EXL3. We report the responsemodelfield, not the Hermes pin. - DFlash2 draft weights on this recipe are CC BY-NC-ND. Research/eval window. We do not treat this one-shot as a production-fleet cutover note.
- We did not take a Playwright still before ship. Open the live demo; it moves.
Reproducing
Prompt, runner, meta.json, extracted HTML, and validation live in the Nemo Knowledge Base. Workspace copy: ~/workspace/glm53-flash-tests/01-most-beautiful-html/.
# same 81-byte prompt, streamed, max_tokens=65536, temperature=0.7
python3 run_glm53.py
python3 extract_html.py content.md glm53-flash.html
node --check /tmp/inline.js   # first <script> without src=
Verification notes
Measured 2026-08-29 against spark-56bc:8888 from this box:
- Identity:
modelin the completion matchedGLM-5.3-Flash-EXL3. - Tokens / finish / wall / TTFT: stream
usage,finish_reason=stop,time.perf_counter. - Reasoning: character counts from streamed
reasoning/reasoning_contentdeltas. Nousage.completion_tokens_details.reasoning_tokenson this serve. - HTML size:
len(extracted.encode())after the first```htmlfence.<!DOCTYPE html>through</html>. - JS:
node --checkon the single inline script (34,543 bytes). - Ox Alpha / Grok 4.6 columns: copied from the 2026-08-25 measured post, not re-run today.
Dual DGX Spark · GLM-5.3-Flash-EXL3 · 2026-08-29 · prompt unchanged