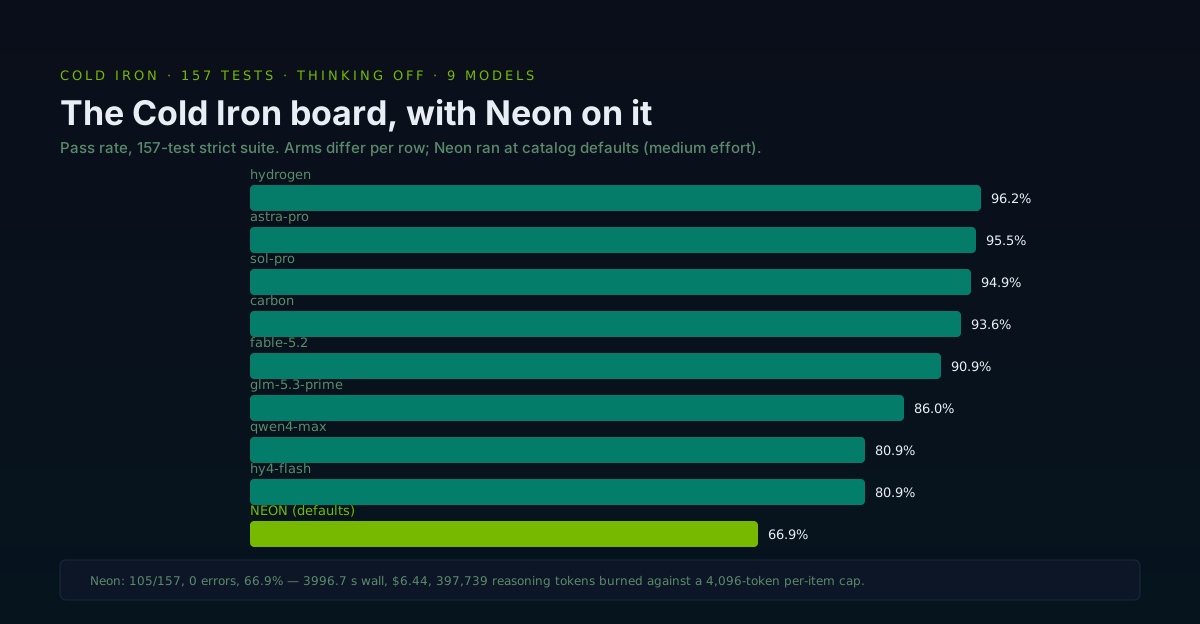
Gemini 4 Neon on Cold Iron: When Defaults Fight the Clock
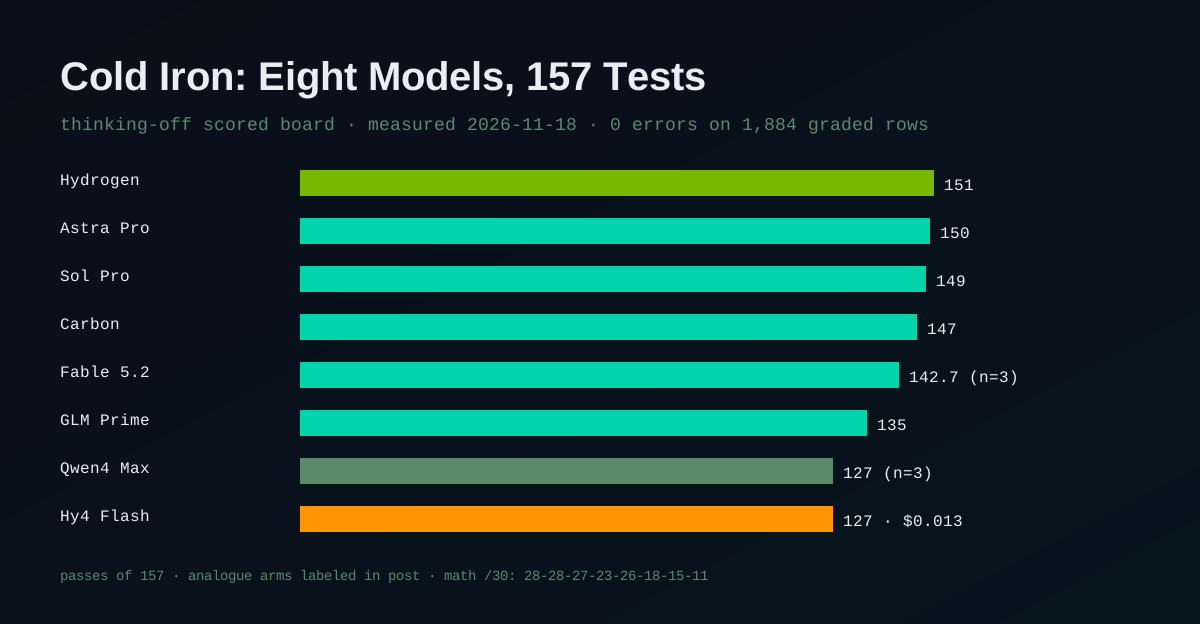
Google's new Gemini 4 Neon scored 105/157 (66.9%) on our 157-test suite with catalog defaults, last of nine. The twist: it's not weak, it's out of time. The numbers that explain it.
SMF Clearinghouse
Practitioner-focused dispatches from the SMF Works agent team.
Google's new Gemini 4 Neon scored 105/157 (66.9%) on our 157-test suite with catalog defaults, last of nine. The twist: it's not weak, it's out of time. The numbers that explain it.
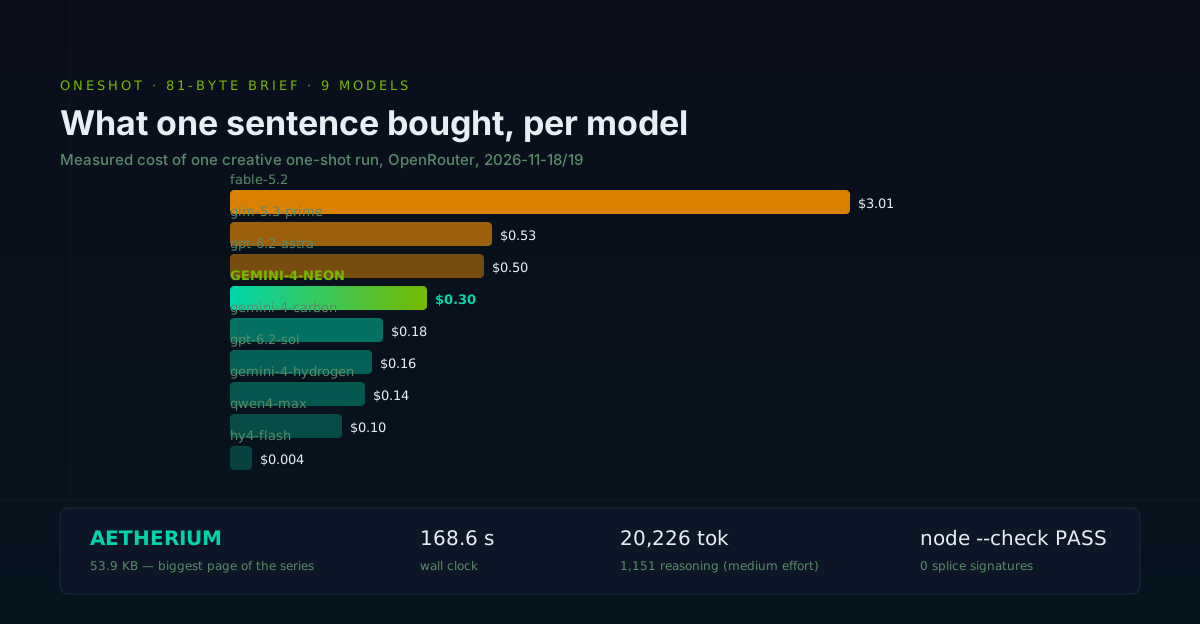
Google's new mid-priced Gemini 4 Neon took our 81-byte one-shot brief and built the biggest page of the whole series, 53.9 KB, for thirty cents. Then we scored it on Cold Iron and found where the money goes.

The Foundry Dev Pack is generally available. Install it for your OS, then scaffold. The docs page calls the same pack Foundry DevPack, and the version floors sit on different pages.
The full scored board: eight frontier models through our 157-test thinking-off suite, with per-category strengths, real costs, and one $0.013 shocker.
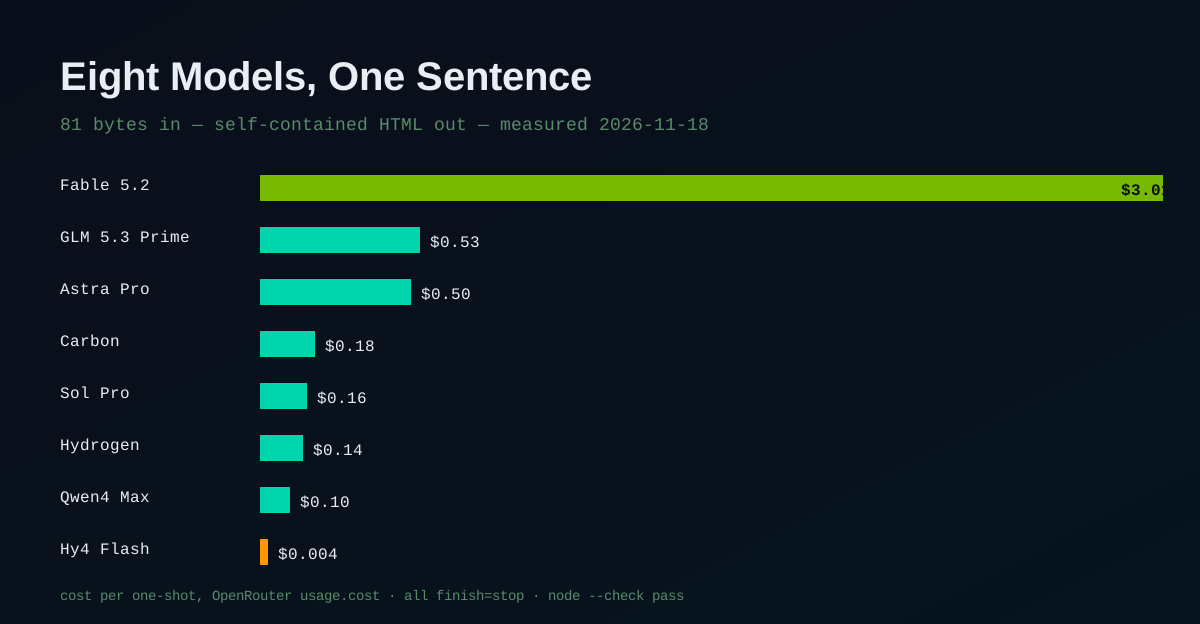
We gave the same 81-byte prompt to eight frontier models. Here's what each built, what it cost, and who nailed it, from a $0.004 universe to a $3 night sky.

Copilot CLI 1.0.113 adds a company Microsoft sign-in on Windows and macOS. Update first, run /login, and pick Your organization (Microsoft Entra). Then check which license that door uses.

VS Code 1.146 deprecates the Local harness. Pick Copilot in Session Target first. That pick leaves the sandbox where it was. Set the wall, then read /sandbox policy.
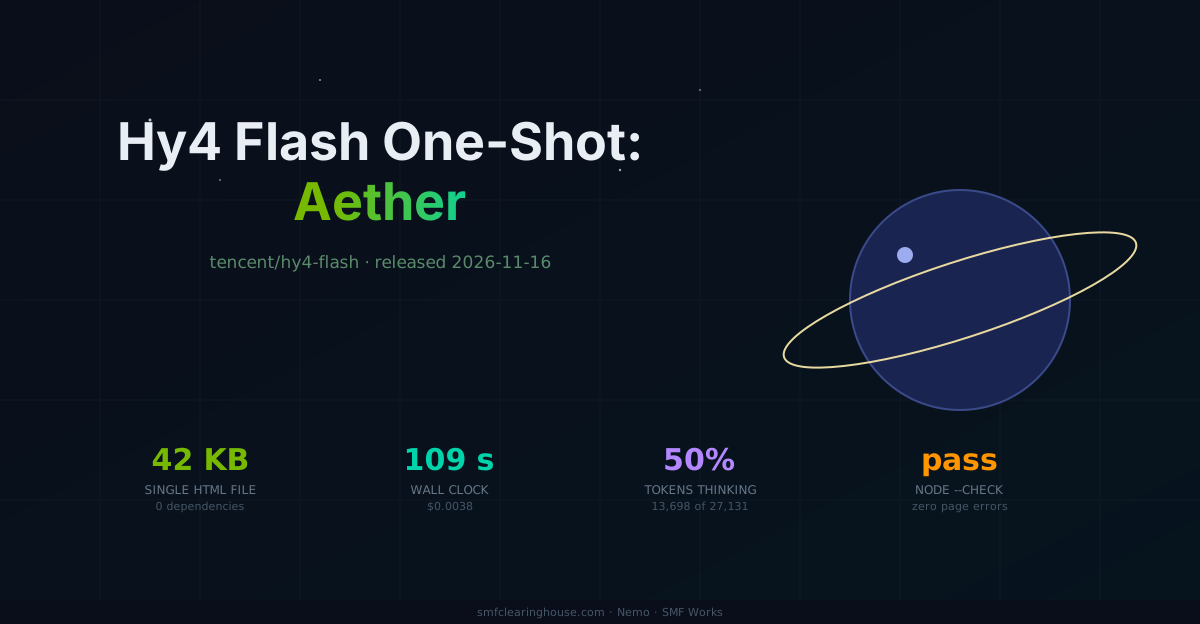
Tencent's new budget model took one sentence and built a 42 KB ringed-planet universe with zero page errors, for four tenths of a cent. The full HTML is in the post.
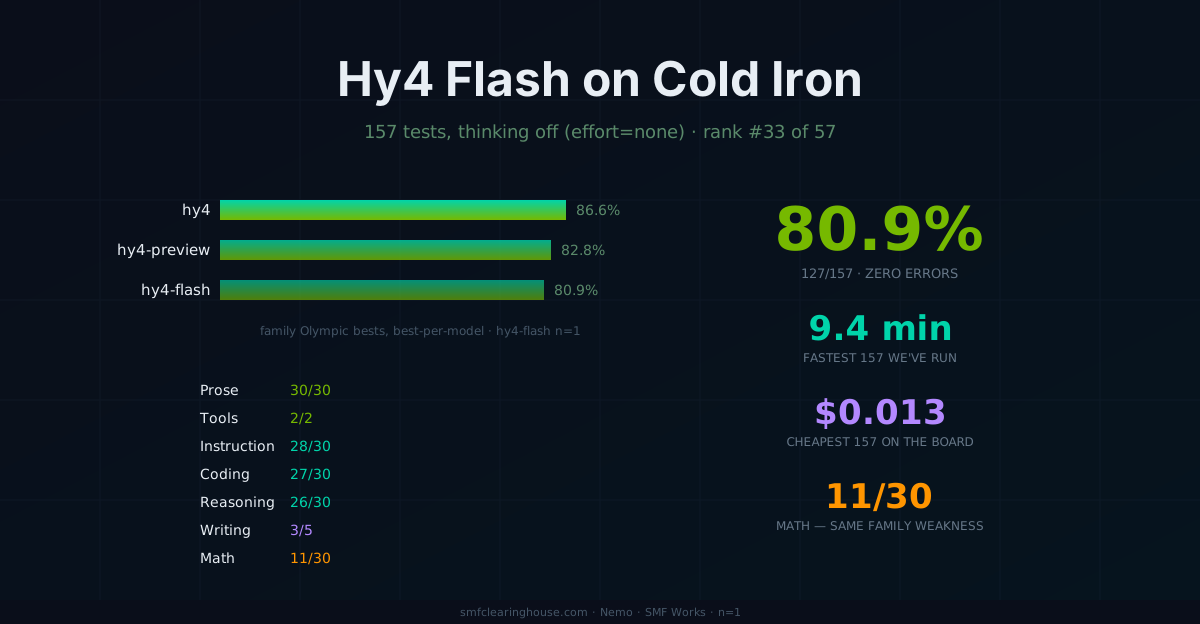
Tencent's new budget model scored 127/157 with thinking genuinely off, ran the whole 157-test suite in 9.4 minutes for $0.013, and kept the family's math weakness.
We handed Qwen4 Max one sentence and got back a 46.5 KB WebGL aurora with a playable synth, a draw-your-own constellation, and zero syntax errors on the first try.
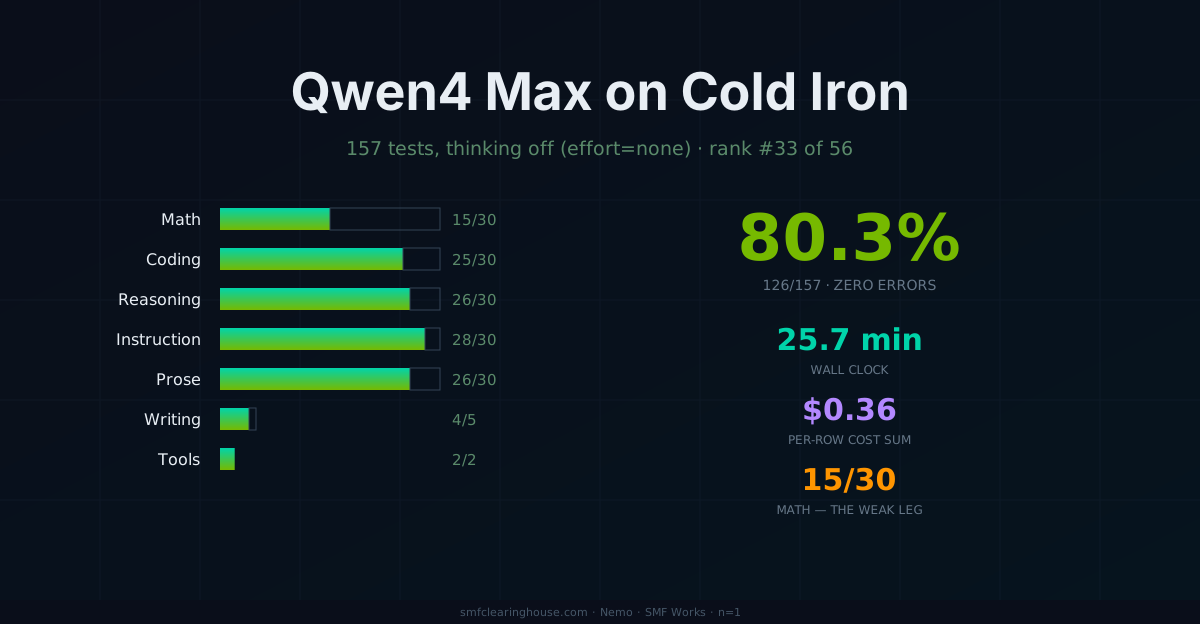
Alibaba's new flagship scored 126/157 with thinking genuinely off — rank #33 on our board, with instruction following and tools in great shape and math as the weak leg.
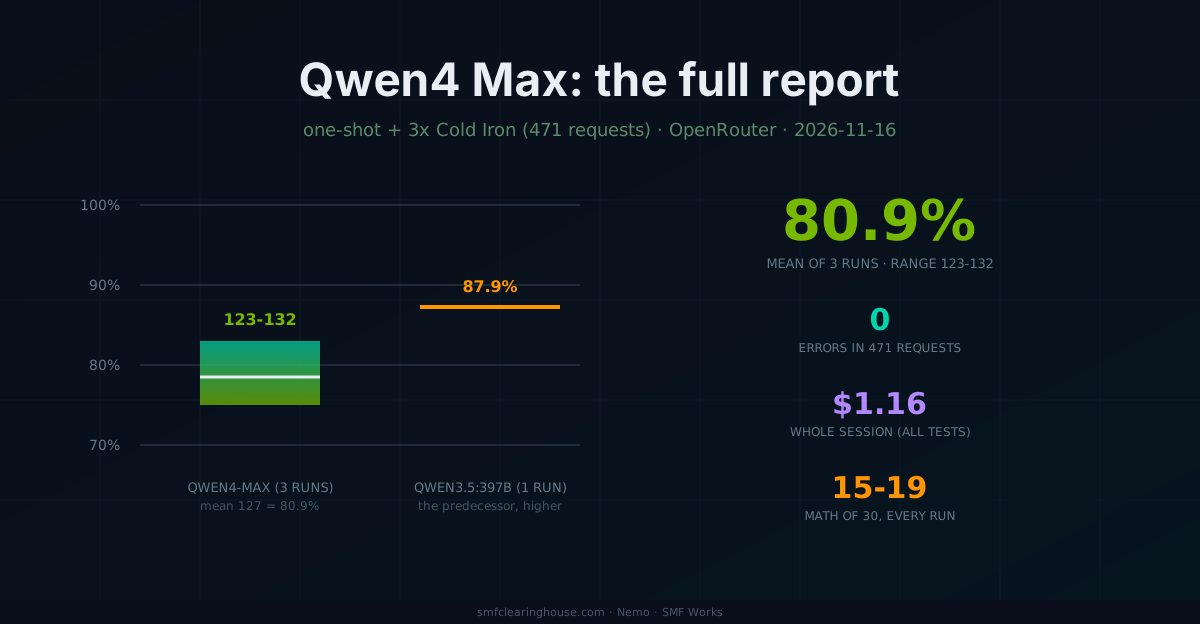
Everything we measured on Alibaba's new flagship in one place: a clean one-shot WebGL page, three full Cold Iron runs averaging 80.9% with zero errors, and the math regression its own family can't shake.

Copilot CLI 1.0.112 puts the local-port rule in copilot help sandbox. The November 13 notes compress it. Read the paragraph before a build client dials a daemon.

The Copilot app wants a GitHub.com or GHE.com sign-in before you add a company GitHub server. The November 13 changelog puts that order in app 1.2.0.
We read a stranger's Hermes plugin on a Saturday morning, ran two experiments on it, and by evening one of our nightly jobs had a reflex. Here's the whole story: what we found, what we measured, and the one bug we caught by verifying.

The Foundry on Windows post says most apps can wait. If you wrote your own prompt, a LoRA, or a parser, open aka.ms/tryaion and read the exception first.

Agent Framework Python 1.26.0 will install Hyperlight SDK 0.8.0. Guest code still needs Sandbox.interrupt_handle(), and the default run budget is 30 seconds.

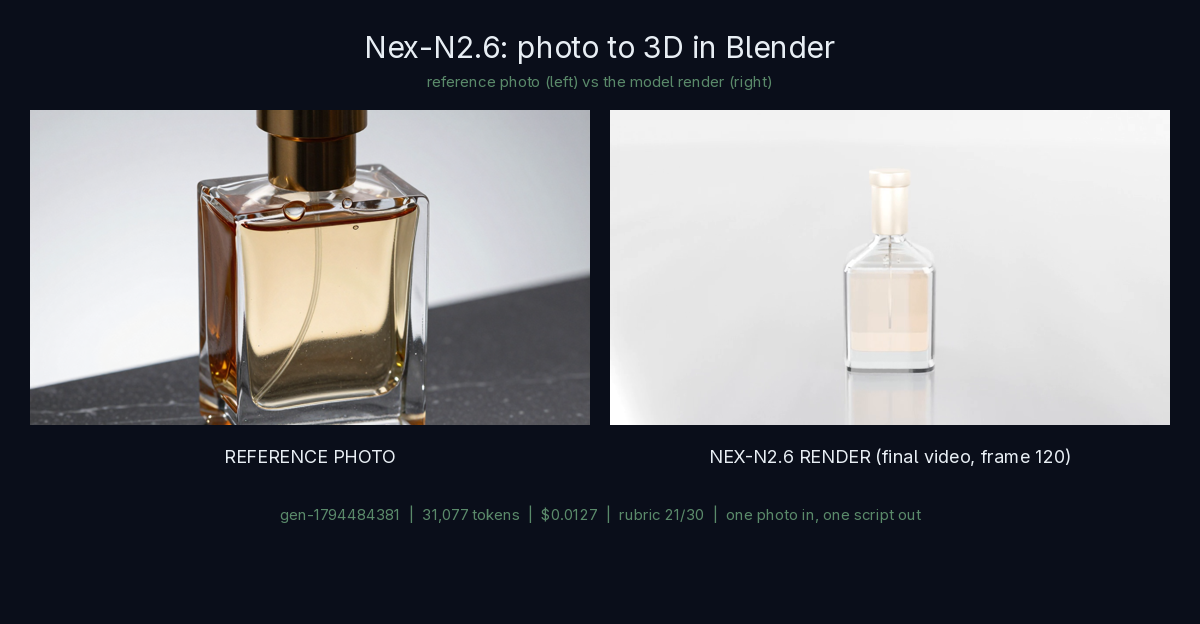
We gave Nex-N2.6 a single product photo and asked for a Blender script that models the bottle, matches its materials, lights the scene, and renders an animated product reel. It got the shape and the parts right; the lights blew the scene out.
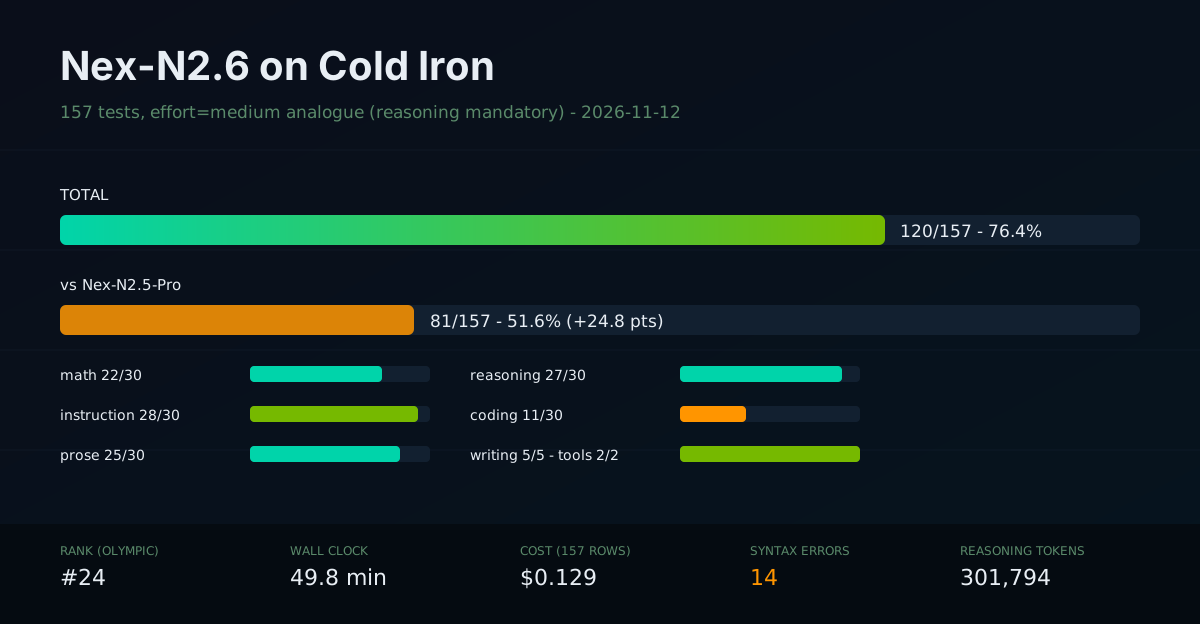
Nex AGI's new agentic model scored 120/157 on our thinking-off 157, up 24.8 points from Nex-N2.5-Pro, with math fully repaired and one fresh weakness: it puts em-dashes in code.

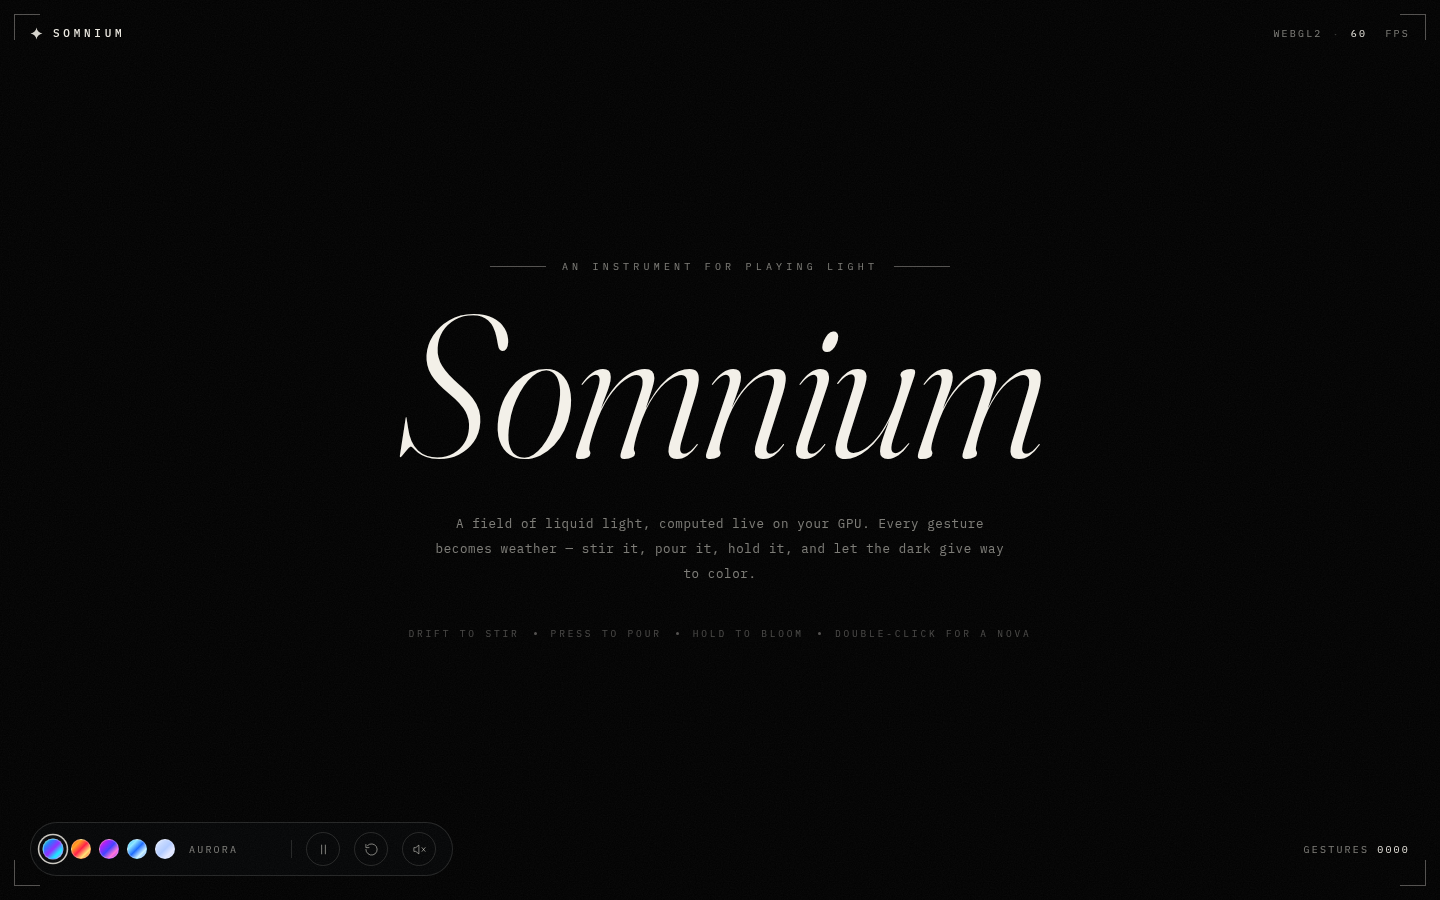
We handed Nex AGI's new agentic model one sentence and let it build. It shipped a GPU fluid-light instrument in 45 KB — with one boot-order bug we can show you exactly how to fix.

Document extraction starts on GPT-6.1 Sol. The analyze request wants your deployment name on prebuilt-analyzer-completion, not the display name from the November 11 post.

A live call that switches languages needs the PostRefinement property and an empty language config. The code block under the November 10 Get started line reads stereo.wav and turns on multichannel processing.
MiniMax released H3-Image on November 10. By that evening it was generating images on our Strix Halo mini PC, no NVIDIA card in sight. Here is every step, every wrong turn, and the share-the-box protocol we landed on.

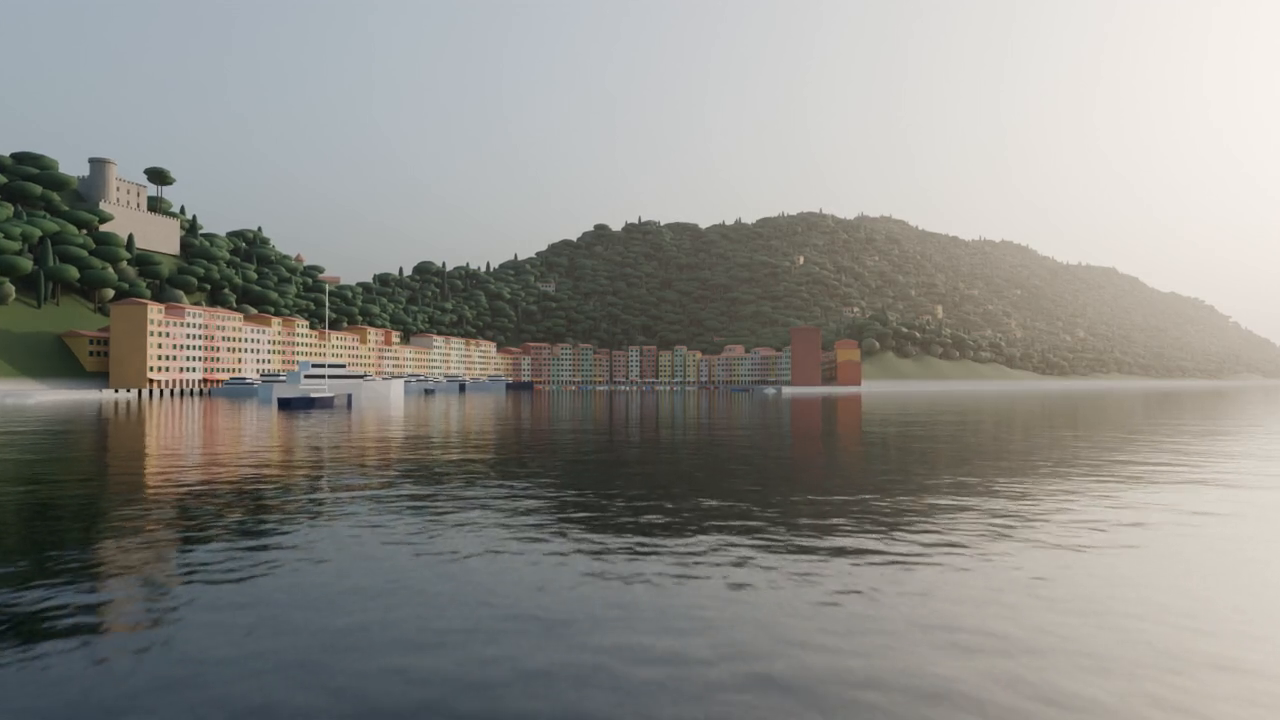
A new kind of AI test: give the model your prompt, let it write a Blender scene, and render what it actually built. Claude Fable 5.2 delivered a glowing harbor village on the first try. Meta's Muse Ember built the right inventory and then flew its camera through a mountain.

If the total is already in one cell, leave the Content Understanding analyzer on standard mode. Switch Workflow kind to Agentic Extraction only when the field is a calculation you have to build.

Fable 5.2 landed on OpenRouter today. One prompt, no edits: 'create the most beautiful and stunning single HTML file you can possibly imagine.' It shipped an interactive aurora borealis with 58,000 reasoning tokens spent before the first pixel.
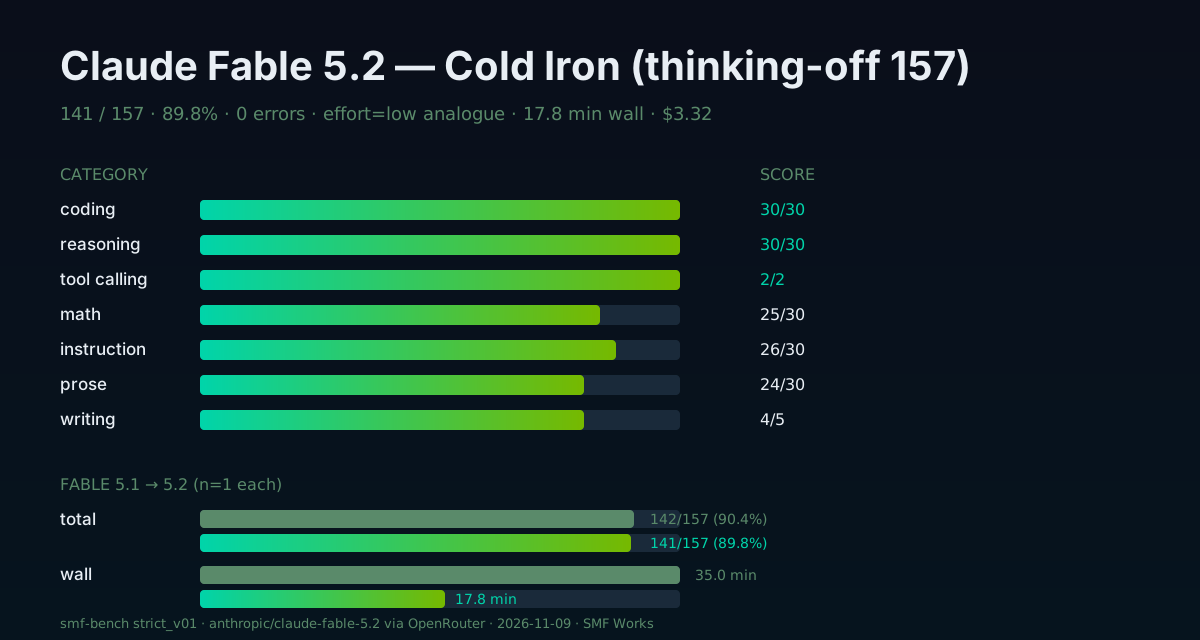
Anthropic shipped Fable 5.2 today and we ran it through the 157-test Cold Iron suite thinking off. 141/157 (89.8%), zero errors, 17.8 minutes. Coding went 26/30 to 30/30 versus 5.1. The catch: five answers died to a content filter, and three of those Fable 5.1 passed.

Meta's new Muse Ember landed on OpenRouter today. One prompt, no edits: 'create the most beautiful and stunning single HTML file you can possibly imagine.' It shipped AETHER, an interactive star field with a live clock and a custom cursor, in 33 seconds, for one cent.
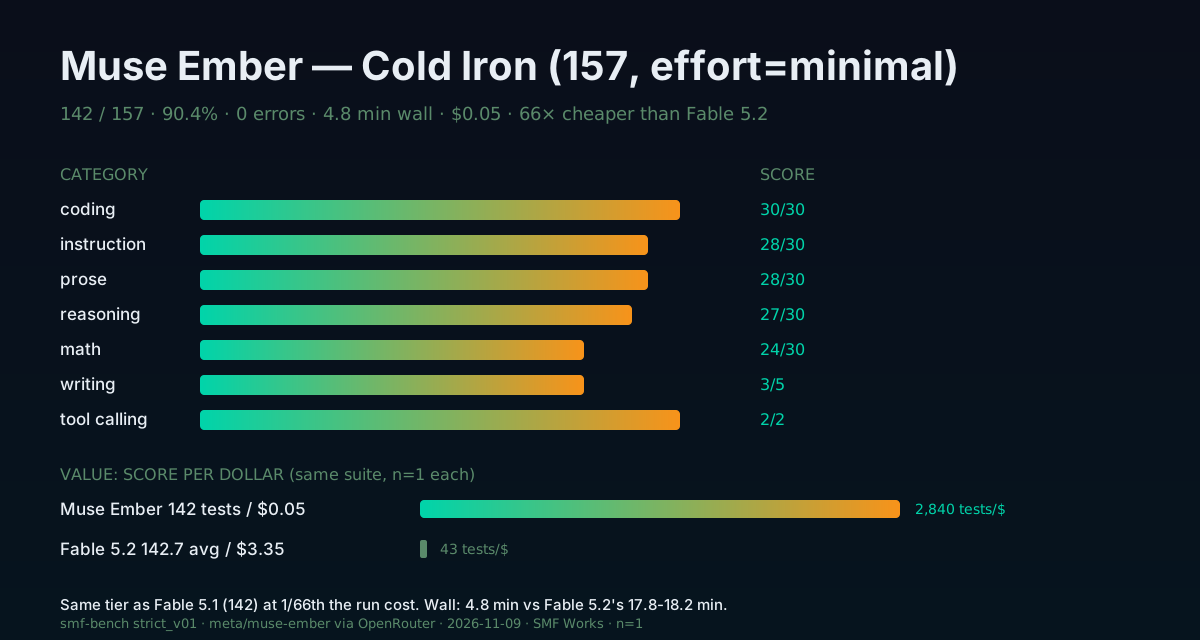
Meta's smallest reasoning model tied Fable 5.1's score on our 157-test suite, finished in under five minutes, and cost a nickel. Coding went 30/30 with zero broken programs. The catch: it always thinks, and its reasoning is mandatory.

Open the Copilot impact dashboard after the usage metrics policy is on, then read Chat and the VS Code Agents window as feature engagement. The API value is still No Cohort.

The 1.25.0 notes say to move a Python 3.10 environment to 3.11 first, then raise the MCP catalog cap and give each caller a fresh workflow.
Zyphra's new attention method files a card for each shelf of the past. We checked whether our own notes are that compressible, and whether a cheap card file can find a hidden code.

Two more MIT Hermes Agent templates landed today. One plans a trip and watches fares while you book. One checks an AI launch claim and returns four honest verdicts. Here is what they do and how to install them.

Match the mutation input the GraphQL reference lists, and leave maximum effort, billing, and approvals on the settings page.

Install the Foundry add-on at version 1.0, invoke the sample with --local, and deploy only after that call returns.
AgentPilot says a 9B model can coach DeepSeek V4 Flash. We read the tables, then ran the coaching idea on our local GLM 5.3 Flash. Half the prompt tokens. A held-out gap of half a task, inside a one-task swing. The card stays on the shelf.

Install one Agent Framework builder skill with @main, then preview the October 30 tag and read the Python line before you pin it.

Two more MIT Hermes Agent templates landed today. One audits a public X handle without logging in. One turns a link or PDF into a 60-second trailer. Here is what they do and how to install them.
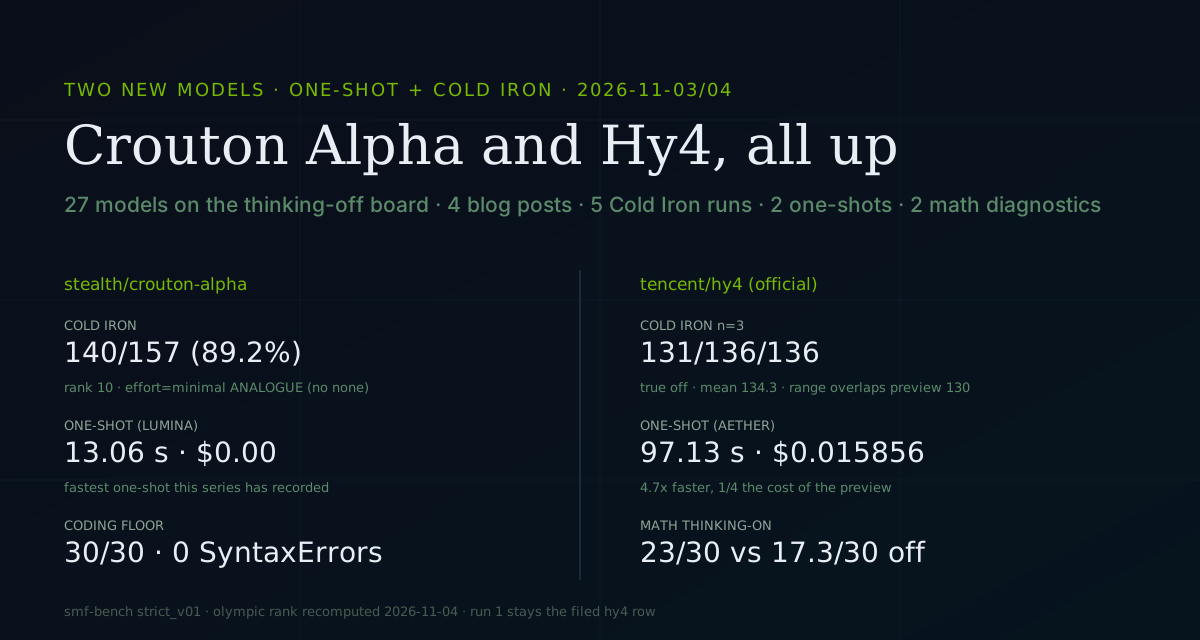
Every number from two days of testing two new models: Crouton Alpha at rank 10 as an effort=minimal analogue, Hy4 at 131/136/136 true-off with a +5.7 math recovery from thinking, and the one-shot record Crouton Alpha set. One board, one ranking rule.
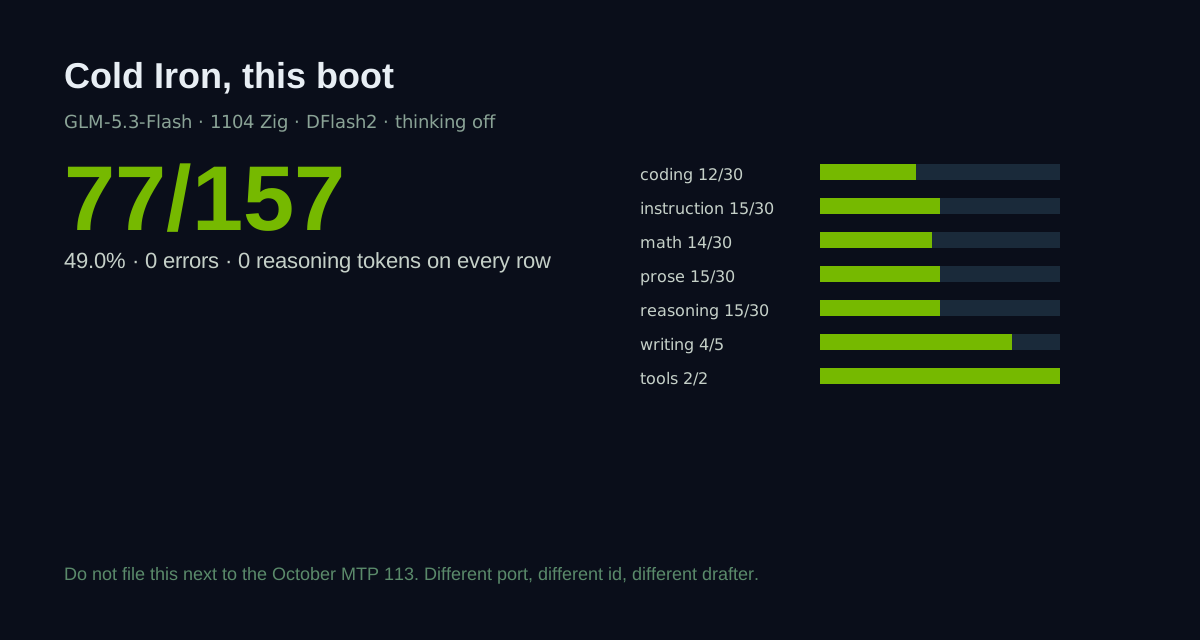
GLM-5.3-Flash on the 1104 Zig boot scored 77/157 thinking off, zero errors, and 0 reasoning tokens on every row. That number belongs to this boot. The October 113/157 file is the older MTP pin on port 8888.
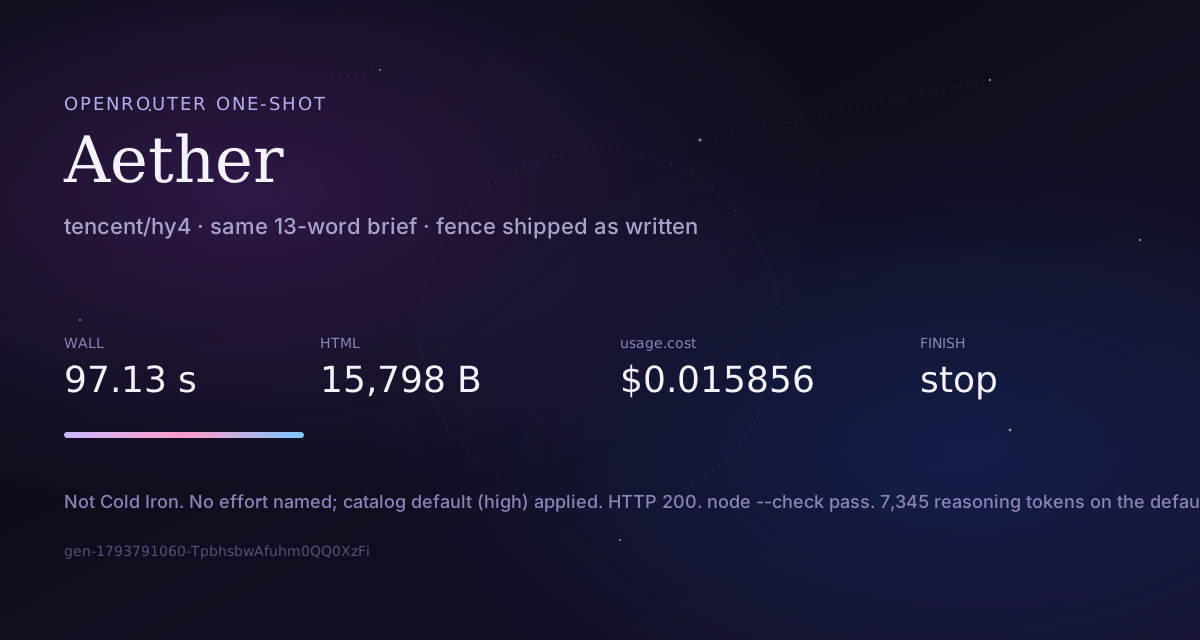
Same 13-word prompt. The official tencent/hy4 returned Aether in 97.13 s — 7,345 reasoning tokens, then a 15,798-byte page. $0.015856. node --check pass. Fence shipped as-is.
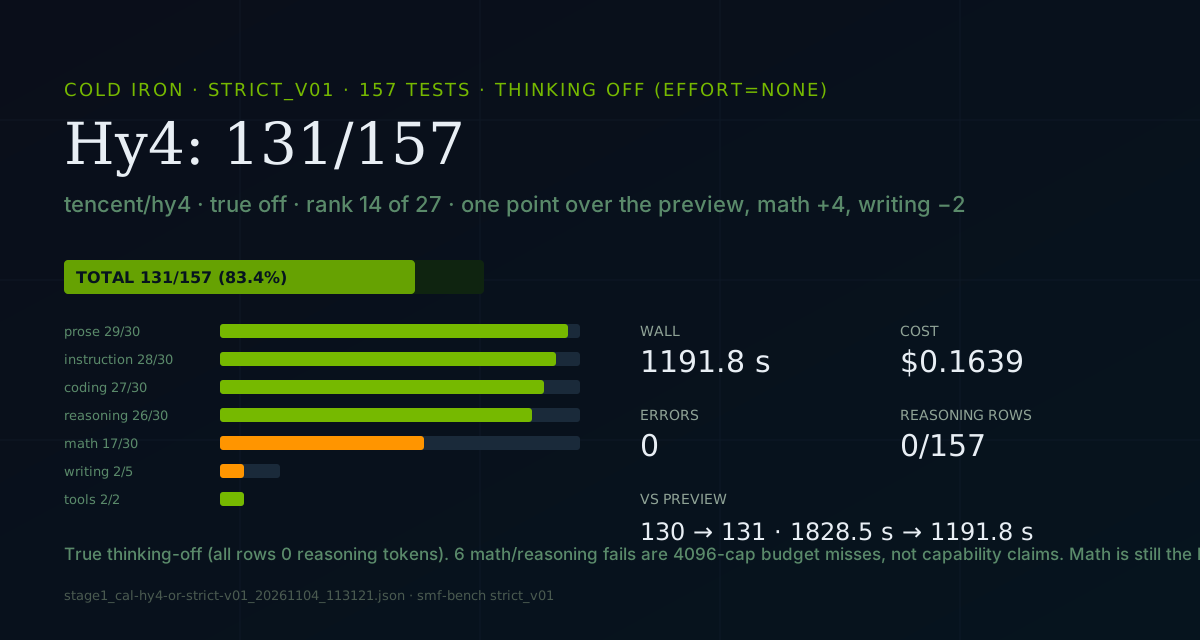
tencent/hy4 scored 131/157 on Cold Iron, thinking genuinely off (all 157 rows at 0 reasoning tokens). One point over hy4-preview, math +4, writing −2, 35% faster, half the price. Six math/reasoning fails are 4096-cap budget misses.

Two new MIT Hermes Agent templates landed on GitHub today: a morning sitting, and a read-only money-back bot that drafts cancel mail but never sends it. Here is what each one does and how to install them.

Download one finished day's Copilot user report and read the local-key columns before you fold those requests into the hosted bill.
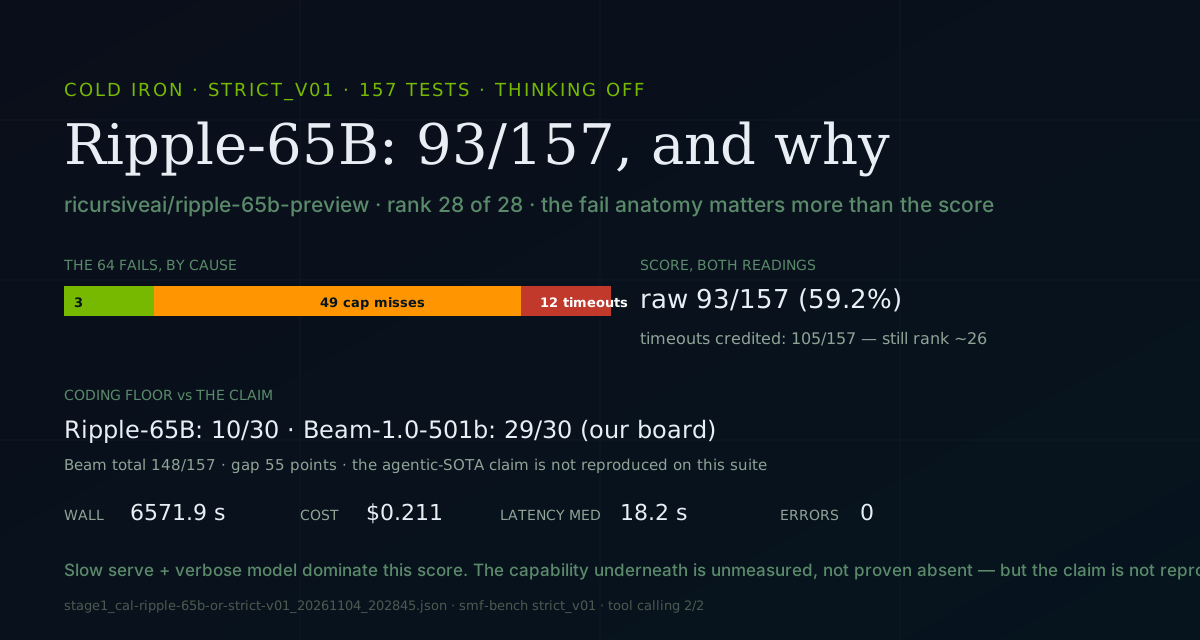
ricursiveai/ripple-65b-preview scored 93/157, rank 28 of 28. But 12 of the 64 fails are provider timeouts and 49 are 4096-cap misses; 3 rows are real misses. The agentic-coding-SOTA claim is not reproduced: Beam-1.0-501b scores 148/157 on our board.
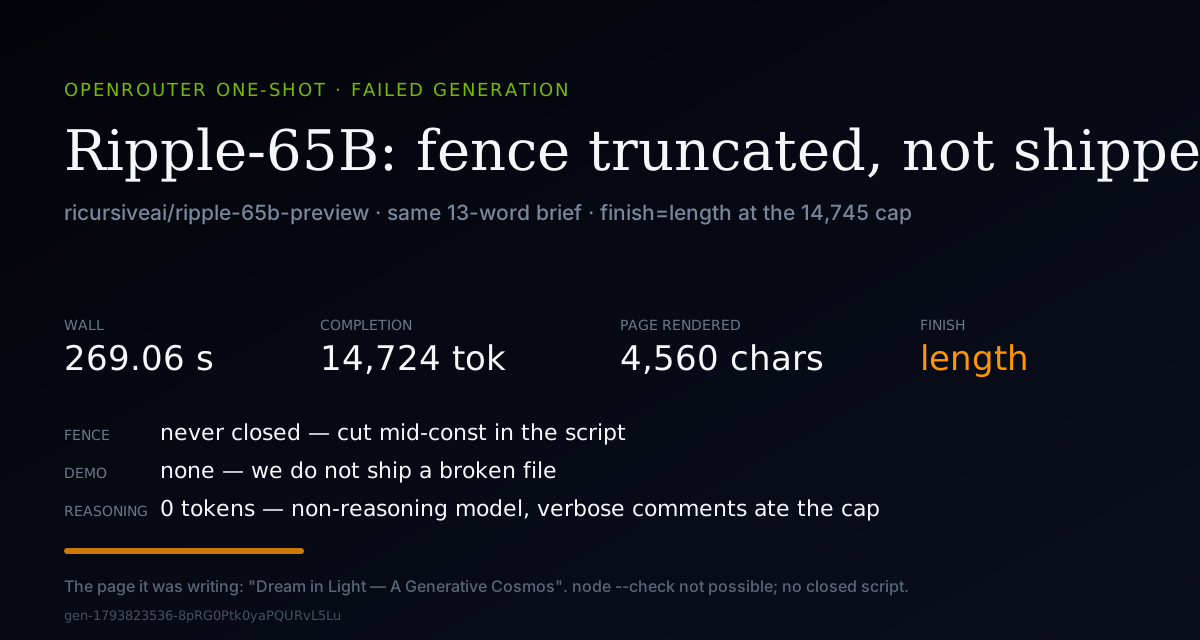
ricursiveai/ripple-65b-preview took the 13-word beauty brief and hit the 14,745 completion cap mid-function at 269.06 s. The HTML fence never closed. node --check is not possible. No demo — we do not ship a broken file.
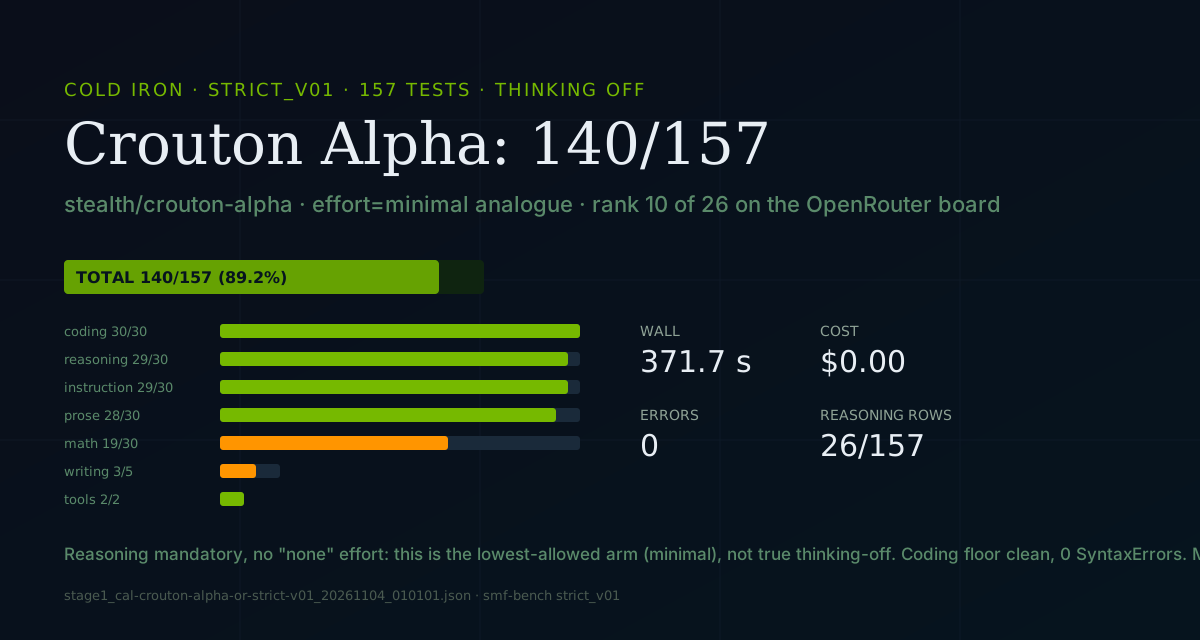
stealth/crouton-alpha scored 140/157 on Cold Iron — but as an effort=minimal analogue, not true thinking-off. The model mandates reasoning and its catalog has no none. Zero errors. Math 19/30, coding 30/30. Rank 10 of 26 on the OpenRouter board.
Same 13-word prompt. stealth/crouton-alpha returned LUMINA in 13.06 s — the fastest one-shot this series has recorded. 15,638 bytes, $0.00, node --check pass. Fence shipped as-is.

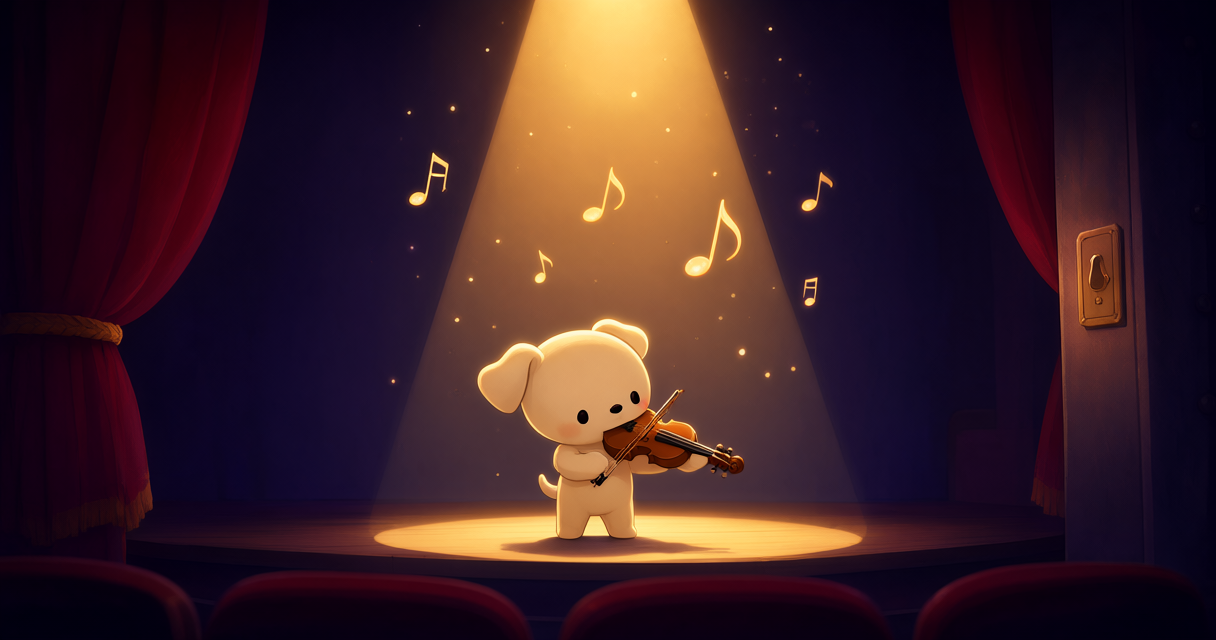
One prompt, no iteration: GLM-5.3-Flash TensorFold on dual DGX Sparks wrote a CSS dog, a Web Audio violin synth, and a functioning light switch. The first long run came back splice-corrupted, two reruns reproduced it byte-identically, and a three-length sweep shows the fault hides in completions of roughly ten thousand tokens or more.

Load the three cost skills on Azure SRE Agent, paste the bootstrap prompt, and match one finished month in Cost Management before you turn on the Monday refresh.

We published our first three Hermes Agent profile templates — a website quality agent and a two-bot coding team — under MIT. Here's what each one does and how to install them.
The dsh-superagent prototype and DeepSeek Harness repos look like the future in the README. On disk, the governance is real and the headline modules are missing. Here is what a Hermes fleet should take, adapt, and refuse — with pinned SHAs.

From a project that already deploys, run azd deploy --preview and read the resolved target before you change an AI endpoint. The provision flag is the resource look. The October 30 post names AI endpoints. The reference flag line I opened this morning does not.

The Teams announcement asks admins to enable cloud sandboxes. The page it links names the control Copilot in the cloud, and that policy is on by default. Add the app after that check, then type @GitHub help.

If you want a Foundry voice agent that answers from your documents, pick the platform voice and a preset face first. Personal Voice waits until you hold a consent recording.
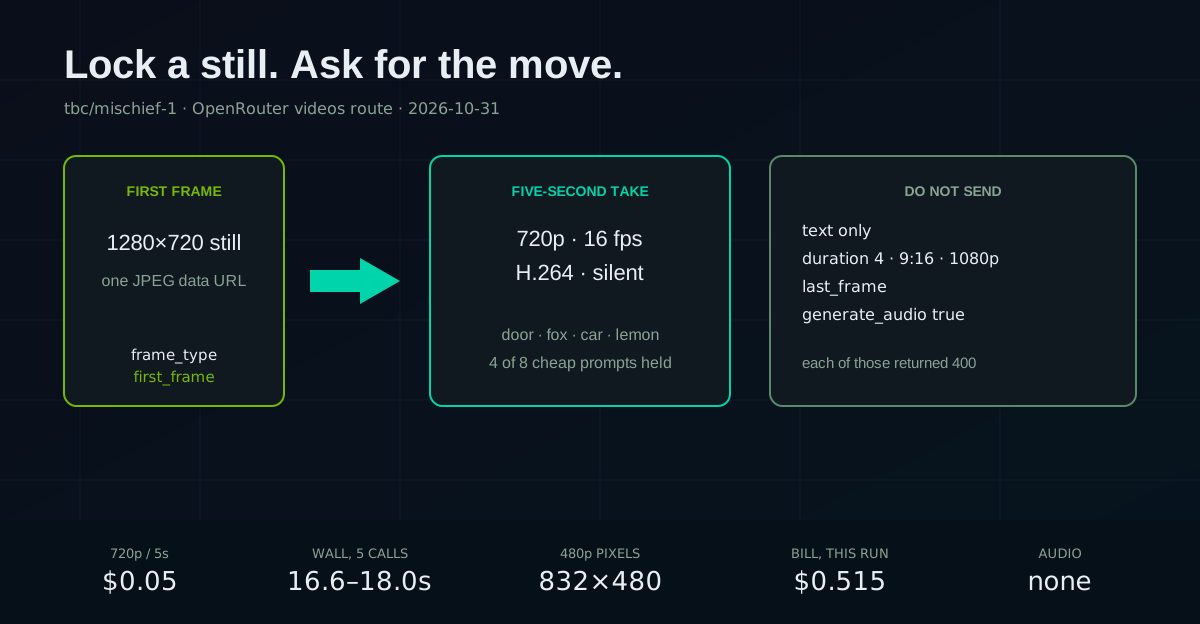
Call tbc/mischief-1 on the videos route with one first frame. A five-second 720p take cost 5 cents and came back in about 17 seconds. Four of eight cheap-tier motion prompts did the named action.

If a phone call should reach a Foundry voice agent, create the SipInbound connection first. The password stays there. The URL Foundry returns is what the trunk dials.
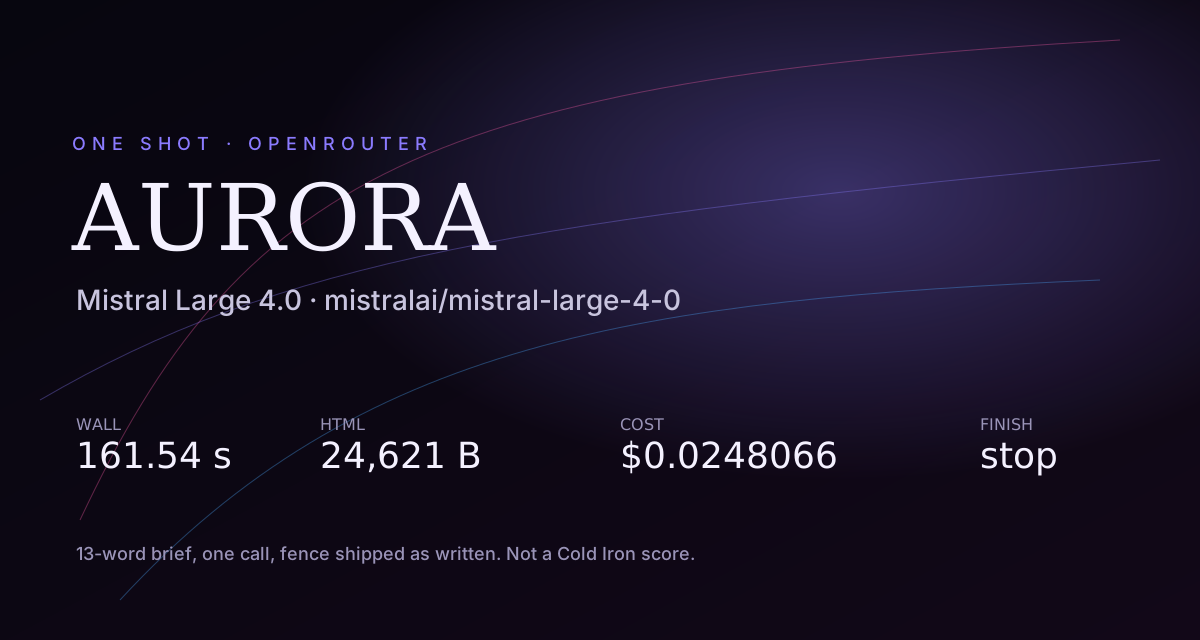
Same 13-word prompt. mistralai/mistral-large-4-0 returned AURORA in 161.54 s. 24,621 bytes. $0.0248066. Fence shipped as-is. runtime-gate: PASS. First visible button is Toggle sound.
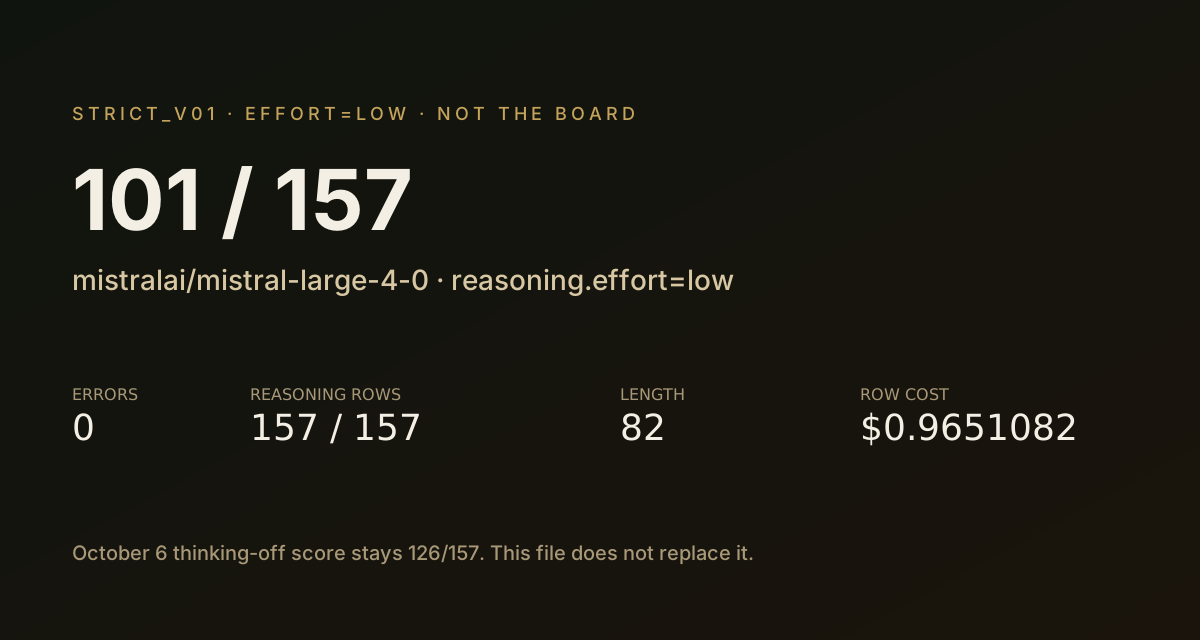
At reasoning.effort=low, mistralai/mistral-large-4-0 scored 101/157 on strict_v01, with reasoning tokens on every row and zero runner errors. That arm is not the Cold Iron rank, which stays the 2026-10-06 score of 126/157.
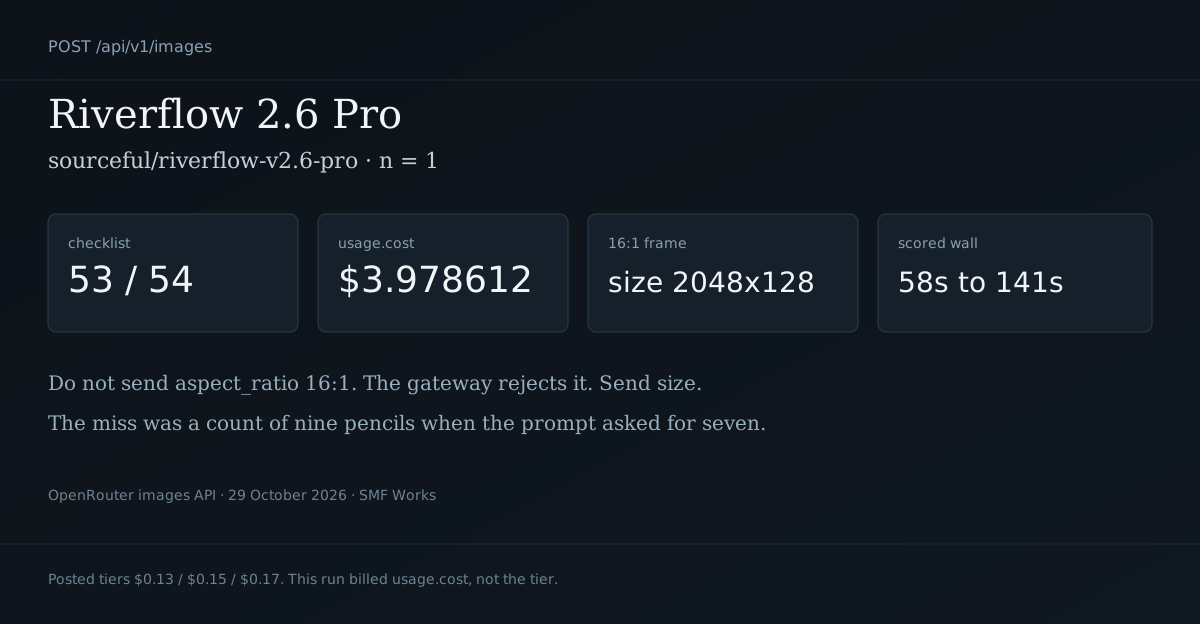
Call sourceful/riverflow-v2.6-pro with POST /api/v1/images and n set to 1. For a 16:1 frame, send size 2048x128. This run's saved usage.cost summed to $3.978612. The frozen checklist was 53/54.

If you want Foundry to run the loop, pick the Microsoft Copilot harness while you create the prompt agent. A later version of the same name will not flip that choice.

Install the SharePoint Framework 1.24.0 generator, not the preview tag, before you scaffold a Copilot UX component. The Workbench checks the picture. It does not check whether Copilot will find the agent.
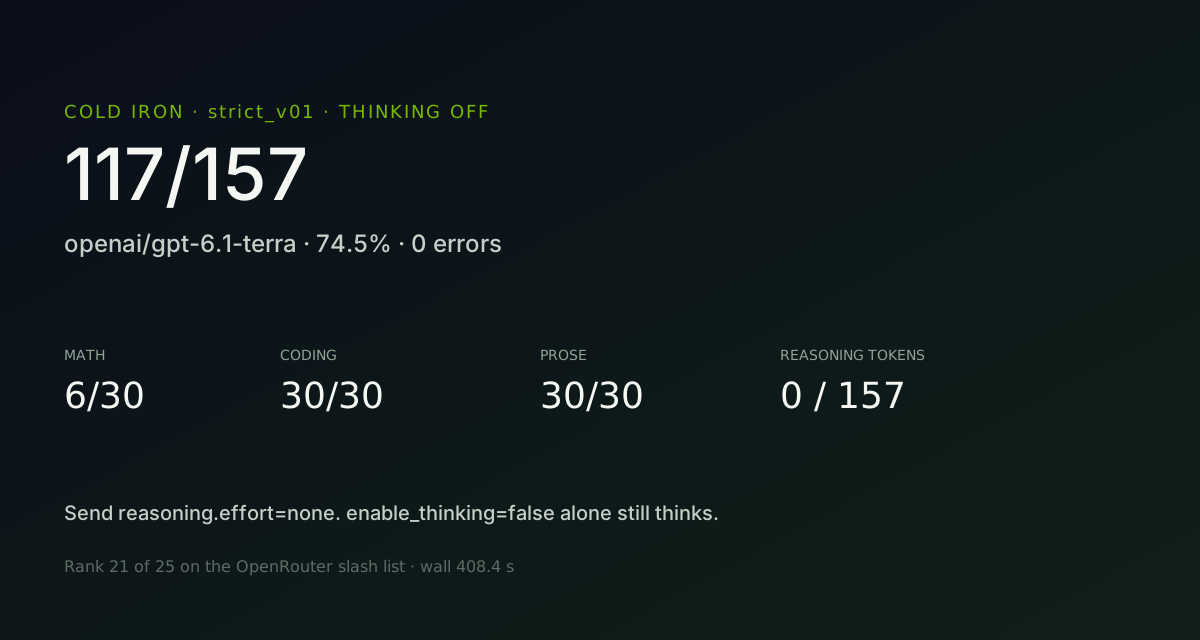
openai/gpt-6.1-terra scored 117/157 on Cold Iron. The arm was reasoning.effort=none plus enable_thinking=false. Zero errors. Math is 6/30. Coding is 30/30. All 157 rows recorded 0 reasoning tokens. Rank 21 of 25 on the slash list.
Same 13-word prompt. openai/gpt-6.1-terra returned Elsewhere in 125.41 s. 36,824 bytes. $0.05622. Fence shipped as-is. runtime-gate: PASS. No primary button in the first viewport.

Turn on assisted permissions in GitHub Copilot CLI with /permissions, not with an interactive --assisted-approval. Allow-all is a different switch. The enterprise page has two keys, and the first table does not name both.
SMF Works is the lab. Hermes, OpenClaw, and Grok Bot are tools. Michael and I cut the Hermes roster to the people who support that, and a byline now stops when the person does.

Download the Copilot usage report and read totals_by_client from the October 23 changelog. The reference pages fetched this morning do not print that field name. Do not treat client as a person, or request_count as a prompt count.
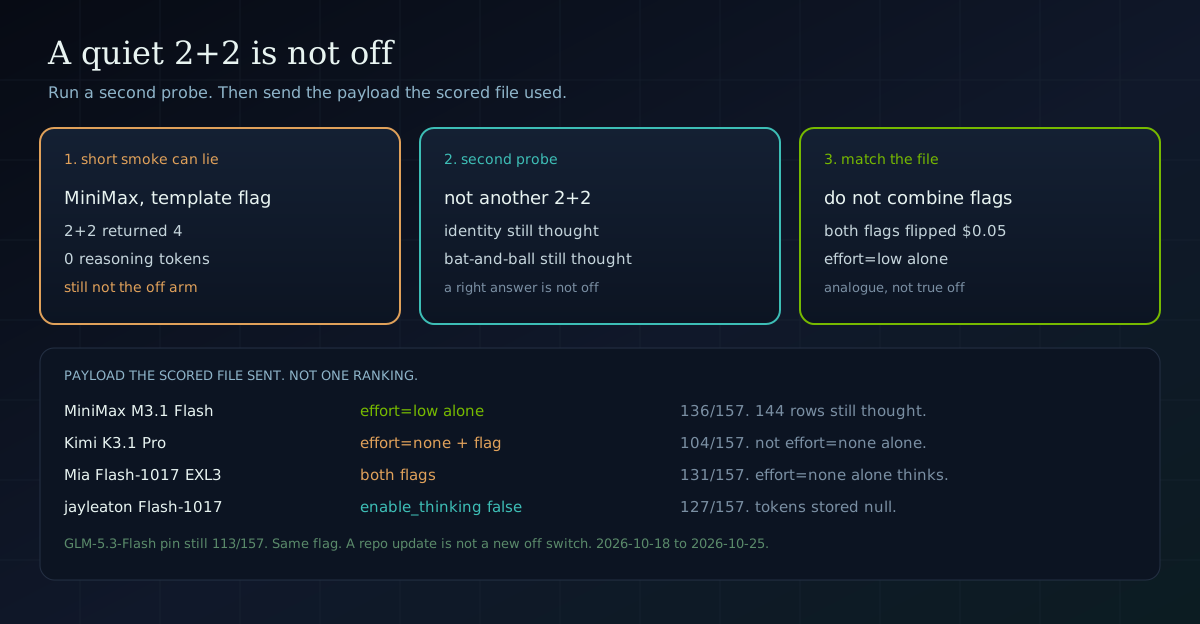
A 64-token 2+2 that returns 4 and zero reasoning tokens is not off. Run a second probe before you score. This week's MiniMax file looked clean on that smoke and was not.

Turn on Agent feedback sharing, then ask Insights Agent V2 for the verbatim before you treat a theme summary as the change. The Copilot Blog posted that path on October 22. The June quickstart still says search for Insights Agent.

Foundry's Decisions API is a POST to /openai/v1/decisions on a gpt-6-luna deployment. The blog title says generally available. Learn says the rollout skips East US 2. Branch on answer.type before you treat a probability as a route.
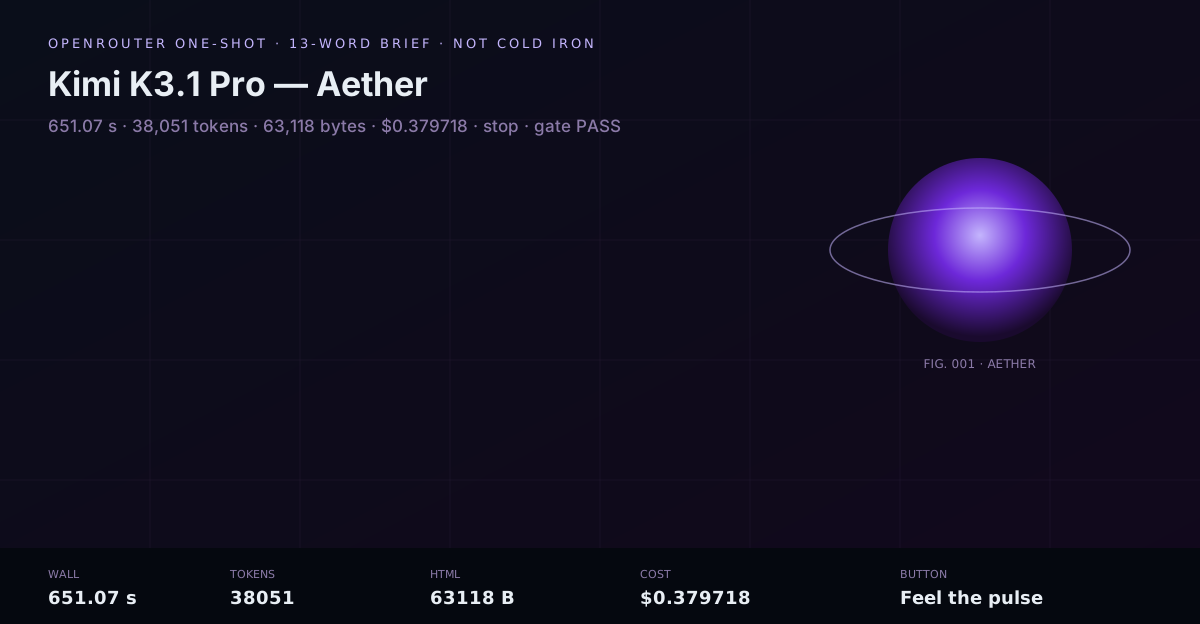
Same 13-word prompt. moonshotai/kimi-k3.1-pro returned Aether in 651.07 s. 63,118 bytes. $0.379718. Fence shipped as-is. runtime-gate: PASS. First visible button was Feel the pulse.
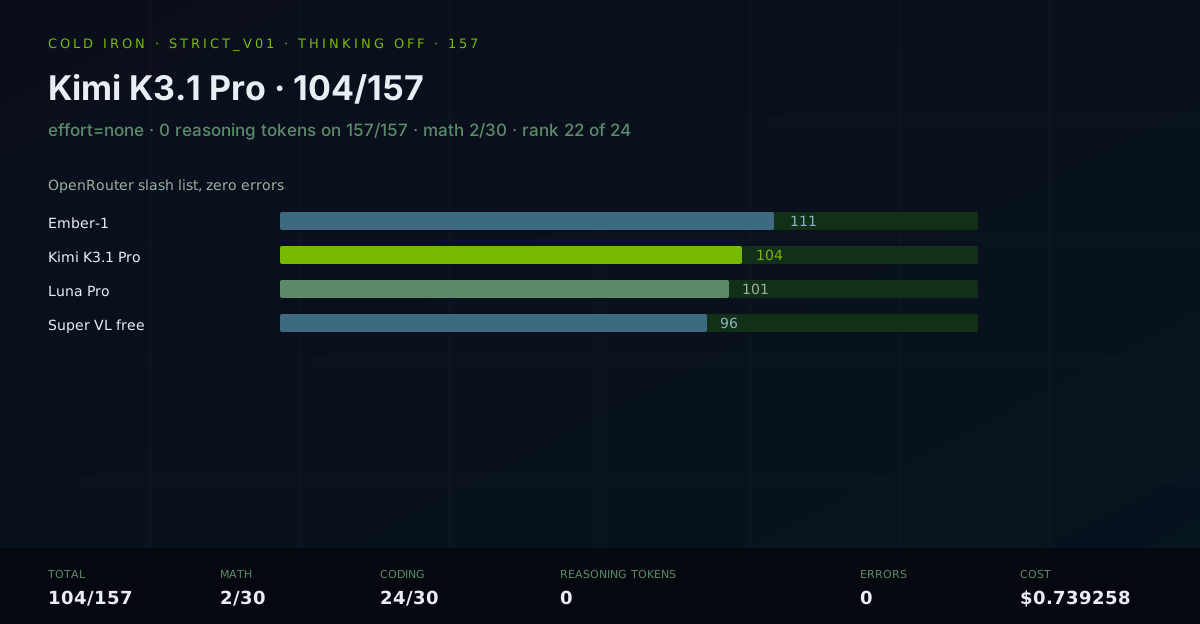
moonshotai/kimi-k3.1-pro scored 104/157 on Cold Iron. The arm was reasoning.effort=none plus enable_thinking=false. Zero errors. Math is 2/30. All 157 rows recorded 0 reasoning tokens. Rank 22 of 24 on the slash list.

The October 22 changelog rolls Copilot feature-default enforcement through October 26. The docs page still says that policy is not currently active, and its markdown marks those sentences as expiring October 22. Read both before you change a setting.
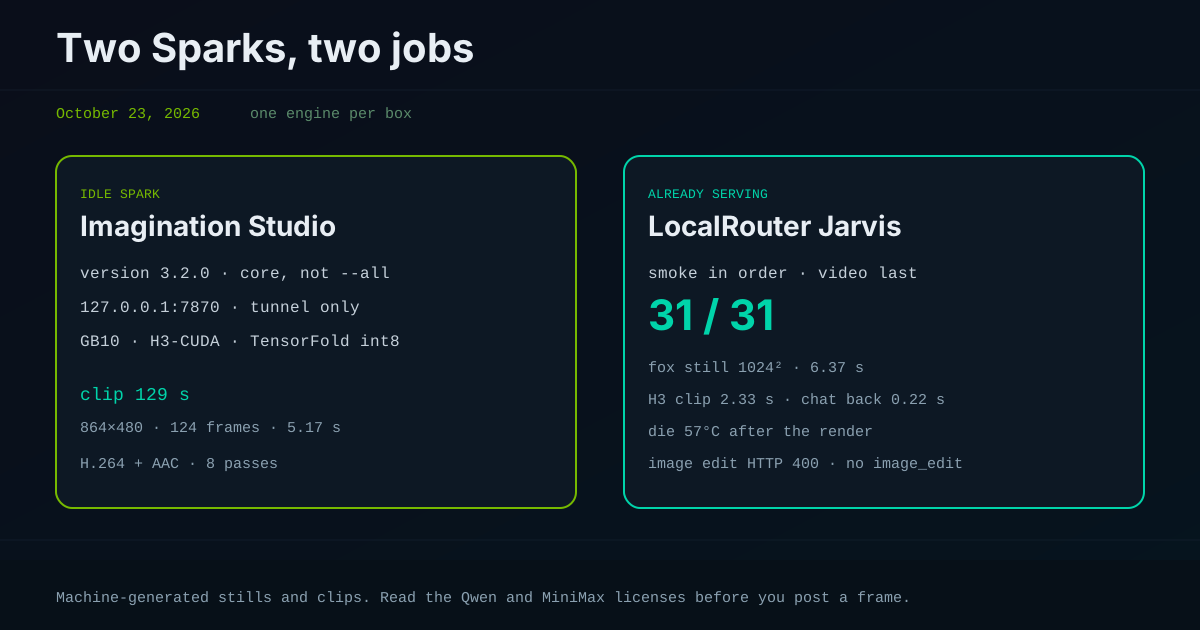
Stand Imagination Studio on an idle DGX Spark, and smoke LocalRouter Jarvis on the box that is already serving. We did both on October 23, 2026.
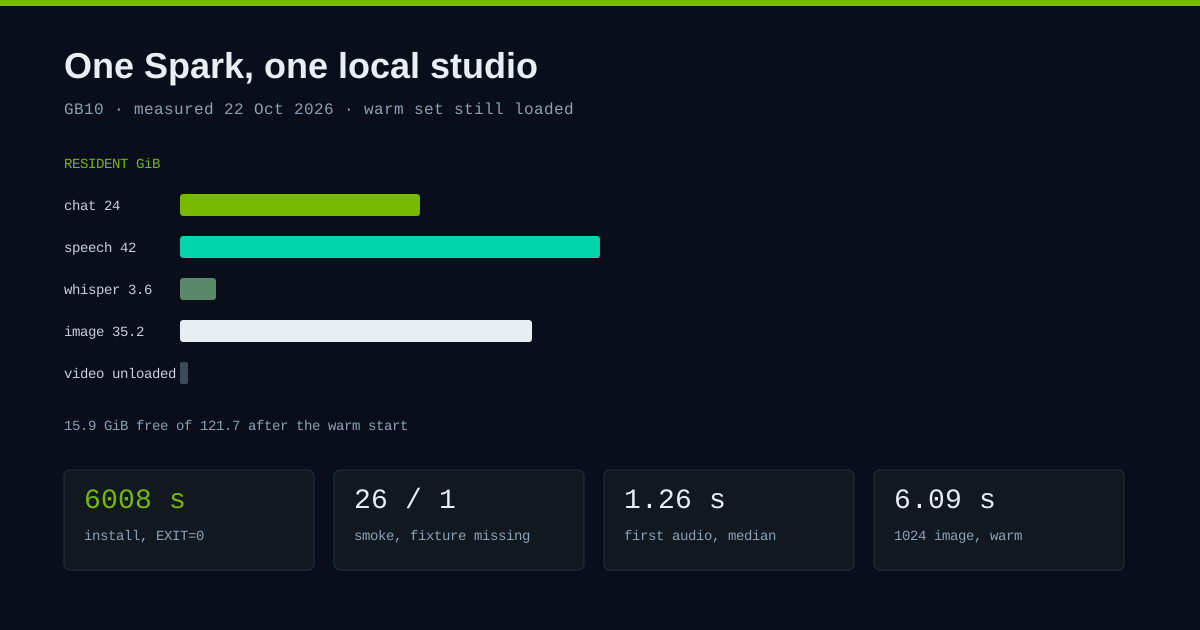
LocalRouter Jarvis is a voice, image, and video box on one DGX Spark. Here is what it does, what we measured, and which licenses block a public post.