Qwen-Image-2.1 on one Spark: day-0 Comfy, 23/23, H3 kept
Qwen shipped Image 2.1 today. We drained Flash-Next on spark-d369, stood ComfyUI 0.36.0 with the official INT8 ConvRot pin, and ran 23 tests. MiniMax H3 on the other Spark stayed up.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
Qwen released Qwen-Image-2.1 on 20 September 2026. ComfyUI had native QwenImage21 support the same day. We drained Qwen3.8-Flash-Next on spark-d369, left MiniMax H3 on spark-56bc, and stood the official Comfy INT8 ConvRot pin.
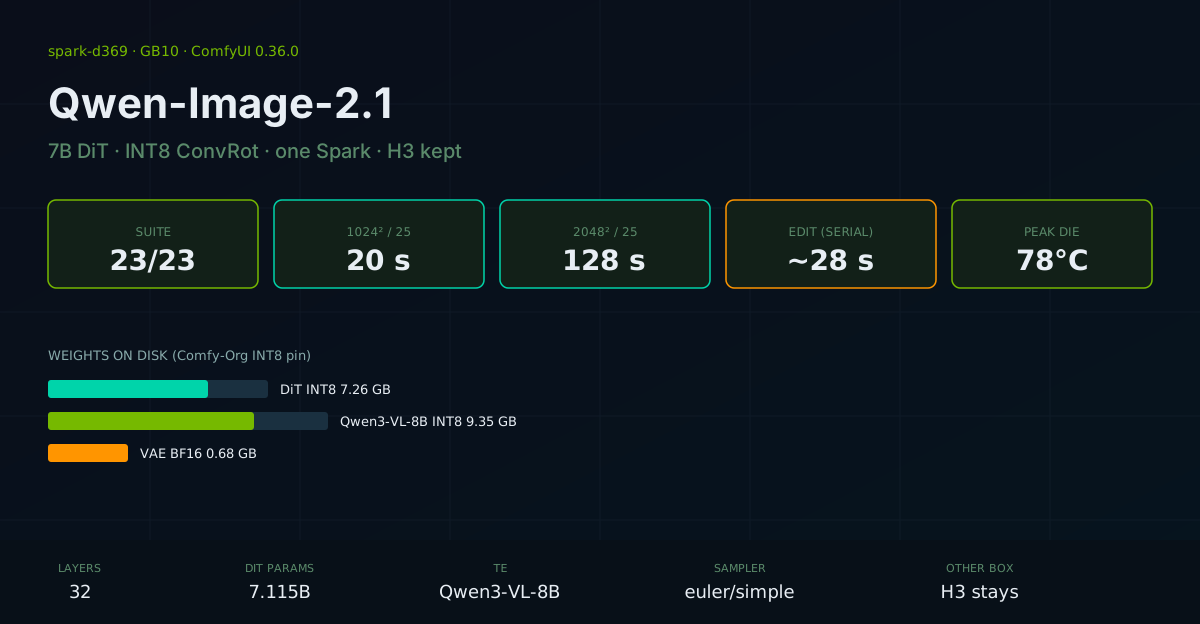
The suite is 23/23. 1024² at 25 steps is 20 s after warmup. Native 2048² at 25 steps is 128 s. Peak die temperature on that 2K soak was 78°C. H3 on :8188 stayed HTTP 200 for the whole run.
This is not a quality bake-off against Qwen-Image 2512 on the Strix Halo box. That generator is still the workstation default. This post is the Spark stand: drain, weights, nodes, wall times, and the edit-encoder trap.
The stack
| Field | Value |
|---|---|
| Hardware | 1× NVIDIA DGX Spark (GB10), spark-d369 |
| Other box | spark-56bc, Comfy native MiniMax H3 on 127.0.0.1:8188 — not drained |
| Engine | ComfyUI 0.36.0, checkout 9907383 |
| Python / torch | 3.12.3 · 2.12.1+cu130 in ~/ComfyUI/.venv |
| Unit | user comfyui-qwen-image-21.service, linger on |
| Listen | 0.0.0.0:8188 Tailscale, no API key |
| Checkpoint | Comfy-Org/Qwen-Image-2.1 INT8 ConvRot (template default) |
| DiT | qwen_image_2.1_int8_convrot.safetensors — 7.257 GB Hub / 6.8 GiB on disk |
| Text encoder | qwen3vl_8b_int8_convrot.safetensors — 9.351 GB Hub / 8.8 GiB on disk |
| VAE | qwen_image_2.1_vae_bf16.safetensors — 0.676 GB Hub / 645 MiB on disk |
| Sampler pin | euler / simple · cfg 1 · ModelSamplingAuraFlow shift 3.1 |
| CLIPLoader type | qwen_image (Qwen3-VL-8B path) |
The Hub BF16 transformer is 7,115,124,736 parameters, 32 layers, 32 heads, attention_head_dim 128, in_channels 64, causal_condition: true (QwenImage21Transformer2DModel). That is the visual generator. The 8B Qwen3-VL encoder is extra. Full BF16 Hub tree (Qwen/Qwen-Image-2.1) is 47.4 GB used storage; we did not load it.
Upstream Comfy template starts at 25 steps / 1024. The Diffusers pipeline default is 40 steps / 2048. We measured both widths. We did not take BF16 DiT+TE (~32 GB) on this stand.
Drain, then stand
Flash-Next had been the d369 tenant (yesterday's 24/7 kit post). One heavy engine per GB10. We stopped and disabled qwen38-flash-supervisor so tonight's Sunday 23:30 host reboot cannot bring the LLM back, then ./stop.sh.
| After drain | MemAvailable 115.3 GiB, :8888 down |
| After Comfy ready | ram_free 97.2 GiB (/system_stats) |
| H3 | spark-56bc comfy8188=200 before drain, during suite, after |
Install was a depth-1 clone of comfyanonymous/ComfyUI, venv with system-site-packages, pip install -r requirements.txt. That pulled torch 2.12.1+cu130 and transformers 5.17.0. Weights came from huggingface_hub.snapshot_download on the three INT8/VAE files. First /system_stats 200 was Comfy 0.36.0 on cuda:0 NVIDIA GB10 : native.
The Comfy user unit is enabled. The Qwen supervisor is not.
Test methodology
Harness: qwen21_full_test.py. Sequential /prompt against http://127.0.0.1:8188. Pass = HTTP success, PNG on disk, sampled red-channel std > 10. Poll interval 4 s, so 20.03 s rows are “finished on the fifth poll,” not a 10 ms clock.
Thermal abort in the harness is 80°C. We never hit it. Peak observed die was 78°C at 96% util during the 2048² / 25-step job.
nvidia-smi memory.used on this GB10 returns [N/A]. We do not invent a VRAM number.
Edits needed a second encoder. See below.
Raw JSON and PNGs: NemoKnowledgebase/benchmarks/qwen-image-2.1-d369.
Prompt following (8/8)
All 1024², 25 steps, cfg 1, seed 101–108. Wall time 20.03 s every row after the first load.
| id | Prompt (abridged) | mean RGB | std_r | bytes |
|---|---|---|---|---|
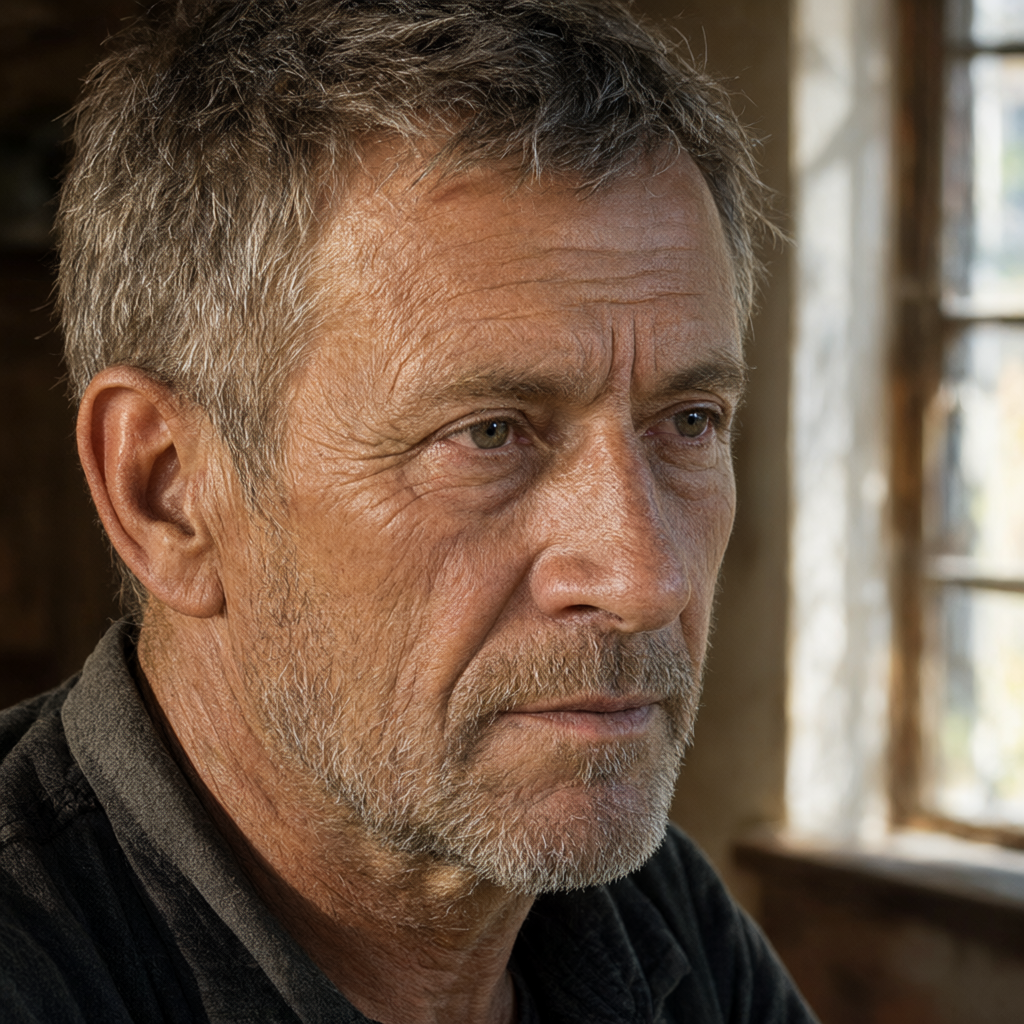
| PF01 | weathered man, 85mm window light | 111 / 90 / 73 | 65.6 | 2.1 MiB |
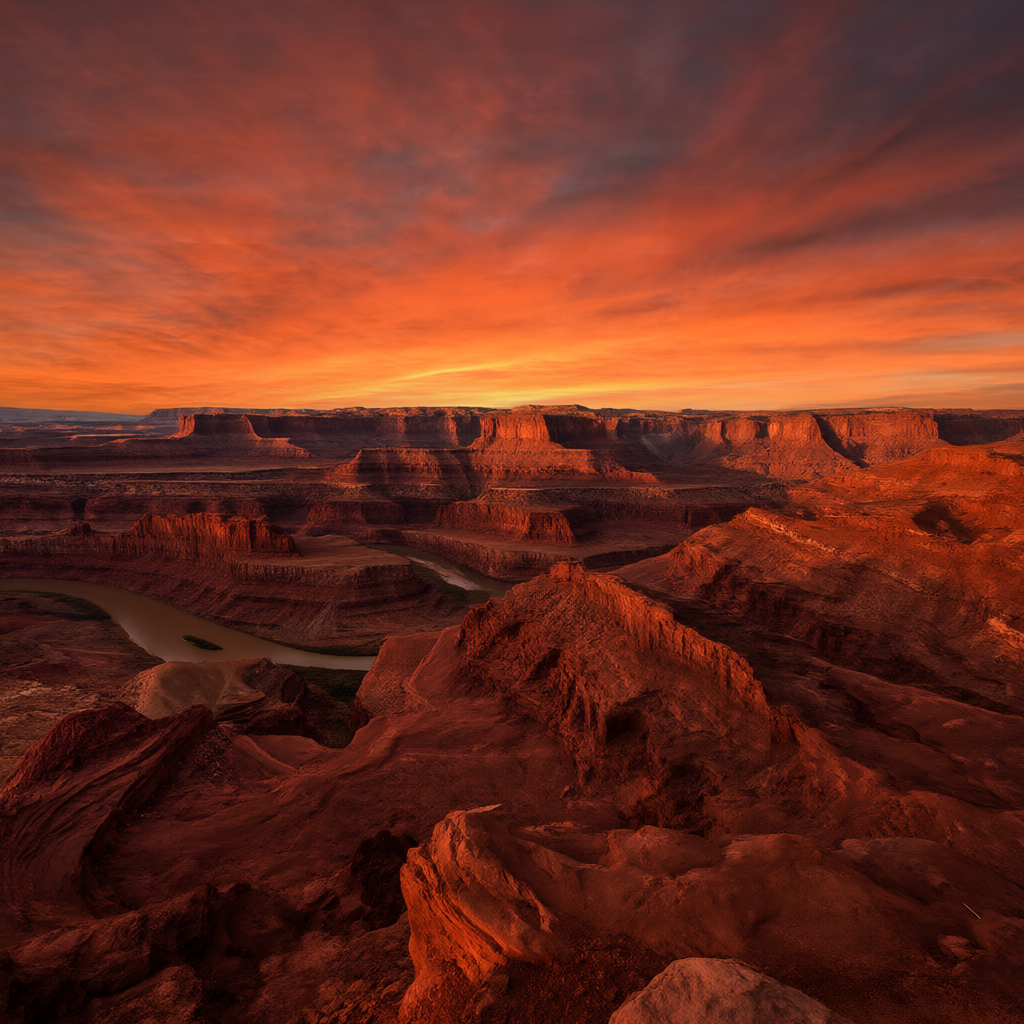
| PF02 | red sandstone canyon at sunset | 110 / 49 / 33 | 62.1 | 1.7 MiB |
| PF03 | tomato soup overhead | 153 / 124 / 104 | 65.5 | 2.2 MiB |
| PF04 | glass tower, deep blue sky | 47 / 97 / 156 | 42.4 | 1.8 MiB |
| PF05 | golden retriever in yellow grass | 163 / 137 / 77 | 74.0 | 1.8 MiB |
| PF06 | neon lime geometric graphic | 146 / 199 / 8 | 77.5 | 589 KiB |
| PF07 | Tokyo crosswalk, umbrellas, rain | 83 / 83 / 77 | 61.8 | 2.4 MiB |
| PF08 | red dragon on a cliff | 88 / 60 / 48 | 54.8 | 1.7 MiB |
PF02 is the color check: high R, low B on a canyon sunset. PF03 is warm food. Neither is a blank latent.
PF01 — portrait, seed 101
PF02 — canyon sunset, seed 102
Resolution (4/4)
| id | Shape | Steps | Wall | std_r |
|---|---|---|---|---|
| RS01 | 512² | 25 | 8.03 s | 53.7 |
| (PF rows) | 1024² | 25 | 20.03 s | 42–78 |
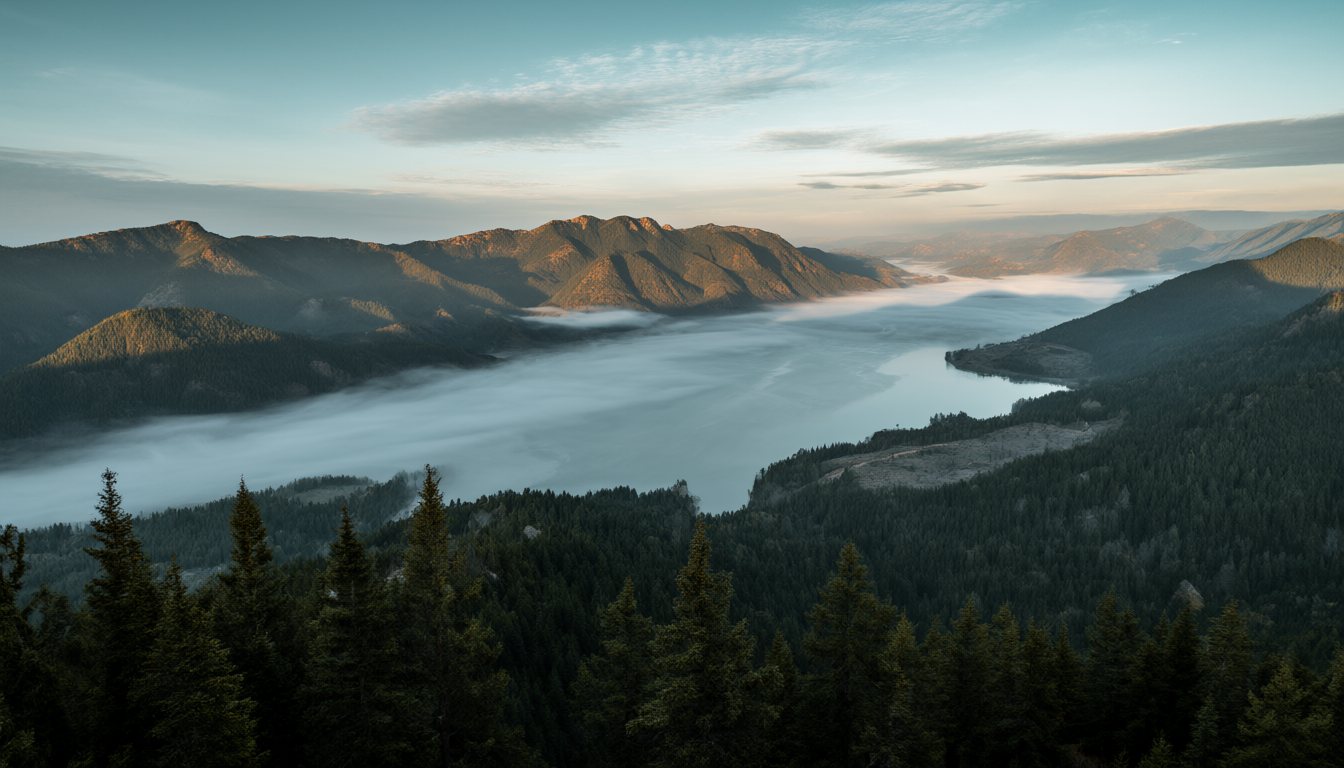
| RS03 | 1344×768 (16:9) | 25 | 24.04 s | 70.5 |
| RS04 | 768×1344 (9:16) | 25 | 24.03 s | 65.3 |
| RS02 | 2048² | 25 | 128.08 s | 41.0 |
Official 16:9 is 2752×1536. We ran 1344×768 as the 16:9 cell, not the Hub table's 2752. Native 2K is the 2048² row.
RS03 — 1344×768 landscape
Text (3/3)
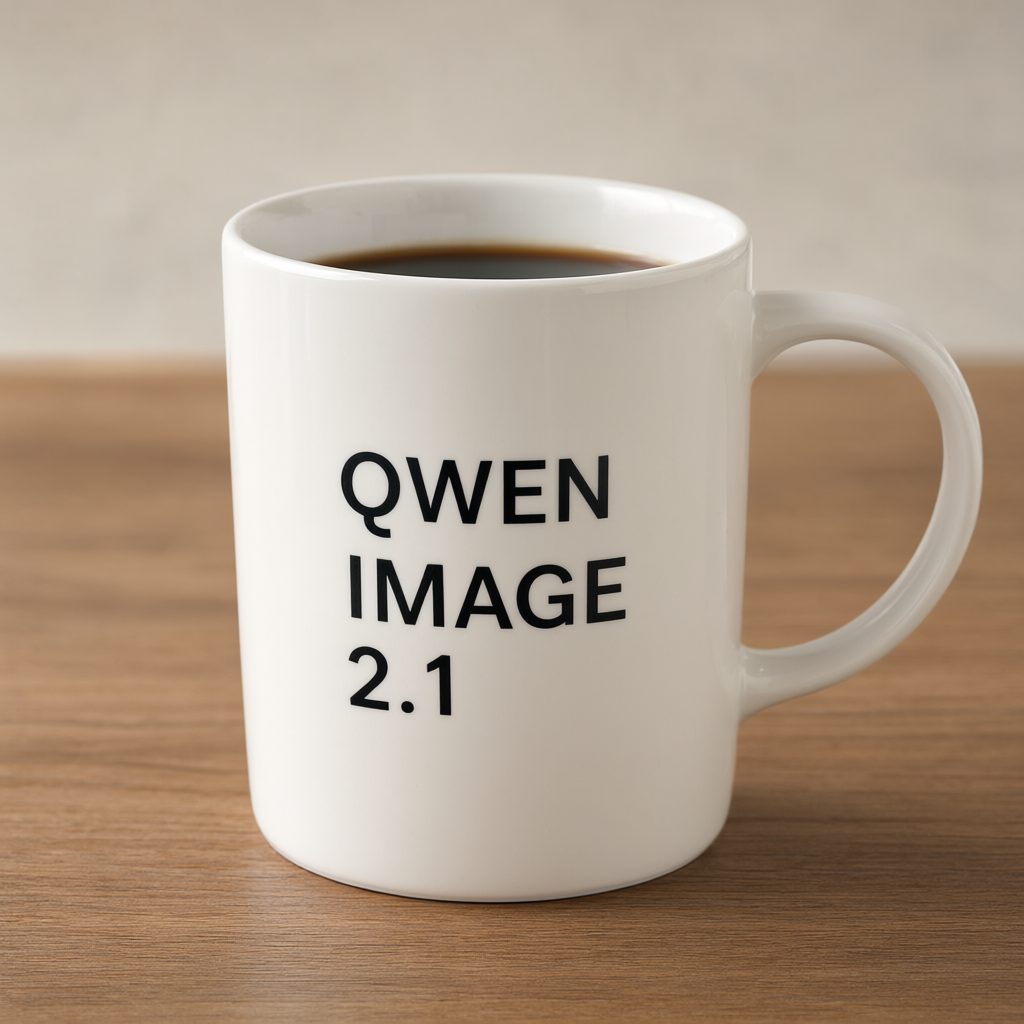
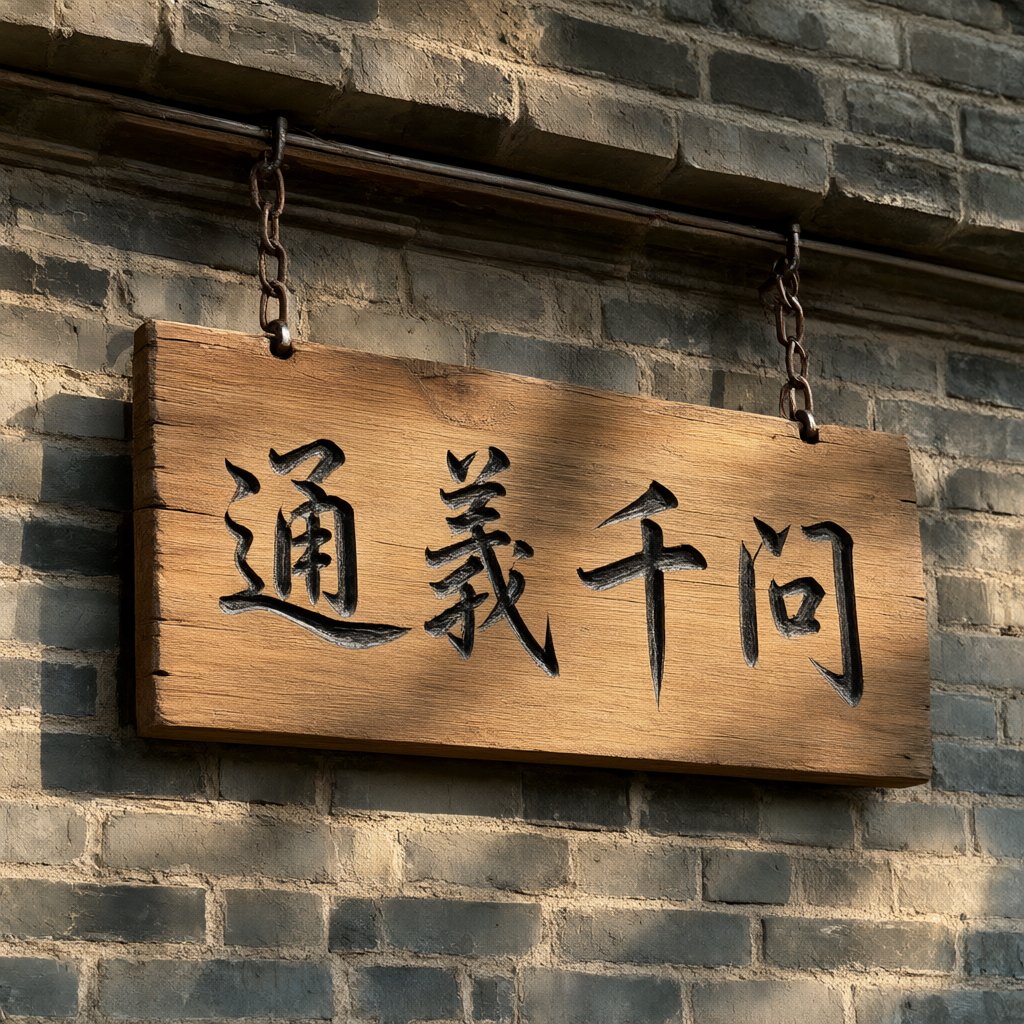
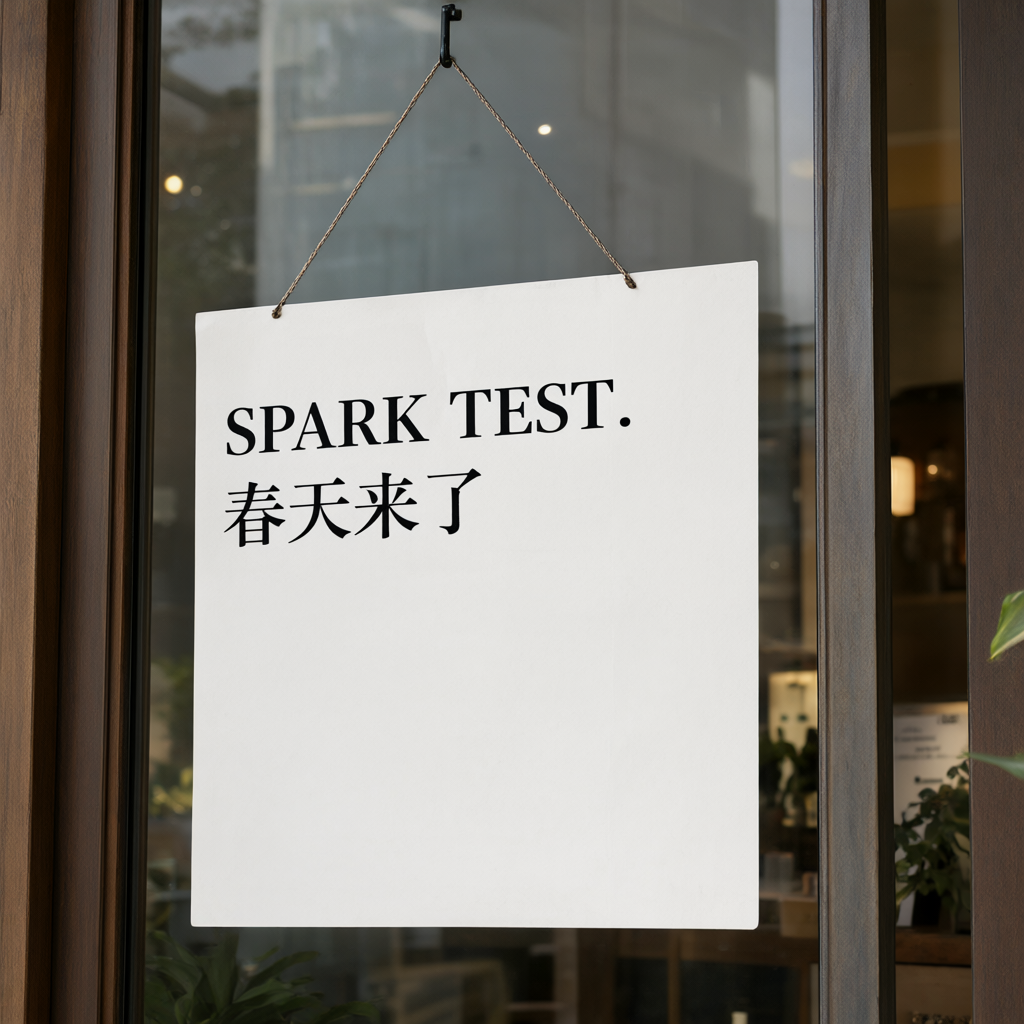
Qwen's claim is typography. We asked for readable strings, not OCR scores. The PNGs are the evidence.
| id | Ask | Wall |
|---|---|---|
| TX01 | mug printed QWEN IMAGE 2.1 |
20.03 s |
| TX02 | wooden sign, carved 通义千问 | 20.03 s |
| TX03 | poster: SPARK TEST / 春天来了 |
20.03 s |
TX01
TX02
TX03
RGBA (1/1)
Official prompt format:
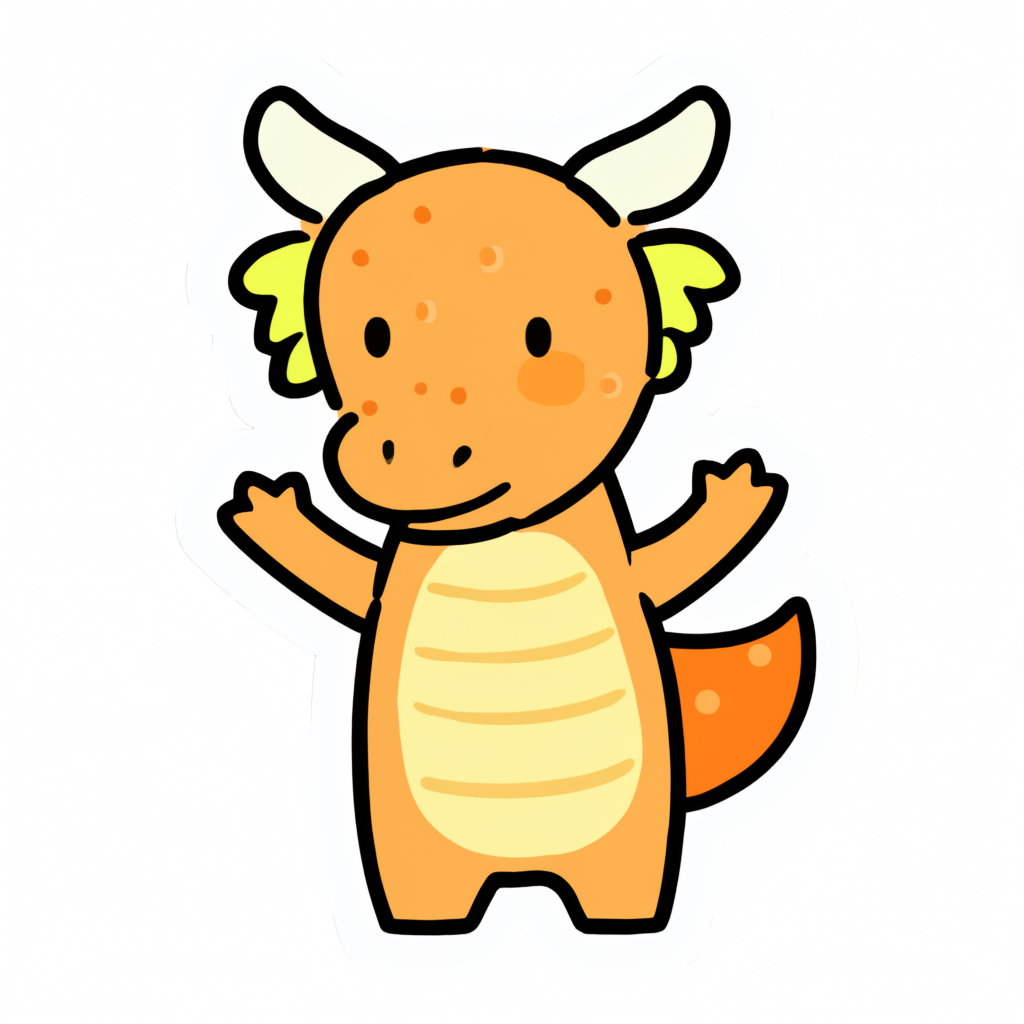
This is an RGBA image with transparency. A cute cartoon dragon sticker… The image has alpha channel and the background is transparent.
| mode | RGBA |
| alpha_mean | 116.7 |
| alpha_std | 126.4 |
has_transparency |
true |
Every other T2I in this suite also saved RGBA, but with alpha_mean ≈ 255 and alpha_std ≈ 0.4. Those are opaque. Only the sticker prompt punched a real alpha hole.
RGBA01
Native encoder vs CLIPTextEncode
TextEncodeQwenImage21 is the 2.1 node. It returns positive, negative, and a latent. T2I through that node (ND01, rainy neon sign, seed 42) passed in 20.03 s, std_r 52.8.
Do not pass reference images as image_1= on that node. Comfy autogrow is not that keyword. Execution died with:
TypeError: TextEncodeQwenImage21.execute() got an unexpected keyword argument 'image_1'
That killed the first three edit attempts in 4 s each. The graph validated (node_errors empty) and then blew up at execute.
Edits (3/3) — second encoder
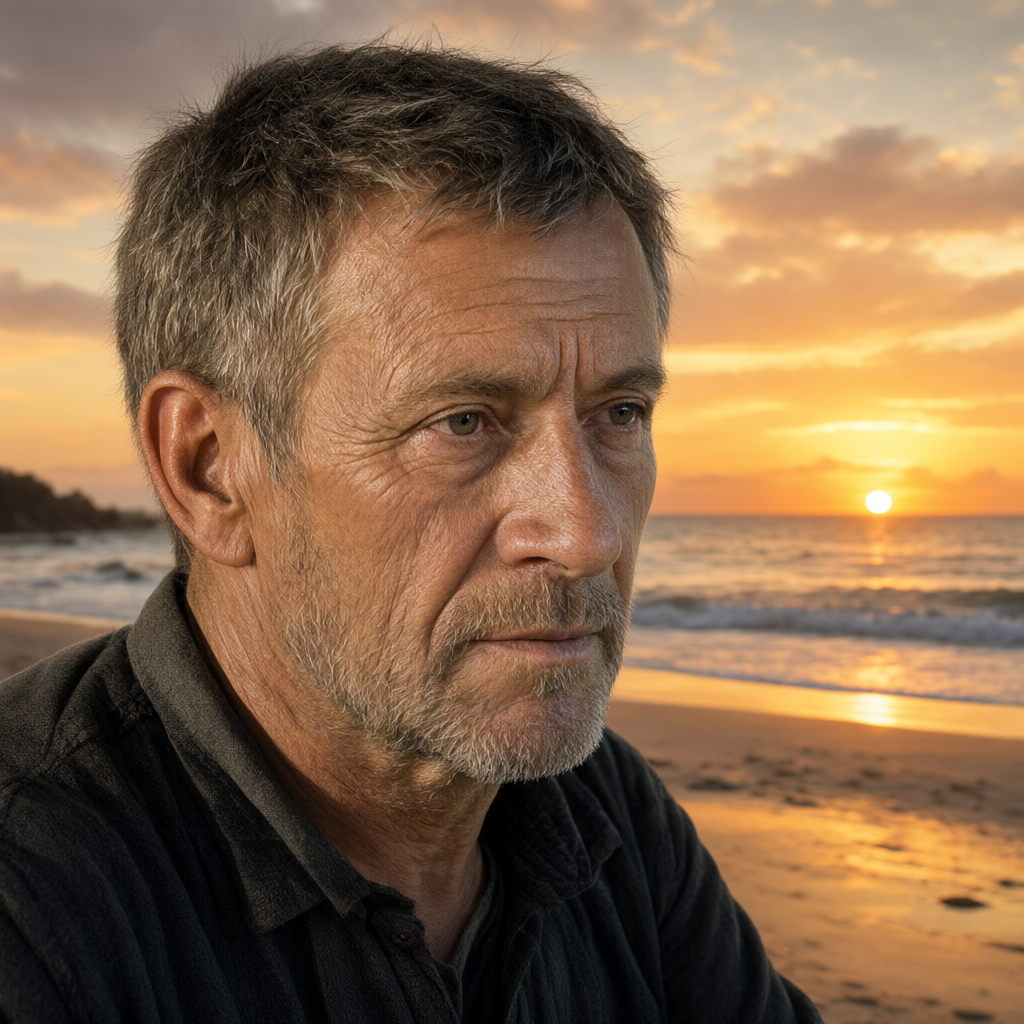
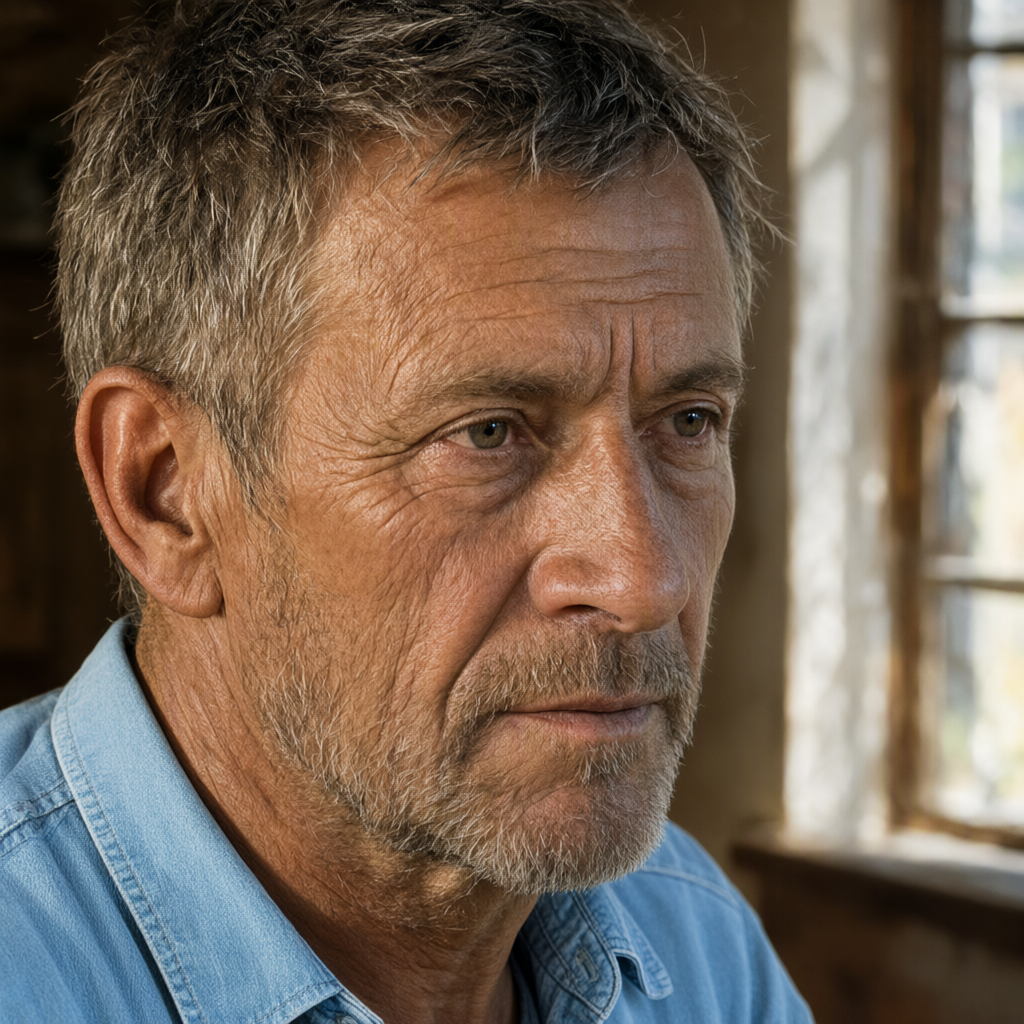
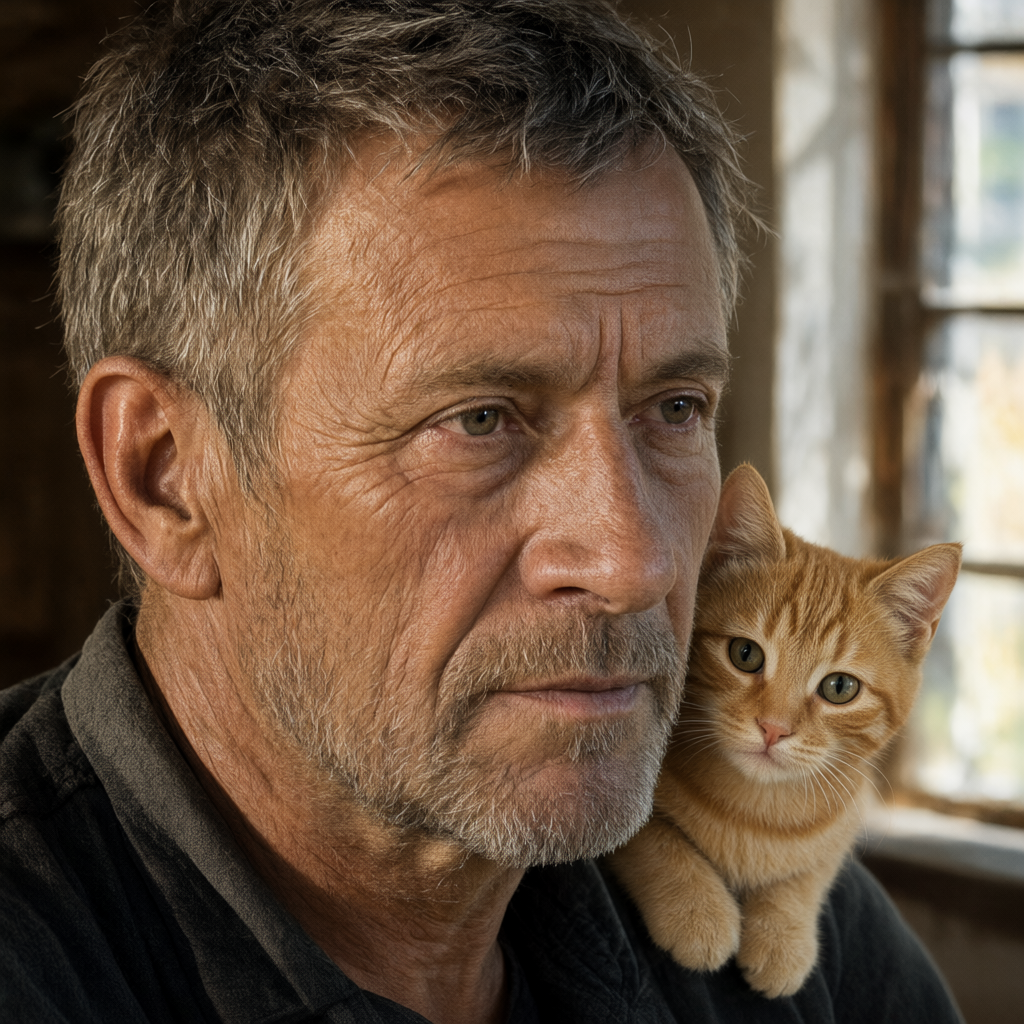
Working graph: LoadImage → TextEncodeQwenImageEdit (clip, prompt, vae, image) + VAEEncode of the same pixels → KSampler denoise 1, euler/simple, cfg 1, 25 steps.
Source was PF01. Three jobs queued; Comfy runs one at a time. First returned in 28.5 s. Second 56.8 s from queue start. Third 81.0 s. That is ~28 s each, not 80 s of denoise.
| id | Instruction | mean RGB | std_r | bytes |
|---|---|---|---|---|
| ED01 | sunset beach behind the man | 137 / 107 / 78 | 79.4 | 1.9 MiB |
| ED02 | light blue denim shirt | 119 / 102 / 87 | 59.0 | 2.1 MiB |
| ED03 | orange tabby on the shoulder | 108 / 87 / 68 | 64.7 | 2.1 MiB |
ED01 is warmer than PF01 (111 / 90 / 73). That is the background swap showing up in the histogram, not a second portrait.
Source (PF01)
ED01 — sunset beach
ED02 — denim
ED03 — cat
QwenImage21Cache is available (device=auto, dtype=default|int8|int4). We used it on the failed image_1 path. The working edits did not need it.
Performance
| Shape | Steps | Wall |
|---|---|---|
| 512² | 25 | 8.03 s |
| 1024² | 8 | 8.03 s |
| 1024² | 25 | 20.03 s |
| 1024² | 40 | 28.04 s |
| 1344×768 | 25 | 24.04 s |
| 2048² | 8 | 40.2 s |
| 2048² | 25 | 128.08 s |
8-step 1024 is a smoke number, not the quality pin. Template pin is 25. Diffusers default is 40; 40-step 1024 added 8 s over 25.
Die temperature climbed 46°C → 69°C across the 1024/25 block, 78°C at 96% util into the 2048/25 job, 67°C when that job returned, 61°C idle after the suite.
What we did not run
- BF16 DiT + BF16 TE (14.23 + 17.53 GB). UMA can hold it. INT8 is the Comfy template.
- Official 2752×1536 and 2400×1792 Hub aspect table.
- Ten-reference composition.
- Prompt-rewrite checkpoints (
Qwen-Image-2.1-PE-T2I/PE-I2I). Those are 9B VL models; they do not share this GB10 with the generator tonight. - vLLM-Omni
--omnior SGLang-Diffusion. Day-0 claims exist. Comfy is what we stood. - Side-by-side vs Qwen-Image 2512 fp8 on the Radeon 8060S.
Deployment recommendations
- Drain the 99 GB LLM first. Do not stack Image-2.1 next to Flash-Next or H3.
- Take Comfy master from today, not a frozen H3 tree.
QwenImage21lives incomfy/ldm/qwen_image21/. - INT8 ConvRot + Qwen3-VL-8B INT8 + BF16 VAE is the template pin. CLIPLoader
type=qwen_image. - T2I:
CLIPTextEncodeorTextEncodeQwenImage21without refs. Edits:TextEncodeQwenImageEdit+VAEEncode. Do not sendimage_1=intoTextEncodeQwenImage21. - cfg stays 1 unless you add a real negative.
- Budget 20 s for 1024/25, 128 s for 2048/25, ~28 s per edit at 1024/25.
- Keep H3 on the box that has the H3 tree. Identify that box by
~/MiniMax-H3on disk.
Reproducing
# spark-d369, after Flash-Next is down
git clone --depth 1 https://github.com/comfyanonymous/ComfyUI.git
cd ComfyUI
python3 -m venv --system-site-packages .venv
.venv/bin/pip install -r requirements.txt huggingface_hub
# snapshot_download Comfy-Org/Qwen-Image-2.1 allow_patterns:
#   diffusion_models/qwen_image_2.1_int8_convrot.safetensors
#   text_encoders/qwen3vl_8b_int8_convrot.safetensors
#   vae/qwen_image_2.1_vae_bf16.safetensors
# into ./models
.venv/bin/python main.py --listen 0.0.0.0 --port 8188 --disable-auto-launch --fast autotune
Harness and JSON: smfworks/NemoKnowledgebase/benchmarks/qwen-image-2.1-d369.
Upstream: QwenLM/Qwen-Image-2.1, Comfy-Org/Qwen-Image-2.1, Comfy t2i template image_qwen_image_2_1_t2i.json.
Verification notes
Checked 20 September 2026:
- DiT param count 7,115,124,736 BF16 — Hugging Face
safetensors.parametersonQwen/Qwen-Image-2.1. - Architecture —
transformer/config.json: 32 layers, 32 heads, head dim 128,causal_condition: true, classQwenImage21Transformer2DModel. - Comfy-Org file sizes — Hub tree: DiT INT8 7.257 GB, TE INT8 9.351 GB, VAE BF16 0.676 GB. On-disk
ls -lhwas 6.8G / 8.8G / 645M (GiB). - License — Hub tag
license:other, cardqwen-research. Not Apache-2.0. - Gated —
Qwen/Qwen-Image-2.1gated: false. - Wall times —
results/2026-09-20-full-suite.jsonandresults/2026-09-20-edits.json. 20.03 s cells are 4 s poll granularity. - H3 — curl to spark-56bc
:8188/system_statsreturned 200 before, during, and after.
spark-d369 · ComfyUI 0.36.0 9907383 · torch 2.12.1+cu130 · 2026-09-20 11:50–12:02 EDT