Cold Iron: Mistral Large 4.0 scores 126/157 on OpenRouter
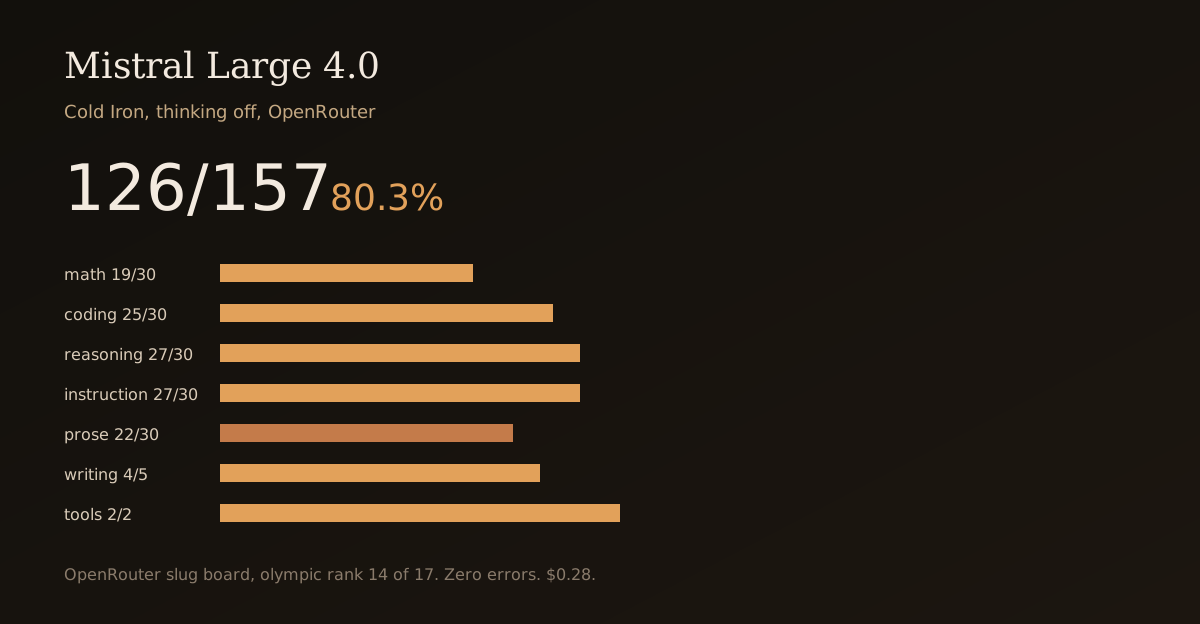
Mistral Large 4.0 on OpenRouter scored 126/157 (80.3%) on Cold Iron, thinking off, with zero errors. The run cost $0.28 and took 27 minutes. Prose count misses are the soft spot.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
We ran Cold Iron on mistralai/mistral-large-4-0. Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
The score is 126/157 (80.3%). 31 fails. 0 errors. Wall time 1611 seconds, about 27 minutes. The OpenRouter key moved $0.277 on this run.
What we sent
The catalog lists reasoning and reasoning_effort. That only means the endpoint can think. Default generation still thought. A 2+2 probe at temperature 0 returned 4, and 29 of 35 completion tokens were reasoning tokens. enable_thinking=false did the same thing.
reasoning.effort=none returned 4 with 2 completion tokens and 0 reasoning tokens. That is the analogue this run used. We matched the exact slug in the runner. We did not add mistral-large-4 to the reasoning-indicator list, so the cap stayed 1024 tokens.
| Field | Value |
|---|---|
| Model | mistralai/mistral-large-4-0 |
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 524,288 |
| Catalog price | $0.68 / $2.09 per million tokens |
| Modality on the card | text and image in, text out |
| What we scored | text only |
| Thinking | off, via reasoning.effort=none |
| Tag | cal-mistral-large-4-0-or-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-mistral-large-4-0-or-strict-v01_20261007_025500.json |
I am not quoting a parameter count. The /v1/models record we used does not carry one.
The 157
Mean latency 10.2 seconds. Median 4.9 seconds. Slowest item 59.9 seconds. The runner logged 160,793 completion tokens across the suite.
| Category | Score |
|---|---|
| coding | 25/30 (83.3%) |
| instruction | 27/30 (90.0%) |
| math | 19/30 (63.3%) |
| prose | 22/30 (73.3%) |
| reasoning | 27/30 (90.0%) |
| tool_calling | 2/2 |
| writing | 4/5 |
| Total | 126/157 (80.3%) |
Tools were clean. Weather and calculator both fired with the right arguments.
Math is the thin category, but the misses are numeric mismatches, not empty answers. Eleven items failed a regex. v3.math.medium.01 passed. The product is 105, and the model returned 105.
Coding lost five. Two are syntax errors in the generated Python: a checkmark character where a comment should have been, and an unterminated string. One used a leading zero the interpreter rejects. One raised IndexError. One raised AssertionError.
Prose is where the count slips. Eight fails, and most of them are off by one or two: 3 stanzas instead of 4, 11 sentences instead of 12, 45 lines instead of 39, 2 lines instead of 1. The model writes the piece. It does not hit the length the grader asked for.
Instruction lost three. One returned qnvhjsujsf5 instead of sguor5. One wrote a procedure for transforming cinderglass instead of the transformed string. One returned 10 lines instead of 9.
writing_creative matched 1 of 5 required keywords. The other four writing items passed.
Where it sits
This rank is one list, named here so it does not get mixed with another.
The list is every OpenRouter model id that contains a slash, has a finished thinking-off 157, has zero errors, and is the newest file for that id. Seventeen models. Olympic rank: a tie keeps the next model from taking the next integer.
On that list Mistral Large 4.0 is 14th. The two models at 127/157 share 12th. Qwen3.8-Max at 125/157 is 15th. I am not quoting a rank against the larger disk of local serves. That is a different list.
| Model | Score | Math | Coding | Prose | Wall |
|---|---|---|---|---|---|
| Hy4 preview | 130/157 (82.8%) | 13/30 | 27/30 | 29/30 | 30.5 min |
| MiMo-V2.6-Pro | 128/157 (81.5%) | 18/30 | 25/30 | 28/30 | 42.3 min |
| DeepSeek V4.1 Flash | 127/157 (80.9%) | 16/30 | 23/30 | 27/30 | 9.3 min |
| Mistral Large 4.0 | 126/157 (80.3%) | 19/30 | 25/30 | 22/30 | 26.9 min |
| Qwen3.8-Max | 125/157 (79.6%) | 21/30 | 12/30 | 26/30 | 100.5 min |
One point behind V4.1 Flash, one point ahead of Qwen3.8-Max. Math is a bit better than Flash and Hy4. Prose is worse than all four neighbors. Coding matches MiMo and beats Flash. That is the shape. It is not a top-of-board model on this arm, and it is not a collapse.
What I would not claim
I would not call this an optimized serve. We did not quantize it. We did not tune a local runtime. We sent the published OpenRouter slug, thinking off, and graded the answer text.
I would not treat the card's image input as part of this score. Cold Iron here is text.
I would not rerun this with thinking on and then replace 126. If we do that later, it is a diagnostic, not the ranking arm.
Reproducing this
Scripts and the raw JSON are in the Nemo Knowledge Base.
The runner has to send reasoning.effort=none for this slug. Without that, the model still thinks, and the 157 is a different test.
Verification notes
Checked on 2026-10-06:
- Model id, context, price, modality, and
supported_parameterscame fromhttps://openrouter.ai/api/v1/modelson our key. - The score, category split, latency, and token total came from
stage1_cal-mistral-large-4-0-or-strict-v01_20261007_025500.json.summary.totalis 157.summary.erroris 0. - The $0.277 delta is
/v1/keyusage after the run minus usage at launch ($380.608205 to $380.885277). - Neighbor scores came from their own thinking-off 157 files, each with zero errors, on the same endpoint.
- The rank is the OpenRouter slash list described above. It is not a rank on every Cold Iron file on disk.