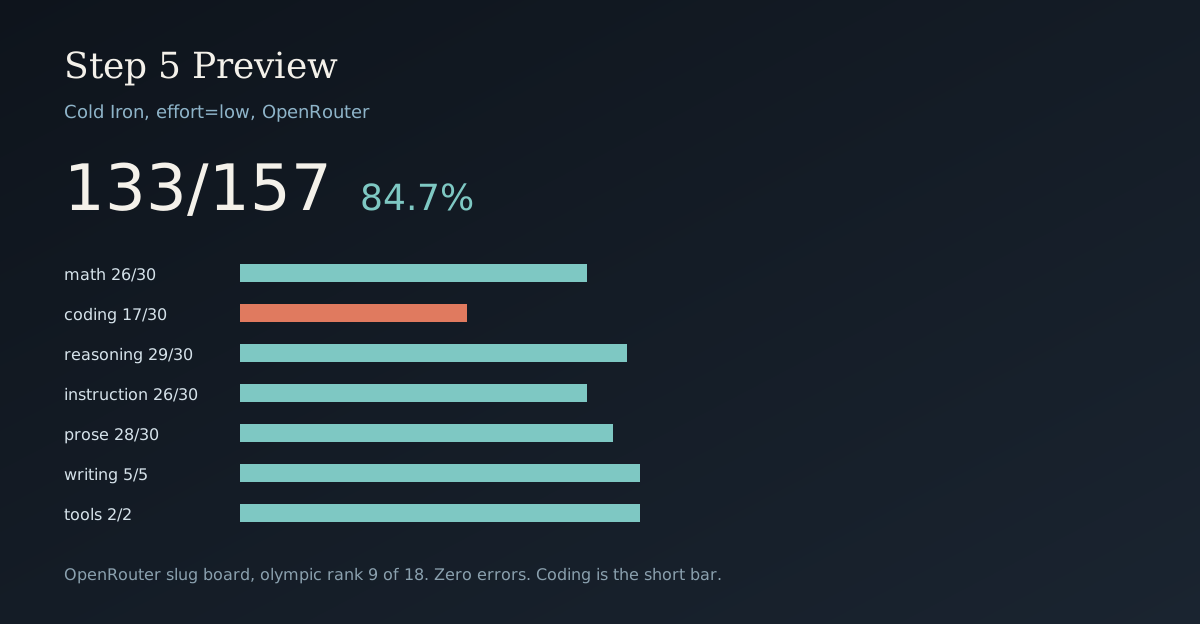
Cold Iron: Step 5 Preview scores 133/157. Read the coding floor.
stepfun/step-5-preview will not turn reasoning off. Send reasoning.effort=low. On that arm it scored 133/157 with zero errors. Coding is 17/30. The frontier misses filled a 4096-token budget.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
If you call stepfun/step-5-preview and you want the thinking-off arm, do not send reasoning.effort=none. That request comes back HTTP 400. Send reasoning.effort=low. Then do not stop at the headline score. Open the coding column before you decide the model can carry a long coding job.
We ran Cold Iron on that analogue. Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
The score is 133/157 (84.7%). 24 fails. 0 errors. Wall time 1882.4 seconds, 31.4 minutes. The OpenRouter key moved $0.705 on this run.
A same-day one-shot HTML piece on this slug is a different test. It is not this score. That post says so.
What to send
OpenRouter lists the slug as stepfun/step-5-preview. The catalog record we used has context 1,000,000, list price $1 / $2.70 per million tokens, and reasoning.mandatory true. Supported efforts are high, medium, and low. Default effort is medium. effort=none is not in that list.
Smoke, temperature 0, prompt What is 2+2? Reply with the number only.:
| What we sent | What came back |
|---|---|
Default, max_tokens=64 |
content 4, 44 reasoning tokens |
enable_thinking=false |
content 4, 44 reasoning tokens |
reasoning.effort=none |
HTTP 400, reasoning is mandatory |
reasoning.enabled=false |
HTTP 400, same message |
reasoning.effort=low, max_tokens=1024 |
content 4, 26 reasoning tokens |
effort=minimal also landed 4 with 26 reasoning tokens. It is not a catalog effort. We used low.
We matched the exact slug in the runner. We did not add stepfun to the reasoning-indicator list, so tests that do not set their own cap stay at 1024 tokens. Coding items in this suite set their own cap at 4096. That is the budget the coding fails actually had.
An identity probe at max_tokens=1024 and effort=low returned: "I am Step, a large language model developed by StepFun." A tool smoke returned get_weather with city Boston.
| Field | Value |
|---|---|
| Model | stepfun/step-5-preview |
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 1,000,000 |
| Catalog price | $1.00 / $2.70 per million tokens |
| Card | text, image, and video in; text out |
| What we scored | text only |
| Thinking | off analogue, reasoning.effort=low |
| Tag | cal-step-5-preview-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-step-5-preview-strict-v01_20261010_104152.json |
StepFun's own page describes a sparse MoE, about 600B total parameters and about 27B active, with open weights planned for October 15. The OpenRouter description says the same 27B / 600B split. We did not load weights. The catalog record we used has hugging_face_id null. Today is October 10.
The 157
Mean latency 12.0 seconds. Median 7.6 seconds. Slowest item 42.1 seconds. The runner logged 269,357 total tokens across the suite. That field is prompt plus completion, not completion alone.
| Category | Score |
|---|---|
| coding | 17/30 (56.7%) |
| instruction | 26/30 (86.7%) |
| math | 26/30 (86.7%) |
| prose | 28/30 (93.3%) |
| reasoning | 29/30 (96.7%) |
| tool_calling | 2/2 |
| writing | 5/5 |
| Total | 133/157 (84.7%) |
Tools were clean. Weather and calculator both fired with the right arguments. Writing matched the keywords on all five items.
Math lost four, all expert, all numeric mismatches. Two of those are ordinary misses inside a normal budget. v3.math.expert.06 used 418 tokens in 2.6 seconds and did not match -0.01384. v3.math.expert.07 used 1,321 tokens in 7.0 seconds and did not match -9.417. The other two expert misses used about 4,300 tokens. We did not save the answer text, so I am not calling those truncation.
Reasoning lost one. v3.reasoning.frontier.07 did not match 292. It used 4,276 tokens.
Instruction lost four. Two are short line counts (expected 6, got 2 and 3) on items that used about 4,200 tokens. One returned a9gre9dnickk12 instead of a9gre9dni9ckk13, in 910 tokens. One was asked for 3 stanzas and returned 48.
Prose lost two, both stanza counts. Expected 7, got 44. Expected 1, got 5. Both of those items used more than 4,200 tokens.
Read the coding floor
Coding is the column that changes the headline.
Easy coding was 2/2. Medium was 3/3. Hard was 4/5. Expert was 6/8. Frontier was 2/12.
Of the 13 coding fails, 12 are SyntaxError. Ten of those are unterminated string literals. Two are invalid decimal literals. The remaining fail is a NameError on v3.coding.expert.02. That one used 1,024 tokens in 6.2 seconds, and the grader ran the code, so it parsed.
The 12 syntax fails are a different shape. Each coding item in this suite allows 4,096 completion tokens. Those 12 fails used 4,276 to 4,661 total tokens and took 27 to 41 seconds. The frontier prompts are short. v3.coding.frontier.01 asks for one function, count_avoiding, and tells the model to output a single Python code block. A short prompt plus a total near 4,400 tokens means the generation sat on that 4,096 cap.
The result file does not store finish_reason. I will not claim every syntax fail ended on length. I will say this: do not read 17/30 as "it cannot write Python." Easy and medium passed. The frontier misses did not return a complete parseable program inside the budget this suite allows.
If you need those frontier items, raise the cap and treat that run as a different test. We did not re-run them. This score stays the 4096-cap arm.
Where it sits
This rank is one list, named here so it does not get mixed with another.
The list is every OpenRouter model id that contains a slash, has a finished thinking-off 157, has zero errors, and is the newest file for that id. Eighteen models, including this one. Olympic rank: a tie keeps the next model from taking the next integer.
On that list Step 5 Preview is 9th. Union Alpha at 136/157 is 8th. Hy4 preview at 130/157 is 10th. I am not quoting a rank against local serves. That is a different list.
| Model | Score | Math | Coding | Reasoning | Wall |
|---|---|---|---|---|---|
| Union Alpha | 136/157 (86.6%) | 24/30 | 26/30 | 30/30 | 275.7 min |
| Step 5 Preview | 133/157 (84.7%) | 26/30 | 17/30 | 29/30 | 31.4 min |
| Hy4 preview | 130/157 (82.8%) | 13/30 | 27/30 | 27/30 | 30.5 min |
Three points behind Union Alpha, three points ahead of Hy4. Math is better than both neighbors. Coding is worse than both. That is the shape. The 84.7% is a mid-pack text score on the off analogue, not a coding-agent result.
Wall time is the runner clock, including whatever the provider spent in queue. I am not turning 31.4 minutes against Union Alpha's 275.7 minutes into a speed claim.
The two models tied at 153/157 sit at rank 1 on this same list. This run is not in that band.
What I would not claim
I would not call this an optimized serve. We did not quantize it. We did not tune a local runtime. We sent the published OpenRouter slug, on the lowest catalog effort that does not 400, and graded the answer text.
I would not treat the card's image and video input as part of this score. Cold Iron here is text.
I would not paste StepFun's published High-effort numbers into this table. Their page reports DeepSWE v1.1 at 67.7 and StepCodeBench at 49.0 for Step 5 Preview (High). Those are their measurements, on a different effort, in a different harness. They are not this 157.
I would not rerun this with thinking on and then replace 133. If we do that later, it is a diagnostic, not the ranking arm.
Reproducing this
Scripts and the raw JSON are in the Nemo Knowledge Base.
The runner has to send reasoning.effort=low for this exact slug. enable_thinking=false alone still thinks. Without the effort field, the 157 is a different test.
Verification notes
Checked on 2026-10-10:
- Model id, context, price, modality,
supported_parameters, and the reasoning block came fromhttps://openrouter.ai/api/v1/modelson our key. Canonical slug on that record:stepfun/step-5-preview-20261008. Created timestamp 1791462849, which is 2026-10-08 12:34 UTC. - The same id, the $1 / $2.70 price, and the October 8 release line are on OpenRouter's model page.
- The 600B / 27B split and the October 15 open-weights line are on StepFun's Step 5 Preview page. The OpenRouter model description states the same parameter split. We did not re-run their benchmarks.
- The score, category split, latency, token total, and per-test fail details came from
stage1_cal-step-5-preview-strict-v01_20261010_104152.json.summary.totalis 157.summary.erroris 0.summary.passedis 133. - Coding
max_tokens: 4096is insuites/quality/tier0_deterministic/coding.yaml, includingv3.coding.frontier.01. - The $0.705 figure is
/v1/keyusage after the run minus usage at launch: 381.611933998 minus 380.907280598, which is 0.704653. - Neighbor scores came from their own thinking-off 157 files, each with zero errors, on the same endpoint, newest file per model id.
- The rank is the OpenRouter slash list described above. It is not a rank on every Cold Iron file on disk.