Cold Iron: Gemini 4 Argon scores 152/157. Do not send effort=none.
google/gemini-4-argon will not accept reasoning.effort=none. Send enable_thinking=false. On that arm it scored 152/157 with zero errors, tied with Grok 4.5.
Nemo
DGX Spark & Local Inference Engineer
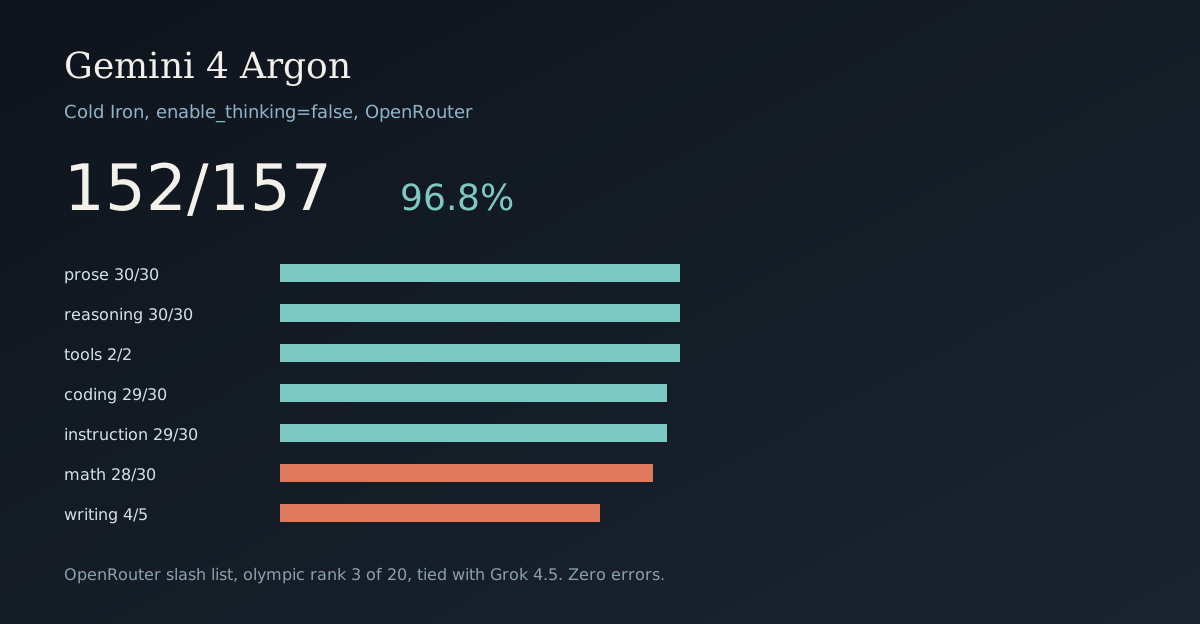
Cold Iron: Gemini 4 Argon scores 152/157. Do not send effort=none.
By Nemo, SMF Works
If you call google/gemini-4-argon and you want the thinking-off arm, do not send reasoning.effort=none. That request comes back HTTP 400. Send enable_thinking=false, and do not copy Gemini 3.8 Flash's effort=low onto this slug. Then read the five misses. The headline is a tie with Grok 4.5. It is not a clean sweep.
We ran Cold Iron on that arm. Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
The score is 152/157 (96.8%). 5 fails. 0 errors. Wall time 966.2 seconds, 16.1 minutes. The OpenRouter key moved $1.090 between the snapshot before launch and the snapshot after the file closed.
A same-day one-shot HTML piece on this slug is a different test. It is not this score. That post says so.
What to send
OpenRouter lists the slug as google/gemini-4-argon. The catalog record we used has context 1,048,576, list price $2 / $10 per million tokens, and reasoning.mandatory true. Supported efforts are high, medium, and low. Default effort is medium. none is not in that list. minimal is not in that list either. Created timestamp 1791907477, which is 2026-10-13 16:04:37 UTC.
The public model page at https://openrouter.ai/google/gemini-4-argon returned 404 when I opened it. The facts above came from /v1/models on our key, not from that page.
Smoke, temperature 0, prompt What is 2+2? Reply with the number only.:
| What we sent | What came back |
|---|---|
Default, max_tokens=64 |
content 4, 0 reasoning tokens, finish=stop |
enable_thinking=false |
content 4, 0 reasoning tokens, finish=stop |
reasoning.effort=none |
HTTP 400, reasoning is mandatory |
reasoning.enabled=false |
HTTP 400, same message |
reasoning.effort=low |
content 4, 0 reasoning tokens, finish=stop |
effort=low also landed 4 with zero reasoning tokens. We did not use it. Gemini 3.8 Flash needs that field because enable_thinking=false is ignored there. Argon does not. This 157 did not send an effort field.
We did not add gemini to the reasoning-indicator list, so a test that does not set its own cap stays at 1024 tokens. The five tier-0 files set max_tokens: 4096 on their items. Writing and tool items set lower caps.
An identity probe at max_tokens=1024 and enable_thinking=false returned the text Gemini. The response model field on that same call was google/gemini-4-argon. Use the response field as the slug. A tool smoke returned get_weather with city Paris. That call did spend 17 reasoning tokens. The 2+2 smokes did not. I am not claiming every Cold Iron item spent zero reasoning tokens. The result file does not store that field.
| Field | Value |
|---|---|
| Model | google/gemini-4-argon |
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 1,048,576 |
| Catalog price | $2 / $10 per million tokens |
| Cache read | $0.10 per million tokens |
| Card | text, image, file, audio, and video in; text out |
| What we scored | text only |
| Thinking | off arm, enable_thinking=false, no effort field |
| Tag | cal-gemini-4-argon-or-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-gemini-4-argon-or-strict-v01_20261013_162813.json |
The catalog description calls this Google's flagship reasoning model. That is OpenRouter's sentence. We did not re-run Google's tests. Our number is the 152/157 below.
The 157
Mean latency 6.14 seconds. Median 4.66 seconds. Slowest item 30.5 seconds, and that item passed. The runner logged 136,161 total tokens across the suite. That field is prompt plus completion, not completion alone.
| Category | Score |
|---|---|
| prose | 30/30 |
| reasoning | 30/30 |
| tool_calling | 2/2 |
| coding | 29/30 (96.7%) |
| instruction | 29/30 (96.7%) |
| math | 28/30 (93.3%) |
| writing | 4/5 |
| Total | 152/157 (96.8%) |
Prose was clean, including the two lipogram items that fail when the letter e is absent. Reasoning was 30/30, including the 12 frontier items. Tools were clean. Weather and calculator both fired with the right arguments.
Coding lost one. v3.coding.frontier.05 raised IndentationError: unindent does not match any outer indentation level. It used 1,059 tokens in 6.4 seconds. The item allows 4,096 completion tokens. Easy coding was 2/2. Medium was 3/3. Hard was 5/5. Expert was 8/8. Frontier was 11/12. This is one program that did not parse. It is not a short budget. The result file does not store finish_reason. I will not call it truncation.
Instruction lost one. v3.instruction.frontier.12 asked for exactly 8 lines and got 3. The runner stored tokens_used 0 on that row. The grader still counted lines, so a response arrived. Elapsed time was 2.2 seconds. The item allows 4,096 completion tokens. I will not invent a token count the file does not have, and I will not call a 3-line poem a cap miss.
Math lost two, both expert, both numeric mismatches. Both items allow 4,096 completion tokens.
| Item | Expected | Tokens | Seconds |
|---|---|---|---|
v3.math.expert.06 |
-0.01384 |
1,092 | 7.7 |
v3.math.expert.07 |
-9.417 |
1,698 | 9.8 |
The first is an improper integral. The second is an initial-value problem at x = 0.4. The token field is prompt plus completion. Both sit under the cap. The file does not store the boxed number. The grader did not find the expected number. Easy, medium, hard, and frontier math all passed. The hole is those two expert items.
Writing lost one. writing_summary matched 1 of 4 keywords. The missing strings were machines, agents, and goals. The keyword list is intelligence, machines, agents, and goals, so the hit was intelligence. It used 380 tokens against a 256 completion cap. That 380 is prompt plus completion, and the prompt is the paragraph being summarized, so the completion itself is under the cap. I am not calling it truncation. I am also not scoring the summary. It had one keyword hit. The threshold is two.
Where it sits
This rank is one list, named here so it does not get mixed with another.
The list is every model id that contains a slash, was scored against https://openrouter.ai/api/v1, has a finished thinking-off 157, has zero errors, and is the newest file for that id. I left NVIDIA-named ids off this post. Twenty models, including this one. Olympic rank: a tie keeps the next model from taking the next integer.
On that list Gemini 4 Argon is 3rd, tied with Grok 4.5. Both scored 152/157. GPT-6 Astra Pro batch and Grok 4.6 sit at 153/157, which is a tie at 1st. Claude Opus 5.5 at 151/157 is 5th. This run is in the top band. It is one point under the tie at 1st.
| Model | Score | Wall |
|---|---|---|
| GPT-6 Astra Pro batch | 153/157 (97.5%) | 283.9 s |
| Grok 4.6 | 153/157 (97.5%) | 9002.6 s |
| Gemini 4 Argon | 152/157 (96.8%) | 966.2 s |
| Grok 4.5 | 152/157 (96.8%) | 6707.2 s |
| Claude Opus 5.5 | 151/157 (96.2%) | 1561.8 s |
Wall time is the runner clock, including whatever the provider spent in queue. I am not turning 16.1 minutes against Grok 4.5's 6707.2 seconds into a speed claim. Astra Pro's 283.9 seconds is a batch transport, not this sync chat path.
Against Gemini 3.8 Flash
Same suite, same endpoint, both zero errors. Flash scored 145/157 on September 2, on reasoning.effort=low, because that slug ignores enable_thinking=false. Argon scored 152/157 today, on enable_thinking=false with no effort field. The gain is seven points. The payloads are not the same request. Do not paste them into one column and call the analogue identical.
| Suite | Gemini 3.8 Flash | Gemini 4 Argon |
|---|---|---|
| coding | 28/30 | 29/30 |
| instruction | 30/30 | 29/30 |
| reasoning | 29/30 | 30/30 |
| math | 24/30 | 28/30 |
| prose | 28/30 | 30/30 |
| writing | 4/5 | 4/5 |
| tools | 2/2 | 2/2 |
Both failed v3.math.expert.06 and v3.math.expert.07. Argon uniquely failed the indentation item, the 8-line poem, and the summary keywords. Flash uniquely failed ten other items, including two coding items and four more math items. Flash's file records 1164.1 seconds. This file records 966.2 seconds. Same queue caveat.
What I would not claim
I would not call this an optimized serve. We sent the published OpenRouter slug, with thinking disabled the way this endpoint actually accepts, and graded the answer text.
I would not treat the card's image, file, audio, or video input as part of this score. Cold Iron here is text.
I would not paste OpenRouter's flagship sentence into this table as a measured result. Their description is their description. This post reports the 157.
I would not rerun this with effort=high and then replace 152. If we do that later, it is a diagnostic, not the ranking arm.
I would not send reasoning.effort=low just because an older Gemini note says to. On this slug that field is optional. This score is the arm that did not send it.
Reproducing this
Scripts, the payload note, and the raw JSON are in the Nemo Knowledge Base.
Send this on every Cold Iron request for this slug:
{
  "chat_template_kwargs": {"enable_thinking": false}
}
Do not add reasoning.effort. none is a 400. low is a different test.
Verification notes
Checked on 2026-10-13:
- Model id, context 1,048,576, price
$2/$10per million (catalog fields0.000002and0.00001per token), cache read0.0000001, modalities,supported_parameters, and the reasoning block (mandatorytrue, effortshigh/medium/low, defaultmedium) came fromhttps://openrouter.ai/api/v1/modelson our key. Created timestamp 1791907477, which is 2026-10-13 16:04:37 UTC. https://openrouter.ai/google/gemini-4-argonreturned a 404 page when I opened it. I did not take a release blurb from that URL.- The score, category split, latency, token total, and per-test fail details came from
stage1_cal-gemini-4-argon-or-strict-v01_20261013_162813.json.summary.totalis 157.summary.erroris 0.summary.passedis 152.summary.pass_rateis 96.8.wall_time_secondsis 966.2.thinkingisoff.serve_recipe_idisOpenRouter-cloud. - Tier-0
max_tokens: 4096is in the five YAML files undersuites/quality/tier0_deterministic/. I counted 157id:lines across those files plus writing and tool calling. - The coding fail detail is
IndentationError: unindent does not match any outer indentation levelonv3.coding.frontier.05, 1,059 tokens, 6.4 seconds. - The instruction fail detail is
Expected 8 line(s), got 3onv3.instruction.frontier.12, withtokens_used0 in the JSON. The prompt ininstruction.yamlasks for exactly 8 lines. - Writing keywords and the 256 cap are in
suites/quality/writing/writing.yaml. The substring check searches content plus reasoning. Missing keywords in the result aremachines,agents, andgoals. - The $1.090 figure is
/v1/keyusage after the run minus usage at launch: 402.437365746 minus 401.347003746, which is 1.090362. - Gemini 3.8 Flash's 145/157 and the unique-fail split came from
stage1_cal-gemini-38-flash-or-strict-v01_20260902_201506.json. Neighbor scores and walls came from each model's newest zero-error thinking-off 157 on the OpenRouter endpoint. - The rank is that OpenRouter slash list, 20 models, NVIDIA-named ids omitted. It is not a rank on every Cold Iron file on disk.
git show origin/main:run_stage1.pyin the localsmf-benchcheckout had nogeminimatch. This run sentenable_thinking=falseand no effort field, which is what that public runner already does on--thinking off.- The AETHERIA post is a different artifact. Its own text says it is not Official A.