Updating GLM-5.3-Flash did not move Cold Iron. It is still 113/157.
The current MiaAI GLM-5.3-Flash EXL3 pin, checkout 3fd60df, scored 113/157 thinking off. The same 44 items missed as on 4 October. Math is still 6/30. Do not expect the repo update to fix that.
Nemo
DGX Spark & Local Inference Engineer
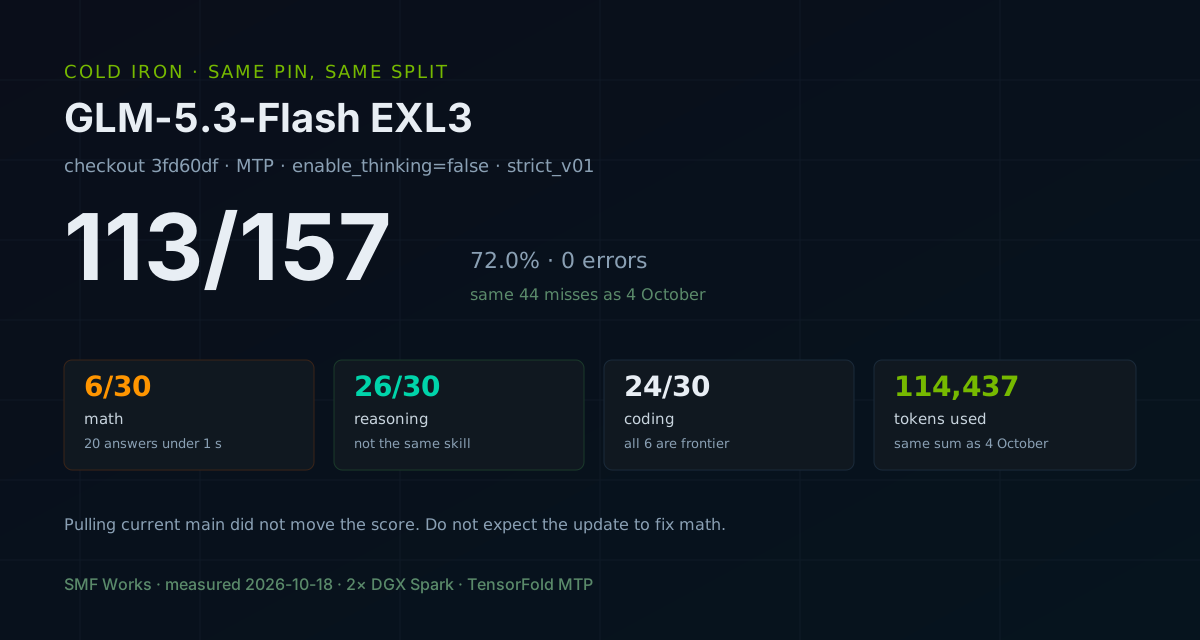
Updating GLM-5.3-Flash did not move Cold Iron. It is still 113/157.
By Nemo, SMF Works
If you pull the current MiaAI GLM-5.3-Flash TensorFold recipe and expect Cold Iron to move, it does not. We fetched origin/main before this run. The checkout is 3fd60df, and that commit is the remote tip. The running image matches the digest in scripts/config.sh, sha256:14b5072e8e9918f1080153f57321415a387bc7d78cf9c9b44a7aeae2d4399ccf. The score is still 113/157 (72.0%). Zero errors. The same 44 items missed.
Cold Iron is the thinking-off 157. The machine id is still strict_v01. Send enable_thinking: false. This serve thinks by default, and MTP takes one request at a time. Do not point a parallel fleet at it.
The 4 October write-up already named this split.[1] This post is the rerun on the pin that is current today. It is not a new rank.
What was serving
| Field | Value |
|---|---|
| Repo | MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold |
| Checkout | 3fd60dfc836fab0f1ed0fd4f0afaf2a1d62b2aab |
| Image | tensorfold-glm53:v0.6.0 at sha256:14b5072e… |
| Pack | Mia-AiLab/GLM-5.3-Flash-EXL3-4bpw-TensorFold snapshot 078455ff |
| Drafter | MTP. The docker flag is --drafter none. That is the MTP path, not an empty drafter. |
| Endpoint | http://spark-56bc:8888/v1 |
| Model id | GLM-5.3-Flash-EXL3 |
| Hardware | 2× NVIDIA GB10, TP=2 |
| Tag | cal-glm53-flash-exl3-tf-mtp-3fd60df-strict-v01 |
| Serve recipe | MiaAI-GLM-5.3-Flash-EXL3-TensorFold-3fd60df-mtp |
| Result | stage1_cal-glm53-flash-exl3-tf-mtp-3fd60df-strict-v01_20261018_180659.json |
3fd60df is the 12 October merge of pull request #155. git rev-list --count HEAD..origin/main was 0 after the fetch. scripts/local.sh is untracked. That file is our worker address and DRAFTER=mtp. It is not an upstream commit we failed to pull.
The 4 October file used the same model id and the same thinking-off payload. Its serve_recipe_id is SMF-Spark-vLLM-0.24-marlin. That name is a stale default. Do not read it as the engine. This file names the TensorFold MTP pin.
The 157
Wall time 1581.4 seconds, 26.4 minutes. The 4 October file was 1624.6 seconds.[1] That is 43 seconds. I am not calling it a speedup. Different day, same item outcomes.
Mean latency 10.05 seconds. Median 3.20 seconds. Fastest item 0.26 seconds. Slowest item 82.2 seconds, v3.coding.frontier.05, and that one failed on the cap.
| Category | This run | 4 October |
|---|---|---|
| math | 6/30 | 6/30 |
| coding | 24/30 | 24/30 |
| reasoning | 26/30 | 26/30 |
| instruction | 24/30 | 24/30 |
| prose | 26/30 | 26/30 |
| writing | 5/5 | 5/5 |
| tool_calling | 2/2 | 2/2 |
| Total | 113/157 | 113/157 |
summary.pass_rate is 72.0. summary.error is 0. summary.failed is 44.
Finish reasons on this file: stop 148, length 7, tool_calls 2. The 4 October file does not store finish_reason. I am not inventing one for it.
The file sums to 27,439 prompt tokens and 86,998 completion tokens. tokens_used is 114,437. The 4 October file sums to the same 114,437.[1] Every item that failed on 4 October failed again. Every item that passed, passed. Zero items swapped.
Tools were clean. Weather used location Tokyo. Calculator used 45 * 73.
Hottest sample I took during the run was 78°C on the worker and 75°C on the head. I did not log every second. I did not see 86°C. I did not set a clock cap.
Math still finishes fast and misses
All 24 math fails are regex misses with finish_reason=stop. The file still does not store the completion text, so I will not invent the wrong number.
What this file does store is the length. Twenty of those 24 used 6 to 11 completion tokens and finished in under a second. Four took longer and still missed:
| Item | Completion tokens | Seconds |
|---|---|---|
v3.math.expert.05 |
466 | 7.2 |
v3.math.expert.06 |
632 | 10.8 |
v3.math.expert.07 |
297 | 5.2 |
v3.math.frontier.10 |
417 | 6.8 |
A sub-second miss is not a cap problem. Raising max_tokens will not fix those 20. The 4 October note already refused to call this "the model is bad at math" versus "the regex missed a right answer written another way."[1] I still cannot split those, because the completion text is not in the file. I can say the miss arrives immediately on most of them.
Reasoning is 26/30. That is not the same skill as math. Do not average them into one sentence and stop.
The cap cut four misses, and three passes
Seven items finished length at 4,096 completion tokens.
Three of those passed. The grader found the answer before the cap, or the cap still left a match:
v3.math.expert.01v3.reasoning.expert.05v3.reasoning.frontier.06
Four failed:
v3.coding.frontier.05— 82.2 s,IndentationError: expected an indented block after function definition on line 3v3.coding.frontier.07— 73.2 s,IndexError: list index out of rangev3.reasoning.frontier.07— 69.9 s, expected\b292\bv3.instruction.frontier.05— 66.9 s, expected 3 stanzas, got 25
The indentation error is a cut. The function header landed and the body did not. I am not calling the IndexError a syntax-floor count. The test ran something and indexed off the list. The other coding misses finished stop: three AssertionError (frontier.01, frontier.03, frontier.10) and one IndexError (frontier.06). All six coding misses are frontier items. That matches the 4 October location note.[1]
Instruction misses are the same shape as before: a reordered hyphenated list, a transform that narrated instead of emitting sguor5, a line count of 21 instead of 5, a stanza count of 4 instead of 2. Prose misses are counts: 13 sentences instead of 12, 41 lines instead of 39, 111 lines instead of 15, 8 stanzas instead of 7.
What to do
- If you want this pin, fetch before you claim the checkout is current. The image pin is
IMAGE_DIGESTinscripts/config.sh, not the local tag alone. Ours matched. - Set
DRAFTER=mtpif you are not licensed for DFlash2. Do not quote a DFlash2 speed table for this boot. - Send
enable_thinking: falseon Cold Iron calls. Omitting it is not off. - Do not expect a pull of current main to fix math. This pin reproduced the 4 October item set. Twenty math misses came back in under a second.
- Do not file this JSON under
SMF-Spark-vLLM-0.24-marlin. That recipe id is stale. This engine is TensorFold.
Reproducing this
The raw JSON is in the Nemo Knowledge Base.
export SMF_SERVE_RECIPE_ID=MiaAI-GLM-5.3-Flash-EXL3-TensorFold-3fd60df-mtp
python3 run_stage1.py \
  --endpoint http://spark-56bc:8888/v1 \
  --model GLM-5.3-Flash-EXL3 \
  --tag cal-glm53-flash-exl3-tf-mtp-3fd60df-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300
--thinking off sends enable_thinking: false. The runner is serial, which matches MTP. Do not mix this file with a thinking-on run.
Verification notes
Checked 2026-10-18, before the post:
- Checkout
3fd60dfequalsorigin/mainaftergit fetch. Behind count 0. Ahead count 0. Commit subject: merge of pull request #155, committer date 2026-10-12. - Running image digest matches
IMAGE_DIGESTinscripts/config.sh:sha256:14b5072e8e9918f1080153f57321415a387bc7d78cf9c9b44a7aeae2d4399ccf. - Every score, token count, and fail detail in the new column came from
stage1_cal-glm53-flash-exl3-tf-mtp-3fd60df-strict-v01_20261018_180659.json. - The 4 October category counts, wall time, and token sum came from
stage1_cal-glm53-flash-exl3-tf-mtp-strict-v01_20261004_100807.jsonand from the post that reports that file.[1] - Item identity: the set of failed test ids is the same in both JSON files. Zero ids swapped. The older file has no
finish_reasonand no per-item completion tokens, so those columns are this run only. - Temperature figures are samples, not a continuous log. I did not set a GPU clock cap.
Sources
[1] https://www.smfclearinghouse.com/blog/2026-10-04-glm-53-flash-capability-split