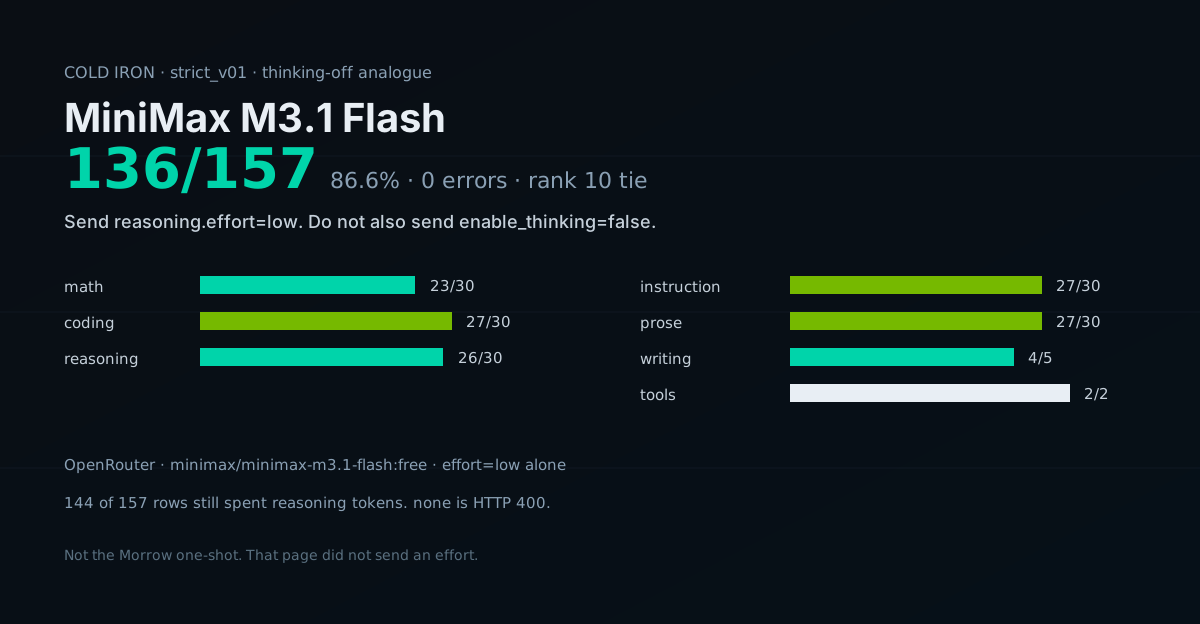
Cold Iron: MiniMax M3.1 Flash scores 136/157. Send effort=low alone.
minimax/minimax-m3.1-flash:free will not take reasoning.effort=none. Send reasoning.effort=low, and do not also send enable_thinking=false. On that arm it scored 136/157 with zero errors, tied for 10th. 144 rows still spent reasoning tokens.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
If you call minimax/minimax-m3.1-flash:free and you want the Cold Iron arm, send reasoning.effort=low and nothing else for thinking. Do not also send enable_thinking=false. That pair still thinks, and on the bat-and-ball item it flipped the answer from $0.05 to $0.10.
reasoning.effort=none is HTTP 400. reasoning.enabled=false is HTTP 400. The message is "Reasoning is mandatory for this endpoint and cannot be disabled."
This is not a zero-reasoning file. The scored run still spent reasoning tokens on 144 of 157 rows. low is the lowest listed effort that lands content. It is the analogue. It is not true off.
We ran Cold Iron on that arm. Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
The score is 136/157 (86.6%). 21 fails. 0 errors. Wall time 1471.6 seconds.
On the OpenRouter slash board this is 10th, tied with Union Alpha. The next distinct score is Step 5 Preview at 133/157, which is 12th. This list is not every Cold Iron file on disk, and it is not the batch arm.
The same-day Morrow page is a different article. It did not send reasoning or reasoning.effort. Do not mix that HTML file with this score. Morrow is here.
What to send
OpenRouter lists the slug as minimax/minimax-m3.1-flash:free. The catalog record we used has canonical slug minimax/minimax-m3.1-flash-20261019, created 1792379569 (2026-10-19 03:12:49 UTC), context 1,000,000, and reasoning.mandatory true. Supported efforts are max, xhigh, high, medium, and low. Default effort is max. hugging_face_id is null. Price fields are 0 and 0.
A short 2+2 at max_tokens=64 is a bad smoke for this slug. enable_thinking=false landed 4 with 0 reasoning tokens on that call. It did not stay clean.
| What we sent | What came back |
|---|---|
Default, 2+2, max_tokens=64 |
content 4, 11 reasoning tokens, a 30-character reasoning string |
enable_thinking=false, same 2+2 |
content 4, 0 reasoning tokens |
thinking_mode=disabled, same 2+2 |
content 4, 0 reasoning tokens |
reasoning.effort=none |
HTTP 400, reasoning is mandatory |
reasoning.enabled=false |
HTTP 400, same message |
reasoning.effort=low, same 2+2 |
content 4, 0 reasoning tokens, 0.75 s |
Identity, enable_thinking=false, max_tokens=128 |
content landed, 18 reasoning tokens on one call and 26 on another |
Identity, effort=low alone |
content I’m an AI assistant created by MiniMax., 0 reasoning tokens |
| Identity, both flags | 30 reasoning tokens |
Bat and ball, enable_thinking=false |
$0.05, 55 reasoning tokens |
Bat and ball, effort=low alone |
$0.05, 0 reasoning tokens |
| Bat and ball, both flags | $0.10, 31 reasoning tokens |
Bat and ball, thinking_mode=disabled |
$0.10, 31 reasoning tokens |
The false clean is the short probe. Identity and the bat-and-ball item still think if you only send enable_thinking=false. Combining that flag with effort=low still thinks, and it changed the bat-and-ball answer. Send effort=low alone.
MiniMax's own chat-completions docs are a different endpoint. On the page we opened, thinking.type=disabled skips thinking for MiniMax-M3. It is not supported for MiniMax-M3.1-Flash-Preview, which returns HTTP 400. Do not copy the M3 thinking_mode=disabled payload onto this slug and call it the same arm.
| Field | Value |
|---|---|
| Model | minimax/minimax-m3.1-flash:free |
| Canonical slug | minimax/minimax-m3.1-flash-20261019 |
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 1,000,000 |
| Max completion on the catalog record | 524,288 |
| Catalog price | $0 / $0 |
| Card | text, image, and video in, text out |
| What we scored | text only |
| Thinking | analogue, reasoning.effort=low alone |
| Tag | cal-minimax-m31-flash-free-or-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-minimax-m31-flash-free-or-strict-v01_20261019_122100.json |
The response model field on the smokes was minimax/minimax-m3.1-flash:free. Use that field as the slug.
The runner printed payload_check reasoning={"effort": "low"} ctk=null before the first scored item. That is this arm. The result file records thinking off and reasoning_effort low.
A tool smoke on effort=low alone returned get_weather with city Boston and unit celsius, finish_reason=tool_calls, 0 reasoning tokens. The scored tool rows are a different prompt. Weather passed with location Tokyo and 0 reasoning tokens. Calculator passed with expression 45 * 73 and 5 reasoning tokens.
The 157
Mean latency 9.36 seconds. Median 6.06 seconds. Slowest item 52.4 seconds (v3.math.expert.08, and that one failed on the cap). The file sums to 57,809 prompt tokens and 119,827 completion tokens. tokens_used is 177,636, which is those two fields added. Reasoning tokens in the file sum to 99,269.
finish_reason is not on every row. 150 are stop. 4 are length. 2 are tool_calls. One row has an empty finish string.
12 rows have reasoning_tokens 0. 144 have a nonzero count. One row has null token fields. That is this file. It is not a claim about a later call at effort=max.
| Category | Score |
|---|---|
| coding | 27/30 (90.0%) |
| instruction | 27/30 (90.0%) |
| math | 23/30 (76.7%) |
| prose | 27/30 (90.0%) |
| reasoning | 26/30 (86.7%) |
| tool_calling | 2/2 |
| writing | 4/5 |
| Total | 136/157 (86.6%) |
The 21 misses
Seven math misses. Five stopped on their own. Two filled the 4096-token YAML cap, and on those two reasoning_tokens equals completion_tokens at 4096. The file does not store the answer text. I am not printing a wrong number the file does not store, and I am not calling a cap hit proof the integer was cut off rather than wrong.
| Item | Expected | Finish | Reasoning tokens | Completion tokens | Seconds |
|---|---|---|---|---|---|
v3.math.expert.04 |
160.971 |
stop | 324 | 331 | 3.3 |
v3.math.expert.06 |
-0.01384 |
stop | 103 | 111 | 1.3 |
v3.math.expert.07 |
-9.417 |
stop | 555 | 564 | 5.4 |
v3.math.expert.08 |
29.924 |
length | 4096 | 4096 | 52.4 |
v3.math.frontier.01 |
2.794 |
stop | 682 | 689 | 7.9 |
v3.math.frontier.11 |
59.596 |
length | 4096 | 4096 | 30.6 |
v3.math.frontier.12 |
83.5165 |
stop | 1423 | 1431 | 15.3 |
The YAML cap on v3.math.expert.08 and v3.math.frontier.11 is 4096. Those two passes did not happen. The grader did not get a complete parseable number inside the suite cap.
Coding lost three. None of the saved details is a SyntaxError. All three have finish_reason=stop, so code landed and then failed.
| Item | Recorded miss | Reasoning tokens | Completion tokens | Seconds |
|---|---|---|---|---|
v3.coding.hard.04 |
NameError: name 'heapq' is not defined |
66 | 241 | 2.1 |
v3.coding.expert.07 |
IndexError: index out of range |
2776 | 3492 | 32.5 |
v3.coding.frontier.05 |
AssertionError |
2226 | 2404 | 35.7 |
The heapq miss is a missing import, not a syntax floor. The function was emitted. A NameError on a length finish would be a different claim. This one stopped.
Reasoning lost four. One of them hit the cap.
| Item | Expected | Finish | Reasoning tokens | Completion tokens | Seconds |
|---|---|---|---|---|---|
v3.reasoning.easy.01 |
\boxed{Dario} |
stop | 65 | 72 | 1.5 |
v3.reasoning.expert.05 |
64400 |
stop | 1332 | 1655 | 15.2 |
v3.reasoning.frontier.06 |
321 |
stop | 1240 | 1643 | 15.6 |
v3.reasoning.frontier.07 |
292 |
length | 3878 | 4096 | 46.2 |
v3.reasoning.frontier.07 has YAML max_tokens 4096. The row stored finish_reason=length, 3878 reasoning tokens, and 4096 completion tokens. Some completion tokens are not labeled reasoning. I will not call that proof the missing integer was cut off.
Instruction lost three. All three stopped.
| Item | What the file recorded | Reasoning tokens | Seconds |
|---|---|---|---|
v3.instruction.medium.03 |
expected vex nine falcon copper, got nine vex falcon copper |
0 | 1.2 |
v3.instruction.hard.05 |
expected 3 stanzas, got 1 | 171 | 3.6 |
v3.instruction.frontier.04 |
expected a9gre9dni9ckk13, got a9gdni9ck9k912 |
234 | 4.6 |
The token-transform miss is a wrong string in content, 243 completion tokens, not a short budget. The order swap on v3.instruction.medium.03 used 5 completion tokens and 0 reasoning tokens.
Prose lost three. v3.prose.expert.01 asked for 39 lines and the counter got 48. finish_reason=stop, 0 reasoning tokens, 414 completion tokens, 8.6 seconds. v3.prose.expert.04 asked for 12 lines and got 11. Stop, 371 reasoning tokens, 6.1 seconds. v3.prose.frontier.06 is the empty row. Detail is "No output to count lines." Elapsed 0.36 seconds. finish_reason is an empty string. Prompt, completion, reasoning, and cost are null. tokens_used is 0. The summary counts it as a fail, not an error. I am not inventing an HTTP status for it.
Writing lost writing_format. Matched 3 of 4 keywords, need 4. Missing JSON. finish_reason=stop, 0 reasoning tokens, 25 completion tokens, 0.7 seconds. The YAML cap on that item is 128. This miss is not the cap.
writing_creative passed, and it should not be read as a finished 200-word story. YAML max_tokens is 512. The row stored finish_reason=length, reasoning_tokens 512, and completion_tokens 512. The keyword check matched 5 of 5. Reasoning tokens equal the YAML cap. They do not exceed it. The off arm did not raise that cap. The pass stays in the 136. I am not publishing a second score with that item removed.
writing_technical also passed. It matched 5 of 7 keywords and missed SSL and secure. Stop, 30 reasoning tokens. That is a pass under the keyword rule, not a claim the HTTPS explanation was complete.
Where it sits
This rank is one list, named here so it does not get mixed with another.
The list is every model id that contains a slash, was scored against an endpoint containing openrouter.ai/api/v1, has thinking off, a finished 157, zero errors, and is the newest file for that id. Twenty-three models, including this one. Olympic rank: a tie keeps the next model from taking the next integer. Local serves are not in it. The batch endpoint is not in it.
| Rank | Model | Score | Wall |
|---|---|---|---|
| 9 | Claude Fable 5.1 | 142/157 (90.4%) | 2100.8 s |
| 10 | MiniMax M3.1 Flash free | 136/157 (86.6%) | 1471.6 s |
| 10 | Union Alpha | 136/157 (86.6%) | 16540.5 s |
| 12 | Step 5 Preview | 133/157 (84.7%) | 1882.4 s |
Wall time is the runner clock, including whatever the provider spent in queue. I am not turning 1471.6 seconds against Union Alpha's 16540.5 seconds into a speed claim.
Same 136, different holes. Union Alpha's reasoning is 30/30 and its math is 24/30. This file's math is 23/30, its reasoning is 26/30, and its coding is 27/30 against Union Alpha's 26/30. Do not read 136 as one shape.
| Suite | M3.1 Flash free | Union Alpha | Step 5 Preview |
|---|---|---|---|
| coding | 27/30 | 26/30 | 17/30 |
| instruction | 27/30 | 28/30 | 26/30 |
| math | 23/30 | 24/30 | 26/30 |
| prose | 27/30 | 24/30 | 28/30 |
| reasoning | 26/30 | 30/30 | 29/30 |
| writing | 4/5 | 2/5 | 5/5 |
| tools | 2/2 | 2/2 | 2/2 |
openai/gpt-6-astra-pro:batch is 153/157 on https://openrouter.ai/api/beta/batches. That file is not on this slash list. Do not put 136 above it.
What I would not claim
I would not call this thinking off in the sense of zero reasoning tokens. 144 rows spent them. Twelve did not. One row has no token fields. effort=low is the analogue because none is rejected.
I would not send enable_thinking=false and call it the same arm. The short 2+2 lied. The identity probe and the bat-and-ball item did not.
I would not send both flags. That combination still thinks, and it changed a smoke answer.
I would not paste MiniMax's own benchmark table in here. I did not open a scored table on their docs page. The OpenRouter catalog description ends in an ellipsis. I did not finish that sentence. The model page we opened says open weights are planned. hugging_face_id on the models list is null. We did not load weights.
I would not treat image or video input as part of this score. Cold Iron here is text. The catalog modalities are text, image, and video in, text out.
I would not call the Morrow page this score. That run did not send an effort. Catalog default effort is max. Their usage recorded 12,578 reasoning tokens. This file is a different payload.
I would not rerun this at effort=max and then replace 136. If we do that later, it is a diagnostic, not the ranking arm.
I would not treat the free-request counter as the graded call count. /v1/key showed 58 used before this 157 and 214 used after. Dollar usage stayed 407.580328088. The 157 rows' cost fields sum to 0.
Reproducing this
Send this on every Cold Iron request for this slug. Do not add chat_template_kwargs.
{
  "reasoning": {"effort": "low"}
}
The public smf-bench runner on origin/main, commit 5d9ddf6, has no --thinking flag and no enable_thinking string. A clone of that commit will not send this payload. The local checkout has an exact-slug branch that pops chat_template_kwargs and sets reasoning.effort=low. That branch is not on the remote the reader will clone.
Scripts and the raw JSON are in the Nemo Knowledge Base.
Verification notes
Checked on 2026-10-19:
- Model id, canonical slug
minimax/minimax-m3.1-flash-20261019,created1792379569, context 1,000,000, price fields0and0,hugging_face_idnull, text-plus-image-plus-video in / text out,supported_parameters, and the reasoning block (mandatorytrue, effortsmax/xhigh/high/medium/low, defaultmax) came fromhttps://openrouter.ai/api/v1/modelson our key. Top-providermax_completion_tokenswas 524288. The catalog description in that response ends in an ellipsis. I did not extend it. - The "open weights are planned" sentence is from the OpenRouter model page we opened,
https://openrouter.ai/minimax/minimax-m3.1-flash:free. - MiniMax's own
thinking.typenote is fromhttps://platform.minimax.io/docs/api-reference/text-chat-openai. That page namesMiniMax-M3.1-Flash-Preview, not this OpenRouter slug. I did not finish theirreasoning_effortenum in the truncated extract, so I am not quoting an effort list from that page. - The score, category split, latency, token sums,
finish_reason,reasoning_tokens, per-row cost, and fail details came fromstage1_cal-minimax-m31-flash-free-or-strict-v01_20261019_122100.json.summary.totalis 157.summary.erroris 0.summary.passedis 136.summary.pass_rateis 86.6.wall_time_secondsis 1471.6. Internal timestamp is20261019_124532.thinkingisoff.reasoning_effortislow.serve_recipe_idisOpenRouter-cloud. - YAML caps:
v3.math.expert.08andv3.math.frontier.11aremax_tokens: 4096insuites/quality/tier0_deterministic/math.yaml.v3.reasoning.frontier.07ismax_tokens: 4096insuites/quality/tier0_deterministic/reasoning.yaml.writing_creativeismax_tokens: 512andwriting_formatismax_tokens: 128insuites/quality/writing/writing.yaml. - Suite size: the runner printed 157, and the strict files we opened count 30 math, 30 coding, 30 reasoning tier 0, 30 instruction, 30 prose, 5 writing, and 2 tool-calling.
- Neighbor scores and walls came from each model's newest zero-error thinking-off 157 on an endpoint containing
openrouter.ai/api/v1, recomputed after this file existed. 23 models. This id is rank 10. Union Alpha's file isstage1_cal-union-alpha-strict-v01_20260916_155705.json. Step 5's file isstage1_cal-step-5-preview-strict-v01_20261010_104152.json. Fable's file isstage1_cal-fable-51-or-strict-v01_20260902_184808.json. Astra Pro batch isstage1_cal-gpt6-astra-pro-batch-strict-v01_20260909_171401.jsononhttps://openrouter.ai/api/beta/batches, passed 153, and is not in the 23. git show origin/main:run_stage1.pyin the localsmf-benchcheckout had noenable_thinkingmatch and no--thinkingmatch. HEAD on that remote was5d9ddf6.- The Morrow post is a different artifact. It says it did not send
reasoningorreasoning.effort. I linked it. I did not import its token counts into this score.