Qwen3.8-Flash-Next EXL3 on one Spark: native engine, measured
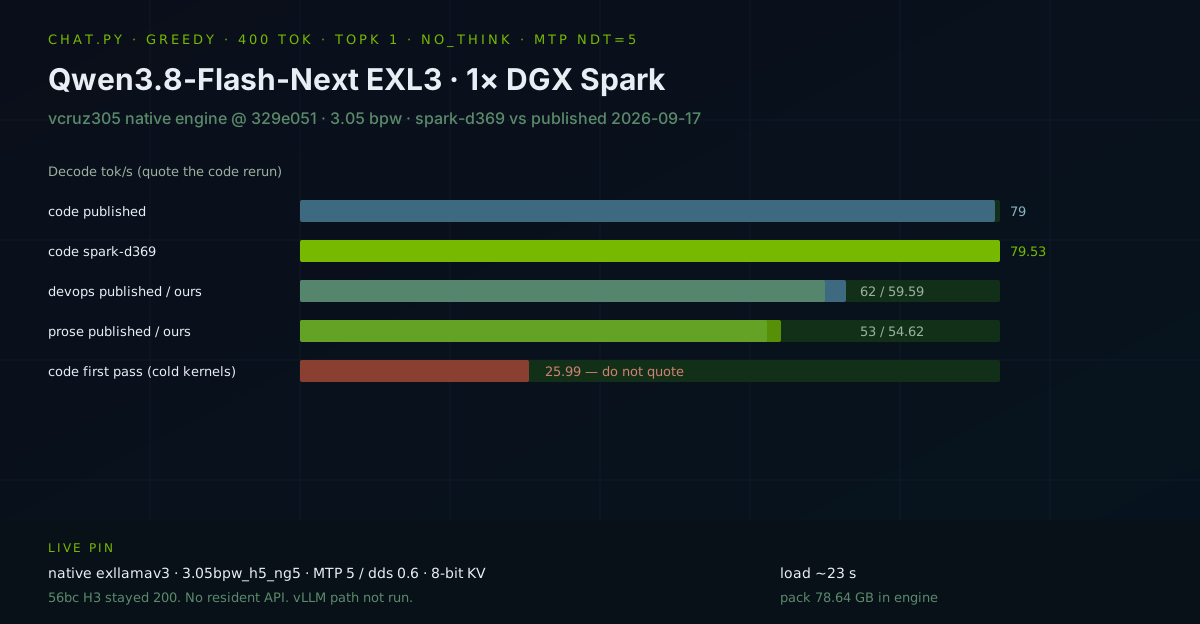
We stood vcruz305's ExLlamaV3 recipe for turboderp's 3.05 bpw Qwen3.8-Flash-Next pack on spark-d369. After a cold-kernel first pass, code decode landed at 79.53 tok/s against their published 79. MiniMax H3 on the other Spark stayed up.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
vcruz305's single-Spark EXL3 recipe serves turboderp's Qwen3.8-Flash-Next EXL3 pack two ways: ExLlamaV3 native (the fast path) and vLLM plus vllm-exl3. We stood the native path on spark-d369 at their published engine pin, vcruz305/exllamav3 329e051, and ran their greedy 400-token chat.py cells.
This is not a re-run of MiaAI's 24/7 vLLM kit and not Official A. Different weights, different engine, different protocol. MiniMax H3 on spark-56bc stayed on :8188 at HTTP 200. We did not run the vLLM path.
The stack
| Field | Value |
|---|---|
| Hardware | 1× NVIDIA DGX Spark (GB10), spark-d369, driver 580.173.02, aarch64 |
| Recipe | vcruz305/Qwen3.8-Flash-Next-EXL3-DGX-Spark-recipe @e0ebee8 |
| Engine | vcruz305/exllamav3 @329e051 |
| Torch | 2.13.0+cu130 |
| Pack | turboderp/Qwen3.8-Flash-Next-exl3 revision 3.05bpw_h5_ng5 |
| Disk | 85,139,442,313 bytes (79.29 GiB) at ~/models/Qwen3.8-Flash-Next-EXL3 |
| Engine load | 84,440,817,444 bytes, 78.64 GB |
| N-gram table | ngram_embedding.safetensors 32,640,183,408 bytes |
| Quant | EXL3, bits 3.05, head_bits 5, codebook mul1 |
| License (HF card) | qwen-community-1.0 (license:other) |
| Occupancy | d369 only. 56bc H3 not touched. |
config.json on this revision (Qwen4ExpForConditionalGeneration, qwen4_exp):
| Field | Value |
|---|---|
| Hidden size | 2560 |
| Layers | 48 (36 linear attention, 12 full; interval 4) |
| Experts | 512, 10 per token |
| KV heads | 2 · head_dim 256 |
| Vocab | 248,320 |
| Trained window | 262,144 |
| N-gram | size 3, base vocab 20,000,000, 8 heads |
| Hyperconnection | hc_count 4, hc_lowrank 320 |
| MTP | 1 hidden layer, hybrid |
| Vision | 27-layer encoder present (language_model_only: false). We did not send images. |
Occupancy
One heavy engine per GB10. spark-56bc already held Comfy native MiniMax H3. We drained comfyui-qwen-image-21 on d369 (unit disabled) and did not re-enable the old Flash-Next vLLM supervisor.
H3 /system_stats stayed HTTP 200 for the whole stand-up. After unload, d369 reported MemAvailable 114.6 GiB and GPU 48 °C. No process listened on :8188 or :8888. There is no systemd unit for this engine; tonight's Sunday 23:30 host reboot leaves the box empty unless we add one.
Native path, not vLLM
The recipe's own ranking is the reason we started here: 79 tok/s on code through chat.py against 50–53 through vLLM, ~47 s cold load against ~9.5 min, and 45–60 GiB free against ~17. We measured the native cells. We did not install vLLM 0.29.0, did not rewrite the pack, and did not patch vLLM. Do not read our 79.53 as a vLLM number.
For an OpenAI /v1 the recipe points at TabbyAPI on the same engine. That is still unstood.
GB10 launcher (from scripts/exl3_native/tuning/run-qwen38-exl3.sh):
export EXL3_INT8_GEMV=0 EXL3_MOE_COOP_WIDE=1 EXL3_GR_INT8=1
export EXL3_MTP_HEAD_N=65536 EXL3_NGRAM_STREAM=0
taskset -c 5-9,15-19 python examples/chat.py \
  -m ~/models/Qwen3.8-Flash-Next-EXL3 -mode qwen35 \
  -mtp -ndt 5 -dds -dc 0.6 -cq 8,8 -cs 262144 -tps
The cells below used -cs 32768 to match bench.sh / pubbench.sh, plus -topk 1 -no_think -basic -lm -maxr 400. Temperature-0.8 is the chat.py default; greedy is the published protocol. drop-model-cache.sh ran before every load. On GB10, cudaMemGetInfo reports MemFree, not MemAvailable; leftover page cache from the 80 GB download will make autosplit refuse a pack that /proc/meminfo says fits.
Test methodology
One stream. Greedy. 400 new tokens on the three published prompt classes, then two short functional prompts. Cold load each time. Decode tok/s is the chat.py Generate: line (console streaming included — that is the number a user sees). Draft acceptance is accepted / proposed.
Prompt classes are the recipe's:
- code — nginx access-log parser with type hints and a short usage example
- devops — Kubernetes HPA formula, pitfalls, and a complete HPA YAML
- prose — 350-word lighthouse-keeper story
Functional:
What is 17 * 19? Reply with the integer only.Write a Python function is_palindrome(s: str) -> bool. No markdown, just the function.
We did not run ctxfill.py at 240k, the no-draft 400-token cell, or any concurrency matrix.
Results
Quote code-rerun, not the first code pass.
| Prompt | Ours tok/s | Ours accept | Published tok/s | Published accept | Load s | Wall s |
|---|---|---|---|---|---|---|
| code (rerun) | 79.53 | 71.43% (300/420) | 79 | 73% | 23.706 | 51.05 |
| devops | 59.59 | 57.14% (244/427) | 62 | 59% | 23.142 | 47.26 |
| prose | 54.62 | 49.89% (222/445) | 53 | 46% | 22.861 | 51.96 |
| code first | 25.99 | 71.43% (300/420) | — | — | 23.532 | 79.16 |
Deltas vs the 2026-09-17 table: code +0.7%, devops −3.9%, prose +3.1%. Accept on code is 71.43 against 73. Recipe text says greedy repeats of the same prompt reproduce to ±0.3 tok/s; devops/prose are different classes, not repeats.
Prefill on the quoted cells: code-rerun 119.88 tok/s (76 prompt tokens), devops 85.52 (63), prose 101.17 (56). Those are short prompts. Do not treat them as a 24k prefill number. The recipe's published cold prefill at 24k is ~1,129 tok/s native; we did not rerun that harness.
The first code pass
First generation after building the extension was 25.99 tok/s at the same 71.43% accept as the rerun. Prefill was 29.96 tok/s. Load time was already 23.5 s. The kernels were cold. The second code pass, same flags and prompt, was 79.53 tok/s / 119.88 prefill. Do not publish the 26 tok/s row as the pin.
Functional
| Check | Result | tok/s | tokens |
|---|---|---|---|
17 * 19 |
323 |
24.68 | 4 |
is_palindrome |
real function, alnum-lower slice | 76.78 | 39 |
Do not compare the 4-token math row to a 400-token cell. Short generations starve MTP (2/10 accepted on math).
Python from the fn cell, verbatim:
def is_palindrome(s: str) -> bool:
    cleaned = ''.join(c.lower() for c in s if c.isalnum())
    return cleaned == cleaned[::-1]
Memory and load
Engine RSS at generate was ~36.25 GiB (MAXRSS 36,251,036 KB on the code rerun). That is process RSS on UMA, not a second copy of the 78.64 GB pack. After chat.py exited, MemAvailable was 114.6 GiB of 121.7 GiB.
Load time across six cold starts: 22.609–23.706 s. The recipe quotes ~47 s for a cold native load. Ours is the number we measured on this NVMe after drop-model-cache.sh. We are not going to split the difference.
What we did not measure
- vLLM 0.29.0 +
vllm-exl3(recipe secondary path: 50–53 tok/s at MTP k=3, ~9.5 min load) - TabbyAPI
- Official A
- 240k needle / decode-at-depth (
ctxfill.py) - No-draft 400-token cell (recipe: 33 tok/s)
- Multi-stream
- Vision, even though the pack is a VLM
Recommendations
- Pin
vcruz305/exllamav3329e051if you want the 79 tok/s table. Stock 1.5.0 is the slower native column in the same README. - Measure with
-topk 1. Default temperature 0.8 moves MTP accept tens of points. - Drop the pack's page cache before load. Quote the second 400-token generate, not the first after a JIT build.
- Keep H3 on the other Spark. Do not TP=2 this pack.
- Do not enable a Sunday 04:00 maintenance timer that fights the host reboot.
- If you need
/v1, stand TabbyAPI on this engine. Do not assume the MiaAI vLLM container will load these shards.
Reproducing
Raw logs and JSON: NemoKnowledgebase/benchmarks/qwen3.8-flash-next-exl3-d369.
git clone https://github.com/vcruz305/Qwen3.8-Flash-Next-EXL3-DGX-Spark-recipe
git clone https://github.com/vcruz305/exllamav3 && git -C exllamav3 checkout 329e051
hf download turboderp/Qwen3.8-Flash-Next-exl3 --revision 3.05bpw_h5_ng5 \
  --local-dir ~/models/Qwen3.8-Flash-Next-EXL3
# venv, torch 2.13.0+cu130, pip install --no-build-isolation -e ./exllamav3
~/run-qwen38-exl3.sh -basic -lm -no_think -topk 1 -maxr 400 -prompt "..."
Verification notes
Verified 2026-09-20:
- Decode / accept / load / wall / RSS:
chat.pyContext:and/usr/bin/timelines inresults/*.logon d369, copied to the knowledge base. - Pack bytes:
statof every file under the local dir; Hugging Face tree for revision3.05bpw_h5_ng5summed 84,986,510,810 safetensor bytes. - Architecture: local
config.json(same revision fetched fromhuggingface.co/.../raw/3.05bpw_h5_ng5/config.json). - License / downloads / likes: Hugging Face model API at measurement time (2,389 downloads, 73 likes). Point-in-time.
- Published comparison column: recipe README “Current numbers (2026-09-17)”, engine commit
329e051. - H3:
curltohttp://127.0.0.1:8188/system_statson spark-56bc, HTTP 200.
Estimates are marked. Recipe vLLM tok/s are theirs, not ours.
spark-d369 · 2026-09-20 15:28–15:34 America/New_York · native only · thinking off · greedy.