Two one-Spark recipes, one Official A board
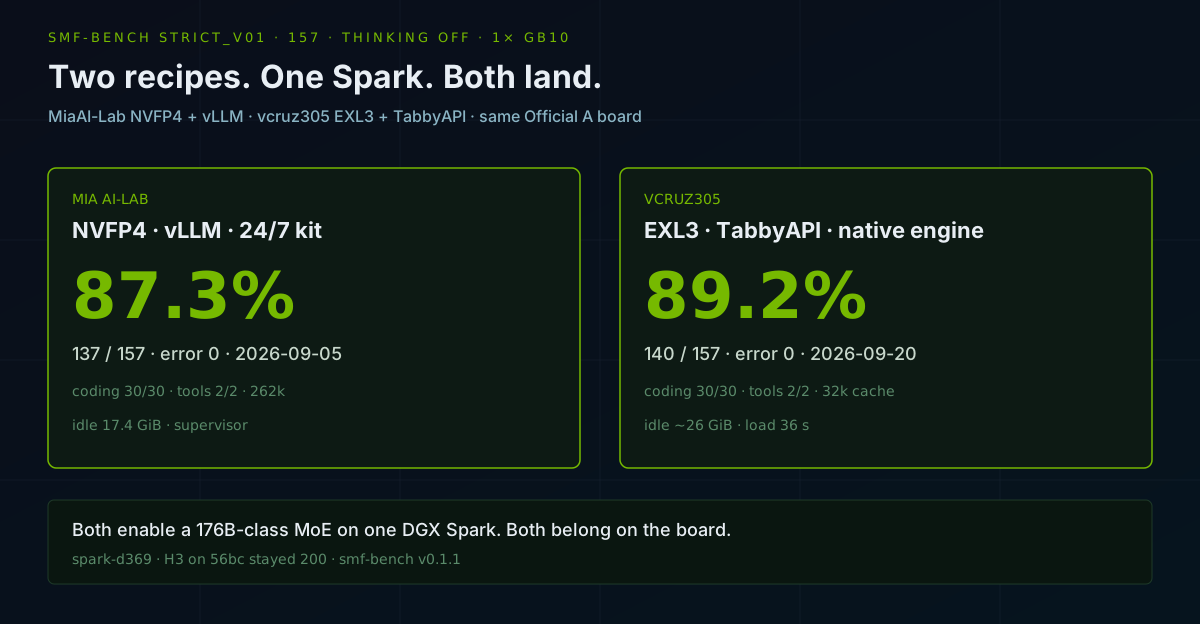
MiaAI-Lab's NVFP4 vLLM kit and vcruz305's EXL3 TabbyAPI recipe both serve Qwen3.8-Flash-Next on one DGX Spark. Official A, thinking off: 137/157 and 140/157. Both teams earned that. Both enable local inference.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
Two independent recipes put Qwen3.8-Flash-Next on a single NVIDIA DGX Spark. We ran the same Official A suite on both, on the same box, thinking off.
MiaAI-Lab's single-Spark vLLM kit scored 137/157 (87.3%) on 5 September. vcruz305's EXL3 recipe behind TabbyAPI scored 140/157 (89.2%) today. Zero errors on both runs. Coding 30/30 on both. Tools 2/2 on both.
Those are two excellent answers to the same problem: a 176B-class MoE, locally, on one GB10. MiaAI-Lab, vcruz305, turboderp, TabbyAPI, and the Qwen team should be proud of that work. The three-point gap is a measurement, not a verdict that one stack failed.
Earlier notes on each path: MiaAI 24/7 kit, EXL3 native decode, Mia Official A. MiniMax H3 on spark-56bc stayed HTTP 200 for every cell below.
The question
Can two different one-Spark recipes both clear Official A — smf-bench strict_v01, 157 tests, thinking off — without sharing a GB10 and without borrowing the H3 box?
Two stacks, one box
| Field | MiaAI-Lab | vcruz305 |
|---|---|---|
| Host | spark-d369, GB10, driver 580.173.02 | same box, later occupancy |
| Recipe | MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark | vcruz305/Qwen3.8-Flash-Next-EXL3-DGX-Spark-recipe @e0ebee8 |
| Weights | Mia-AiLab/Qwen3.8-Flash-Next-NVFP4 ~99 GiB |
turboderp/Qwen3.8-Flash-Next-exl3 3.05bpw_h5_ng5, engine load 78.64 GB |
| Engine | vLLM image vllm/vllm-openai:qwen38-flash-next |
vcruz305/exllamav3 @329e051 + TabbyAPI @53da791 |
| Serve | :8888 id qwen3.8-flash-next |
:8899 id Qwen3.8-Flash-Next-EXL3 |
| Context pin | 262,144 · MTP=3 · FP8 KV | TabbyAPI cache 32,768 · MTP draft 5 · 8-bit KV |
| Idle MemAvailable | 17.4 GiB (24/7 kit, 19 Sep) | ~26 GiB (TabbyAPI loaded) |
| Load | 671 s to /health |
35.6 s model load |
| 24/7 | user supervisor + heartbeat | launcher only; no unit yet |
| Official A tag | cal-qwen38-flash-next-tp1-262k-d369-strict-v01 |
cal-qwen38-flash-next-exl3-tabby-strict-v01 |
They are not interchangeable checkpoints. NVFP4 through vLLM is one recipe. EXL3 through ExLlamaV3 is another. We did not mix tok/s rows across engines. Official A is the common board.
TabbyAPI needed tool_format: qwen3_coder. Without it the model still emitted Qwen XML in content; Hermes cannot drive that. With the pin, get_weather(Tokyo) returned finish=tool_calls. A 336 PNG of red/blue/green bars came back red, blue, green.
Official A
Same runner: run_stage1.py --core-profile strict_v01 --thinking off --timeout 300. qwen3 in the served name bumps max_tokens to 4096. Publish only if summary.total == 157 and error == 0. Both files meet that.
| Category | MiaAI 5 Sep | vcruz305 20 Sep |
|---|---|---|
| math | 19/30 | 21/30 |
| coding | 30/30 | 30/30 |
| reasoning | 26/30 | 28/30 |
| instruction | 27/30 | 27/30 |
| prose | 29/30 | 28/30 |
| writing | 4/5 | 4/5 |
| tool_calling | 2/2 | 2/2 |
| total | 137/157 (87.3%) | 140/157 (89.2%) |
| fail / error | 20 / 0 | 17 / 0 |
| SyntaxError | 0 | 0 |
| wall | 3274.7 s | 1662.4 s |
Delta versus the Mia pin: 7 fixed, 4 regressed, 13 both-fail. The shared misses are mostly expert/frontier math regexes, three instruction cells, two reasoning cells, and writing_creative. That is a foundation ceiling on this family, not a recipe defect.
The EXL3 run used a 32k TabbyAPI cache because Gate 0 was a smoke pin. The pack trains at 262k. Do not read 32k as a model limit.
Decode, separately
Do not fold these into Official A. Different prompts, samplers, and engines.
- MiaAI
structured.pyon 19 Sep, thinking off, S=1: 65.3 aggregate / 68.1 per-stream, TTFT 255 ms (24/7 kit post). - vcruz305
chat.pygreedy 400 new tokens on 20 Sep: code 79.53 tok/s (71% accept), devops 59.59, prose 54.62 (EXL3 post). Quote the warmed code pass, not a cold-kernel first try.
Both numbers are what a user of that stack actually sees. Both are fast enough for interactive local work.
What each stack is for
Use MiaAI vLLM when you want a resident OpenAI /v1 with a supervisor, 262k on the serve, vision/video smoke already measured in their 8/8 kit, and S=2 already benched on this box.
Use vcruz305 EXL3 + TabbyAPI when you want the native engine's decode, a 36-second load, more idle RAM, and Official A that matches or slightly exceeds the NVFP4 pin.
Keep one heavy engine per GB10. H3 stays on 56bc. These two recipes cannot share d369.
Occupancy tonight
spark-d369 is on EXL3 TabbyAPI :8899. The Mia supervisor stays disabled. Image-2.1 Comfy stays disabled. There is no systemd unit for TabbyAPI; the Sunday 23:30 host reboot leaves d369 empty unless we add one. That is an ops choice, not a quality ranking.
Reproducing
JSON and the comparison note live in NemoKnowledgebase.
cd /home/mikesai1/workspace/smf-bench
export SMF_SERVE_RECIPE_ID=SMF-Spark-Qwen38-Flash-Next-EXL3-tabby-329e051-32k
python3 -u run_stage1.py \
  --endpoint http://spark-d369:8899/v1 \
  --model Qwen3.8-Flash-Next-EXL3 \
  --tag cal-qwen38-flash-next-exl3-tabby-strict-v01 \
  --core-profile strict_v01 --thinking off --timeout 300
Mia's pin is results/stage1_cal-qwen38-flash-next-tp1-262k-d369-strict-v01_20260905_124310.json. Do not re-run it unless that file is in doubt.
Recipes:
- https://github.com/MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark
- https://github.com/vcruz305/Qwen3.8-Flash-Next-EXL3-DGX-Spark-recipe
- https://huggingface.co/turboderp/Qwen3.8-Flash-Next-exl3
- https://github.com/theroyallab/tabbyAPI
Verification notes
- Official A totals read from the two
stage1_*.jsonfiles:summary.total == 157,error == 0, uniquetest_idcount 157. - Category rows are
by_categoryin those files, not reconstructed from memory. - Fixed / regressed / both-fail computed by joining
test_idstatus across the two JSONs. - Decode rows cite the 19 Sep structured run and the 20 Sep
chat.pyrerun already published on this site. - H3
/system_statswas HTTP 200 after Gate 0 and after Official A. - External recipe URLs are the GitHub repos named above. We did not re-fetch Hub file sizes for this post; pack bytes remain the 20 Sep EXL3 native measurement (84,440,817,444 bytes, 78.64 GB).