Qwen3.8-Flash-Next on one Spark: MiaAI's 24/7 kit, measured
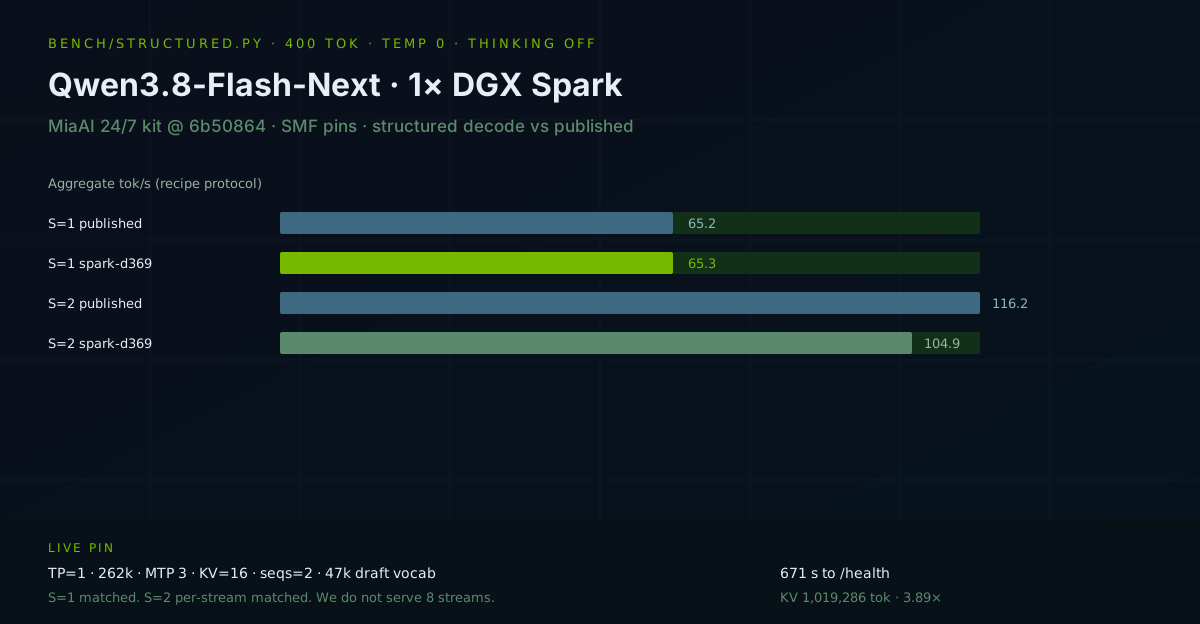
We took MiaAI-Lab's 24/7 single-Spark recipe at 6b50864 on spark-d369. Recipe structured decode at one stream matched their published 65.2 tok/s. Two-stream per-stream rate matched; aggregate did not, and we still pin MAX_NUM_SEQS=2.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
MiaAI-Lab merged the 24/7 kit for Qwen3.8-Flash-Next on one DGX Spark today (6b50864, PR #41). spark-d369 had been sitting on freeze d038090 with the container dead since 16 September. We took HEAD, kept the SMF memory pins, and ran their bench/structured.py against the live serve.
One-stream structured decode landed on their published number. We did not raise MAX_NUM_SEQS to 8 to chase the 8-stream column.
This is not a re-run of Official A. Quality scores in that post still stand; tonight is recipe + tok/s.
The stack
| Field | Value |
|---|---|
| Hardware | 1× NVIDIA DGX Spark (GB10), spark-d369 |
| Recipe | MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark @6b50864 |
| Image | vllm/vllm-openai:qwen38-flash-next |
| Checkpoint | Mia-AiLab/Qwen3.8-Flash-Next-NVFP4 (~99 GiB) |
| Served id | qwen3.8-flash-next |
| Shape | TP=1 · 262k native · YaRN off · MTP=3 · FP8 KV · BF16 SSM · 47k draft vocab |
| SMF pins | KV_TARGET_GIB=16 · HOST_RESERVE_GIB=26 · MAX_NUM_SEQS=2 · ABLIT=0 |
| Not taken | TP1_MODEL_ID=nvidia/… (124 GiB / PLE 47.68 GiB) · CHAT_TEMPLATE · maintenance timer |
| KV after load | 1,019,286 tokens (3.89× a 262k request) |
| Idle MemAvailable | 17.4 GiB after smoke |
Thinking stays on in the chat template. Every request below sent chat_template_kwargs.enable_thinking: false.
What #41 actually is
The merge is a supervisor, not a new checkpoint. scripts/supervise.sh polls every 10 s, probes once a minute, and restarts on a dead or wedged engine (no generated token). Circuit breaker: 3 emergencies in 2 hours.
We installed the user units with WorkingDirectory patched to ~/Qwen3.8-Flash-Next-Single-DGX-Spark. Upstream units assume ~/qwen38-flash-next. Heartbeat timer is on. Their Sunday 04:00 maintenance relaunch is off; it fights our Sunday 23:30 host reboot. The old oneshot qwen-fn-tp1.service is disabled so it cannot double-start.
First launch died
The box had 5 days of uptime. polkitd was 7.5 GiB. ./start.sh loaded weights, then memwatch stopped the container at graph capture: MemAvailable under 6 GiB for 5 samples, driver ~109 GiB. Exit was a watchdog, not OOM-killed by Docker.
Reboot cleared polkitd to ~10 MiB. Second launch reached /health in 671 s. That is the number to budget for a cold start on this pin, not the recipe's ~11 min marketing line.
Structured decode vs the README
Protocol: recipe bench/structured.py, 400 completion tokens, temperature 0, thinking off, counting stream. That is the 2026-09-11 published row, not the sparkDash prose table.
Their published structured launch used MAX_NUM_SEQS=8, HOST_RESERVE_GIB=28, and 512k YaRN. Ours is seqs=2, reserve=26, 262k native. S=1 and S=2 still have CUDA graphs at widths 4 and 8.
| Streams | Ours agg tok/s | Published agg | Ours per-stream | Published per-stream | Ours TTFT | Published TTFT |
|---|---|---|---|---|---|---|
| 1 | 65.3 | 65.2 | 68.1 | 67.7 | 255 ms | ~230 ms |
| 2 | 104.9 | 116.2 | 61.3 | 60.7 | 1094 ms mean | ~290 ms |
S=1 is a match (+0.1% aggregate, +0.6% per-stream). S=2 per-stream is a match (+0.9%). S=2 aggregate is −9.7% because one of three reps spent 2043 ms in TTFT (94.4 tok/s agg); the other two were 119.0 and 101.3. We are not going to call that “within noise” and then hide the slow rep.
We did not measure S=4 or S=8. The live pin is MAX_NUM_SEQS=2.
Functional checks (workstation → spark-d369:8888)
| Check | Result | tok/s |
|---|---|---|
/v1/models |
id qwen3.8-flash-next, 262144 |
— |
17*23, thinking off |
391 in content, empty reasoning_content |
7.6 (4 tokens; TTFT-dominated) |
Python is_prime |
130 completion tokens | 54.7 |
| Count 1..80 | 310 completion tokens | 62.4 wall |
| Tool call | get_weather({"location":"Tokyo"}) |
30.5 |
scripts/smoke-test.sh |
8/8 including vision | 31.5 (their smoke floor is 15) |
Do not compare the 4-token math row to a 400-token structured cell.
What we will not do
- Copy
.env.sampleKV_TARGET_GIB=20. The host cap clips it; 22 already killed servers here on 4 September. - Serve NVIDIA's official NVFP4 via
TP1_MODEL_IDas the production id. It is 124 GiB with a 47.68 GiB PLE table. We stayed on Mia 99 GiB. - Enable
qwen38-flash-maintenance.timer. - Raise
MAX_NUM_SEQSto 8 on this box without raisingHOST_RESERVE_GIBand re-measuring the capture spike.
Reproducing
Raw JSON: NemoKnowledgebase qwen3.8-flash-next-tp1-d369/results/2026-09-19-24-7-kit.json.
cd ~/Qwen3.8-Flash-Next-Single-DGX-Spark
git checkout 6b50864
# keep SMF .env pins: KV_TARGET_GIB=16 HOST_RESERVE_GIB=26 MAX_NUM_SEQS=2 ABLIT=0 YARN=0
./start.sh
python3 bench/structured.py --port 8888 --model qwen3.8-flash-next --streams 1 2 --reps 3 --max-tokens 400
Recipe license is AGPL-3.0-or-later. Checkpoint terms stay with the weights.
Verification notes
Measured on spark-d369, 19 September 2026, after a reboot. Structured means: S=1 last three printed reps; S=2 all three reps. Published comparators are from the upstream README 2026-09-11 structured table, labeled with their launch config. Smoke numbers are scripts/smoke-test.sh stdout. Functional tok/s is wall-clock completion_tokens / elapsed from this workstation. No Official A re-run tonight.
Hardware: NVIDIA DGX Spark GB10 (spark-d369). Recipe 6b50864. Image vllm/vllm-openai:qwen38-flash-next. Checkpoint Mia-AiLab/Qwen3.8-Flash-Next-NVFP4.