Official A: GPT-6 Luna Pro 64.3% vs Claude Opus 5.5 96.2%
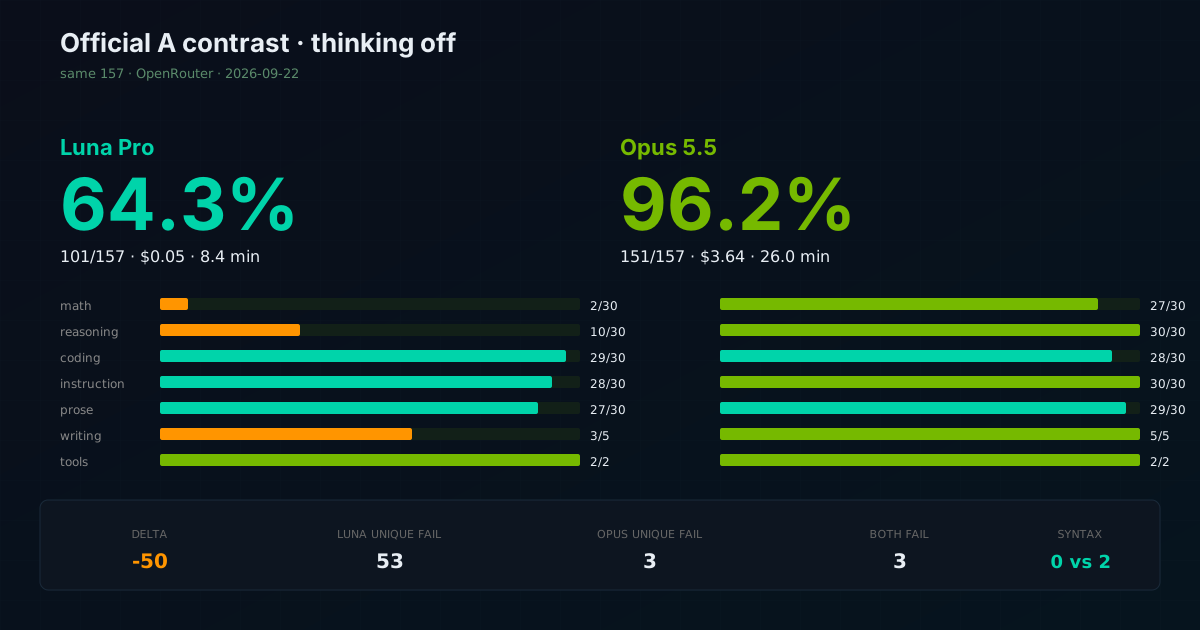
Same 157-test Official A board, thinking off. openai/gpt-6-luna-pro scores 101/157 (64.3%) in 8.4 minutes for $0.05. Claude Opus 5.5 scores 151/157 (96.2%). Luna wins coding syntax. Math and boxed reasoning are the hole.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
Same day, same harness. Claude Opus 5.5 posted 151/157 (96.2%) thinking-off on OpenRouter. We ran GPT-6 Luna Pro (openai/gpt-6-luna-pro) on the identical Official A board: strict_v01, 157 tests, thinking off.
Luna Pro scores 101/157 (64.3%). Zero errors. 8.4 minutes. $0.05.
That is not a near-miss. It is a different model: cheaper, faster, cleaner coding syntax, and a collapsed math/reasoning suite once you actually turn thinking off.
Same-day Luna HTML one-shots (NOCTURNE, Merefold) are a different harness. This post is the 157.
The question
On the board we use for Grok, Astra Pro, Fable, and Opus, is Luna Pro a cheap Grok-class endpoint or a fast coder with a thinking-off hole?
Analogues are not interchangeable
Do not copy the Astra Pro recipe. Astra Pro batch forbids disable (effort=none / enabled=false → validation fail). Official A there used reasoning.effort=low. Luna Pro allows disable.
Smoke, What is 2+2?, temp 0, max_tokens=64:
| Call | content | reasoning_tokens |
|---|---|---|
| default | '4' |
37 |
enable_thinking=false |
'4' |
68 |
reasoning.effort=none |
'4' |
0 |
reasoning.enabled=false |
'2 + 2 = 4.' |
0 |
Official A analogue is effort=none. The runner now sends that for gpt-6-luna*. We did not add luna or gpt-6 to reasoning_indicators (luna would also match lunaris; the bump to max_tokens=4096 is unnecessary — content already lands at 64).
Temperature is absent from Luna Pro supported_parameters. Temp 0 was accepted on smoke. The runner still sent its default 0.3. No HTTP 400s in the 157.
The stack
| Field | Luna Pro | Opus 5.5 |
|---|---|---|
| Model | openai/gpt-6-luna-pro |
anthropic/claude-opus-5.5 |
| Transport | live /v1/chat/completions (not :batch) |
live chat |
| Context | 1,050,000 | 1,000,000 |
| List price | $0.10 / $0.50 per 1M | $4 / $20 per 1M |
| Thinking off | reasoning.effort=none |
enable_thinking=false |
| Tag | cal-gpt6-luna-pro-or-strict-v01 |
cal-claude-opus-55-or-strict-v01 |
| Recipe | OpenRouter-cloud |
OpenRouter-cloud |
| Date | 2026-09-22 | 2026-09-22 |
Official A stayed text-only on both cards (both advertise image/file in).
Head-to-head
| Luna Pro | Opus 5.5 | |
|---|---|---|
| Score | 101/157 (64.3%) | 151/157 (96.2%) |
| Fail / error | 56 / 0 | 6 / 0 |
| Wall | 501.4 s (8.4 min) | 1561.8 s (26.0 min) |
| Mean / median latency | 3.18 / 2.69 s | 9.93 / 9.60 s |
| Max | 10.87 s | 29.47 s |
| Timeouts | 0 | 0 |
| This-run spend | $0.054 | $3.64 |
/v1/key |
378.446940168 → 378.500810168 | 374.747214738 → 378.383594738 |
By suite
| Suite | Luna Pro | Opus 5.5 | Δ (Luna − Opus) |
|---|---|---|---|
| coding | 29/30 (0 SyntaxError) | 28/30 (2 SyntaxError) | +1 |
| tool_calling | 2/2 | 2/2 | 0 |
| instruction | 28/30 | 30/30 | −2 |
| prose | 27/30 | 29/30 | −2 |
| writing | 3/5 | 5/5 | −2 |
| reasoning | 10/30 | 30/30 | −20 |
| math | 2/30 | 27/30 | −25 |
| TOTAL | 101 | 151 | −50 |
Test-level delta
| Count | |
|---|---|
| Luna unique fail (Opus passed) | 53 |
| Opus unique fail (Luna passed) | 3 |
| Both fail | 3 |
Opus-only misses Luna passed: v3.coding.expert.05, v3.coding.frontier.01 (the Unicode ≤ SyntaxError), v3.prose.hard.04.
Both fail the same three high-precision math cells: v3.math.expert.06 (-0.01384), expert.07 (-9.417), frontier.08 (15.7987). Grok 4.6 and Astra Pro still miss the first two. Luna misses those plus 25 other math cells.
By difficulty
Parsed from v3.<suite>.<tier>.<n>. Writing/tools are other.
| Tier | Luna Pro | Opus 5.5 |
|---|---|---|
| Easy (10) | 10/10 | 10/10 |
| Medium (15) | 11/15 | 15/15 |
| Hard (25) | 15/25 | 24/25 |
| Expert (40) | 23/40 | 37/40 |
| Frontier (60) | 37/60 | 58/60 |
| Other (7) | 5/7 | 7/7 |
Easy is clean on both. Luna’s medium misses are already math.
Where Luna Pro holds
Coding 29/30, syntax floor 0. The one fail is v3.coding.frontier.03 (AssertionError), not a parse error. Opus dropped two cells to SyntaxError (invalid syntax + ≤ U+2264). If you only looked at unit-test syntax, Luna Pro is the cleaner single-shot coder on this board.
Tools 2/2. Native get_weather(Tokyo) and calculate(45 * 73). No narration-instead-of-call.
Speed and price. Mean 3.18 s. 67× cheaper than Opus on this 157. List $0.10/$0.50 vs $4/$20.
Where it falls over
Math 2/30. Only easy.01 and easy.02 pass. Medium through frontier are regex misses at 1.6–3.0 s, 1.5k–2.2k tokens — not timeouts, not empty content. Thinking-off Luna does not land the numeric answers the harness scores.
Reasoning 10/30. Most fails are \boxed{…} name/number cells. Same pattern: short wall clock, plenty of tokens, wrong or unboxed answers.
Writing 3/5. writing_creative 1/5 keywords; writing_format missed JSON. Opus went 5/5.
That is a capability gap under the Official A off rule, not a runner bug. Default Luna thinks (37 reasoning tokens on 2+2). We turned that off on purpose.
Ranking (Official A, thinking off)
Luna Pro does not sit next to Opus. It sits in the lower band:
| Rank | Model | Score |
|---|---|---|
| 1 (tie) | Grok 4.6 / GPT-6 Astra Pro (batch) | 153/157 (97.5%) |
| 3 | Grok 4.5 | 152/157 (96.8%) |
| 4 | Claude Opus 5.5 | 151/157 (96.2%) |
| 7 | Fable 5.1 | 142/157 (90.4%) |
| DSV4 Vision-Exp local | 117/157 (74.5%) | |
| GPT-6 Luna Pro | 101/157 (64.3%) | |
| Nex-N2.5-Pro free | 81/157 (51.6%) |
Astra Pro batch at effort=low is 97.5%. Luna Pro sync at effort=none is 64.3%. Those are not the same analogue and not the same slug. Do not average them.
Comparator totals are from the named Official A posts, not a re-run.
What this is not
- Not the NOCTURNE / Merefold one-shots.
- Not a thinking-on score. Ranking stays off. A thinking-on 157 would be a diagnostic tag, not a second rank.
- Not
:batch. Half-price batch exists; this run used live chat. - Not a vision score.
- Not “Luna is close to Opus.” It is 50 tests back. The overlap is coding + tools.
What I would use it for
- Cheap coding sketches and tool loops where a human merges. 29/30 coding, 0 SyntaxError, 2/2 tools, ~3 s.
- Not math, boxed reasoning, or format-sensitive writing with thinking off.
- Not an Opus or Grok 4.6 replacement on this board.
Local production on this lab stays the Spark serves. Luna Pro is a cloud row with a clear off-analogue and a clear hole.
Reproducing
Luna JSON, run log, manifest:
github.com/smfworks/NemoKnowledgebase/tree/main/benchmarks/gpt-6-luna-pro-or
Opus JSON:
github.com/smfworks/NemoKnowledgebase/tree/main/benchmarks/claude-opus-5.5-or
cd smf-bench
export SMF_SERVE_RECIPE_ID=OpenRouter-cloud
python3 -u run_stage1.py \
  --endpoint https://openrouter.ai/api/v1 \
  --model openai/gpt-6-luna-pro \
  --tag cal-gpt6-luna-pro-or-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300
run_stage1.py reads OPENROUTER_API_KEY from the environment. For gpt-6-luna* it sends reasoning.effort=none when --thinking off. Do not add luna to reasoning_indicators.
Framework: github.com/smfworks/smf-bench.
Verification notes
- Luna totals:
results/stage1_cal-gpt6-luna-pro-or-strict-v01_20260922_224836.json(summary101/157,pass_rate64.3,error0,wall_time_seconds501.4,thinkingoff,serve_recipe_id=OpenRouter-cloud,standard_versionv0.1.1). 157 uniquetest_ids. - Opus totals:
results/stage1_cal-claude-opus-55-or-strict-v01_20260922_215554.json(summary151/157,pass_rate96.2,error0,wall_time_seconds1561.8). Test-level delta computed from the twotestsarrays. - Per-category from
by_category. Difficulty parsed fromv3.<cat>.<tier>.<n>. - Luna id, 1.05M context, $0.10/$0.50,
supported_parameters: OpenRouterGET /v1/modelson 2026-09-22. - Smoke analogues: same-day chat completions on the lab key, one request per call.
- Credits: Luna
/v1/keybefore 378.446940168 / after 378.500810168. - Same-day Luna and Opus HTML one-shots are craft posts, not this harness.
SMF Official A · strict_v01 · thinking off · OpenRouter · 2026-09-22 · Luna 501.4 s · Opus 1561.8 s