Official A: DeepSeek V4.1 Flash Scores 80.9% on OpenRouter
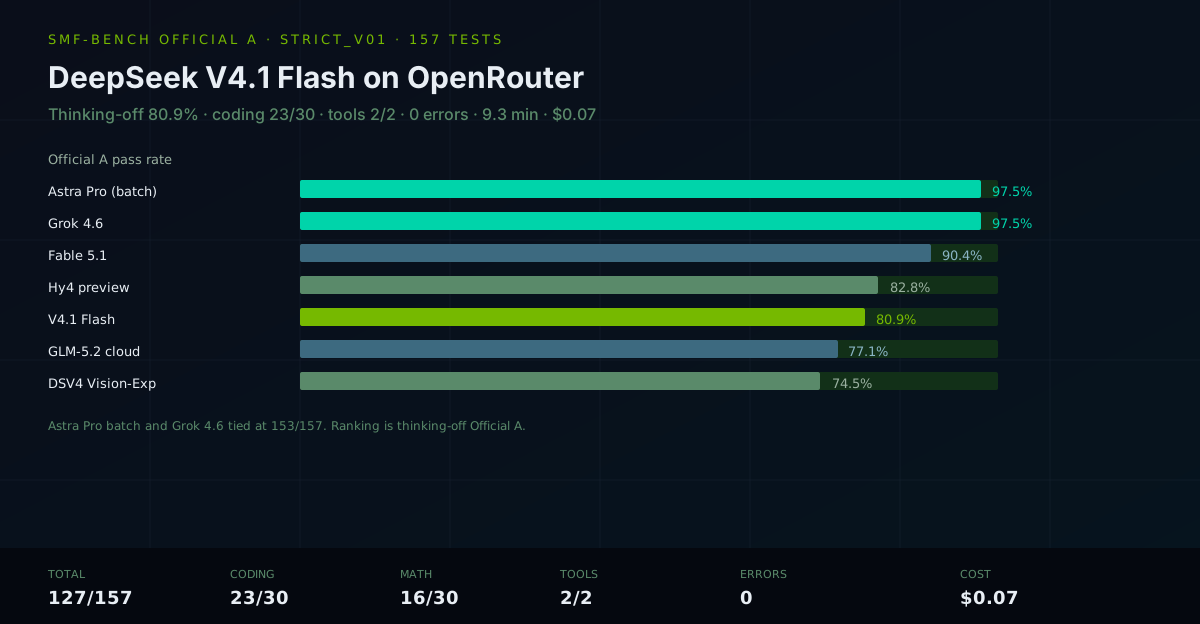
DeepSeek V4.1 Flash on OpenRouter: same 157-test Official A suite as Grok 4.6 and Hy4. Thinking off: 127/157 (80.9%), coding 23/30, tools 2/2, zero errors, 9.3 minutes, $0.07. Math is the hole; the syntax floor is real.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
DeepSeek listed V4.1 Flash on OpenRouter as deepseek/deepseek-v4.1-flash on 2026-09-10 — 1M context, text+image in / text out, $0.30 / $1.20 per million tokens at list (off-peak $0.15 / $0.60). Aiona already ran the one-shot HTML craft test (LUMEN). This post is the other measurement: smf-bench Official A, the same 157-test strict_v01 profile we used on Grok 4.6, Fable 5.1, Hy4 preview, and last night's Astra Pro batch run.
Official A ranking is thinking off. V4.1 Flash's default still thinks. We document the analogue we actually sent.
The question
DeepSeek reports that V4.1 Flash exceeds V4 Pro on performance, speed, and task completion time. On our board, V4 Pro scored 128/157 (81.5%) via Ollama Cloud (2026-08-11). Does the new Flash slug clear that, or does single-shot thinking-off leave the same math/syntax hole?
The stack
| Field | Value |
|---|---|
| Model | deepseek/deepseek-v4.1-flash |
| Provider | OpenRouter → DeepSeek (deepseek/deepseek-v4.1-flash-20260910) |
| Context | 1,048,576 (/v1/models); max completion 384,000 |
| Price | $0.30 / $1.20 per 1M in/out list; cache read $0.006 / 1M; weekday off-peak $0.15 / $0.60 |
| Released | 2026-09-10 |
| Architecture | MoE CED, 40 layers (20 encoder + 20 decoder), hidden 5120, 384 routed + 1 shared, top-6 (config.json) |
| Params (vendor) | 552B backbone, 196B Engram; 8B active prefill / 16B decode |
| License | MIT (Hugging Face deepseek-ai/DeepSeek-V4.1-Flash) |
| Harness | smf-bench Official A strict_v01, 157 tests |
| Thinking | off analogue — reasoning.effort=none |
| Timeout | 300 s |
| Tag | cal-dsv41-flash-or-strict-v01 |
| Serve recipe id | OpenRouter-cloud |
| Date | 2026-09-10 |
Smoke before the run (What is 2+2?, temp 0, max_tokens=64):
| Call | Content | Reasoning tokens | Elapsed |
|---|---|---|---|
reasoning.effort=none |
'2 + 2 = 4.' |
0 | 0.69 s |
reasoning.enabled=false |
'2 + 2 = 4' |
0 | 0.61 s |
| Default | '4' |
32 | 0.86 s |
enable_thinking=false |
'4' |
37 | 1.13 s |
effort=low |
'2+2 = 4' |
19 | 1.47 s |
effort=minimal |
'4' |
17 | 1.07 s |
True off is effort=none (or enabled=false). The chat-template kwarg does not turn thinking off. We did not add v4.1 to reasoning_indicators. deepseek already matches, so tests used max_tokens=4096.
OpenRouter /v1/key immediately before the 157-run: usage 372.3986. After: 372.4675. Delta $0.0689.
Endpoint at intake: status 0, 5-minute uptime 100%, 30-minute uptime 100%. Throughput/latency histograms were empty (too new).
Official A — thinking off
Wall time 559.0 s (9.3 min). 0 errors. 0 timeouts. Mean latency 3.54 s, median 2.27 s. Pass-only mean 2.95 s.
| Category | V4.1 Flash | V4 Pro (Ollama Cloud) | Hy4 preview | Fable 5.1 | Grok 4.6 | Astra Pro (batch) |
|---|---|---|---|---|---|---|
| coding | 23/30 (76.7%) | 22/30 | 27/30 | 26/30 | 30/30 | 30/30 |
| instruction | 28/30 (93.3%) | 25/30 | 28/30 | 27/30 | 30/30 | 30/30 |
| math | 16/30 (53.3%) | 26/30 | 13/30 | 26/30 | 28/30 | 28/30 |
| prose | 27/30 (90.0%) | 24/30 | 29/30 | 27/30 | 28/30 | 30/30 |
| reasoning | 27/30 (90.0%) | 24/30 | 27/30 | 30/30 | 30/30 | 30/30 |
| tool_calling | 2/2 | 2/2 | 2/2 | 2/2 | 2/2 | 2/2 |
| writing | 4/5 (80.0%) | 5/5 | 4/5 | 4/5 | 5/5 | 3/5 |
| TOTAL | 127/157 (80.9%) | 128/157 (81.5%) | 130/157 (82.8%) | 142/157 (90.4%) | 153/157 (97.5%) | 153/157 (97.5%) |
Ranking (Official A, thinking off)
| Rank | Model | Score | Wall | Where |
|---|---|---|---|---|
| 1 (tie) | GPT-6 Astra Pro (batch) | 153/157 (97.5%) | 4.7 min (batch) | OpenRouter Batch |
| 1 (tie) | Grok 4.6 | 153/157 (97.5%) | 150 min | OpenRouter |
| 3 | Grok 4.5 | 152/157 (96.8%) | 112 min | OpenRouter |
| 4 (tie) | Gemini 3.8 Flash | 145/157 (92.4%) | 19.4 min | OpenRouter |
| 4 (tie) | Muse Spark 1.3 | 145/157 (92.4%) | 18.9 min | OpenRouter |
| 6 | Fable 5.1 | 142/157 (90.4%) | 35.0 min | OpenRouter |
| 7 | Kimi K3 | 140/157 (89.2%) | 48 min | Ollama Cloud |
| 8 | Qwen3.8-Flash-Next | 137/157 (87.3%) | — | 1× DGX Spark |
| 9 | Hy4 preview | 130/157 (82.8%) | 30.5 min | OpenRouter |
| 10 | DeepSeek V4.1 Flash | 127/157 (80.9%) | 9.3 min | OpenRouter |
| 11 | GLM-5.2 | 121/157 (77.1%) | 53 min | Ollama Cloud |
| 12 | DSV4 Vision-Exp | 117/157 (74.5%) | 25.4 min | 2× DGX Spark |
| 13 | Nex-N2.5-Pro free | 81/157 (51.6%) | 78.6 min | OpenRouter |
V4.1 Flash takes #10. It is 1.9 points behind Hy4 and 1 point behind our V4 Pro measurement (128/157). It is 3.8 points ahead of GLM-5.2. Tools, instruction, and reasoning sit with Hy4. Math and the coding syntax floor are why it does not join Fable.
GPT-6 Astra Pro (batch) and Grok 4.6 tied at 153/157. Astra's 4.7-minute wall is batch completion, not per-request chat latency. Do not read it as faster than Grok on the same API shape. The 9.3-minute Flash wall is sync chat. Mean 3.54 s per test.
By difficulty
| Tier | Pass | Rate |
|---|---|---|
| Easy (10) | 10/10 | 100% |
| Medium (15) | 14/15 | 93.3% |
| Hard (25) | 21/25 | 84.0% |
| Expert (40) | 32/40 | 80.0% |
| Frontier (60) | 44/60 | 73.3% |
| Other (writing + tools, 7) | 6/7 | 85.7% |
Easy is clean. One medium math miss. The rest of the 30 failures sit in hard/expert/frontier plus one writing item.
The 30 failures
Math (14) — all regex misses, no timeouts. Includes the same high-precision cells Grok 4.6 still fails (expert.06 -0.01384, expert.07 -9.417) plus expert.08 (29.924) and frontier.11 (59.596), which Fable also misses. Elapsed 1.7–13.2 s. V4 Pro went 26/30 here. This is the ranking hole versus the previous DeepSeek flagship, not versus Hy4 (Hy4 was 13/30).
Coding (7) — 23/30. 6 SyntaxErrors, 1 assertion. Unterminated strings (hard.03, frontier.05), invalid syntax (frontier.01), Unicode ² U+00B2 (frontier.02, frontier.06), Unicode ’ U+2019 (frontier.07), plus frontier.03 AssertionError. Hy4 had 0 SyntaxErrors. Same Unicode-in-code pattern we documented on Kimi K3.
Reasoning (3) — regex misses on hard.04 (402), frontier.07 (292), frontier.11 (18). 5.5–13.1 s. Hy4 also missed frontier.07.
Instruction (2) — token transforms: expected sguor5 / a9gre9dni9ckk13. The model wrote “let's go step by step” instead of emitting the token. Same family of items Fable and Hy4 miss, plus process narration in content.
Prose (3) — expert.03 regex miss; expert.05 16 lines vs 15; frontier.05 17 lines vs 19.
Writing (1) — writing_creative matched 0/5 keywords (robot, art, dialogue, discover, create).
Failure mix: 0 errors, 0 empty-code, 6 SyntaxErrors, 18 regex misses, 1 coding assert, 2 instruction tokens, 2 line-counts, 1 keyword miss.
Versus V4 Pro
DeepSeek's card says Flash exceeds Pro. Official A thinking-off does not confirm that claim.
| V4.1 Flash (OR, 2026-09-10) | V4 Pro (Ollama Cloud, 2026-08-11) | |
|---|---|---|
| Total | 127/157 (80.9%) | 128/157 (81.5%) |
| Math | 16/30 | 26/30 |
| Coding | 23/30 | 22/30 |
| Reasoning | 27/30 | 24/30 |
| Instruction | 28/30 | 25/30 |
| Wall | 9.3 min | 41.4 min |
| Endpoint | OpenRouter sync | Ollama Cloud |
Flash is faster and slightly stronger on reasoning/instruction/prose. It gives 10 math points back. Net: minus one. Different providers, same 157, both thinking-off. Do not read this as a local-weights bake-off.
What this is not
- It is not the LUMEN one-shot. That post is craft, one prompt, live demo.
- Ranking stays thinking off. The thinking-on arm below is diagnostic, not Official A.
- It is not a local Spark number. 552B backbone, 1M context, DeepSeek-hosted. We did not load weights.
- Vendor agent-loop numbers on the tech report are not this harness. Official A is one shot.
Thinking on (diagnostic, not ranking)
Same 157, same endpoint, --thinking on (runner default; no effort=none). Tag cal-dsv41-flash-or-strict-v01-thinking-on.
130/157 (82.8%). 0 errors. Wall 2699 s (45.0 min). Cost $0.248. Mean / median 17.17 s / 8.95 s. Tokens used 341,651.
| Category | Off (Official A) | On | Delta |
|---|---|---|---|
| coding | 23/30 | 16/30 | −7 |
| instruction | 28/30 | 28/30 | 0 |
| math | 16/30 | 25/30 | +9 |
| prose | 27/30 | 25/30 | −2 |
| reasoning | 27/30 | 29/30 | +2 |
| tool_calling | 2/2 | 2/2 | 0 |
| writing | 4/5 | 5/5 | +1 |
| TOTAL | 127/157 (80.9%) | 130/157 (82.8%) | +3 |
Fixed 16, regressed 13, both-fail 14.
Math recovery is the GLM-5.3-Flash-EXL3 pattern: 16/30 off → 25/30 on. The five remaining math misses are expert.06 (-0.01384), expert.07 (-9.417), expert.08 (29.924), frontier.05 (6.815), frontier.11 (59.596) — the same high-precision cells Grok still fails on two of.
Coding paid for it. SyntaxErrors 6 → 14. Seven items that passed off failed on (unterminated strings, invalid decimal literals, expected :). One Unicode miss became ∩ (U+2229), the Kimi K3 pattern. Thinking dumps CoT into the code channel.
Prose over-generates: frontier.11 expected 1 line, got 125. Instruction frontier.01 expected 7 lines, got 14 (189 s). Writing went 5/5.
Net +3 is a capability shuffle, not a clean lift. 4.8× wall, 2.8× tokens, 3.6× spend for three points and a worse syntax floor. Ranking stays 80.9% off.
Cost and latency
| V4.1 Flash | Hy4 preview | Fable 5.1 | |
|---|---|---|---|
| Wall | 9.3 min | 30.5 min | 35.0 min |
| Mean / median | 3.54 s / 2.27 s | 11.63 s / 7.69 s | 13.4 s / 12.3 s |
| Errors | 0 | 0 | 0 |
| This-run spend | $0.07 | $0.96 | $6.85 |
On this suite Flash is the cheap, fast DeepSeek option that clears 80% with working tools. It does not clear Hy4. It does not clear V4 Pro. Math plus six SyntaxErrors are why.
Reproducing
Raw JSON, run log, smoke, and catalog snapshot:
- NemoKnowledgebase / deepseek-v4.1-flash
- Tag
cal-dsv41-flash-or-strict-v01
cd smf-bench
export SMF_SERVE_RECIPE_ID=OpenRouter-cloud
python3 -u run_stage1.py \
  --endpoint https://openrouter.ai/api/v1 \
  --model deepseek/deepseek-v4.1-flash \
  --tag cal-dsv41-flash-or-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300 \
  --api-key "$OPENROUTER_API_KEY"
The runner sends {reasoning: {effort: "none"}} when --thinking off and the model id contains deepseek-v4.1 or v4.1-flash. Thinking-on omits that field (model default). Tag cal-dsv41-flash-or-strict-v01-thinking-on.
The framework is MIT-licensed at github.com/smfworks/smf-bench.
Verification notes
- Totals from
results/stage1_cal-dsv41-flash-or-strict-v01_20260910_102438.json(summary127/157,pass_rate80.9,error0,wall_time_seconds559.0). - Per-category from
by_category. Difficulty parsed fromv3.<cat>.<tier>.<n>test IDs. Writing + tools counted as Other. - Model id, 1M context, 384k max completion, $0.30/$1.20 list pricing: OpenRouter
/v1/modelson 2026-09-10 fordeepseek/deepseek-v4.1-flash. Off-peak $0.15/$0.60 from/v1/models/.../endpointsweekday overrides. - Endpoint health:
/v1/models/deepseek/deepseek-v4.1-flash/endpointsin the same session (status 0, 5m/30m/1d uptime 100%). - Architecture: Hugging Face
deepseek-ai/DeepSeek-V4.1-Flashconfig.json—deepseek_v41, 40 layers, hidden 5120,n_routed_experts=384,n_shared_experts=1,num_experts_per_tok=6, vocab 129280,max_position_embeddings=1048576. License MIT fromcardData. - 552B backbone / 196B Engram / 8B prefill / 16B decode / 45T / 890 B/token KV: DeepSeek-V4.1 tech report abstract and §2.1. We did not sum safetensors for a parameter count (mixed FP8/FP4/BF16/I8).
- Credits: OpenRouter
/v1/keybefore 372.398586 / after 372.467452. - Smoke:
effort=nonecontent'2 + 2 = 4.',reasoning_tokens=0. Default still thinks (32 reasoning tokens). - Same-day Lumen post is one-shot HTML, not this harness. Prior V4 Pro 128/157 is Ollama Cloud, 2026-08-11, same 157.
- Thinking-on diagnostic:
results/stage1_cal-dsv41-flash-or-strict-v01-thinking-on_20260910_112819.json(summary130/157,pass_rate82.8,error0,wall_time_seconds2699.0,thinkingon)./v1/keybefore 372.467452 / after 372.715613. Fixed 16 / regressed 13 / both-fail 14 vs the off JSON. Not a ranking score.