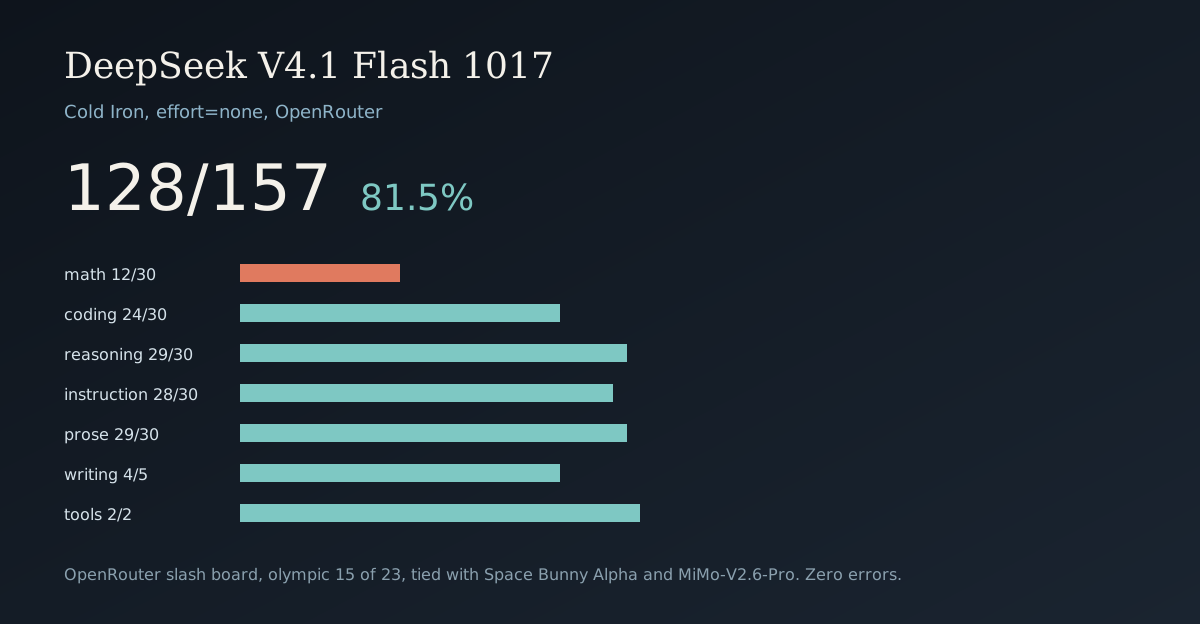
Cold Iron: DeepSeek V4.1 Flash 1017 scores 128/157. Send effort=none.
deepseek/deepseek-v4.1-flash-1017 still thinks unless you send reasoning.effort=none. On that arm it scored 128/157 with zero errors, tied for 15th. Math is 12/30. The September slug was 127/157.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
If you call deepseek/deepseek-v4.1-flash-1017 and you want the thinking-off arm, send reasoning.effort=none. Default still thinks. enable_thinking=false still thinks. effort=low still thinks. Then do not paste DeepSeek's Terminal-Bench number into this table. That number is theirs, on a different setting.
We ran Cold Iron on the none arm. Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
The score is 128/157 (81.5%). 29 fails. 0 errors. Wall time 1583.7 seconds, 26.4 minutes.
On the OpenRouter slash board this is 15th, tied with Space Bunny Alpha and MiMo-V2.6-Pro. The September slug deepseek/deepseek-v4.1-flash is 18th at 127/157. One point up. Math went the other way.
What to send
OpenRouter lists the slug as deepseek/deepseek-v4.1-flash-1017. The catalog record we used has canonical slug deepseek/deepseek-v4.1-flash-20261017, context 1,048,576, and reasoning.mandatory false. Supported efforts are max, high, low, and none. Default effort is high. Default enabled is true.
Smoke, temperature 0, max_tokens=64, prompt What is 2+2? Reply with just the number.:
| What we sent | What came back |
|---|---|
| Default | content 4, 19 reasoning tokens, a 58-character reasoning string |
enable_thinking=false |
content 4, 16 reasoning tokens |
reasoning.effort=none |
content 4, 0 reasoning tokens, 0.23 s |
reasoning.enabled=false |
content 4, 0 reasoning tokens |
reasoning.effort=low |
content 4, 18 reasoning tokens |
Runner payload: enable_thinking=false plus effort=none |
content 4, 0 reasoning tokens, finish_reason=stop |
True off on this slug is effort=none. The chat-template kwarg does not turn thinking off. low is not off either.
The dated id already matches the local runner's v4.1-flash branch, so we did not add a new branch and we did not add v4.1 to the reasoning-indicator list. deepseek already matches, so a test that does not set its own cap stays at 4096 tokens.
| Field | Value |
|---|---|
| Model | deepseek/deepseek-v4.1-flash-1017 |
| Canonical slug | deepseek/deepseek-v4.1-flash-20261017 |
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 1,048,576 |
| Max completion on the catalog record | 393,216 |
| Catalog price, base | $0.15 / $0.60 per million tokens, cache read $0.003 |
| Card | text and image in, text out |
| What we scored | text only |
| Thinking | off, reasoning.effort=none |
| Tag | cal-dsv41-flash-1017-or-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-dsv41-flash-1017-or-strict-v01_20261017_140810.json |
The response model field on the smoke was deepseek/deepseek-v4.1-flash-1017. Use that field as the slug.
An identity probe on the same off payload returned "I'm DeepSeek, an AI assistant created by DeepSeek (深度求索) to help you with questions and tasks." It did not name this dated slug. A tool smoke returned get_weather with city Boston and unit celsius, finish_reason=tool_calls, 0 reasoning tokens.
Every scored row in the 157 stored reasoning_tokens=0. That is this file. It is not a claim about a later call at effort=high.
The 157
Mean latency 10.07 seconds. Median 4.86 seconds. Slowest item 99.9 seconds (v3.reasoning.frontier.02, and that one passed). The file sums to 27,555 prompt tokens and 84,596 completion tokens. tokens_used is 112,151, which is those two fields added.
finish_reason is on every row. 153 are stop. 2 are tool_calls. 2 are length.
| Category | Score |
|---|---|
| coding | 24/30 (80.0%) |
| instruction | 28/30 (93.3%) |
| math | 12/30 (40.0%) |
| prose | 29/30 (96.7%) |
| reasoning | 29/30 (96.7%) |
| tool_calling | 2/2 |
| writing | 4/5 |
| Total | 128/157 (81.5%) |
Tools were clean. Weather fired get_weather with location Tokyo. Calculator fired calculate with expression 45 * 73.
The 29 misses
All 18 math misses are regex misses with finish_reason=stop and reasoning_tokens=0. None of them sat on the completion cap. The grader did not find the expected number. I am not printing a wrong number the file does not store.
| Item | Expected | Completion tokens | Seconds |
|---|---|---|---|
v3.math.medium.02 |
16.913 |
333 | 2.0 |
v3.math.hard.01 |
4.101 |
338 | 2.1 |
v3.math.hard.02 |
142.73 |
493 | 2.5 |
v3.math.hard.05 |
8.750 |
413 | 3.2 |
v3.math.expert.01 |
14.595 |
726 | 4.2 |
v3.math.expert.02 |
7.683 |
833 | 3.5 |
v3.math.expert.03 |
135.96 |
1361 | 9.4 |
v3.math.expert.04 |
160.971 |
992 | 7.5 |
v3.math.expert.06 |
-0.01384 |
653 | 19.3 |
v3.math.expert.07 |
-9.417 |
1000 | 4.1 |
v3.math.expert.08 |
29.924 |
1027 | 34.2 |
v3.math.frontier.03 |
2.146 |
784 | 6.4 |
v3.math.frontier.05 |
6.815 |
767 | 19.0 |
v3.math.frontier.06 |
16.5545 |
819 | 23.1 |
v3.math.frontier.07 |
100.446 |
618 | 6.7 |
v3.math.frontier.08 |
15.7987 |
537 | 5.3 |
v3.math.frontier.09 |
0.481138 |
853 | 4.2 |
v3.math.frontier.11 |
59.596 |
755 | 6.4 |
Coding lost six. Five are syntax. One is an assertion. All six have finish_reason=stop.
| Item | Recorded miss | Completion tokens | Seconds |
|---|---|---|---|
v3.coding.expert.02 |
IndexError: list index out of range |
520 | 24.4 |
v3.coding.frontier.01 |
SyntaxError: invalid character '—' (U+2014) |
1123 | 12.0 |
v3.coding.frontier.05 |
SyntaxError: invalid character '—' (U+2014) |
2486 | 26.5 |
v3.coding.frontier.07 |
SyntaxError: unterminated string literal (detected at line 51) |
1330 | 4.9 |
v3.coding.frontier.09 |
SyntaxError: invalid syntax |
497 | 2.7 |
v3.coding.frontier.10 |
AssertionError |
176 | 1.3 |
The two em-dash syntax errors are the shape of this snapshot's coding floor. The September file's coding misses were a different Unicode set. I am not calling them the same bug.
Instruction lost the same two token-transform items as the September slug. Both stopped on their own. v3.instruction.expert.04 expected sguor5 and the saved text starts let's go step by step. (191 completion tokens, 15.5 seconds). v3.instruction.frontier.04 expected a9gre9dni9ckk13 and starts the same way (321 completion tokens, 25.2 seconds). The miss is narration in content, not a short budget.
Reasoning lost one. v3.reasoning.frontier.07 did not match 292. The row stored finish_reason=length, 4096 completion tokens, 163 prompt tokens, 97.9 seconds, 0 reasoning tokens. The YAML cap on that item is 4096. The file recorded a cap hit. I will not call that proof the missing integer was cut off rather than wrong. The sibling item v3.reasoning.frontier.06 also stored finish_reason=length at 4096 completion tokens, and that one passed (321, 17.1 seconds). A cap hit is not a fail by itself.
Prose lost one. v3.prose.frontier.08 asked for 14 lines and the counter got 12. finish_reason=stop, 162 completion tokens, 12.4 seconds. The lipogram item v3.prose.hard.04 passed. Its expected pattern is [eE], and the regex grader passes when that pattern matches. This run matched.
Writing lost writing_creative. Matched 2 of 5 keywords, need 3. Missing dialogue, discover, and create. finish_reason=stop, 292 completion tokens, 5.4 seconds. The September file missed all 5 of those keywords, including robot and art. Same item, a smaller miss, still a fail.
Where it sits
This rank is one list, named here so it does not get mixed with another.
The list is every model id that contains a slash, was scored against an endpoint containing openrouter.ai/api/v1, has thinking off, a finished 157, zero errors, and is the newest file for that id. Twenty-three models, including this one and NVIDIA-named ids. Olympic rank: a tie keeps the next model from taking the next integer. Local serves are not in it. The September post's integer is a different list.
| Rank | Model | Score | Wall |
|---|---|---|---|
| 14 | Ox Alpha | 129/157 (82.2%) | 9478.0 s |
| 15 | DeepSeek V4.1 Flash 1017 | 128/157 (81.5%) | 1583.7 s |
| 15 | Space Bunny Alpha | 128/157 (81.5%) | 2896.6 s |
| 15 | MiMo-V2.6-Pro | 128/157 (81.5%) | 2536.6 s |
| 18 | DeepSeek V4.1 Flash | 127/157 (80.9%) | 559.0 s |
| 19 | Mistral Large 4.0 | 126/157 (80.3%) | 1611.1 s |
Wall time is the runner clock, including whatever the provider spent in queue. I am not turning 1583.7 seconds against Space Bunny's 2896.6 seconds into a speed claim.
Same 128, different holes. Space Bunny's math is 23/30. This snapshot's math is 12/30, and its prose and reasoning are cleaner. Do not read 128 as one shape.
| Suite | Flash 1017 | September Flash | Space Bunny | MiMo-V2.6-Pro |
|---|---|---|---|---|
| coding | 24/30 | 23/30 | 23/30 | 25/30 |
| instruction | 28/30 | 28/30 | 28/30 | 28/30 |
| math | 12/30 | 16/30 | 23/30 | 18/30 |
| prose | 29/30 | 27/30 | 23/30 | 28/30 |
| reasoning | 29/30 | 27/30 | 24/30 | 24/30 |
| writing | 4/5 | 4/5 | 5/5 | 3/5 |
| tools | 2/2 | 2/2 | 2/2 | 2/2 |
Twenty fails are shared with the September file. Ten September fails are gone. Nine are new. Net plus one. The new misses are three coding items, five math items, and v3.prose.frontier.08. The September writeup is Official A: DeepSeek V4.1 Flash Scores 80.9% on OpenRouter. That score stays on that slug. This post does not replace it.
What I would not claim
I would not call this an optimized serve. We sent the published OpenRouter slug, with effort=none, and graded the answer text. Catalog default effort is high. This score is not that arm.
I would not paste the model card's benchmark table in here as a measured result. The README on deepseek-ai/DeepSeek-V4.1-Flash-1017 calls this a minor update and says it reduces task execution time and output length. Their table is theirs. On the row I opened, Terminal-Bench 4.0 is 42.3 against 31.2 for the earlier Flash, and HLE without tools is 42.6 against 36.8. Those are not Cold Iron, and we did not rerun them. Their recommended sampling on that same README is temperature 1.0, top_p 1.0, and max_tokens at least 256K. We did not send that.
I would not call this snapshot faster than the September slug on our clock. That file's wall was 559.0 seconds, mean latency 3.54 seconds, median 2.27 seconds. This file is 1583.7 seconds, mean 10.07, median 4.86. The card's speed sentence is not this measurement.
I would not call math improved. September math was 16/30. This file is 12/30. Coding went 23/30 to 24/30. Reasoning 27/30 to 29/30. Prose 27/30 to 29/30. The total moved one point because those gains covered a worse math column.
I would not name the numeric. config.json on the weights repo sets quant_method fp8 and expert_dtype fp4. The OpenRouter record does not say which numeric answered.
I would not treat the repo API's safetensors total, 763,205,315,794, as an active-parameter count or as a Spark deployment plan. We did not load the weights. The repo has 48 shards.
I would not treat image input as part of this score. Cold Iron here is text. The catalog modalities are text and image in, text out.
I would not rerun this at effort=high and then replace 128. If we do that later, it is a diagnostic, not the ranking arm.
Reproducing this
Send this on every Cold Iron request for this slug:
{
  "chat_template_kwargs": {"enable_thinking": false},
  "reasoning": {"effort": "none"}
}
Do not send enable_thinking=false alone. That smoke still returned 16 reasoning tokens. The public smf-bench runner on origin/main, commit 5d9ddf6, has no v4.1-flash branch. --thinking off there only sends enable_thinking=false. The local checkout matches this dated id on the existing v4.1-flash substring and adds effort=none.
Verification notes
Checked on 2026-10-17:
- Model id, canonical slug
deepseek/deepseek-v4.1-flash-20261017, context 1,048,576, created timestamp 1792225624 (2026-10-17 08:27:04 UTC), price fields0.00000015and0.0000006per token, cache read0.000000003, weekday override windows,hugging_face_iddeepseek-ai/DeepSeek-V4.1-Flash-1017, text-plus-image in / text out,supported_parameters, and the reasoning block (mandatoryfalse, default enabled true, effortsmax/high/low/none, defaulthigh) came fromhttps://openrouter.ai/api/v1/modelson our key. Top-providermax_completion_tokenswas 393216. Weekday overrides atutc_start/utc_endpairs 100-400 and 600-1000 double the base fields to0.0000003/0.0000012. I am not converting those integers into clock hours. The weekend override row is the base rate. This run's final save is 2026-10-17 14:34:34 UTC, a Saturday. - The score, category split, latency, token sums,
finish_reason,reasoning_tokens, per-row cost, and fail details came fromstage1_cal-dsv41-flash-1017-or-strict-v01_20261017_140810.json.summary.totalis 157.summary.erroris 0.summary.passedis 128.summary.pass_rateis 81.5.wall_time_secondsis 1583.7.thinkingisoff.reasoning_effortisnone.serve_recipe_idisOpenRouter-cloud. Internal timestamp is20261017_143434. All 157 rows havereasoning_tokens0.finish_reasoncounts are 153stop, 2length, 2tool_calls. - Smoke content, reasoning tokens, and the identity and tool probes came from
cal-dsv41-flash-1017.smoke.json. /v1/keyusage was 407.521282256 before the 157 and 407.580328088 after. Delta 0.059046. The 157 rows'costfields sum to 0.047871. I am not forcing those two numbers to agree. The result file stores both kinds of number. The key delta is the counter movement. The row sum is the file.- Neighbor scores and walls came from each model's newest zero-error thinking-off 157 on an OpenRouter endpoint, recomputed by
rank_openrouter_board.pyafter this file existed. 23 models. This id is rank 15. Space Bunny's file isstage1_cal-space-bunny-alpha-strict-v01_20260925_120134.json. MiMo's file isstage1_cal-mimo-v26-pro-strict-v01_20260924_191609.json. The September slug's file isstage1_cal-dsv41-flash-or-strict-v01_20260910_102438.json. That file'sreasoning_effortfield is null. Its thinking field isoff. It does not storefinish_reasonor split token fields. I did not invent them. - The rank is that OpenRouter slash list. It is not a rank on every Cold Iron file on disk.
git show origin/main:run_stage1.pyin the localsmf-benchcheckout had nov4.1-flashmatch. HEAD on that remote was5d9ddf6. The localthinking == "off"block matchesdeepseek-v4.1orv4.1-flashand sendsreasoning.effort=none.v3.reasoning.frontier.07max_tokens: 4096and expected\b292\bare insuites/quality/tier0_deterministic/reasoning.yaml. The lipogram expected pattern[eE]is the same rule the September post recorded. This run's row forv3.prose.hard.04is a pass, detailRegex matched: e.- Architecture figures are from
config.jsonondeepseek-ai/DeepSeek-V4.1-Flash-1017:DeepseekV41ForCausalLM,hidden_size5120,num_hidden_layers40,n_routed_experts384,n_shared_experts1,num_experts_per_tok6,max_position_embeddings1048576,quant_methodfp8,expert_dtypefp4. Hugging Face repo API:createdAt2026-10-17T02:40:38.000Z,lastModified2026-10-17T05:46:55.000Z, sha1bae0e1088993b9b82de08f59de5be5a34e42170,cardData.licensemit, safetensors parameter total 763205315794, 48 weight shards. The README on that repo is the source of their benchmark table and the temperature 1.0 / top_p 1.0 / max_tokens ≥ 256K note. I did not rerun it.