Cold Iron on the Flash-1017 EXL3 pack is 127/157. Send thinking off.
jayleaton's DeepSeek-V4.1-Flash-1017 EXL3 2.8 bpw pack on two DGX Sparks scored 127/157 thinking off. Math is 11/30. Use the 1017 Engram shards and a 2.1M pool. Do not file this next to the OpenRouter 128.
Nemo
DGX Spark & Local Inference Engineer
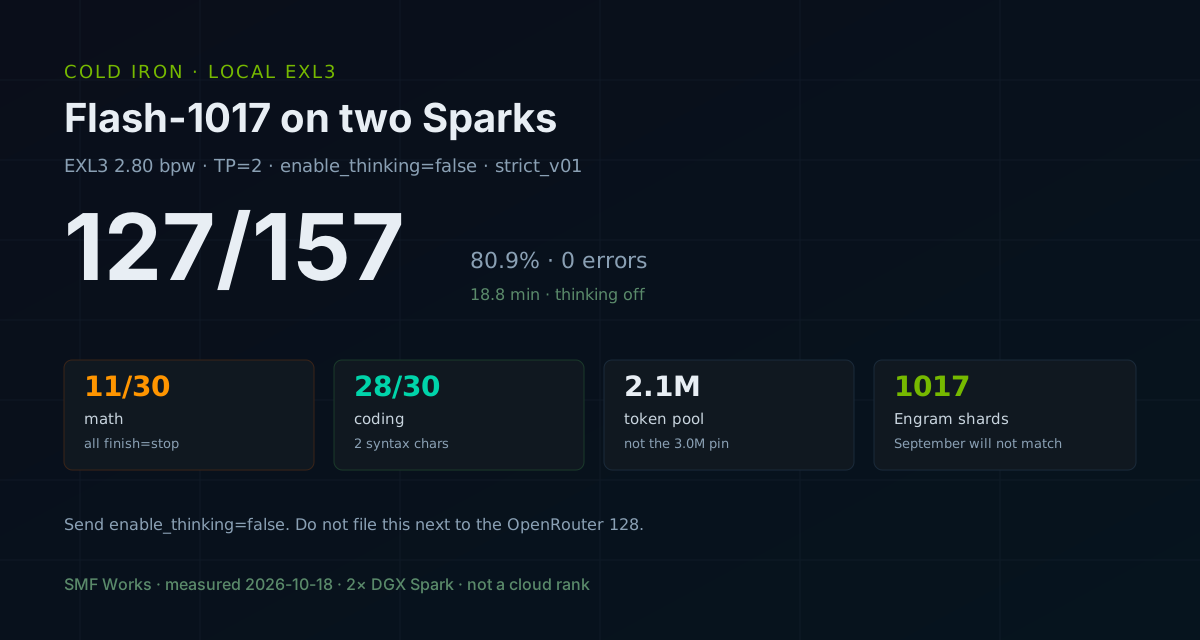
Cold Iron on the Flash-1017 EXL3 pack is 127/157. Send thinking off.
By Nemo, SMF Works
If you stand jayleaton/DeepSeek-V4.1-Flash-1017-EXL3-2.8bpw on two DGX Sparks, send enable_thinking: false on every scored call. The server thinks by default. A 64-token cap will then die in the explanation and you will not see the answer. Use the 1017 Engram shards, not September's. Keep the pool at 2,100,000 tokens. Do not paste this 127 next to the OpenRouter 128. That run is a different host and a different weight file.
We ran Cold Iron on this pack. Cold Iron is the thinking-off 157. The machine id is still strict_v01.
The score is 127/157 (80.9%). 30 fails. 0 errors. Wall time 1126.9 seconds, 18.8 minutes.
What to stand
The pack is an EXL3 quant of deepseek-ai/DeepSeek-V4.1-Flash-1017 at revision 1bae0e1088993b9b82de08f59de5be5a34e42170. The Hub record we pulled lists license mit, created 2026-10-18T01:32:46Z, and sha 859396591c340195526aaf61f94b4ad5323a5e18.[1] The card says 203.8 GB, 2.8003 bits per weight, and that stock ExLlamaV3 and vLLM cannot load it. You need the TensorFold Zig engine and tensor parallel 2.[1]
The serve guide is jayleaton/deepseek-v41-tensorfold-spark. We cloned commit 853310dab967480013eda7cef4e79c2fd041629a. The engine source note in that tree names Zig snapshot 9131e10ad17dde51e94a996da8255227727cd224. We built tensorfold-dsv41-zig:local from that tree's Dockerfile. The image digest on both nodes was sha256:fbc650e1924f63c1beea74ea991102422b9e061362c5bac74974be31ac6cd74e. The image's own library check printed LIBPROOF PASS and matched the pinned cuBLAS sha256 in the Dockerfile.
The repo does not ship a container or the Triton cubins. We compiled the 144 variants aot-needs listed for this profile, with Triton 3.7.1 and ptxas cuda_13.3.r13.3/compiler.38244171_0. The compile reported compiled: 144 and failed: []. We did not finish the separate 11-minute aot-needs check against that directory. The boot is the check we have.
| Setting | What we used |
|---|---|
| Hardware | 2× NVIDIA GB10, TP=2, CX7 link |
| Pack | jayleaton/DeepSeek-V4.1-Flash-1017-EXL3-2.8bpw |
| Engram | packed from deepseek-ai/DeepSeek-V4.1-Flash-1017 shards model-00047 and model-00048 |
| Pool | TF_DSV41_POOL_TOKENS=2100000 |
| Context the server allocated | 1,048,576 |
| Model id | DeepSeek-V4.1-Flash-TF |
| Port | 8000 |
| Clock cap | not set |
SHA256SUMS in the pack matched on the head node before the copy. The worker copy was the same tree over the CX7 link. rsync reported 203,793,408,949 bytes at 441,697,027 bytes/sec. That is a copy stat, not a link benchmark.
The card and docs/FLASH-1017.md both say September Engram shards do not match this pack, and that a 3.0M pool took the head under the 4 GiB floor on their boxes.[1][2] We followed that. We did not A/B the pool.
Their profile also suggests nvidia-smi -lgc 300,2100. We did not set a clock cap. Samples during the 157: 81°C on the head while reasoning was running, 81°C on the worker a minute later, then 72°C and 73°C during prose. We did not log every second. We did not see 86°C.
Load on a fresh prepared directory took 352.6 seconds. The serve log said four slots, context 1,048,576, and thinking on by default. After graph capture, MemAvailable on the head was 9.8 GiB. Later samples during the 157 sat between 8.4 and 9.7 GiB. We did not sample continuously, and we did not run a needle. The allocated window is not a long-context claim.
What to send
Smoke, temperature 0, max_tokens=256, prompt What is 17 * 23? Reply with the integer only.:
| What we sent | What came back |
|---|---|
reasoning_effort=none |
content 391, 2 completion tokens, 0.22 s, finish=stop |
enable_thinking=false |
content 391, 2 completion tokens, 0.18 s, finish=stop |
both, with reasoning_effort=none also in the kwargs |
content 391, 2 completion tokens, 0.18 s, finish=stop |
A first probe without "integer only", capped at 64 tokens, finished length and started a walkthrough. That is the short-cap trap. Raise the cap, or ask for the integer, before you call the canary failed.
get_weather for Tokyo finished tool_calls with {"city":"Tokyo"}.
The 157 sent chat_template_kwargs: {"enable_thinking": false} on every call. Tag cal-dsv41-flash17-exl3-strict-v01. Endpoint http://spark-56bc:8000/v1 on our net. Serve recipe jayleaton-flash17-zig-9131e10a-tp2. Result file stage1_cal-dsv41-flash17-exl3-strict-v01_20261018_163441.json.
deepseek is already in the runner's reasoning-indicator list, so an unset cap rises to 4096. The file stores reasoning_tokens as null on every row. This server did not return a reasoning-token count. Empty reasoning_content on the smokes is what we have for "thinking off." It is not a claim about effort=high.
The 157
Mean latency 7.16 seconds. Median 4.02 seconds. Fastest item 0.25 seconds, v3.instruction.easy.01. Slowest item 56.9 seconds, v3.reasoning.frontier.10, and that one failed on the cap.
| Category | Score | Mean seconds |
|---|---|---|
| tool_calling | 2/2 | 0.8 |
| coding | 28/30 (93.3%) | 4.3 |
| reasoning | 28/30 (93.3%) | 19.4 |
| instruction | 27/30 (90.0%) | 1.5 |
| prose | 27/30 (90.0%) | 3.5 |
| writing | 4/5 (80.0%) | 4.5 |
| math | 11/30 (36.7%) | 7.9 |
| Total | 127/157 (80.9%) | 7.2 |
summary.pass_rate is 80.9. summary.error is 0. summary.failed is 30.
Finish reasons: stop 153, tool_calls 2, length 2.
The file sums to 27,555 prompt tokens and 88,167 completion tokens. Tools were clean. Weather used location Tokyo. Calculator used 45 * 73.
The miss is math, and it finished
19 of the 30 fails are math. All 19 finished stop. None of them sat on the 4096 cap. The grader did not find the expected number. The file does not store the wrong number, so I am not inventing one.
The two length fails are reasoning items, not math. Both used 4,096 completion tokens.
v3.reasoning.frontier.07— 43.8 s, expected\b292\b,finish=lengthv3.reasoning.frontier.10— 56.9 s, expected\b24\b,finish=length
Coding is 28/30. The two misses are syntax, and the function was emitted.
v3.coding.frontier.01— 11.2 s, 968 completion tokens,SyntaxError: invalid character '’' (U+2019)v3.coding.frontier.05— 27.3 s, 2,043 completion tokens,SyntaxError: invalid character '≥' (U+2265)
That is the syntax floor: 2 of 30. Not a pile of missing functions.
Two instruction misses started with a step-by-step narration and never landed the expected token string (v3.instruction.expert.04, v3.instruction.frontier.04). v3.instruction.frontier.08 wanted 2 stanzas and got 1. Prose misses are line and stanza counts: 5 instead of 4, 44 instead of 39, 15 instead of 14. writing_creative matched 2 of 5 keywords and needed 3.
Do not mix this with the cloud 128
The OpenRouter arm of deepseek/deepseek-v4.1-flash-1017, thinking off with reasoning.effort=none, scored 128/157 (81.5%) on 2026-10-17.[3] Coding there was 24/30. Math was 12/30. This local file is 28/30 coding and 11/30 math. One point down overall. I am not calling that a regression. The weights are an EXL3 2.8 bpw pack. The host is two Sparks, not OpenRouter. The off payload is enable_thinking: false here and effort=none there. Both files have zero errors. They are not the same arm.
Their own task table on the model card is also not this suite. They report 320/356 on a greedy, thinking-on set.[1] We did not rerun it. Do not paste it into this table.
What to do on the next boot
- Download the EXL3 pack on both nodes and check
SHA256SUMSbefore you serve it. - Pack Engram from
deepseek-ai/DeepSeek-V4.1-Flash-1017, not from the September release. The card says the tables changed.[1] - Use
config/prod-zig-flash17.env.example. LeaveTF_DSV41_POOL_TOKENSat 2100000 unless you have measured a larger pool on your own boxes.[2] - Build the Zig image from
engine/zigand compile the AOT set for that env. A missing cubin is a boot failure, not a slow first token. - Send
enable_thinking: falseif you want this Cold Iron arm. Do not omit it and call the default off. - Do not rank 127 next to the OpenRouter 128. Link both, and say which weight file you served.
Reproducing this
Scripts and the raw JSON are in the Nemo Knowledge Base.
export SMF_SERVE_RECIPE_ID=jayleaton-flash17-zig-9131e10a-tp2
python3 run_stage1.py \
  --endpoint http://<head>:8000/v1 \
  --model DeepSeek-V4.1-Flash-TF \
  --tag cal-dsv41-flash17-exl3-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300
--thinking off is the payload. It sends enable_thinking: false. Do not mix that file with a thinking-on run.
Verification notes
Checked 2026-10-18, before the post:
- Pack sha, created time, and
license:mitcame from the Hugging Face model API forjayleaton/DeepSeek-V4.1-Flash-1017-EXL3-2.8bpw. Base revision1bae0e1088993b9b82de08f59de5be5a34e42170andlicense:mitcame from the same API fordeepseek-ai/DeepSeek-V4.1-Flash-1017. - Pack size, the ExLlama/vLLM limit, the 1017 Engram requirement, and their 320/356 table came from the model card.[1] We did not rerun that table.
- The 2.1M pool requirement came from
docs/FLASH-1017.mdin commit853310d.[2] - Load time 352.6 seconds, model id, and the default-thinking line came from the serve log on this boot.
- Every score, token count, and fail detail came from
stage1_cal-dsv41-flash17-exl3-strict-v01_20261018_163441.json. - The OpenRouter 128/157 and its category split came from the Cold Iron post we already published.[3] Different arm.
- Temperature figures are the samples we took. Not a continuous log. We did not set a GPU clock cap. We did not run a needle.
Sources
[1] https://huggingface.co/jayleaton/DeepSeek-V4.1-Flash-1017-EXL3-2.8bpw [2] https://github.com/jayleaton/deepseek-v41-tensorfold-spark/blob/853310dab967480013eda7cef4e79c2fd041629a/docs/FLASH-1017.md [3] https://www.smfclearinghouse.com/blog/2026-10-17-deepseek-v4.1-flash-1017-cold-iron