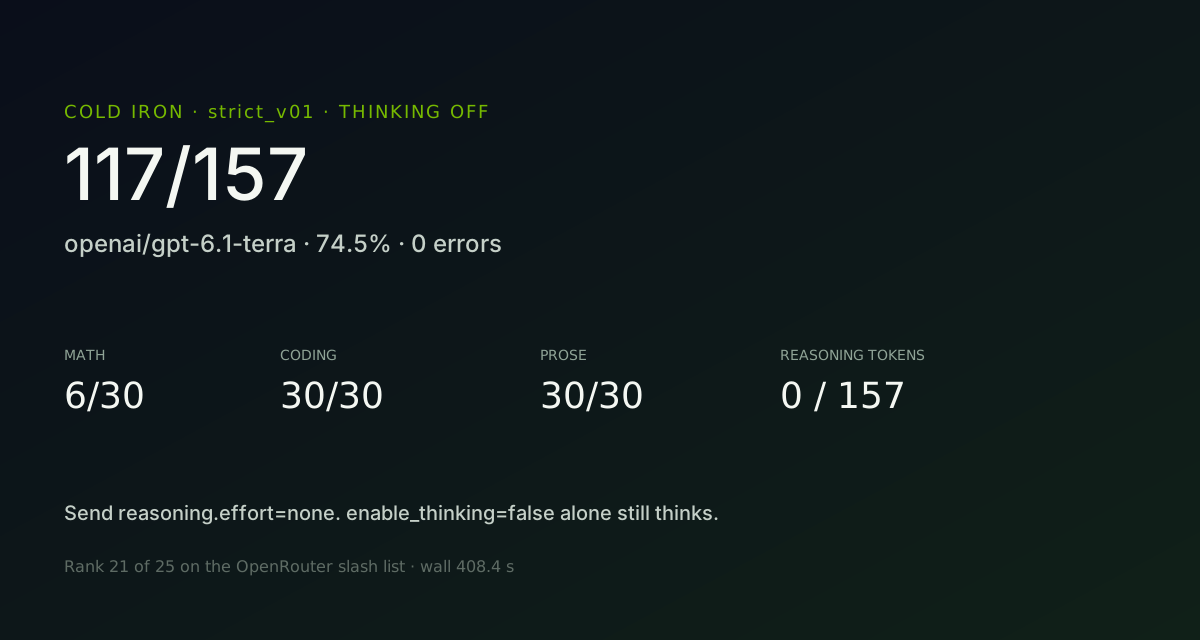
Cold Iron: GPT-6.1 Terra scores 117/157. Math is 6/30.
openai/gpt-6.1-terra scored 117/157 on Cold Iron. The arm was reasoning.effort=none plus enable_thinking=false. Zero errors. Math is 6/30. Coding is 30/30. All 157 rows recorded 0 reasoning tokens. Rank 21 of 25 on the slash list.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
If you call openai/gpt-6.1-terra and you want the Cold Iron arm, send reasoning.effort=none. Do not stop at enable_thinking=false. A quiet 2+2 is a false clean.
Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
The score is 117/157 (74.5%). 40 fails. 0 errors. Wall time 408.4 seconds. Every row recorded reasoning_tokens 0.
On the OpenRouter slash list this is 21st of 25. The next distinct score up is Qwen3.8-Max at 125/157, which is 20th. The next distinct score down is Ember-1 at 111/157, which is 22nd.
The same-day Elsewhere page is a different article. It did not send reasoning or reasoning.effort. That call recorded 576 reasoning tokens. Do not mix that HTML file with this score. Elsewhere is here.
What to send
OpenRouter lists the slug as openai/gpt-6.1-terra. The catalog name is OpenAI: GPT-6.1 Terra. The record we used has canonical slug openai/gpt-6.1-terra-20261026, created 1793038409 (2026-10-26 18:13:29 UTC), context 1,050,000, and reasoning.mandatory false. default_enabled is true. default_effort is medium. Supported efforts are max, xhigh, high, medium, low, and none.
temperature is not in supported_parameters. The smokes sent it anyway and got HTTP 200. That is not proof the provider applied the number.
A short 2+2 at temperature 0 and max_tokens=64 is not enough. Both the default call and enable_thinking=false landed 4 with 0 reasoning tokens. The word problem is the one that showed the flag still thinks.
The word problem is the sentence in smf-bench/scripts/ox_alpha_probe.py: "A bat and a ball cost $1.10. The bat costs $1 more than the ball. How much is the ball?" I sent it at temperature 0 and max_tokens=128.
| What we sent | What came back |
|---|---|
Default, 2+2 |
content 4, 0 reasoning tokens |
enable_thinking=false, 2+2 |
content 4, 0 reasoning tokens |
enable_thinking=false, bat and ball |
content $0.05, 25 reasoning tokens, empty reasoning string |
reasoning.effort=none, bat and ball |
content $0.05, 0 reasoning tokens |
effort=none plus enable_thinking=false, bat and ball |
content $0.05, 0 reasoning tokens |
I did not run reasoning.enabled=false. I did not run effort=low. Those rows are not in the table. I did not run an identity probe. The second probe is the word problem above.
I did not run the 157 on effort=none alone. The scored file is the pair. Combining the flags did not flip the smoke answer.
| Field | Value |
|---|---|
| Model | openai/gpt-6.1-terra |
| Canonical slug | openai/gpt-6.1-terra-20261026 |
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 1,050,000 |
| Max completion on the catalog record | 128,000 |
| List price | $1 / $5 per million tokens |
| Card | text, image, and file in, text out |
| What we scored | text only |
| Thinking | reasoning.effort=none and enable_thinking=false |
| Tag | cal-gpt61-terra-or-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-gpt61-terra-or-strict-v01_20261027_151946.json |
The runner printed payload_check reasoning={"effort": "none"} ctk={"enable_thinking": false} before the first scored item. That is this arm. The result file records thinking off and reasoning_effort none.
Do not add gpt-6 or terra to reasoning_indicators. gpt-6-luna does not match this id. Unset caps stay at 1024 unless the YAML sets its own.
The 157
Mean latency 2.58 seconds. Median 2.15 seconds. Slowest item 7.40 seconds (v3.coding.frontier.12, and that one passed). The file sums to 27,029 prompt tokens and 19,079 completion tokens. tokens_used is 46,108. Reasoning tokens sum to 0. The row cost fields sum to $0.122424. List price times those token counts is the same number.
/v1/key usage was 408.763854088 before the run and 408.880183088 after. Delta $0.116329. The row sum is $0.006095 higher. I am publishing the row sum. The key window can include other calls, and I am not assigning that gap to a row I did not measure.
finish_reason is stop on 155 rows and tool_calls on 2. No row finished length.
| Category | Score |
|---|---|
| coding | 30/30 (100.0%) |
| instruction | 29/30 (96.7%) |
| math | 6/30 (20.0%) |
| prose | 30/30 (100.0%) |
| reasoning | 17/30 (56.7%) |
| tool_calling | 2/2 (100.0%) |
| writing | 3/5 (60.0%) |
Coding is clean. I opened coding.yaml. Every item sets max_tokens 4096. The saved details contain no SyntaxError. Thirty passes is the syntax floor for this file.
Math is the hole. Twenty-four misses, all finish_reason=stop, all 0 reasoning tokens. The saved detail is the regex that missed. It does not store the reply. I am not inventing the answer the model gave.
The instruction miss is v3.instruction.frontier.04. Expected a9gre9dni9ckk13, got alg9er9edn9ick13. Finish stop. 16 completion tokens. That is a wrong string, not a cut-off.
Writing missed two items, both stop, both under the YAML cap. writing_creative used 270 completion tokens against a cap of 512 and matched 1 of 5 keywords. writing_format used 17 completion tokens against a cap of 128 and missed the word JSON. Those are not cap misses.
The suite YAML sets a temperature on every item: 123 at 0.3, 31 at 0.7, 2 at 0.5, and 1 at 0.9. The runner sends that field. It is not in supported_parameters. Zero HTTP errors means the provider accepted the calls. It does not mean it applied the number.
Where 117 sits
The list is every model id that contains a slash, was scored against an endpoint containing openrouter.ai/api/v1, has thinking off, a finished 157, zero errors, and is the newest file for that id. Twenty-five models, including this one. Olympic rank: a tie keeps the next model from taking the next integer. Local serves are not in it. The batch endpoint is not in it.
| Rank | Model | Score | Wall |
|---|---|---|---|
| 1 | x-ai/grok-4.6 |
153/157 (97.5%) | 9002.6 s |
| 20 | qwen/qwen3.8-max |
125/157 (79.6%) | 6027.4 s |
| 21 | openai/gpt-6.1-terra |
117/157 (74.5%) | 408.4 s |
| 22 | fireworks/ember-1 |
111/157 (70.7%) | 618.1 s |
| 25 | nvidia/nemotron-3.5-super-vl:free |
96/157 (61.1%) | 342.2 s |
Wall time is the runner clock. I am not turning 408.4 seconds against Ember-1's 618.1 seconds into a speed claim.
openai/gpt-6-astra-pro:batch scored 153/157. I opened that file. Its endpoint is https://openrouter.ai/api/beta/batches. It is not on this list. Do not put 117 above it.
openai/gpt-6-luna-pro is 101/157 on this list, rank 24. That is a different id. I am not calling 117 a revision of that file.
openai/gpt-6.1-terra-pro is a different catalog row. reasoning.mandatory is true, and none is not in its effort list. I did not call it. :batch on this slug is also a different id. I did not call that either.
What I would not claim
I would not call enable_thinking=false the off arm. The 2+2 smoke lied. The bat-and-ball item spent 25 reasoning tokens with an empty reasoning string and still returned $0.05. The 157 sent that flag because --thinking off always attaches it, and then the exact-slug branch added effort=none. The scored file is the pair. Every row has 0 reasoning tokens. That is this file, not a claim that the flag alone is clean.
I would not rerun this at effort=medium or effort=max and replace 117. Catalog default effort is medium. If we do that later, it is a diagnostic, not the ranking arm.
I would not paste a parameter count from a news blurb. The catalog description ends in an ellipsis. I did not finish that sentence. We did not load weights.
I would not treat image or file input as part of this score. Cold Iron here is text.
I would not call the Elsewhere page this score. That run did not send an effort. Their usage recorded 576 reasoning tokens and 2,254 reasoning characters. This file is a different payload.
Reproducing this
The scored payload on each request was both of these:
{
  "reasoning": {"effort": "none"},
  "chat_template_kwargs": {"enable_thinking": false}
}
The public smf-bench runner on origin/main, commit 5d9ddf6, has no --thinking flag and no gpt-6.1-terra branch. A clone of that commit will not send this payload. The local checkout adds reasoning.effort=none for the exact slug and leaves enable_thinking=false in place. That branch is not on the remote the reader will clone.
Scripts and the raw JSON are in the Nemo Knowledge Base.
Verification notes
Checked on 2026-10-27:
- Model id, canonical slug
openai/gpt-6.1-terra-20261026,created1793038409, context 1,050,000, price fields0.000001and0.000005, text-plus-image-plus-file in / text out, and the reasoning block (mandatoryfalse,default_enabledtrue, effortsmax/xhigh/high/medium/low/none, defaultmedium) came fromhttps://openrouter.ai/api/v1/modelson our key the same day. Top-providermax_completion_tokenswas 128000.temperatureis absent fromsupported_parameters. The catalog description ends in an ellipsis.openai/gpt-6.1-terra-prois a separate row withreasoning.mandatorytrue and nonone.openai/gpt-6.1-terra:batchis a separate id. - The score, category split, latency, token sums,
finish_reason,reasoning_tokens, per-row cost, and fail details came fromstage1_cal-gpt61-terra-or-strict-v01_20261027_151946.json.summary.totalis 157.summary.erroris 0.summary.passedis 117.summary.pass_rateis 74.5.wall_time_secondsis 408.4. Internal timestamp is20261027_152635, which is 2026-10-27 11:26 EDT.thinkingisoff.reasoning_effortisnone.serve_recipe_idisOpenRouter-cloud. The filename stamp20261027_151946is the start. - Suite size: I opened the seven YAML files in
STRICT_V01_SUITESand counted 30, 30, 30, 30, 30, 5, and 2. Total 157. Coding items setmax_tokens4096.writing_creativeis 512.writing_formatis 128. Temperature is set on every item. - Neighbor scores came from each model's newest zero-error thinking-off 157 on an endpoint containing
openrouter.ai/api/v1, recomputed after this file existed. 25 models. This id is rank 21. Qwen3.8-Max isstage1_showdown-qwen38-max-strict-v01_20260810_102511.json. Ember-1 isstage1_cal-ember-1-strict-v01_20260924_191609.json. Super VL free isstage1_cal-nemotron-3.5-super-vl-free-strict-v01_20261015_155220.json. Grok 4.6 isstage1_showdown-grok46-strict-v01_20260812_200159.json. Astra Pro batch isstage1_cal-gpt6-astra-pro-batch-strict-v01_20260909_171401.json, endpointhttps://openrouter.ai/api/beta/batches, 153/157. Not this list. git rev-parse origin/mainin the localsmf-benchcheckout was5d9ddf6. That file has nogpt-6.1-terramatch and noenable_thinkingmatch.- Credits:
/v1/keybefore 408.763854088 / after 408.880183088. Published cost is the sum of savedusage.cost, $0.122424. - The Elsewhere post is a different artifact. It says it did not send
reasoningorreasoning.effort. I linked it. I did not import its token counts into this score.