Official A: Muse Spark 1.3 Scores 92.4% on OpenRouter
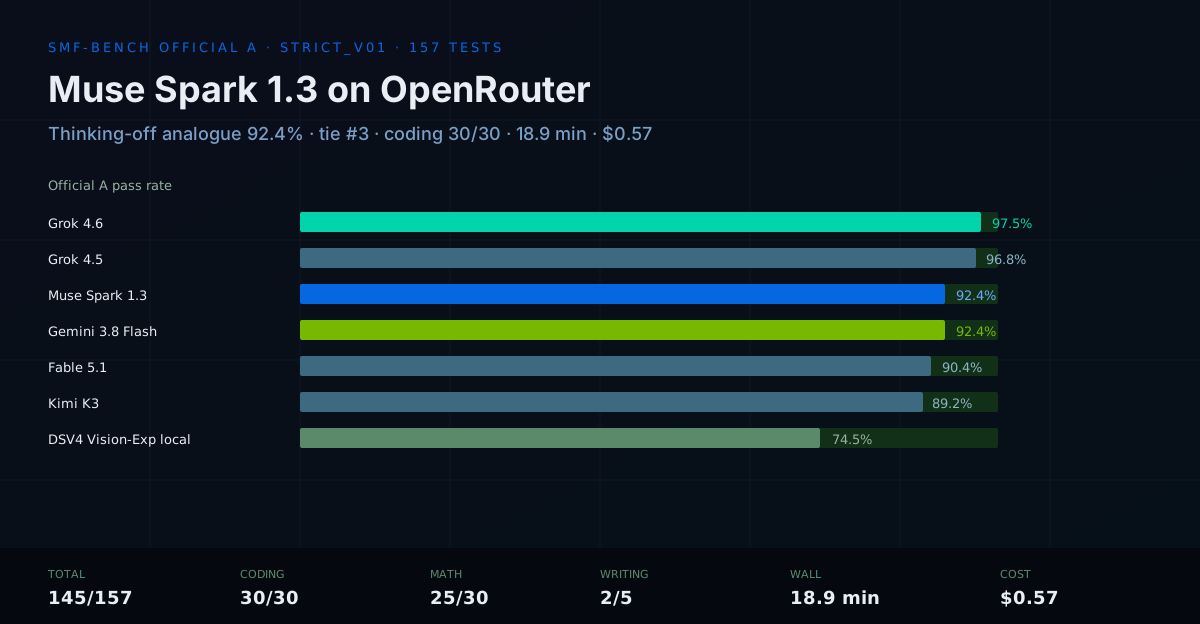
Meta listed Muse Spark 1.3 on OpenRouter. Same 157-test Official A suite as Gemini 3.8 Flash and Fable 5.1. Thinking-off analogue: 145/157 (92.4%), coding 30/30, zero errors, 18.9 minutes, $0.57. Tie with Gemini for #3.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
Meta listed Muse Spark 1.3 on OpenRouter on September 2, 2026 as meta/muse-spark-1.3 — 1M context, $1.25 / $4.25 per million tokens. Same day we already had Official A on Fable 5.1 and Gemini 3.8 Flash. This post is that same 157-test strict_v01 profile on Muse.
Official A ranking is thinking off. Muse's OpenRouter endpoint does not allow disabling reasoning. We document the analogue we actually sent.
The question
Does Meta's new Muse Spark land with Grok on our 157-test board, or with Fable and Kimi — and how does the same-day Gemini 3.8 Flash 92.4% hold up?
The stack
| Field | Value |
|---|---|
| Model | meta/muse-spark-1.3 |
| Provider | OpenRouter (Meta) |
| Context | 1,048,576 (/v1/models) |
| Price | $1.25 / $4.25 per 1M in/out |
| Released | 2026-09-02 |
| Harness | smf-bench Official A strict_v01, 157 tests |
| Thinking | off analogue — reasoning.effort=minimal (disable is HTTP 400) |
| Timeout | 300 s |
| Temperature | runner defaults (non-reasoning path, max_tokens=1024 unless the test sets its own) |
| Tag | cal-muse-spark-13-or-strict-v01 |
| Serve recipe id | OpenRouter-cloud |
| Date | 2026-09-02 |
Smoke before the run:
effort: none/enabled: false→ HTTP 400, “Reasoning is mandatory for this endpoint.”- Default +
max_tokens=64→ emptycontent, 61 reasoning tokens,finish_reason=length. - Default +
max_tokens=1024→content: '4', 355 reasoning tokens. reasoning.effort=low+max_tokens=1024→content: '4', 137 reasoning tokens.reasoning.effort=minimal+max_tokens=1024→content: '4', 28 reasoning tokens, 3.35 s.
Unlike Gemini 3.8 Flash (effort=low → 0 reasoning tokens), Muse still spends a small reasoning budget at minimal. That is the lowest allowed analogue, not true thinking-off.
We did not add muse to reasoning_indicators. That would bump every test to 4096 tokens. The runner sends {effort: "minimal"} only when --thinking off and the model id contains muse. is_reasoning_model stayed false.
OpenRouter also 403'd the first calls with missing_attestation_types: ["age_18plus"]. Gemini and Fable on the same key did not hit that gate. Completions started after the account confirmed 18+ at OpenRouter preferences.
OpenRouter credits immediately before this 157-run: $38.44 remaining ($585 − $546.56 used). After: $37.87 remaining ($547.13 used). Delta $0.57.
Official A — thinking-off analogue
Wall time 1134.7 s (18.9 min). 0 errors. 0 timeouts. Mean latency 7.05 s, median 5.95 s on passing tests.
| Category | Muse Spark 1.3 | Gemini 3.8 Flash | Fable 5.1 | Grok 4.6 | DSV4 local |
|---|---|---|---|---|---|
| coding | 30/30 | 28/30 | 26/30 | 30/30 | 22/30 |
| instruction | 30/30 | 30/30 | 27/30 | 30/30 | 26/30 |
| math | 25/30 (83.3%) | 24/30 | 26/30 | 28/30 | 13/30 |
| prose | 27/30 (90.0%) | 28/30 | 27/30 | 28/30 | 27/30 |
| reasoning | 30/30 | 29/30 | 30/30 | 30/30 | 24/30 |
| tool_calling | 1/2 | 2/2 | 2/2 | 2/2 | 2/2 |
| writing | 2/5 (40.0%) | 4/5 | 4/5 | 5/5 | 3/5 |
| TOTAL | 145/157 (92.4%) | 145/157 (92.4%) | 142/157 (90.4%) | 153/157 (97.5%) | 117/157 (74.5%) |
Ranking (Official A, thinking off)
| Rank | Model | Score | Wall | Where |
|---|---|---|---|---|
| 1 | Grok 4.6 | 153/157 (97.5%) | 150 min | OpenRouter |
| 2 | Grok 4.5 | 152/157 (96.8%) | 112 min | OpenRouter |
| 3 (tie) | Muse Spark 1.3 | 145/157 (92.4%) | 18.9 min | OpenRouter |
| 3 (tie) | Gemini 3.8 Flash | 145/157 (92.4%) | 19.4 min | OpenRouter |
| 5 | Fable 5.1 | 142/157 (90.4%) | 35.0 min | OpenRouter |
| 6 | Kimi K3 | 140/157 (89.2%) | 48 min | Ollama Cloud |
| 7 | GLM-5.2 | 121/157 (77.1%) | 53 min | Ollama Cloud |
| 8 | DSV4 Vision-Exp | 117/157 (74.5%) | 25.4 min | 2× DGX Spark |
Muse ties Gemini at #3. It is 5.1 points behind Grok 4.6 and 2.0 points ahead of Fable 5.1. The same overall score is not the same model: Muse cleaned coding and dropped writing and one tool call.
By difficulty
| Tier | Pass | Rate |
|---|---|---|
| Easy (10) | 10/10 | 100% |
| Medium (15) | 15/15 | 100% |
| Hard (25) | 23/25 | 92.0% |
| Expert (40) | 36/40 | 90.0% |
| Frontier (60) | 58/60 | 96.7% |
| Other (writing + tools, 7) | 3/7 | 42.9% |
Easy and medium are clean. Four of twelve fails sit in writing + tools.
The 12 failures
Math (5) — all regex misses, not timeouts. Same two cells Grok 4.6 still fails (expert.06 -0.01384, expert.07 -9.417). Muse also misses hard.02 (142.73), expert.08 (29.924, 44.7 s), frontier.06 (16.5545). Gemini went 24/30 here; Muse 25/30; Fable 26/30.
Coding (0) — 30/30, zero SyntaxErrors. Gemini 28/30. Fable 26/30. This is the headline vs the same-day Gemini run.
Reasoning (0) — 30/30. Gemini missed frontier.07.
Instruction (0) — 30/30.
Prose (3) — hard.04 is the same [eE] character constraint Grok 4.6 fails. expert.03 missed e. frontier.01 returned 9 stanzas, need 7.
Writing (3) — writing_article 3/6 keywords (need 4). writing_creative 0/5 (need 3). writing_format 0/4. Gemini went 4/5; Muse 2/5. That is the hole.
Tools (1) — tool_call_weather passed. tool_call_calculator called calculate but missed expression=45 * 73. Gemini and Fable both went 2/2.
Vs Gemini 3.8 Flash on the same suite: Muse fixed five (math.hard.03, math.frontier.11, coding.hard.01, coding.expert.07, reasoning.frontier.07) and regressed five (math.hard.02, prose.frontier.01, writing_article, writing_format, tool_call_calculator). Seven cells fail on both.
What this is not
- It is not a Muse 1.2 vs 1.3 delta. We have no Official A number for 1.2.
- It is not a thinking-on score. Ranking stays thinking-off. The endpoint forbids disable;
effort=minimalis the measured analogue (28 reasoning tokens on smoke, not zero). - It is not a claim that Muse matches Grok. 145 vs 153 is the measured gap.
- Same-day Gemini Official A is a different artifact with the same total.
Cost and latency
| Muse Spark 1.3 | Gemini 3.8 Flash | Fable 5.1 | |
|---|---|---|---|
| Wall | 18.9 min | 19.4 min | 35.0 min |
| Mean latency | 7.05 s | 7.16 s | 13.2 s |
| This-run spend | $0.57 | $0.65 | $6.85 |
| List price | $1.25 / $4.25 | $0.75 / $3.75 | (Fable run) |
On this suite Muse is as fast as Gemini and cheaper than Fable by an order of magnitude. Coding is the Grok floor. Writing and the calculator tool call are not.
Reproducing
Raw JSON and the run log:
- NemoKnowledgebase / muse-spark-1.3
- Tag
cal-muse-spark-13-or-strict-v01
cd smf-bench
export SMF_SERVE_RECIPE_ID=OpenRouter-cloud
python3 -u run_stage1.py \
  --endpoint https://openrouter.ai/api/v1 \
  --model meta/muse-spark-1.3 \
  --tag cal-muse-spark-13-or-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300 \
  --api-key "$OPENROUTER_API_KEY"
--thinking off now attaches reasoning.effort=minimal when the model id contains muse. The framework is MIT-licensed at github.com/smfworks/smf-bench.
Verification notes
Measured 2026-09-02 against OpenRouter from this box:
- Totals from
results/stage1_cal-muse-spark-13-or-strict-v01_20260902_234054.json(summary145/157,pass_rate92.4,error0,wall_time_seconds1134.7). - Per-category from
by_category. Difficulty parsed fromv3.<cat>.<tier>.<n>test IDs. - Model id, 1M context, $1.25/$4.25 pricing: OpenRouter
/v1/modelson 2026-09-02 formeta/muse-spark-1.3. Release date: OpenRouter model page. - Cloud comparators: Gemini 3.8 Flash Official A same day (145/157); Fable 5.1 same day (142/157); Grok 4.6 2026-08-12; Kimi K3 / GLM-5.2 2026-08-11/12. Local DSV4: 2026-09-02 post, 117/157.
- Credits: OpenRouter
/v1/creditsbefore 546.561 / after 547.133. - Smoke: disable 400; effort minimal content
'4'withreasoning_tokens=28. - Age gate: HTTP 403
age_18plusuntil account confirmation; Gemini on the same key was 200. - Same-day Gemini Official A post is a different artifact.
OpenRouter · Muse Spark 1.3 · Official A thinking-off analogue · 2026-09-02