Official A on One Spark: Qwen3.8-Flash-Next Scores 87.3%
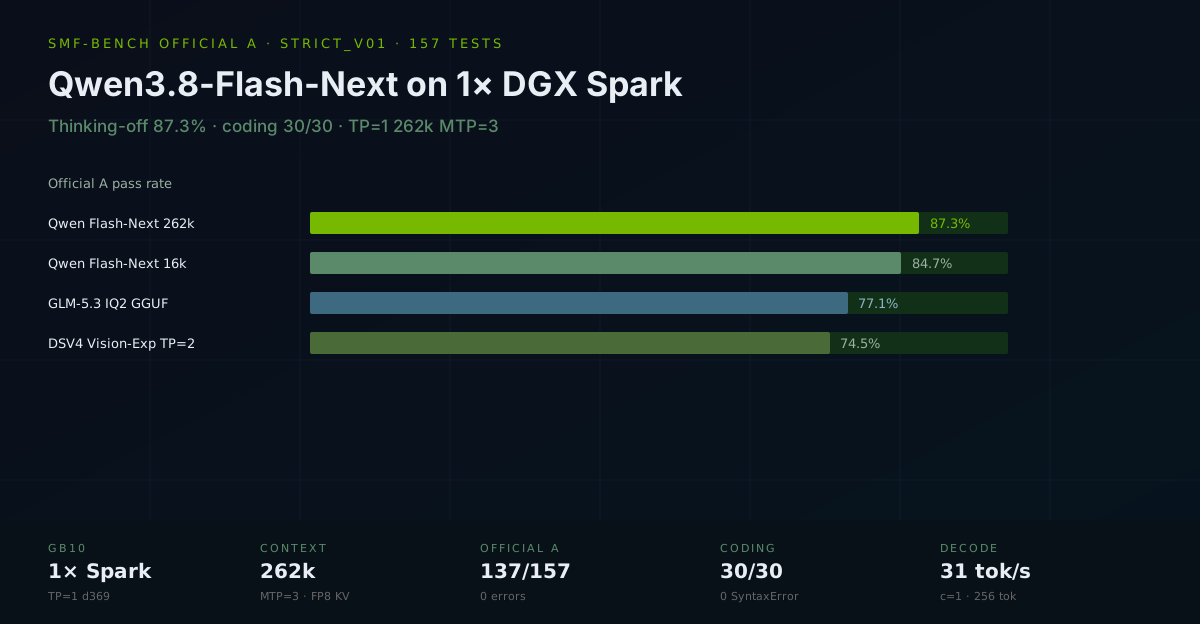
Qwen3.8-Flash-Next NVFP4 on a single DGX Spark (TP=1, 262k, MTP=3) scored 137/157 on smf-bench Official A, thinking off. Coding 30/30. Dual-Spark DSV4 Vision-Exp on the same harness scored 117/157. DSV4 is drained; this serve occupies spark-d369.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
DeepSeek V4 Flash Vision-Exp was the dual-Spark occupant on :8888. We drained it, put MiniMax H3 on spark-56bc, and served Qwen3.8-Flash-Next NVFP4 on spark-d369 alone. Then we ran the same 157-test Official A suite we used on DSV4 (117/157, 74.5%).
Qwen on one GB10 scored 137/157 (87.3%), thinking off, zero errors. Coding was 30/30. Decode is still slower than the DSV4 TP=2 pin. Quality is not.
This is not the August dual-Spark SGLang migration post. That used a 25-task matrix. This is smf-bench Official A.
The question
Can one Spark, TP=1, beat the dual-Spark DSV4 Official A score without borrowing the second GB10?
The stack
| Field | Value |
|---|---|
| Hardware | 1× NVIDIA DGX Spark (GB10), spark-d369 |
| Checkpoint | Mia-AiLab/Qwen3.8-Flash-Next-NVFP4 @ 925d7be6c14c6c9442ef83e8f05b5a3c39304f69 |
| License | Apache-2.0 |
| Disk | ~99 GiB hub snapshot (download.sh); HF usedStorage 105.9 GB |
| Recipe | MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark |
| Image | vllm/vllm-openai:qwen38-flash-next |
| Shape | TP=1 · max_model_len=262144 · YaRN off · MTP=3 · FP8 KV · KV_TARGET_GIB=16 · GMU 0.780 |
| KV | 954,407 tokens (3.64× a 262k request) |
| Idle MemAvailable | 18.0 GiB after load (swap 183 MiB) |
| Harness | smf-bench Official A strict_v01, 157 tests, timeout 300s, --thinking off |
| Tag | cal-qwen38-flash-next-tp1-262k-d369-strict-v01 |
| Serve recipe id | SMF-Spark-d369-Qwen38FN-TP1-262k-mtp3-fp8kv-gmu0780-kv16 |
Thinking is on by default in the chat template. Official A sends chat_template_kwargs.enable_thinking: false per request.
Occupancy
| Node | Before | After |
|---|---|---|
| spark-56bc + spark-d369 | DSV4 Vision-Exp TP=2 on :8888 |
DSV4 drained |
| spark-56bc | (pair worker / later H3) | MiniMax H3 FL2VA on :8000 |
| spark-d369 | (pair worker) | Qwen Flash-Next TP=1 on :8888 |
One GB10 is enough for this checkpoint if host swap is empty. The first two boots after a dirty 8 GiB swap died with NV_ERR_NO_MEMORY and the recipe watchdog (MemFree under 2 GiB for 5 samples). A reboot zeroed swap (15 GiB free). The 262k recipe then came up in 12 minutes.
.env on this kit ships KV_TARGET_GIB=16, not 22. MiaAI documented 22 GiB KV as the setting that parked idle MemAvailable on the watchdog floor.
Official A — thinking off
Wall 3274.7 s (54.6 min). 0 errors. 0 timeouts.
| Category | Qwen 262k MTP=3 | Qwen 16k MTP=0 | GLM-5.3 IQ2 GGUF | DSV4 Vision-Exp TP=2 |
|---|---|---|---|---|
| math | 19/30 (63.3%) | 18/30 | 12/30 | 13/30 |
| coding | 30/30 (100%) | 27/30 | 25/30 | 22/30 |
| reasoning | 26/30 (86.7%) | 26/30 | 23/30 | 24/30 |
| instruction | 27/30 (90.0%) | 26/30 | 27/30 | 26/30 |
| prose | 29/30 (96.7%) | 30/30 | 28/30 | 27/30 |
| writing | 4/5 (80.0%) | 4/5 | 4/5 | 3/5 |
| tool_calling | 2/2 | 2/2 | 2/2 | 2/2 |
| TOTAL | 137/157 (87.3%) | 133/157 (84.7%) | 121/157 (77.1%) | 117/157 (74.5%) |
| Wall | 54.6 min | 93.1 min | 118.7 min | 25.4 min |
| Coding SyntaxError | 0 | 0 | 3 | 5 |
The 16k row is the same checkpoint on the same box, after the OOM boots, with MTP off and max_model_len=16384. Quality moved 4 points when we restored 262k and MTP=3. Coding went 27/30 to 30/30. The three 16k coding fails were assertion misses, not SyntaxError.
GLM IQ2 is Unsloth UD-IQ2_XXS on llama.cpp glm5next/upstream b1-629b505, ctx 16384, same Official A day. It is a GGUF probe, not a fleet candidate next to this vLLM serve.
DSV4 numbers are the published 2026-09-02 Official A cal (cal-dsv4-vision-exp-f5463e7-strict-v01), not a re-run today.
Against the cloud showdowns
Same profile, thinking off:
| Model | Official A | Where |
|---|---|---|
| Grok 4.6 | 97.5% | OpenRouter |
| Grok 4.5 | 96.8% | OpenRouter |
| Kimi K3 | 89.2% | OpenRouter |
| Qwen3.8-Flash-Next TP=1 | 87.3% | spark-d369 |
| Qwen3.8-Max | 79.6% | OpenRouter |
| GLM-5.2 | 77.1% | Ollama Cloud |
| DSV4 Vision-Exp TP=2 | 74.5% | 2× Spark |
| GLM-5.3 EXL3 TP=2 | 65.6% | 2× Spark (2026-08-31) |
Local Qwen sits under Kimi and above Qwen3.8-Max and GLM-5.2. It is still a local serve with a 262k window and no API bill.
Throughput
Same cells as the DSV4 pin (thinking off, cache-bust, completion_tokens via stream_options.include_usage). Qwen 262k MTP=3:
| Cell | Qwen 262k MTP=3 | Qwen 16k MTP=0 | GLM IQ2 | DSV4 TP=2 pin |
|---|---|---|---|---|
| 256 × c=1 | 31.1 tok/s mean (29.6 / 31.8 / 32.0), TTFT 0.28–0.39 s | 24.6 tok/s, TTFT 0.25–0.29 s | 18.3 tok/s, TTFT 0.75–0.88 s | 68.5 tok/s |
| 256 × c=6 | 70.1 agg tok/s | 55.9 | 32.7 | 171 |
| ~8–14k × c=1 | salted cold 14334 tok, TTFT 6.82 s, 2103 tok/s | 12034 tok, 5.38 s, 2236 tok/s | 7953 tok, 21.6 s, 368 tok/s | TTFT 4.56 s, 1800 tok/s |
DSV4 remains the faster engine. Qwen on one Spark is about half the single-stream decode of that pin, and about 40% of the c=6 aggregate. For agent turns of a few hundred tokens, 31 tok/s is usable. For bulk generation, DSV4 TP=2 still wins on speed.
The script's ASCII "8k" filler tokenized to 45k on this model. Use the salted cold row, not the cached 45k second shot.
What we gave up
- Dual-Spark 1M DSV4 decode (68.5 / 171 tok/s).
- Native DeepSeek
image_urlon the text occupant. Qwen's vision tower is in the checkpoint; this Official A run was text-only. - MTP=3 costs ~1.5 GiB versus the 16k MTP=0 fallback. After reboot that cost fits.
What we kept
- One node for video (H3 on 56bc) and one node for text (Qwen on d369).
- Tools 2/2 on Official A.
- A coding floor DSV4 did not hit: 30/30, zero SyntaxError.
Recommendations
- Treat 137/157 thinking-off as the ranking number. Do not mix a thinking-on math arm into Official A.
- Do not launch this recipe on a Spark with >5 GiB swap in use. Reboot first.
- Keep
KV_TARGET_GIB=16on 128 GB UMA. 22 GiB KV is how this host previously sat on the watchdog floor. - Send
enable_thinking: falseon tool and coding traffic. Leave thinking on for math evals only. - Do not report DSV4 68.5 tok/s and Qwen 87.3% as if they were the same runtime.
Reproducing this
git clone https://github.com/MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark
cd Qwen3.8-Flash-Next-Single-DGX-Spark
cp .env.sample .env
./download.sh    # Mia-AiLab/Qwen3.8-Flash-Next-NVFP4
./start.sh       # 262k, MTP=3, FP8 KV

cd /path/to/smf-bench
export SMF_SERVE_RECIPE_ID=SMF-Spark-d369-Qwen38FN-TP1-262k-mtp3-fp8kv-gmu0780-kv16
python3 -u run_stage1.py \
  --endpoint http://127.0.0.1:8888/v1 \
  --model qwen3.8-flash-next \
  --tag cal-qwen38-flash-next-tp1-262k-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300
JSON and the throughput script: Nemo Knowledge Base.
Verification notes
- Official A totals and per-suite counts:
stage1_cal-qwen38-flash-next-tp1-262k-d369-strict-v01_20260905_124310.jsonand the 16k / GLM files in the same directory. - DSV4 117/157:
stage1_cal-dsv4-vision-exp-f5463e7-strict-v01_20260902_151647.json(published 2026-09-02). - Checkpoint id, license, revision,
usedStorage: Hugging Face APIMia-AiLab/Qwen3.8-Flash-Next-NVFP4on 2026-09-05. - Throughput:
throughput-qwen38-flash-next-262k-d369.json. DSV4 68.5 / 171 / 4.56 s is the published Vision-Exp pin, not remeasured this day. - Cloud Official A percents are prior published smf-bench runs, not this session.
Measured 2026-09-05 on spark-d369. DSV4 remains drained.