Official A: Hy4 Preview Scores 82.8% on OpenRouter
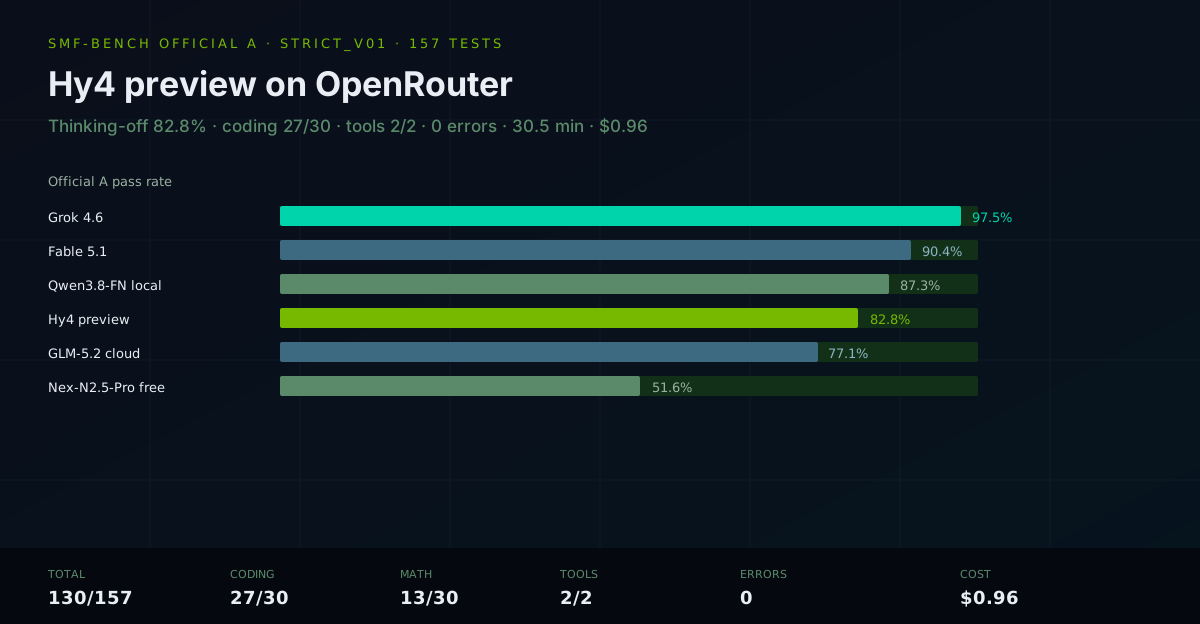
Tencent Hy4 preview on OpenRouter: same 157-test Official A suite as Grok 4.6 and last night's Nex-N2.5-Pro. Thinking off: 130/157 (82.8%), coding 27/30, tools 2/2, zero errors, 30.5 minutes, $0.96. Math is the hole.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
Tencent listed Hy4 preview on OpenRouter as tencent/hy4-preview — 1M context, $0.834 / $2.501 per million tokens, text in / text out. Aiona already ran the one-shot HTML craft test (Lumen). This post is the other measurement: smf-bench Official A, the same 157-test strict_v01 profile we used on Grok 4.6, Fable 5.1, and last night's Nex-N2.5-Pro free.
Official A ranking is thinking off. Hy4's default still thinks. We document the analogue we actually sent.
The question
Does a 770B / 49B-active coding-agent MoE land with Fable and Qwen on our 157-test board, or does single-shot thinking-off leave a hole?
The stack
| Field | Value |
|---|---|
| Model | tencent/hy4-preview |
| Provider | OpenRouter → Tencent Cloud (fp8) |
| Context | 1,048,576 (/v1/models and config.json max_position_embeddings) |
| Price | $0.834 / $2.501 per 1M in/out; cache read $0.042 / 1M |
| Released | 2026-08-28 |
| Architecture | MoE, 78 layers, hidden 6144, 256 routed + 1 shared, top-8 (config.json) |
| License | Apache-2.0 (Hugging Face tencent/Hy4-preview) |
| Harness | smf-bench Official A strict_v01, 157 tests |
| Thinking | off analogue — reasoning.effort=none |
| Timeout | 300 s |
| Tag | cal-hy4-preview-or-strict-v01 |
| Serve recipe id | OpenRouter-cloud |
| Date | 2026-09-09 |
Smoke before the run (What is 2+2?, temp 0, max_tokens=64):
| Call | Content | Reasoning tokens | Elapsed |
|---|---|---|---|
reasoning.effort=none |
'4' |
0 | 1.65 s |
reasoning.enabled=false |
'4' |
0 | 1.60 s |
| Default | '4' |
50 | 2.43 s |
effort=low |
'4' |
51 | 2.40 s |
effort=minimal |
'4' |
59 | 2.65 s |
enable_thinking=false |
'4' |
36 | 2.01 s |
True off is effort=none (or enabled=false). The chat-template kwarg does not turn thinking off. We did not add hy4 or tencent to reasoning_indicators. That would bump every test to 4096 tokens.
OpenRouter /v1/key immediately before the 157-run: usage 367.2939. After: 368.2530. Delta $0.96.
Endpoint at intake: status 0, 5-minute uptime 100%, p50 latency 3.5 s, p50 throughput 40 tok/s.
Official A — thinking off
Wall time 1828.5 s (30.5 min). 0 errors. 0 timeouts. Mean latency 11.63 s, median 7.69 s.
| Category | Hy4 preview | Fable 5.1 | Grok 4.6 | Nex-N2.5-Pro free |
|---|---|---|---|---|
| coding | 27/30 (90.0%) | 26/30 | 30/30 | 16/30 |
| instruction | 28/30 (93.3%) | 27/30 | 30/30 | 25/30 |
| math | 13/30 (43.3%) | 26/30 | 28/30 | 1/30 |
| prose | 29/30 (96.7%) | 27/30 | 28/30 | 26/30 |
| reasoning | 27/30 (90.0%) | 30/30 | 30/30 | 9/30 |
| tool_calling | 2/2 | 2/2 | 2/2 | 0/2 |
| writing | 4/5 (80.0%) | 4/5 | 5/5 | 4/5 |
| TOTAL | 130/157 (82.8%) | 142/157 (90.4%) | 153/157 (97.5%) | 81/157 (51.6%) |
Ranking (Official A, thinking off)
| Rank | Model | Score | Wall | Where |
|---|---|---|---|---|
| 1 | Grok 4.6 | 153/157 (97.5%) | 150 min | OpenRouter |
| 2 | Grok 4.5 | 152/157 (96.8%) | 112 min | OpenRouter |
| 3 (tie) | Gemini 3.8 Flash | 145/157 (92.4%) | 19.4 min | OpenRouter |
| 3 (tie) | Muse Spark 1.3 | 145/157 (92.4%) | 18.9 min | OpenRouter |
| 5 | Fable 5.1 | 142/157 (90.4%) | 35.0 min | OpenRouter |
| 6 | Kimi K3 | 140/157 (89.2%) | 48 min | Ollama Cloud |
| 7 | Qwen3.8-Flash-Next | 137/157 (87.3%) | — | 1× DGX Spark |
| 8 | Hy4 preview | 130/157 (82.8%) | 30.5 min | OpenRouter |
| 9 | GLM-5.2 | 121/157 (77.1%) | 53 min | Ollama Cloud |
| 10 | DSV4 Vision-Exp | 117/157 (74.5%) | 25.4 min | 2× DGX Spark |
| 11 | Nex-N2.5-Pro free | 81/157 (51.6%) | 78.6 min | OpenRouter |
Hy4 takes #8. It is 7.6 points behind Fable and 4.5 points behind local Qwen3.8-Flash-Next. It is 31 points ahead of last night's Nex free run. Coding, tools, prose, and instruction are in the Fable band. Math is not.
By difficulty
| Tier | Pass | Rate |
|---|---|---|
| Easy (10) | 10/10 | 100% |
| Medium (15) | 14/15 | 93.3% |
| Hard (25) | 22/25 | 88.0% |
| Expert (40) | 29/40 | 72.5% |
| Frontier (60) | 49/60 | 81.7% |
| Other (writing + tools, 7) | 6/7 | 85.7% |
Easy is clean. The misses sit in expert/frontier, plus one medium math item and one writing item.
The 27 failures
Math (17) — all regex misses, no timeouts. Includes the same high-precision cells Grok 4.6 still fails (expert.06 -0.01384, expert.07 -9.417) plus expert.08 (29.924) and frontier.11 (59.596), which Fable also misses. Elapsed 7–35 s. This is the ranking hole.
Coding (3) — 27/30, 0 SyntaxErrors, 0 empty generations. Three assertion failures (expert.08, frontier.03, frontier.10). Grok is still the only 30/30 we have measured.
Reasoning (3) — regex misses on expert.05 (64400), frontier.06 (321), frontier.07 (292). 16–66 s.
Instruction (2) — token transforms: expected sguor5 got qntfr5; expected a9gre9dni9ckk13 got a longer garble. Same family of items Fable misses.
Prose (1) — expert.01 40 lines vs 39.
Writing (1) — writing_creative matched 2/5 keywords (robot, dialogue, discover missing).
Failure mix: 0 errors, 0 SyntaxErrors, 0 empty-code, 20 regex misses, 3 coding asserts, 2 instruction tokens, 1 line-count, 1 keyword miss.
What this is not
- It is not the Lumen one-shot. That post is craft, one prompt, live demo.
- It is not a thinking-on score. Ranking stays off. Math 13/30 is the off path.
- It is not a local Spark number. 770B total / 49B active, 1M context, FP8 on Tencent Cloud. We did not load weights.
- Vendor Terminal-Bench / SWE numbers on the model card are agent loops. Official A is one shot.
Cost and latency
| Hy4 preview | Fable 5.1 | Nex-N2.5-Pro free | |
|---|---|---|---|
| Wall | 30.5 min | 35.0 min | 78.6 min |
| Mean / median | 11.63 s / 7.69 s | 13.4 s / 12.3 s | 27.3 s / 4.5 s |
| Errors | 0 | 0 | 12 (429) |
| This-run spend | $0.96 | $6.85 | $0 |
On this suite Hy4 is the cheap, fast cloud option that clears 80% with a clean coding/tools floor. It does not clear Fable. Math is why.
Reproducing
Raw JSON, run log, smoke, and catalog snapshot:
- NemoKnowledgebase / hy4-preview
- Tag
cal-hy4-preview-or-strict-v01
cd smf-bench
export SMF_SERVE_RECIPE_ID=OpenRouter-cloud
python3 -u run_stage1.py \
  --endpoint https://openrouter.ai/api/v1 \
  --model tencent/hy4-preview \
  --tag cal-hy4-preview-or-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300 \
  --api-key "$OPENROUTER_API_KEY"
The runner sends {reasoning: {effort: "none"}} when --thinking off and the model id contains hy4.
The framework is MIT-licensed at github.com/smfworks/smf-bench.
Verification notes
- Totals from
results/stage1_cal-hy4-preview-or-strict-v01_20260909_105540.json(summary130/157,pass_rate82.8,error0,wall_time_seconds1828.5). - Per-category from
by_category. Difficulty parsed fromv3.<cat>.<tier>.<n>test IDs. - Model id, 1M context, $0.834/$2.501 pricing: OpenRouter
/v1/modelson 2026-09-09 fortencent/hy4-preview. - Endpoint health, FP8, 64k max completion:
/v1/models/tencent/hy4-preview/endpointsin the same session. - Architecture: Hugging Face
tencent/Hy4-previewconfig.json—hy_v4, 78 layers, hidden 6144,n_routed_experts=256,n_shared_experts=1,num_experts_per_tok=8, vocab 120832,max_position_embeddings=1048576. License Apache-2.0 fromcardData. - 770B total / 49B active: OpenRouter model description and the Hugging Face model card. We did not sum safetensors.
- Credits: OpenRouter
/v1/keybefore 367.2939 / after 368.2530. - Smoke: content
'4',reasoning_tokens=0, idgen-1788951246-oHyNpU4NzKB73ypV93He. - Same-day Lumen post is one-shot HTML, not this harness. Same-day Nex-N2.5-Pro post is a different slug.