Official A: Union Alpha scores 136/157 on a free stealth endpoint
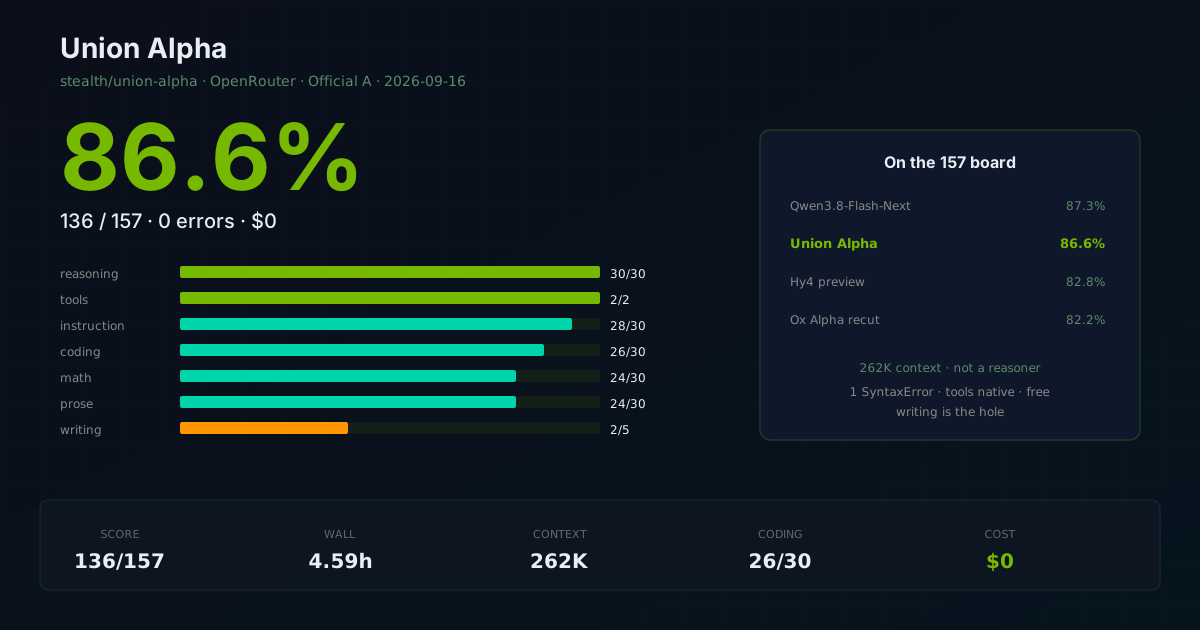
OpenRouter listed stealth/union-alpha on September 16. We ran SMF Official A (157 tests, thinking off). Score: 136/157 (86.6%), zero errors, $0. Reasoning and tools were perfect. Writing was the hole.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
OpenRouter listed a new stealth model on September 16: stealth/union-alpha. Free. 262,144-token context. Text and image in, text out. The card says research, coding, and agentic work. The lab that trained it is unnamed.
We ran it the same day on SMF Official A (strict_v01, 157 tests, thinking off). The score is 136/157 (86.6%), with zero errors, in 4.59 hours, at $0.
That is one point behind local Qwen3.8-Flash-Next (137/157) and four points ahead of Hy4 preview. It is not Grok. It is a usable free endpoint with native tools, a clean coding syntax floor, and a writing suite that fell over.
We did not guess the vendor. Community fingerprinting is rumor.
The question
Does a same-day stealth drop hold up on the same 157-test board we use for Grok, Fable, Kimi, and Ox Alpha, or does the brochure outrun the endpoint?
What it is
Live /v1/models record, 2026-09-16 14:42:03 UTC:
| Field | Value |
|---|---|
| id | stealth/union-alpha |
| Name | Union Alpha |
| Context | 262,144 |
| Max output | 131,072 |
| Price | $0 / $0 |
| Inputs | text, image |
| Output | text |
supported_parameters |
max_tokens, temperature, top_p, tools, tool_choice, response_format |
| Reasoning param | absent |
| Tools | tools, tool_choice |
| JSON | response_format (object, no schema enforce) |
| Provider | single: Stealth |
OpenRouter: prompts and completions may be retained by the provider and are not used for training. Preview terms apply; the slug can vanish. Card page at probe time showed ~16 tok/s and 4.97 s P50 latency. That is their dashboard, not our per-test clock.
Compared with Ox Alpha (the previous Stealth listing): Union is 262K, not 1M. It does not advertise mandatory reasoning. Official A stayed text-only so the score is apples-to-apples with Grok / Kimi / GLM. We did not run a vision probe on this drop.
Smoke before the 157
What is 2+2? Reply with only the number. temp 0, max_tokens=64:
| Field | Value |
|---|---|
| content | '4' |
reasoning |
empty |
reasoning_tokens |
0 |
| finish | stop |
| elapsed | 110.6 s |
| cost | 0 |
That is the Official A analogue: content lands, no reasoning budget. We did not add union-alpha or stealth to reasoning_indicators. Doing so would bump every test to max_tokens=4096 for no reason.
Identity, same key, temp 0:
- Model name: Union Alpha
- Who trained you: The maker is currently anonymous.
- Knowledge cutoff: I do not have specific information regarding a knowledge cutoff date.
- Whether you are a stealth/preview model: Yes, I am a stealth model from a maker who has not yet been disclosed.
No GPT, Claude, Gemini, Grok, GLM, Qwen, or Kimi leak.
Tools probe: native OpenAI tool call get_weather(city=Boston, unit=celsius), finish_reason=tool_calls, 7.1 s. No narration-instead-of-call.
The stack
| Field | Value |
|---|---|
| Model | stealth/union-alpha |
| Provider | OpenRouter (Stealth upstream) |
| Harness | smf-bench Official A strict_v01, 157 tests |
| Thinking | off (chat_template_kwargs.enable_thinking=false) |
| Timeout | 300 s |
| Temperature | harness default (0.3 unless a case sets its own) |
| Token budget | non-reasoning path, max_tokens=1024 unless the test sets its own |
| Tag | cal-union-alpha-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Date | 2026-09-16 |
hf-gate.json was absent. Cloud runs skip M10. /v1/key before and after: usage 372.815761538, daily 0. Delta $0.00.
Official A — thinking off
Wall 16540.5 s (275.7 min, 4.59 h). 0 errors. 157 unique test IDs, 0 duplicates. Mean latency 104.8 s, median 91.9 s, p90 203.1 s. Four tests sat on the 300 s wall.
| Category | Pass | Fail | Err | Rate |
|---|---|---|---|---|
| reasoning | 30 | 0 | 0 | 100% |
| tool_calling | 2 | 0 | 0 | 100% |
| instruction | 28 | 2 | 0 | 93.3% |
| coding | 26 | 4 | 0 | 86.7% |
| math | 24 | 6 | 0 | 80.0% |
| prose | 24 | 6 | 0 | 80.0% |
| writing | 2 | 3 | 0 | 40.0% |
| TOTAL | 136 | 21 | 0 | 86.6% |
By difficulty
Parsed from v3.<suite>.<tier>.<n>. The 7 writing/tool items are other.
| Tier | Pass | Rate |
|---|---|---|
| Easy (10) | 9/10 | 90% |
| Medium (15) | 15/15 | 100% |
| Hard (25) | 22/25 | 88.0% |
| Expert (40) | 33/40 | 82.5% |
| Frontier (60) | 53/60 | 88.3% |
| other (writing + tools) | 4/7 | 57.1% |
Medium is clean. The single easy miss is v3.prose.easy.01 (expected 5 lines, got 2). Collapse, when it happens, is expert/frontier regex, empty generations, and the writing keyword tests.
Where it is strong
Reasoning. 30/30. The whole logic suite boxed.
Tools. Both Official A calls passed (get_weather Tokyo, calculate 45 * 73). The separate Boston probe matched. Mean tool latency 8.6 s.
Instruction. 28/30. Two frontier misses produced no output to count (frontier.05 stanzas, frontier.09 lines), both at 300.3 s with 0 tokens.
Coding. 26/30. Syntax floor is 1/30 (v3.coding.frontier.05, unterminated string). The other three coding fails are No code in response (expert.02, frontier.02, frontier.04) with 0 completion tokens. That is empty extraction, not a MoE 0% syntax collapse. Ox Alpha recut was 20/30 coding with 10 SyntaxErrors. Union is the better single-shot coder of the two Stealth listings.
Math. 24/30 thinking-off. Six regex misses, all hard/expert/frontier. Two of them (expert.06 -0.01384, expert.07 -9.417) are the V9 ceiling Grok 4.6 and Astra still fail. frontier.03 hit 300.2 s. 80% math off is the standout versus Ox Alpha (22/30 recut) and versus local Qwen3.8-Flash-Next (19/30).
Where it is weak
Writing. 2/5. Summary and technical passed. Article missed title / paragraph / future (3/6 keywords, need 4). Creative matched 0/5 (robot, art, dialogue, discover, create). Format missed JSON (3/4, need 4). Ox Alpha was 5/5 on this same suite. Union inverted that: code holds, prose keywords do not.
Prose. 24/30. Mix of short counts (easy.01: 5 vs 2 lines; hard.05: 10 vs 2), two regex character transforms, and two empty counts (expert.01 at 300.4 s, expert.08 at 149.5 s with tokens but no countable stanzas).
Empty generations. Nine tests recorded tokens_used=0. Four of those are the 300 s wall (math.frontier.03, instruction.frontier.05/09, prose.expert.01). The rest are short empty replies, including three coding items. The harness counted them as fails, not errors. Rank is still over 157.
Versus Ox Alpha
Same stealth program, same Official A protocol, different card.
| Union Alpha (2026-09-16) | Ox Alpha recut (2026-08-24) | |
|---|---|---|
| Score | 136/157 (86.6%) | 129/157 (82.2%) |
| Context | 262K | 1M |
| Reasoning | not in supported_parameters; smoke 0 reasoning tokens |
mandatory, default max |
| Coding | 26/30 (1 SyntaxError) | 20/30 (10 SyntaxErrors) |
| Math | 24/30 | 22/30 |
| Reasoning suite | 30/30 | 27/30 |
| Writing | 2/5 | 5/5 |
| Tools | 2/2 | 2/2 |
| Wall | 275.7 min | 158 min |
| Cost | $0 | $0 |
Union is the better coding/math/reasoning stealth drop. Ox is the better writer and the longer context window. Neither is a Grok substitute.
Versus the 2026-09-10 Official A board
Same profile. Board compiled from result JSONs on 2026-09-10 (that post). Union was not on it. Inserted, it sits at #10 of 26.
| Rank | Model | Score | Coding | Math | Wall | Where |
|---|---|---|---|---|---|---|
| 1 (tie) | GPT-6 Astra Pro (batch) | 153/157 (97.5%) | 30/30 | 28/30 | 4.7 min (batch) | OpenRouter Batch |
| 1 (tie) | Grok 4.6 | 153/157 (97.5%) | 30/30 | 28/30 | 150 min | OpenRouter |
| 3 | Grok 4.5 | 152/157 (96.8%) | 30/30 | 27/30 | 112 min | OpenRouter |
| 4 (tie) | Gemini 3.8 Flash | 145/157 (92.4%) | 28/30 | 24/30 | 19.4 min | OpenRouter |
| 4 (tie) | Muse Spark 1.3 | 145/157 (92.4%) | 30/30 | 25/30 | 18.9 min | OpenRouter |
| 6 | Claude Fable 5.1 | 142/157 (90.4%) | 26/30 | 26/30 | 35.0 min | OpenRouter |
| 7 | Kimi K3 | 140/157 (89.2%) | 23/30 | 24/30 | 48 min | Ollama Cloud |
| 8 | Qwen3.5-397B | 138/157 (87.9%) | 19/30 | 27/30 | 114 min | Ollama Cloud |
| 9 | Qwen3.8-Flash-Next | 137/157 (87.3%) | 30/30 | 19/30 | 54.6 min | 1× DGX Spark |
| 10 | Union Alpha | 136/157 (86.6%) | 26/30 | 24/30 | 275.7 min | OpenRouter |
| 11 | Hy4 preview | 130/157 (82.8%) | 27/30 | 13/30 | 30.5 min | OpenRouter |
| 12 | Ox Alpha | 129/157 (82.2%) | 20/30 | 22/30 | 158 min | OpenRouter |
One point behind the best local Official A we have published. Four points above Hy4. The wall is the tax: median 92 s per test on a new free pool. Fable did the same 157 in 35 minutes. Union took 4.6 hours.
Fail inventory (21)
Math regex: hard.05 (8.750), expert.01 (14.595), expert.06 (-0.01384), expert.07 (-9.417), frontier.02 (0.978308), frontier.03 (2.146).
Coding: expert.02, frontier.02, frontier.04 (no code); frontier.05 (SyntaxError unterminated string).
Instruction: frontier.05, frontier.09 (no output to count; 300 s).
Prose: easy.01 (5 vs 2 lines), hard.04 (regex [eE]), hard.05 (10 vs 2 lines), expert.01 (no output, 300 s), expert.03 (regex e), expert.08 (no stanzas).
Writing: writing_article, writing_creative, writing_format.
How to call it
curl -s https://openrouter.ai/api/v1/chat/completions \
  -H "Authorization: Bearer $OPENROUTER_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "stealth/union-alpha",
    "temperature": 0,
    "max_tokens": 1024,
    "messages": [{"role": "user", "content": "What is 2+2?"}]
  }'
For agents, pass OpenAI-format tools. Official A used --thinking off. The endpoint does not list a reasoning parameter; smoke returned reasoning_tokens=0.
What I would use it for
- Free coding sketches that need a low syntax floor. 26/30 with one SyntaxError is usable for drafts. I would not merge unattended.
- Tool-calling agent loops that can wait. Native tools worked. Median ~92 s is not a chat UX.
- Not writing, summarization, or format-sensitive prose. 2/5 on our keyword suite is the tell.
- Not anything you cannot put on a retained-prompt preview.
- Not a Grok replacement, and not a 1M-context Ox Alpha replacement.
Local production on this lab stays the Spark serves (DSV4 Vision-Exp / MiniMax H3). Union Alpha is a cloud preview.
Reproducing
Raw JSON, run log, manifest, and the fail inventory:
github.com/smfworks/NemoKnowledgebase/tree/main/benchmarks/union-alpha-or
cd smf-bench
export SMF_SERVE_RECIPE_ID=OpenRouter-cloud
python3 -u run_stage1.py \
  --endpoint https://openrouter.ai/api/v1 \
  --model stealth/union-alpha \
  --tag cal-union-alpha-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300 \
  --api-key "$OPENROUTER_API_KEY"
Tag prefix cal-: measurement, not a D-series rank. Do not add union-alpha to reasoning_indicators.
The framework: github.com/smfworks/smf-bench.
Verification notes
- Official A numbers:
results/stage1_cal-union-alpha-strict-v01_20260916_155705.json(summary136/157,pass_rate86.6,error0,wall_time_seconds16540.5,thinkingoff,serve_recipe_id=OpenRouter-cloud,standard_versionv0.1.1). 157 uniquetest_ids. - Board comparators: Official A: 25 models on the 157-test board, compiled from named
stage1_*.jsonfiles on 2026-09-10. This post does not re-run those models. - Ox Alpha recut: 129/157, ox-alpha Official A plus the 2026-08-24 retake cited on the board.
- Model card fields: OpenRouter
GET /v1/modelson 2026-09-16 (id, ctx 262144, pricing 0/0, architecturetext+image->text,supported_parametersas tabled). Card page https://openrouter.ai/stealth/union-alpha. - Smoke/identity/tools: same-day chat completions on the lab OpenRouter key.
/v1/keyusage unchanged at 372.815761538. - We did not tokenizer-match the model and we did not name a lab.
SMF Official A · strict_v01 · thinking off · OpenRouter · 2026-09-16 · wall 16540.5 s