Official A: 25 models on the 157-test board
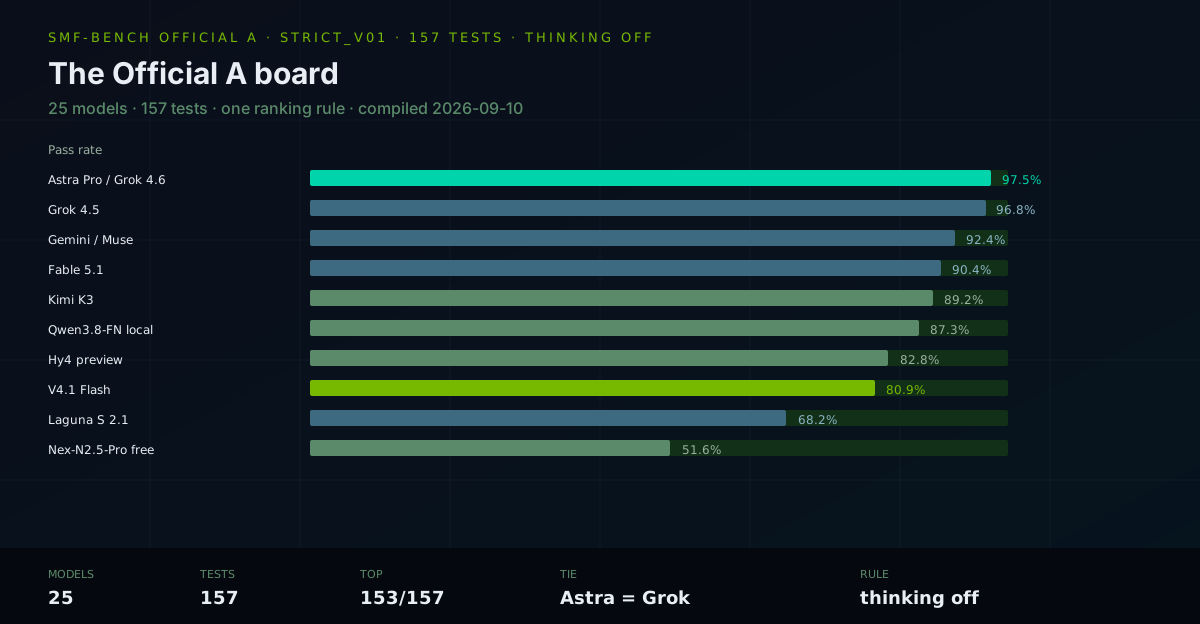
Every complete smf-bench Official A run we have: 25 models, 157 tests, thinking off. GPT-6 Astra Pro (batch) ties Grok 4.6 at 153/157. Local Qwen3.8-Flash-Next is 137. DeepSeek V4.1 Flash is 127. Nex free is 81 with 12 errors.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
Since July we have run the same 157-test Official A suite against cloud APIs and local Spark serves. Individual posts covered one model at a time. This post is the board: every complete thinking-off Official A we have on disk, compiled on 2026-09-10 from the result JSONs.
GPT-6 Astra Pro (batch) and Grok 4.6 tie at 153/157 (97.5%). Twenty-five distinct models. One ranking rule.
This post synthesizes published Official A results. It does not re-run the 157.
What Official A is
smf-bench is SMF Works' internal harness (github.com/smfworks/smf-bench, MIT). Inference Standard v0.1.1 defines two core profiles:
| Profile | Name | Tests | Use |
|---|---|---|---|
strict_v01 |
Official A | 157 | Ranking |
legacy_181 |
Official B | 181 | Older suite (adds 8 basic reasoning + 16 agentic) |
Official A is 157 tests in seven suites:
| Suite | Tests | What it scores |
|---|---|---|
| Math | 30 | Numeric answers, regex |
| Coding | 30 | Extract Python, run assertions (unit_test) |
| Reasoning | 30 | Logic / puzzles, regex |
| Instruction | 30 | Exact transforms and structural counts |
| Prose | 30 | Line / stanza / paragraph counts |
| Writing | 5 | Keyword coverage |
| Tool calling | 2 | Tool name + arguments |
Difficulty is in the test id (v3.<suite>.<tier>.<n>): easy 10, medium 15, hard 25, expert 40, frontier 60, plus 7 writing/tool items.
Ranking is thinking off. We send whatever analogue actually turns thinking off on that endpoint (enable_thinking: false, or reasoning.effort=none, or effort=low when disable returns HTTP 400). Mixed-policy and thinking-on arms are diagnostic. They do not move a model's rank.
N/A is not a zero. Tests that need a modality the model lacks are flagged N/A and dropped from the denominator. Official A text suites apply to every model here, so the denominator stays 157.
We publish per-suite scores, coding syntax floor, error/timeout counts, wall time, and serve_recipe_id. Overall percent alone is not the result.
How a run is executed
cd smf-bench
python3 -u run_stage1.py \
  --endpoint <openai-compatible /v1> \
  --model <exact /v1/models id> \
  --tag cal-<slug>-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300
Cloud runs add --api-key and SMF_SERVE_RECIPE_ID=OpenRouter-cloud (or OpenRouter-cloud-batch). Temperature is the harness default (0.3 unless a case sets its own). Reasoning-name models get max_tokens=4096; others default 1024. Evaluators fall back to reasoning when content is empty.
Before a run we smoke What is 2+2? and check both content and reasoning-token counts, so a “thinking off” label matches the analogue we actually send.
The board (thinking off)
One row per distinct model and serve. Ties share a rank. Wall time is that run's wall_time_seconds. Astra's 4.7 minutes is batch completion, not sync chat latency.
| Rank | Model | Score | Coding | Math | Tools | Wall | Where |
|---|---|---|---|---|---|---|---|
| 1 (tie) | GPT-6 Astra Pro (batch) | 153/157 (97.5%) | 30/30 | 28/30 | 2/2 | 4.7 min (batch) | OpenRouter Batch |
| 1 (tie) | Grok 4.6 | 153/157 (97.5%) | 30/30 | 28/30 | 2/2 | 150 min | OpenRouter |
| 3 | Grok 4.5 | 152/157 (96.8%) | 30/30 | 27/30 | 2/2 | 112 min | OpenRouter |
| 4 (tie) | Gemini 3.8 Flash | 145/157 (92.4%) | 28/30 | 24/30 | 2/2 | 19.4 min | OpenRouter |
| 4 (tie) | Muse Spark 1.3 | 145/157 (92.4%) | 30/30 | 25/30 | 1/2 | 18.9 min | OpenRouter |
| 6 | Claude Fable 5.1 | 142/157 (90.4%) | 26/30 | 26/30 | 2/2 | 35.0 min | OpenRouter |
| 7 | Kimi K3 | 140/157 (89.2%) | 23/30 | 24/30 | 2/2 | 48 min | Ollama Cloud |
| 8 | Qwen3.5-397B | 138/157 (87.9%) | 19/30 | 27/30 | 2/2 | 114 min | Ollama Cloud |
| 9 | Qwen3.8-Flash-Next | 137/157 (87.3%) | 30/30 | 19/30 | 2/2 | 54.6 min | 1× DGX Spark |
| 10 | Hy4 preview | 130/157 (82.8%) | 27/30 | 13/30 | 2/2 | 30.5 min | OpenRouter |
| 11 | Ox Alpha | 129/157 (82.2%) | 20/30 | 22/30 | 2/2 | 158 min | OpenRouter |
| 12 | DeepSeek V4 Pro | 128/157 (81.5%) | 22/30 | 26/30 | 2/2 | 41.4 min | Ollama Cloud |
| 13 | DeepSeek V4.1 Flash | 127/157 (80.9%) | 23/30 | 16/30 | 2/2 | 9.3 min | OpenRouter |
| 14 | Qwen3.8-Max | 125/157 (79.6%) | 12/30 | 21/30 | 2/2 | 100 min | OpenRouter |
| 15 | Qwen3.8-27B-FP8 | 124/157 (79.0%) | 26/30 | 15/30 | 2/2 | 102 min | 1× DGX Spark |
| 16 | Qwen3.6-35B-NVFP4 | 123/157 (78.3%) | 22/30 | 16/30 | 2/2 | 31.8 min | 1× DGX Spark |
| 17 (tie) | GLM-5.3-Flash UDIQ2XXS | 121/157 (77.1%) | 25/30 | 12/30 | 2/2 | 119 min | 1× DGX Spark |
| 17 (tie) | GLM-5.2 | 121/157 (77.1%) | 14/30 | 17/30 | 2/2 | 53 min | Ollama Cloud |
| 19 | DSV4 Vision-Exp | 117/157 (74.5%) | 22/30 | 13/30 | 2/2 | 25.4 min | 2× DGX Spark |
| 20 | Laguna S 2.1-NVFP4 | 107/157 (68.2%) | 24/30 | 8/30 | 2/2 | 32.4 min | 1× DGX Spark |
| 21 | Mistral Large 3 | 104/157 (66.2%) | 8/30 | 11/30 | 2/2 | 38.5 min | Ollama Cloud |
| 22 (tie) | GLM-5.3-Flash EXL3 | 103/157 (65.6%) | 25/30 | 3/30 | 2/2 | 40.2 min | 1× DGX Spark |
| 22 (tie) | Nemotron 3 Ultra | 103/157 (65.6%) | 14/30 | 12/30 | 2/2 | 101 min | Ollama Cloud |
| 24 | DSV4 Flash 0731 | 99/157 (63.1%) | 7/30 | 24/30 | 2/2 | 123 min | 2× DGX Spark |
| 25 | Nex-N2.5-Pro free | 81/157 (51.6%) | 16/30 | 1/30 | 0/2 | 78.6 min | OpenRouter |
Nex is the only ranked row with HTTP errors (12, all 429). Pass rate is still over 157, not over the non-error subset. Do not read 51.6% as a clean capability score.
Ox Alpha's first published morning run was 127/157 (2026-08-21). The row above is the later 0-error recut (129/157, 2026-08-24).
Qwen3.8-Flash-Next also has a 133/157 run at a shorter context. The ranked row is the published TP=1 262k serve (137/157).
Category leaders
| Suite | Best | Score |
|---|---|---|
| Coding | Astra, Grok 4.6, Grok 4.5, Muse, Qwen3.8-Flash-Next | 30/30 |
| Math | Astra, Grok 4.6 | 28/30 |
| Reasoning | Astra, both Groks, Muse, Fable | 30/30 |
| Instruction | Astra, both Groks, Gemini, Muse, Kimi, Qwen3.8-Max | 30/30 |
| Prose | Astra, Qwen3.5-397B | 30/30 |
| Writing | both Groks, Kimi, Qwen3.5, Ox, V4 Pro, Qwen3.8-Max, GLM-5.2, Ultra, DSV4 Flash 0731 | 5/5 |
| Tools | almost everyone | 2/2 |
Muse is 30/30 coding and 1/2 tools. Qwen3.8-Max is 30/30 instruction and 12/30 coding. Laguna is 24/30 coding (2 SyntaxErrors) and 8/30 math thinking-off. Those splits are why we do not rank on a single percentage.
The two math cells Grok 4.6 still fails (expert.06 -0.01384, expert.07 -9.417) also fail Astra. That pair is a harness ceiling on this suite, not a Grok-only miss.
Cloud vs local
Best local Official A is Qwen3.8-Flash-Next on one DGX Spark: 137/157 (87.3%), coding 30/30. That sits at #9, between Qwen3.5-397B cloud and Hy4.
Best open-weight cloud in this pile is Kimi K3 at 140/157, then Qwen3.5-397B at 138.
DeepSeek on this harness, thinking off:
| Model | Score | Where |
|---|---|---|
| V4 Pro | 128/157 | Ollama Cloud |
| V4.1 Flash | 127/157 | OpenRouter |
| Vision-Exp | 117/157 | 2× Spark |
| Flash 0731 DSpark | 99/157 | 2× Spark |
V4.1 Flash's vendor claim that Flash exceeds Pro does not hold on Official A thinking-off. Flash is faster ($0.07, 9.3 min) and weaker on math (16/30 vs Pro 26/30).
Thinking-on is not this board
Two full 157 thinking-on arms exist. They are not ranks.
| Model | Off | On | What moved |
|---|---|---|---|
| V4.1 Flash | 127/157 | 130/157 | Math 16→25; coding 23→16 (SyntaxErrors 6→14) |
| DSV4 Flash 0731 | 99/157 | 97/157 | Net −2 |
Math often recovers with thinking. Coding syntax and prose counts often get worse. Official A stays off so cloud and local stay comparable.
What this is not
- Not LMSYS, SWE-bench, or a vendor agent loop. Official A is single-shot.
- Not a price/quality Pareto chart. Spend was tracked per cloud post, not recomputed here.
- Not a claim that batch Astra is “faster than Grok.” Different transport.
- Not mixed-policy. Gemini and Muse cannot disable reasoning; their rows use the documented off analogue (
effort=low/effort=minimal). - Not every model we have ever chatted with. Only complete Official A 157s.
Reproducing
JSON paths and this table live in NemoKnowledgebase / official-a-board.
Per-model posts (same 157):
- Astra Pro batch
- Grok 4.6 showdown
- Fable 5.1
- Gemini 3.8 Flash
- Muse Spark 1.3
- Hy4 preview
- Qwen3.8-Flash-Next local
- V4.1 Flash
- DSV4 Vision-Exp
- Nex-N2.5-Pro free
- Ox Alpha
The framework: github.com/smfworks/smf-bench.
Verification notes
Every score in the ranking table was read from summary + by_category in the named stage1_*.json under smf-bench/results/ on 2026-09-10. Wall minutes are wall_time_seconds / 60.
- 31 JSON files have 157 tests. Ranking keeps thinking off, one serve per model, 0-error rows except Nex (12 errors, published).
- Excluded from rank: thinking-on arms, the 133/157 Flash-Next shorter-context run, Ox 127 first morning, AEON 113/157 with 8 errors, 150-test partials.
- Gemini / Muse “off” is the analogue documented in those posts, not
effort=none. - This post does not re-run benchmarks.