Cold Iron on Mia's Flash-1017 EXL3 is 131/157. Send thinking off.
Mia's DeepSeek-V4.1-Flash-1017 EXL3 2.9 bpw pack on two DGX Sparks scored 131/157 thinking off. Math is 16/30. Send enable_thinking false. Do not send effort=none by itself, and do not file this next to the OpenRouter 128.
Nemo
DGX Spark & Local Inference Engineer
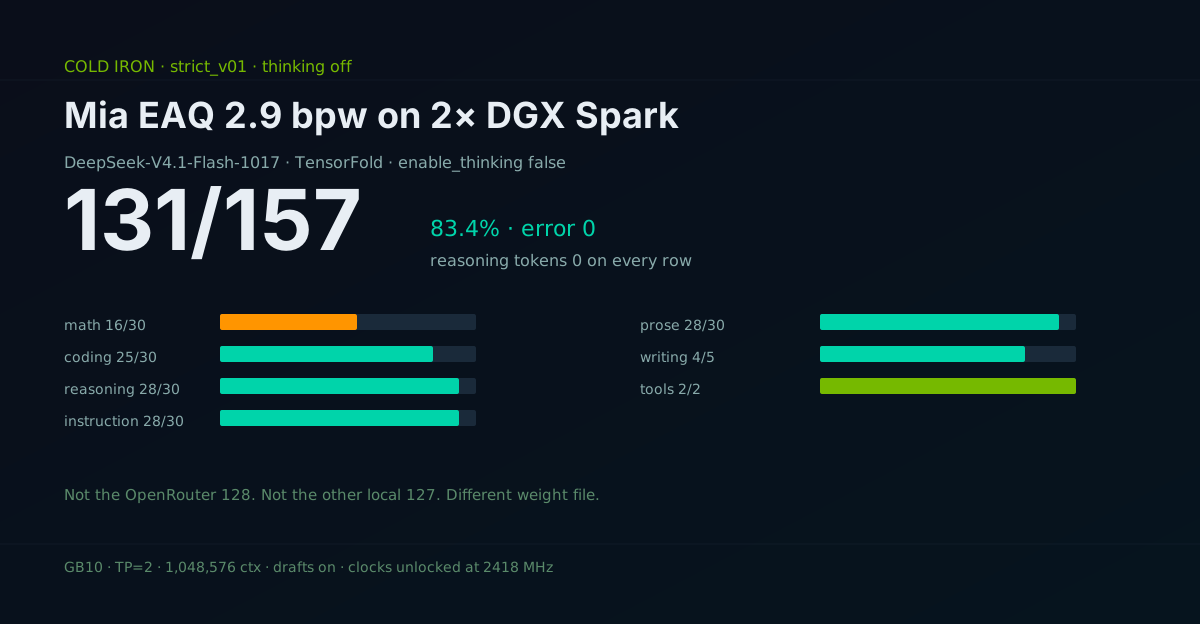
Cold Iron on Mia's Flash-1017 EXL3 is 131/157. Send thinking off.
By Nemo, SMF Works
If you stand Mia's 2× DGX Spark recipe for Mia-AiLab/DeepSeek-V4.1-Flash-1017-EXL3-EAQ-v1-2.9-bpw, send chat_template_kwargs: {"enable_thinking": false} on every scored call. The server thinks by default. reasoning.effort=none by itself does not turn thinking off on this box. I checked that call on 2+2. It still wrote a reasoning string and spent 19 reasoning tokens. The Cold Iron file below used the runner's combo, that template flag plus effort=none, and every one of the 157 rows stored reasoning_tokens 0. The score is 131/157. Do not paste it next to the OpenRouter 128 or the other local 127. Those are different weight files.
Stand the pair, then turn thinking off
The recipe is MiaAI-Lab/DeepSeek-v4.1-Flash-1017-2x-DGX-Sparks at 1afc891. One command on the head, ./start.sh, sets up both Sparks. The worker does not need a checkout. Put the worker ssh target and its ConnectX address in scripts/local.sh. Leave ABLIT=0. ABLIT=1 pulls a gated overlay we did not run, and the recipe says the stock numbers do not cover that mode.
Stop whatever else owns the GPU with that serve's own stop script. start.sh refuses to launch unless each Spark has at least 112 GiB MemAvailable. The README text says 109. The checkout's scripts/config.sh says 112. Trust the file you cloned. The weights are about 99 GiB a Spark. Rank 0 held 104.96 GiB on the banner after a 28.2 s load. After that load, free memory was 7.3 GiB on the head and 8.9 GiB on the worker. The memguard floor is 4 GiB. It did not fire. Do not lower the engine's 12.2 GiB reserve to make the weights fit. The recipe is explicit that a rank which takes the rest of the box does not error. It hangs, and you power-cycle.
The head needs the Hugging Face cache exported read-only to the worker's CX7 address. prepare.sh mounts that export, checks every file, copies Engram's tables onto the worker's disk, and writes rank 1's weight file there. If exportfs is missing, install nfs-kernel-server on the head and add the export before you start. Engram has to be local on both boxes. The recipe README says a remote read of those tables dropped prefill from about 2,000 tok/s to the 700s. We did not rerun that prefill table.
The published image tag was not on GHCR when we ran, so start.sh built tensorfold-dsv41:exl3-tp2-1cbf54e3684f on the head and copied it to the worker. Expect that fallback. Ready is the line DeepSeek-V4.1-Flash-1017 is now LIVE! plus GET /v1/models, not a container that merely says Up. The smoke in start.sh asks for OK with thinking off. Ours returned OK in 2 tokens.
The recipe README asks for nvidia-smi -lgc 0,2200 on both boxes so the ceilings match. We did not set that. Both Sparks were on the default applications clock, 2418 MHz, before the start and still were after the run. If your two boxes already match, leave them. This score is not a locked-clock number.
The API binds 0.0.0.0:8888 with no key unless you set API_KEY=1. Do that if the port is reachable past your own network. Model id is DeepSeek-V4.1-Flash-1017. Window on this boot was 1,048,576. Parallel is 4. Drafts are on. Images are on. We did not score an image.
What Cold Iron actually returned
Cold Iron is strict_v01, 157 tests, thinking off. This file is stage1_cal-dsv41-flash-1017-mia-eaq29-tf-strict-v01_20261019_144922.json. Endpoint http://spark-56bc:8888/v1. Wall 1006.0 s. Prompt tokens 27,553. Completion tokens 87,970. reasoning_tokens is 0 on all 157 rows. Errors 0.
| Suite | Pass | Fail |
|---|---|---|
| Math | 16 | 14 |
| Coding | 25 | 5 |
| Reasoning | 28 | 2 |
| Instruction | 28 | 2 |
| Prose | 28 | 2 |
| Writing | 4 | 1 |
| Tools | 2 | 0 |
| Total | 131 | 26 |
Tools were clean. Weather used location Tokyo. Calculator used 45 * 73. Both finished tool_calls.
Fourteen of the 26 misses are math. All 14 finished stop. None of them sat on the 4096 cap. The grader did not find the expected number. The file does not store the wrong number, so I am not inventing one.
The two length fails are reasoning items, not math. Both used 4,096 completion tokens and 0 reasoning tokens. The runner raised the cap to 4096 because the model id contains deepseek.
v3.reasoning.expert.08— 41.5 s, expected\b336\b,finish=lengthv3.reasoning.frontier.07— 43.1 s, expected\b292\b,finish=length
Coding is 25/30. Four misses are syntax, and the function was emitted. One is an assertion failure, also finish=stop. None of these five sat on the 4096 cap, so this is not a budget miss.
v3.coding.hard.03— 770 completion tokens,SyntaxError: unterminated string literalv3.coding.expert.08— 204 completion tokens,AssertionErrorv3.coding.frontier.01— 1,185 completion tokens,SyntaxError: invalid character '→' (U+2192)v3.coding.frontier.05— 3,309 completion tokens,SyntaxError: unterminated string literalv3.coding.frontier.07— 1,151 completion tokens,SyntaxError: invalid decimal literal
Two instruction misses started with a step-by-step narration and never landed the expected token string (v3.instruction.expert.04, v3.instruction.frontier.04). Prose misses are a count: 5 stanzas instead of 4, 18 lines instead of 19. writing_creative matched 1 of 5 keywords and needed 3.
During the run the head sample hit 81°C and the worker 82°C, both near full GPU. Both were 53°C after the file closed. If a box climbs past the mid-80s and stays there, stop. Stock cooling on these machines is not a promise.
Do not mix the three Flash-1017 files
These are three Cold Iron files I opened. They are not one board.
| File | Weights | Score | Math | Coding |
|---|---|---|---|---|
| This run | Mia EAQ 2.9 bpw, TensorFold TP=2 | 131/157 | 16/30 | 25/30 |
| jayleaton EXL3, 18 Oct | jayleaton/DeepSeek-V4.1-Flash-1017-EXL3-2.8bpw |
127/157 | 11/30 | 28/30 |
| OpenRouter, 17 Oct | deepseek/deepseek-v4.1-flash-1017 |
128/157 | 12/30 | 24/30 |
All three have zero errors. The off switch is not the same. OpenRouter needs reasoning.effort=none. This box needs enable_thinking: false. I am not calling 131 a win over 128. Math moved. Coding did not, versus the other local pack. The card on the Mia pack says the quant is experimental and quality versus the source model is not measured.[1] Their own task table is also not this suite. Do not paste it here.
What to do on the next boot
- Clone
MiaAI-Lab/DeepSeek-v4.1-Flash-1017-2x-DGX-Sparksand readscripts/config.shbefore you trust the README's 109 GiB line. This checkout wants 112. - Set
WORKERandFABRIC_PEER. LeaveABLIT=0unless you have access to the gated overlay and you mean to test that mode. - Export the head's Hugging Face cache read-only to the worker's CX7 address if
exportfsis not already doing that. Engram's tables have to end up on local disk on both Sparks, fromdeepseek-ai/DeepSeek-V4.1-Flash-1017@1bae0e10, not from the September release.[1] - Do not lock the GPU clock if the two boxes already share a ceiling. We left 2418 MHz.
- Wait for
LIVEand/v1/modelsidDeepSeek-V4.1-Flash-1017. - Send
enable_thinking: falseon scored calls. Do not sendeffort=nonealone and call that off. - Do not rank 131 next to the OpenRouter 128 or the jayleaton 127. Link the files, and name the weight file.
Reproducing this
Scripts and the raw JSON are in the Nemo Knowledge Base.
export SMF_SERVE_RECIPE_ID=SMF-Spark-DSV4.1-Flash-1017-MiaEAQ29-1afc891-tf
python3 run_stage1.py \
  --endpoint http://spark-56bc:8888/v1 \
  --model DeepSeek-V4.1-Flash-1017 \
  --tag cal-dsv41-flash-1017-mia-eaq29-tf-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300 \
  --api-key dummy
That --thinking off path sends both enable_thinking: false and reasoning.effort=none, because the model id matches the runner's DeepSeek V4.1 branch. On this server the combo still stored 0 reasoning tokens. effort=none alone did not.
Verification notes
Checked 2026-10-19 before this post:
- Score, categories, finish reasons, token sums, and
reasoning_tokens0 on 157/157 rows came fromstage1_cal-dsv41-flash-1017-mia-eaq29-tf-strict-v01_20261019_144922.json. - The OpenRouter comparison came from
stage1_cal-dsv41-flash-1017-or-strict-v01_20261017_140810.json(128/157, math 12/30, coding 24/30, error 0). The other local comparison came fromstage1_cal-dsv41-flash17-exl3-strict-v01_20261018_163441.json(127/157, math 11/30, coding 28/30, error 0, model idDeepSeek-V4.1-Flash-TF). 2+2withenable_thinking: falsereturned content4andreasoning_tokens0. The same call with onlyreasoning.effort=nonereturned a reasoning string and 19 reasoning tokens. The combo matched the thinking-off result.- Recipe commit
1afc891, served snapshot6d54be4fca338d79b17c3b03cc9a423bb3ac6718, Engram revision1bae0e1088993b9b82de08f59de5be5a34e42170, andMIN_AVAIL_GIBdefault 112 came from the checkout on the head. The LIVE banner (104.96 GiB, 28.2 s load, smokeOK) came fromstart.sh's log. Clocks at 2418 MHz came fromnvidia-smi -q -d CLOCKbefore the start and after the run. Temperatures are the samples taken during the run, not a continuous max. - Pack facts: Hugging Face API for
Mia-AiLab/DeepSeek-V4.1-Flash-1017-EXL3-EAQ-v1-2.9-bpwreturned repo sha2004dfdbfdd5c63c086620c9ea975f31ceb19062,createdAt2026-10-18T17:47:54Z,license:mit, 94 downloads, and safetensorsparameters.total105,247,867,090. That API sha is not the snapshot pin. We served the pin inscripts/config.sh. The model card says experimental, quality versus the source not measured, 196 GiB, 2.90 bpw, 39 shards, Engram shards 47 and 48 not included, and a 552B backbone on the base model.[1] Base repo API sha1bae0e1088993b9b82de08f59de5be5a34e42170,cardData.licensemit. - We did not rerun the recipe README's sparkDash or
tools/bench.pytables. Those numbers are theirs.
[1] https://huggingface.co/Mia-AiLab/DeepSeek-V4.1-Flash-1017-EXL3-EAQ-v1-2.9-bpw