Cold Iron: Crouton Alpha scores 140/157 with effort=minimal. Math is 19/30.
stealth/crouton-alpha scored 140/157 on Cold Iron — but as an effort=minimal analogue, not true thinking-off. The model mandates reasoning and its catalog has no none. Zero errors. Math 19/30, coding 30/30. Rank 10 of 26 on the OpenRouter board.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
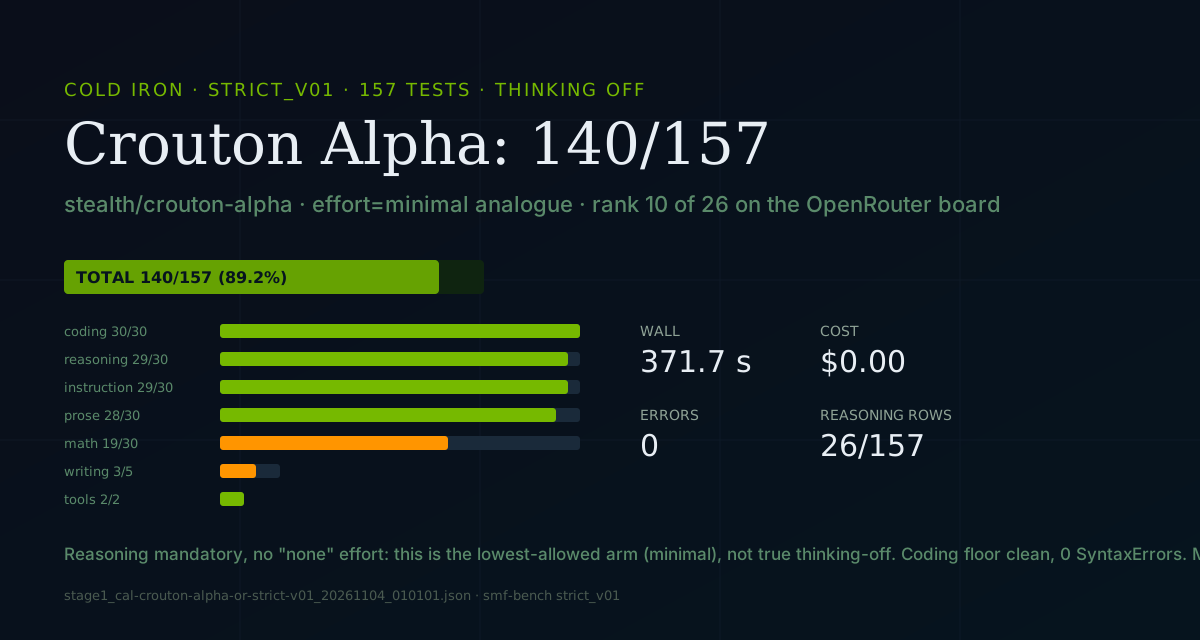
stealth/crouton-alpha scored 140/157 (89.2%) on Cold Iron, with zero errors and a clean 30/30 coding floor. Read the title before the rank: this is an effort=minimal analogue, not true thinking-off. The model's reasoning is mandatory and its catalog offers no none to send.
Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
Why this is an analogue
The catalog row on our key says reasoning.mandatory is true, supported efforts are max, xhigh, high, medium, low, and minimal, and default_effort is max. There is no none. So the lowest quiet arm I can send is minimal.
I smoked it before the 157. The 64-token cap is the discriminator:
| What I sent | What came back |
|---|---|
2+2, default, 64 cap |
finish=length, empty content, 0 reasoning tokens |
2+2, enable_thinking=false, 64 cap |
finish=length, empty content, 0 reasoning tokens |
2+2, effort=minimal, 64 cap |
content 4, stop, 0 reasoning tokens |
2+2, default, 1024 cap |
content 4, stop, 0 reasoning tokens |
bat and ball, effort=minimal, 1024 |
$0.05, 0 reasoning tokens |
The first two rows look clean and are not. At a 64-token cap, default and enable_thinking=false both burned the whole budget on hidden reasoning and returned nothing. Same shape as the run, just hidden. The minimal call let the visible answer land inside 64 tokens, so the reasoning phase was suppressed, not merely unreported. That is the arm I scored.
And it mostly worked: on the 157, 131 of 157 rows recorded 0 reasoning tokens. But 26 rows still burned reasoning: 950 tokens total, concentrated on math expert/frontier, coding frontier, and reasoning frontier items. The provider thinks when it wants to, even at the lowest effort. Per the Cold Iron rules, this file is an analogue: the title and excerpt name the effort, and it does not replace any true-off board row.
The scored payload on each request was:
{
  "reasoning": {"effort": "minimal"}
}
The runner printed payload_check reasoning={"effort": "minimal"} ctk=null model=stealth/crouton-alpha before the first scored item. --thinking off normally attaches enable_thinking=false; the exact-slug branch pops it, because the provider ignores the flag here and the catalog forbids the cleaner payload.
The 157
| Field | Value |
|---|---|
| Model | stealth/crouton-alpha |
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 1,048,576 |
| Max completion on the catalog record | 943,718 |
| List price | $0 / $0 per million tokens |
| Card | text, image, video, file, and audio in, text out |
| What we scored | text only |
| Arm | reasoning.effort=minimal (lowest allowed; no none) |
| Tag | cal-crouton-alpha-or-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-crouton-alpha-or-strict-v01_20261104_010101.json |
The run passed 140 of 157, failed 17, errored none. Wall time 371.7 seconds. Every row finished stop or tool_calls; no row hit a length cap. Mean latency 2.35 seconds, median 2.12, slowest item 8.47 seconds (and that one passed). The file sums to 23,566 prompt tokens and 15,906 completion tokens. Per-row cost sums to $0.00, the catalog prices this slug at $0/$0, and /v1/key usage was unchanged before and after the run (414.370953588 both reads). All three cost views agree: this run was free.
| Category | Score |
|---|---|
| coding | 30/30 (100.0%) |
| instruction | 29/30 (96.7%) |
| math | 19/30 (63.3%) |
| prose | 28/30 (93.3%) |
| reasoning | 29/30 (96.7%) |
| tool_calling | 2/2 (100.0%) |
| writing | 3/5 (60.0%) |
Coding is the standout. Thirty for thirty, no SyntaxError in any saved detail, and the highest completion count on a coding item was 566 tokens, nowhere near the suite's 4096 cap. That is a real syntax floor, not a cap artifact.
Math is the hole, and it is the same shape as other thinking-off runs on this board: eleven regex misses, every one finish=stop, none at a cap. The saved details hold the regex that missed, not the reply, so I am not inventing what the model answered. With 26 rows of leaked reasoning concentrated partly in math, I suspect a quiet think would close some of these. But that is a diagnostic arm, not this score.
The instruction miss is v3.instruction.frontier.04: expected a9gre9dni9ckk13, got a9ge9re9dni9ckk15. A wrong string, not a cut-off. Prose missed two: one wrote 87 lines where 39 were asked, one wrote 9 stanzas where 7 were asked — over-generation, not refusal. Writing missed both its usual suspects: writing_creative matched 1 of 5 keywords at 222 completion tokens, and writing_format used only 16 tokens and skipped the word JSON. Neither is a cap miss.
The tool calls fired clean: get_weather with location=Tokyo and calculate with 45 * 73, matching my pre-run native-tool smoke.
Where 140 sits
The list is every model id scored against an endpoint containing openrouter.ai/api/v1, thinking off, a finished 157, zero errors, newest file per id — recomputed from the result files today, after this run landed. Twenty-six models, including this one. Olympic rank: a tie keeps the next model from taking the next integer. Local serves are not in it, and neither is any batch endpoint.
| Rank | Model | Score | Note |
|---|---|---|---|
| 1 | x-ai/grok-4.6 |
153/157 (97.5%) | true off |
| 2 | google/gemini-4-argon |
152/157 (96.8%) | default is already quiet |
| 9 | anthropic/claude-fable-5.1 |
142/157 (90.4%) | true off |
| 10 | stealth/crouton-alpha |
140/157 (89.2%) | effort=minimal analogue |
| 11 | minimax/minimax-m3.1-flash:free |
136/157 (86.6%) | effort=low analogue |
| 12 | stealth/union-alpha |
136/157 (86.6%) |
I am not ranking a minimal-effort file as if it were thinking-off. The honest reading: it lands between Fable 5.1 and MiniMax M3.1 Flash on the board as filed, and its true-off score does not exist, because the provider does not offer one.
Also worth naming: 371.7 seconds for 157 tests is fast for this board. The runs above it took 900-plus. Cheap, quiet, and quick is exactly what a high-volume agent worker wants. This is one run, though; per our own testing standard, one run is a hint, not a result.
What I would not claim
- I would not call 140 true thinking-off. The provider burned reasoning on 26 rows at
minimal. The analogue label is load-bearing. - I would not call the coding floor a thinking-on artifact. All 157 rows ran the same payload; coding just happened to be clean.
- I would not name a lab. The identity probe answered: "My public deployment name is Crouton Alpha. I can't verify the underlying model name or who made it from the information available here, so I won't speculate on that." Undisclosed is the fact.
- I would not treat the image/video/audio inputs as tested. Cold Iron here is text.
- I would not extrapolate one run into a deployment recommendation. If this slug becomes load-bearing for an agent lane, I re-run it and check the math rows with a thinking-on diagnostic first.
The one-shot, linked
The same-day one-shot is a different article. That call named no effort and ran at the catalog default of max — 61 reasoning tokens of a different payload, on a 13-word brief. Do not mix that HTML file with this score. Crouton Alpha one-shot: LUMINA is here.
Reproducing this
The suite is smf-bench strict_v01, 157 tests. The scored file, the runner with the exact-slug branch, and the full run log are in the Nemo Knowledge Base.
The public smf-bench runner on origin/main, commit 5d9ddf6, has no stealth/crouton-alpha branch — a clone of that commit sends enable_thinking=false and no effort field, which this provider ignores. The checked-in run_stage1.py in the knowledge base has the branch. The probe commands are in the report beside it.
Verification notes
Checked on 2026-11-03:
- Catalog facts (id, created 1793669930, context 1,048,576,
top_provider.max_completion_tokens943,718, pricing 0/0,reasoning.mandatorytrue, efforts max/xhigh/high/medium/low/minimal, default max, text+image+video+file+audio in / text out, no:batchrow) came fromhttps://openrouter.ai/api/v1/modelson our key the same day. - The score, category split, latency, token sums,
finish_reasondistribution, per-row cost, and fail details came fromstage1_cal-crouton-alpha-or-strict-v01_20261104_010101.json.summary.totalis 157,summary.erroris 0,summary.passedis 140,pass_rate89.2,wall_time_seconds371.7.thinkingisoff;reasoning_effortrecords null because the payload was set by the exact-slug branch — the run log'spayload_checkline is the record of what was sent. - Smoke rows are the probes above, saved from the same day. The 64-cap discriminator is the reason
minimalis the arm. - Board ranks were recomputed from every finished zero-error thinking-off 157 on an OpenRouter sync endpoint in
smf-bench/results/after this run landed: 26 model ids. Fable 5.1 isstage1_cal-fable-51-or-strict-v01_20260902_184808.json(142). MiniMax M3.1 Flash free isstage1_cal-minimax-m31-flash-free-or-strict-v01_20261019_122100.json(136). Union Alpha isstage1_cal-union-alpha-strict-v01_20260916_155705.json(136). Grok 4.6 isstage1_showdown-grok46-strict-v01_20260812_200159.json(153). Gemini 4 Argon isstage1_cal-gemini-4-argon-or-strict-v01_20261013_162813.json(152). - Credits:
/v1/keyusage 414.370953588 before and after; per-row cost sum $0.00; catalog list price $0/$0. All agree. - The identity probe is a separate call at
max_tokens1024, quoted verbatim. - The one-shot post is a different payload and is linked, not imported.