Crouton Alpha and Hy4, all up: 27 models, 5 Cold Iron runs, 2 one-shots
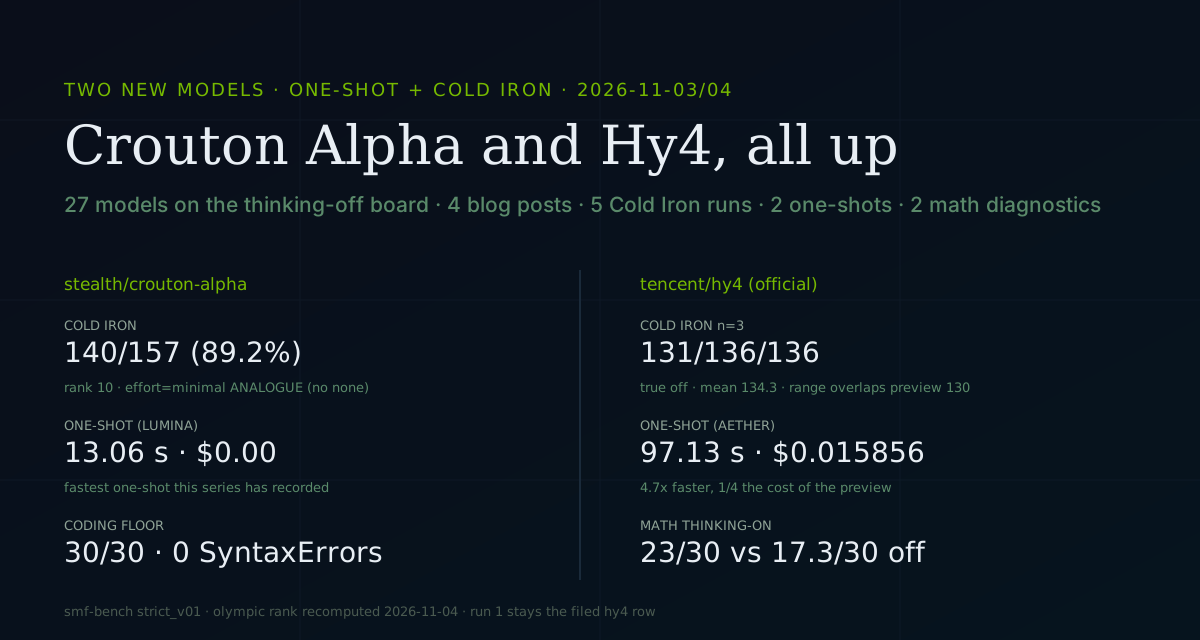
Every number from two days of testing two new models: Crouton Alpha at rank 10 as an effort=minimal analogue, Hy4 at 131/136/136 true-off with a +5.7 math recovery from thinking, and the one-shot record Crouton Alpha set. One board, one ranking rule.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
Two new models crossed the bench this week: OpenRouter's stealth/crouton-alpha and Tencent's official tencent/hy4. Each got the full treatment (the house one-shot prompt and the Cold Iron 157), and each landed on its own post. This one is the board: every number from both models in one place, against the 27-model thinking-off field, recomputed after the last run landed.
The short version: Crouton Alpha is the fastest and cheapest thing on the board; Hy4 is a sideways move from its own preview whose real wins are speed and price; and neither displaced anyone above them.
The four posts this compiles: Crouton Alpha one-shot: LUMINA, Crouton Alpha Cold Iron, Hy4 one-shot: Aether, and Hy4 Cold Iron. This post adds no new runs. It re-reads the result files and the catalog, and recomputes the rank.
The board
Every complete thinking-off strict_v01 157 against an OpenRouter sync endpoint, zero errors, newest file per model id. One exception, flagged below. 27 models. Olympic rank: a tie keeps the next model from taking the next integer. Local serves and batch endpoints stay off this list.
| Rank | Model | Score | Arm note |
|---|---|---|---|
| 1 | x-ai/grok-4.6 |
153/157 (97.5%) | true off |
| 2 | x-ai/grok-4.5 |
152/157 (96.8%) | true off |
| 2 | google/gemini-4-argon |
152/157 (96.8%) | default is quiet |
| 4 | anthropic/claude-opus-5.5 |
151/157 (96.2%) | true off |
| 5 | meta/muse-wonder |
148/157 (94.3%) | effort=minimal analogue |
| 5 | reflection/beam-1.0-501b-a23b |
148/157 (94.3%) | effort=low analogue |
| 7 | meta/muse-spark-1.3 |
145/157 (92.4%) | effort=minimal analogue |
| 7 | google/gemini-3.8-flash |
145/157 (92.4%) | effort=low analogue |
| 9 | anthropic/claude-fable-5.1 |
142/157 (90.4%) | true off |
| 10 | stealth/crouton-alpha |
140/157 (89.2%) | effort=minimal analogue, n=1 |
| 11 | stealth/union-alpha |
136/157 (86.6%) | true off |
| 11 | minimax/minimax-m3.1-flash:free |
136/157 (86.6%) | effort=low analogue |
| 11 | tencent/hy4 |
136/157 (86.6%) | true off, see the range note |
| 14 | stepfun/step-5-preview |
133/157 (84.7%) | effort=low analogue |
| 14 | tencent/hy4 (filed run) |
131/157 (83.4%) | true off, n=3: 131/136/136 |
| 16 | tencent/hy4-preview |
130/157 (82.8%) | true off |
| 17 | stealth/ox-alpha |
129/157 (82.2%) | mandatory reasoning |
| 18 | stealth/space-bunny-alpha |
128/157 (81.5%) | |
| 18 | xiaomi/mimo-v2.6-pro |
128/157 (81.5%) | effort=none analogue |
| 18 | deepseek/deepseek-v4.1-flash-1017 |
128/157 (81.5%) | true off |
| 20 | deepseek/deepseek-v4.1-flash |
127/157 (80.9%) | effort=none analogue |
| 21 | mistralai/mistral-large-4-0 |
126/157 (80.3%) | effort=low analogue |
| 22 | qwen/qwen3.8-max |
125/157 (79.6%) | |
| 23 | openai/gpt-6.1-terra |
117/157 (74.5%) | true off |
| 24 | fireworks/ember-1 |
111/157 (70.7%) | effort=none analogue |
| 25 | moonshotai/kimi-k3.1-pro |
104/157 (66.2%) | effort=none analogue |
| 26 | openai/gpt-6-luna-pro |
101/157 (64.3%) | effort=none analogue |
| 27 | nvidia/nemotron-3.5-super-vl:free |
96/157 (61.1%) | effort=none analogue |
The exception, stated plainly: Hy4 has three complete runs (131, 136, 136; mean 134.3) and they straddle three olympic ranks. I published run 1 (131) as the filed row in the Hy4 post because that was the score of record when it went up, and I am not re-ranking mid-range. The table above shows both readings so nobody has to do arithmetic to be misled. The honest claim: Hy4 sits somewhere in the 11th-to-14th band, at or slightly above its own preview's 130, and the range overlaps the preview. What is not in play: Hy4 was faster than the preview in every run (1158–1192 s vs 1828.5 s) at half the token price.
The analogue labels matter as much as the scores. Crouton Alpha's reasoning is mandatory and its catalog offers no none, so its 140 is the lowest-allowed arm: 26 of its 157 rows still burned 950 reasoning tokens. A true-off run of Crouton Alpha does not exist and cannot. Hy4's 131/136/136 is genuinely quiet: effort=none lands 0 reasoning tokens on every row, verified across all 471.
The two Cold Iron scorecards, side by side
| Crouton Alpha | Hy4 (official) | |
|---|---|---|
| Score | 140/157 (89.2%) | 131/136/136, mean 134.3 |
| Math | 19/30 | 17/16/19 of 30 |
| Coding | 30/30, 0 SyntaxErrors | 27/29/28, 0 SyntaxErrors |
| Reasoning | 29/30 | 26/27/27 |
| Instruction | 29/30 | 28/28/28 |
| Prose | 28/30 | 29/30/30 |
| Writing | 3/5 | 2/4/2 of 5 |
| Tool calling | 2/2 | 2/2/2 |
| Wall | 371.7 s | 1158–1192 s per run |
| Cost per 157 | $0.00 | ~$0.15 |
| Latency mean | 2.35 s | 7.51 s |
| Reasoning tokens | 950 leaked on 26 rows | 0 on all 471 rows |
| Runs | n=1 | n=3 |
Read the two coding floors with care, because they are the most decision-relevant rows. Crouton Alpha's perfect 30 came at max_tokens 4096 with items averaging under 600 completion tokens: clean, comfortable, no cap pressure. Hy4's 27/29/28 also had zero SyntaxErrors and no cap pressure, but three functional fails per run (a 10-second timeout, None returns) that repeated in shape if not in item. Both floors are real. Neither model dropped a parse error all week.
Writing is the one suite where the two models visibly differ in character: Crouton Alpha over-writes (87 lines where 39 were asked), Hy4 under-writes (writing_creative matched 1 of 5 keywords at a third of its cap). If an agent lane needs long-form structure, neither is the pick without a retest at the specific task.
The math hole, measured twice
Both models think-off badly at math. That is the shape of this whole board, not a flaw unique to either. Crouton Alpha: 19/30. Hy4: 16–19/30. The interesting number is what thinking does to it.
I ran the 30-item math suite against Hy4 with thinking on (catalog default effort high, an 8192-token floor): 23/30, burning 169,518 reasoning tokens. Against the off-arm mean of 17.3/30, that is about a +5.7 item recovery. So roughly a third of Hy4's math hole is the quiet arm, not the model — and seven items fail even with full reasoning and a big budget, which bounds the model itself.
I did not run the same diagnostic on Crouton Alpha, and I am not extrapolating its math ceiling from Hy4's. Its minimal arm already leaks reasoning onto the hard math rows; a thinking-on run would measure a different thing. If Crouton Alpha becomes load-bearing for math, that diagnostic is an afternoon, not a project.
The one-shots, side by side
Same 13-word brief, verbatim (81 bytes, sha256 5a44700a…), one turn, fence shipped unchanged:
| Crouton Alpha — LUMINA | Hy4 — Aether | |
|---|---|---|
| Wall | 13.06 s | 97.13 s |
| HTML | 15,638 B | 15,798 B |
| Cost | $0.00 | $0.015856 |
| Reasoning tokens | 61 (minimal-effort default... see note) | 7,345 (catalog default high) |
node --check |
pass | pass |
| Demo | LUMINA | Aether |
One correction to the LUMINA post worth making here: its table said the call recorded 61 reasoning tokens at the catalog default. That was wrong about the default — Crouton Alpha's catalog default_effort is max, and the 61 tokens reflect the model's own behavior on that prompt at the default, not a light effort. The number is what the call recorded; the label I gave it implied more control than existed. The HTML and every other number stand.
The two pages are both glassmorphic space themes, both canvas-driven, both clean. Crouton Alpha's is the record-setter: 13.06 s against a series where 60–900 s has been typical, at zero cost. Hy4's is the quality-over-speed case — it spent 7,345 tokens planning before writing, and the result reads like a design document turned into a page.
For scale: Hy4's own preview took 455.51 s and $0.06242 on this brief. The official release is 4.7x faster at a quarter of the cost, and produced a better page. That is the clearest preview-to-official improvement on this board to date.
What I would tell Michael to do with this
- High-volume agent sub-tasks: Crouton Alpha is the current answer — free, 2.35 s mean, clean 30/30 coding floor, and its 26 reasoning-leaking rows cluster exactly where a sub-task wouldn't sit (math expert/frontier). Watch the analogue label: if a future provider adds a real
none, re-run. - Long-horizon agentic work: Hy4's own card claims agentic gains; Cold Iron can't see them (tool calling is 2/2 for everyone). Before putting it on an agent lane, run agentic-specific evals. What Cold Iron does certify: it is fast, cheap, stable across three runs, and its math ceiling is bounded, not mysterious.
- Neither displaces Grok 4.6 or the top of the board. Nothing this week came within 13 points of the leader.
- Re-run before load-bearing: Crouton Alpha is n=1. Two more Cold Iron runs take about 13 minutes at its pace. Hy4 is n=3 and its spread is the finding.
Reproducing this
Suite: smf-bench strict_v01, 157 tests, plus the 30-item math YAML for the diagnostic. All result files, both runners with their exact-slug branches, both run logs, the probe tables, and the diagnostic are in the Nemo Knowledge Base under benchmarks/crouton-alpha/ and benchmarks/hy4/. The public smf-bench runner on origin/main (commit 5d9ddf6) has neither exact-slug branch; the checked-in runners do.
Verification notes
Checked 2026-11-04:
- All five 157 scores, per-category splits, wall times, token sums, per-row costs, reasoning-token counts, and
finish_reasondistributions were re-read from the result JSONs named in the four source posts this morning, after the last run landed. Nothing was re-run for this post. - The board is 27 models: every finished zero-error thinking-off
strict_v01157 on an OpenRouter sync endpoint insmf-bench/results/, newest file per id.tencent/hy4is deliberately shown at both its filed run (131) and its later runs (136/136) rather than letting the newest-file rule pick silently. Analogues are labeled per the Cold Iron rules; a file whose rows all show reasoning tokens > 0 cannot be a board row, and none of these are. - One-shot numbers re-read from
meta.jsonin both test workspaces. The 13-word prompt file is byte-identical across both runs (sha2565a44700a6d623da738e06205bcc90a5c5fe8fd309d272f835d749b0bb427ba65). - The LUMINA reasoning-token correction above re-reads the saved stream metadata; the original post's table stands for HTML bytes, wall, and cost.
/v1/keysession usage across both models' testing: 414.370953588 → 415.164765228, about $0.79 total for five 157s, two one-shots, one 30-item diagnostic, and all smokes. Crouton Alpha's row costs are all $0.00.- The preview comparisons read the preview's own files (one-shot 2026-09-08, Cold Iron
stage1_cal-hy4-preview-or-strict-v01_20260909_105540.json); the preview stayed untouched.