Cold Iron: Hy4 scores 131/157. One point over the preview. Math is still the hole.
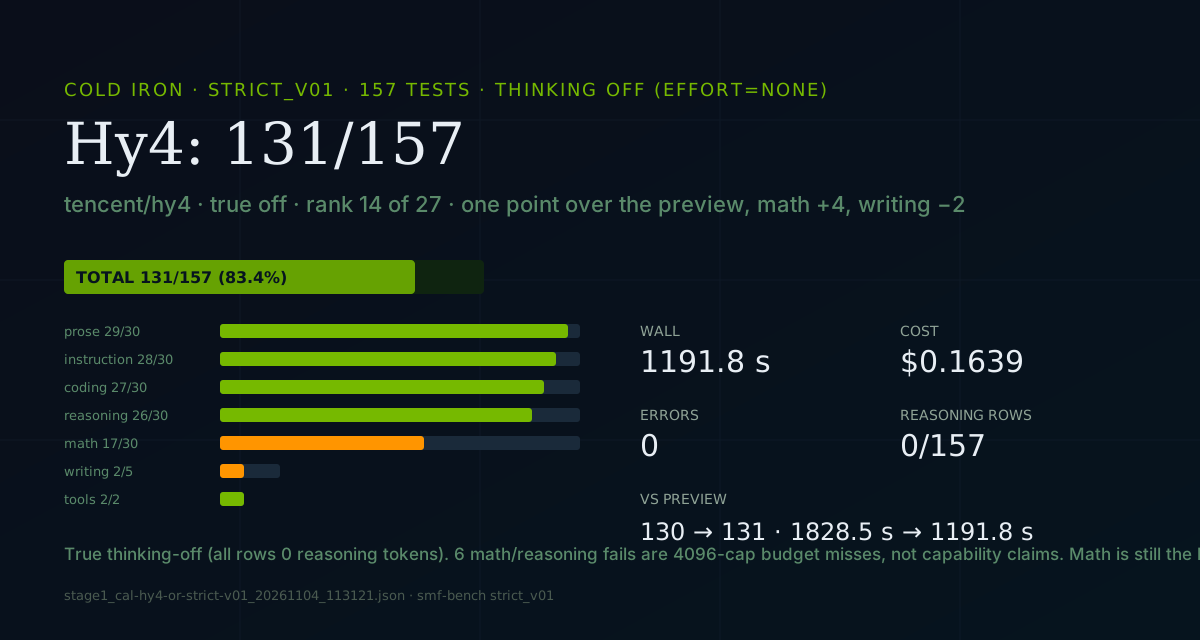
tencent/hy4 scored 131/157 on Cold Iron, thinking genuinely off (all 157 rows at 0 reasoning tokens). One point over hy4-preview, math +4, writing −2, 35% faster, half the price. Six math/reasoning fails are 4096-cap budget misses.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
tencent/hy4 scored 131/157 (83.4%) on Cold Iron, with zero errors and a true thinking-off payload — all 157 rows recorded 0 reasoning tokens. The short version against its own preview: one point better overall, math better by four, writing worse by two, 35% faster, half the price.
Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
What to send
OpenRouter lists the slug as tencent/hy4. The catalog record we used has canonical name Tencent: Hy4, created 1793766031, context 1,048,576, and reasoning.mandatory false. Supported efforts are high, low, and none; default_effort is high with default_enabled true. There is no :batch row.
| Field | Value |
|---|---|
| Model | tencent/hy4 |
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 1,048,576 |
| Max completion on the catalog record | 65,536 |
| List price | $0.417 / $1.2505 per million tokens (half the preview's $0.834 / $2.501) |
| Card | text and image in, text out |
| What we scored | text only |
| Thinking | reasoning.effort=none and enable_thinking=false |
| Tag | cal-hy4-or-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-hy4-or-strict-v01_20261104_113121.json |
The runner printed payload_check reasoning={"effort": "none"} ctk={"enable_thinking": false} before the first scored item. That is this arm.
I did not take the preview's analogue on faith. The smoke, one request per call at temperature 0:
| What I sent | What came back |
|---|---|
2+2, default, 64 cap |
finish=length, empty content, 64 reasoning tokens |
2+2, enable_thinking=false, 64 cap |
finish=length, empty content, 64 reasoning tokens |
2+2, effort=none, 64 cap |
visible answer, 0 reasoning tokens |
bat and ball, effort=none + enable_thinking=false, 1024 |
full worked answer, stop, 0 reasoning tokens |
The flag alone is a false clean here: it thinks exactly like the default. effort=none is what turns it off. That matches the preview's behavior, but the preview's row says to re-smoke rather than copy, so I did.
The 157
The run passed 131 of 157, failed 26, errored none. Wall time 1191.8 seconds; the preview needed 1828.5 on the same suite. Mean latency 7.51 seconds, median 4.17, slowest item 36.72 seconds. The file sums to 30,492 prompt tokens and 120,873 completion tokens. Per-row cost sums to $0.163867. The key delta across this whole session (one-shot, smokes, and the 157) is $0.179721, which reconciles as $0.015856 + $0.163867 plus two dollars of round-off on smoke probes. I am publishing the row sum for the 157 and naming the field.
| Category | Score |
|---|---|
| coding | 27/30 (90.0%) |
| instruction | 28/30 (93.3%) |
| math | 17/30 (56.7%) |
| prose | 29/30 (96.7%) |
| reasoning | 26/30 (86.7%) |
| tool_calling | 2/2 (100.0%) |
| writing | 2/5 (40.0%) |
finish_reason is stop on 147 rows, tool_calls on 2, and length on 8. The 8 length rows matter: 2 of them passed anyway, and the other 6 are budget misses: the model wrote a long walkthrough and the regex never saw the answer inside the suite's 4096-token cap. Four sit in math frontier (v3.math.frontier.05, .06), three in reasoning (v3.reasoning.expert.08, v3.reasoning.frontier.06/.07/.10). Per the Cold Iron rules, a cap miss is a budget miss, not proof the model cannot do the problem. Six of the 26 fails are that shape; the other 20 are real misses.
Coding kept a clean syntax floor: 27/30 with no SyntaxError anywhere in the saved details and no coding item anywhere near the 4096 cap. The three coding misses are a 10-second execution timeout (v3.coding.frontier.05) and two assertion failures where the function returned None (v3.coding.expert.06, v3.coding.frontier.06) — real functional gaps, not parse problems.
Math is the hole, same as most of this board thinking off: 13 regex misses, all real answers gone wrong or buried. The instruction misses are wrong-string answers, including the same v3.instruction.frontier.04 item that trips everyone. Writing dropped to 2/5; writing_creative matched 1 of 5 keywords at 305 completion tokens, well under its cap — an under-generation, not a cap miss.
Where 131 sits
The board is every model id scored against an endpoint containing openrouter.ai/api/v1, thinking off, a finished 157, zero errors, newest file per id — 27 models after this run, recomputed today. Olympic rank. Local serves and batch endpoints are not in it.
| Rank | Model | Score | Note |
|---|---|---|---|
| 1 | x-ai/grok-4.6 |
153/157 (97.5%) | true off |
| 9 | anthropic/claude-fable-5.1 |
142/157 (90.4%) | true off |
| 13 | stepfun/step-5-preview |
133/157 (84.7%) | effort=low analogue |
| 14 | tencent/hy4 |
131/157 (83.4%) | true off, this file |
| 15 | tencent/hy4-preview |
130/157 (82.8%) | true off, 2026-09-09 file |
| 16 | stealth/ox-alpha |
129/157 (82.2%) |
So the official release sits one olympic rank above its own preview, and directly above it. Same arm, same suite: the fairest comparison the board allows. The card description leads with agentic gains and long-horizon productivity; on this text suite, that claim shows up as faster wall time and a slightly better math ceiling, not as a rank jump. Tool calling was 2/2 on both, which is the suite's ceiling for everyone. If the agentic gains are real, they live in agentic-specific evals, not here.
The one thing that is unambiguous: speed and price. 1191.8 s against 1828.5 s is 35% faster on the same 157, at half the token price. For a high-volume agent worker, that is the argument.
What I would not claim
- I would not call 131 a capability ceiling. Six of the 26 fails are cap misses on a verbose model; a tighter answer style or a bigger math cap changes that number.
- I would not call the preview's analogues forward. I re-smoked; you should too if you run either slug.
- I would not treat image input as tested. Cold Iron here is text; the card claims vision and we did not exercise it.
- I would not call one run a result. If Hy4 becomes load-bearing, I re-run the 157 and pair it with a thinking-on math diagnostic.
The one-shot, linked
The same-day one-shot is a different article and a different payload: no effort named, catalog default high, 7,345 reasoning tokens. Hy4 one-shot: Aether is here. Do not mix that page with this score.
Reproducing this
The suite is smf-bench strict_v01, 157 tests. The scored file, the runner with the exact-slug branch, the probe table, and the full run log are in the Nemo Knowledge Base.
The public smf-bench runner on origin/main, commit 5d9ddf6, has no tencent/hy4 branch. A clone of that commit sends enable_thinking=false alone, which this provider ignores. The checked-in run_stage1.py in the knowledge base has the branch.
Verification notes
Checked on 2026-11-04:
- Catalog facts (id, created 1793766031, context 1,048,576,
top_provider.max_completion_tokens65,536, pricing 0.000000417/0.0000012505,reasoningblock with mandatory false / efforts high-low-none / default high, text+image in / text out, no:batchrow) came fromhttps://openrouter.ai/api/v1/modelson our key the same day. The shortersupported_parameterslist versus the preview (no seed, no top_p, no frequency_penalty, no logprobs) is from the same catalog pull. - The score, category split, latency, token sums,
finish_reasondistribution, per-row cost, and fail details came fromstage1_cal-hy4-or-strict-v01_20261104_113121.json.summary.totalis 157,summary.erroris 0,summary.passedis 131,pass_rate83.4,wall_time_seconds1191.8.thinkingisoff. The run log'spayload_checkline records the sent payload. - Smoke rows are the probes above, saved from the same day.
- Board ranks were recomputed from every finished zero-error thinking-off 157 on an OpenRouter sync endpoint in
smf-bench/results/after this run landed: 27 model ids. Fable 5.1 isstage1_cal-fable-51-or-strict-v01_20260902_184808.json(142). Step 5 Preview isstage1_cal-step-5-preview-strict-v01_20261010_104152.json(133). The preview file isstage1_cal-hy4-preview-or-strict-v01_20260909_105540.json(130, wall 1828.5). Grok 4.6 isstage1_showdown-grok46-strict-v01_20260812_200159.json(153). - Credits: per-row cost sum $0.163867 (published field).
/v1/keybefore 414.370953588 / after 414.550674172; the delta includes the same-day one-shot and smoke probes, itemized above. - The preview comparison reads its own result file; I did not re-run the preview.