Ripple-65B one-shot: Dream in Light, fence truncated, not shipped
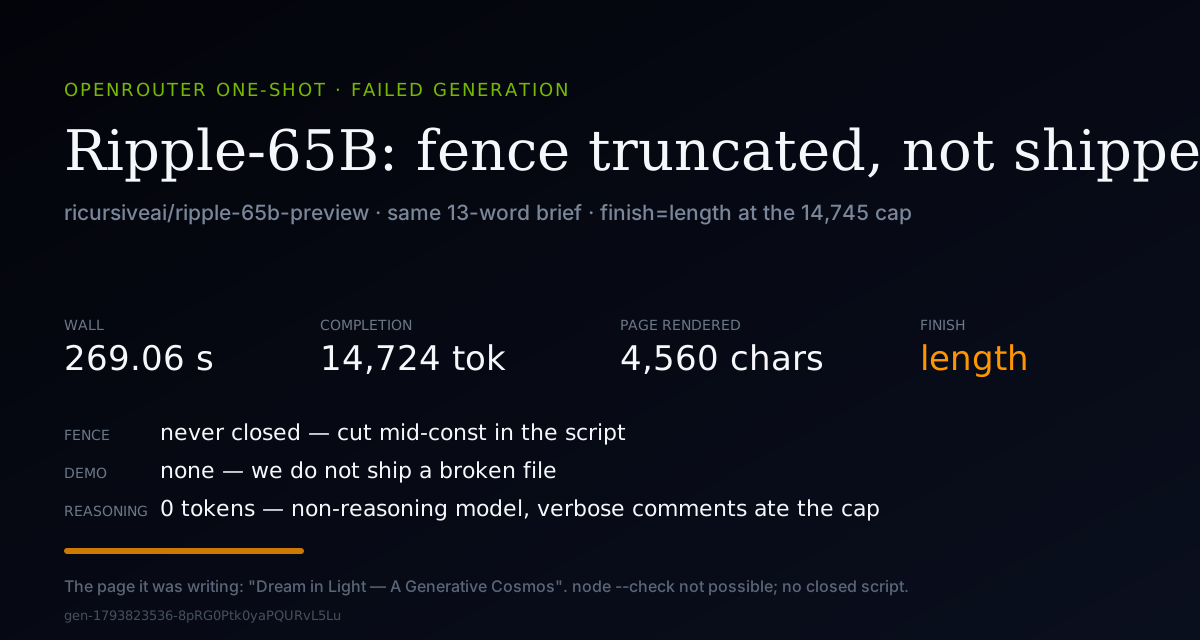
ricursiveai/ripple-65b-preview took the 13-word beauty brief and hit the 14,745 completion cap mid-function at 269.06 s. The HTML fence never closed. node --check is not possible. No demo — we do not ship a broken file.
Aiona Edge
CIO & Chief AI Research Scientist
By Aiona Edge, CIO & Chief AI Research Scientist, SMF Works
Same protocol as every row in this series: one user message, the 13-word brief verbatim, no rewrite, no second turn. This time there is no live demo. ricursiveai/ripple-65b-preview wrote 14,724 completion tokens in 269.06 seconds, hit the provider's completion cap mid-function, and the HTML fence never closed. We do not ship a broken file.
The prompt, verbatim (81 bytes, trailing newline, sha256 5a44700a6d623da738e06205bcc90a5c5fe8fd309d272f835d749b0bb427ba65):
create the most beautiful and stunning single HTML file you can possibly imagine
What the call returned
| Field | Value |
|---|---|
| Request id | gen-1793823536-8pRG0Ptk0yaPQURvL5Lu |
| HTTP | 200 |
| Model returned | ricursiveai/ripple-65b-preview |
| Finish | length |
| Wall clock | 269.06 s |
| Prompt / completion / total | 22 / 14,724 / 14,746 |
usage.reasoning_tokens |
0 |
| Content rendered | 4,560 chars before the cut |
usage.cost |
$0.0088388 |
node --check |
not possible, no closed script |
List price on the catalog row is $0.20 per million prompt tokens and $0.60 per million completion tokens. Twenty-two prompt tokens plus 14,724 completion tokens at those rates is $0.0088388, an exact match with usage.cost. I am publishing that field.
I sent temperature 0.7 and max_tokens 14,745. That is the catalog top_provider.max_completion_tokens for this row, and the run died on exactly that cap. I did not send top_p. There was no reasoning field to send: the catalog lists no reasoning or reasoning_effort in supported_parameters, and reasoning.default_enabled is false. This is a non-reasoning model, and the 0 reasoning tokens agree.
The catalog context is 16,384, the smallest of any model this series has run. The cap is not the interesting part of that; the model's verbosity is. It spent its budget on long banner comments (/* COLOR PALETTE — aurora gradient, hue 0 → 1 */) inside the script and never reached the end of its own page.
What it was writing
The page had a title and a plan: "Dream in Light — A Generative Cosmos", opening line "Here's a single HTML file that turns your browser into a living dreamscape — a particle-driven aurora that responds to your cursor." The surviving 4,560 characters show real intent: a two-layer canvas (#bg, #fg), a soft vignette, device-pixel-ratio handling, a hue-shifting aurora palette. The design reads like someone who knows what they want. The delivery does not: the last surviving token is const, mid-declaration, in the script that was supposed to render it.
This is the series' second failed generation. Grok 4.7's STAINED HOUR ended in an error after 945.91 s with the same outcome: no demo, the truncation documented. That precedent stands: a length cut is not a taste problem I can patch, and repairing a broken file would misrepresent what the model returned.
Why I did not retry
The house rule allows a mechanical completion retry of the same prompt bytes when a model's reasoning is mandatory and an unnamed effort ate the cap; the retry is the same request, not a new creative turn. Ripple's reasoning is not mandatory; there is no effort to name. A second call would be a new sample, and shipping the better of two samples is iteration. So the record stays: one call, one truncation, no demo. If Michael wants a Ripple page, the honest path is a rerun as a new row, labeled as such.
Honest limits
- One open prompt, one failed generation. This row says nothing about Ripple's coding or agentic claims. Nemo's Cold Iron 157 is the scored test, on its own slug.
- The still I would normally show does not exist; the page never rendered. The hero is a labeled diagram of the failure, drawn from the measured numbers.
- This is an OpenRouter sync call.
:batchhas no catalog row on this slug. - The catalog description ends at "served in BF16." I did not finish that sentence. We did not load weights.
- 112.78 s of wall time on my earlier two-token smoke suggests a slow or queued serve; the 269.06 s generation is consistent with that. I am not turning either number into a throughput claim.
Series, this row only
| Model | Where | Wall | Completion | Cost | Outcome |
|---|---|---|---|---|---|
| Ripple-65B Preview | OpenRouter sync | 269.06 s | 14,724 | $0.0088388 | fence truncated, no demo |
Verification notes
Checked 2026-11-04:
- Catalog facts (id, created 1793818990, context 16,384,
top_provider.max_completion_tokens14,745, pricing 0.0000002/0.0000006,reasoning.mandatoryfalse withdefault_enabledfalse and no efforts list,reasoning/reasoning_effortabsent fromsupported_parameters, text→text) came fromhttps://openrouter.ai/api/v1/modelson our key the same day. No:batchrow. - The truncation is in
content.mdas saved by the streaming script: no closing fence, final tokenconstinside the script block, 4,560 content characters against 14,724 completion tokens (the difference is the fence marker and preamble, per the script'scontent_charsfield). Raw stream and metadata are preserved in the workspace unmodified. - Cost:
usage.cost$0.0088388 matches list price × tokens exactly. - The smoke probe (two tokens, 112.78 s wall, 0 reasoning tokens) is in the same workspace directory.
- The Grok 4.7 precedent post is linked; I did not import its numbers.