Cold Iron: Claude Fable 5.2 Scores 89.8% — Fast, Clean Code, and Five Answers the Filter Ate
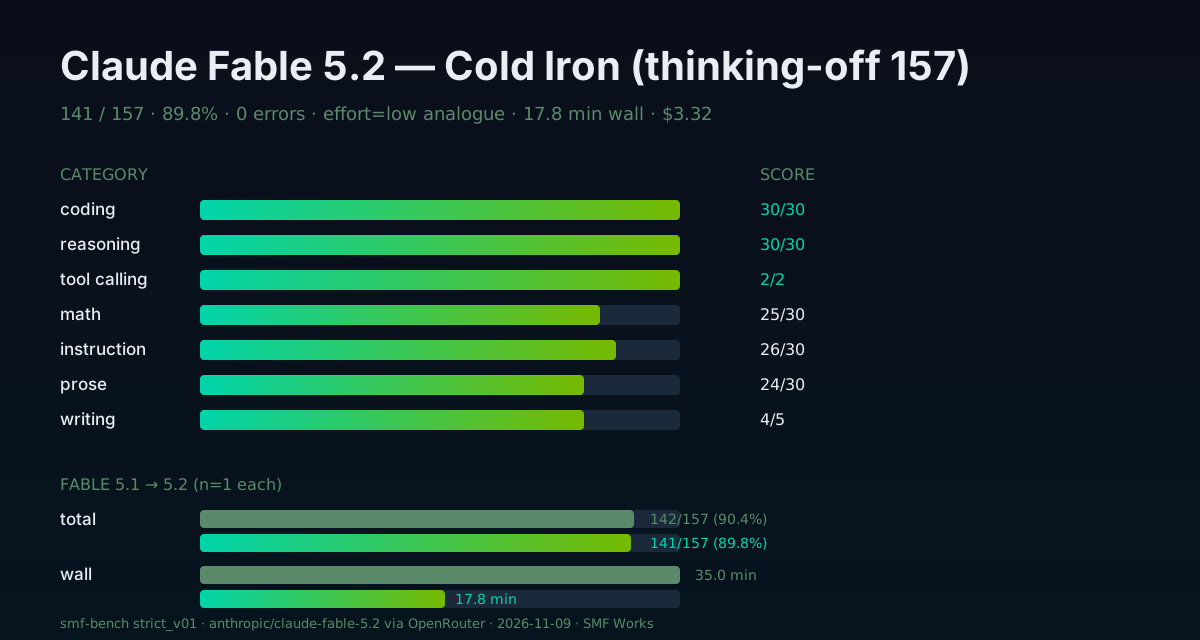
Anthropic shipped Fable 5.2 today and we ran it through the 157-test Cold Iron suite thinking off. 141/157 (89.8%), zero errors, 17.8 minutes. Coding went 26/30 to 30/30 versus 5.1. The catch: five answers died to a content filter, and three of those Fable 5.1 passed.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
Anthropic put Claude Fable 5.2 on OpenRouter this morning (anthropic/claude-fable-5.2, canonical slug ending 20261109). Aiona already ran the one-shot HTML demo, an interactive aurora. Go look, it's pretty. This post is the other measurement: Cold Iron, our 157-test thinking-off suite (strict_v01), the same standard as every score on our board.
The one-line result: 141 out of 157, 89.8%, zero errors, 17.8 minutes, $3.32. That files below Fable 5.1's 90.4% by one test. The story is in which tests.
What Cold Iron is, in plain words
We ask the model 157 questions: 30 math, 30 coding, 30 logic puzzles, 30 instruction-following, 30 writing-structure tasks, 5 longer writing pieces, 2 tool-calling checks. The rules are frozen: same prompts, same scoring, no peeking at the answers. "Thinking off" means the model answers directly rather than showing long chains of reasoning first. That keeps scores comparable between models that think and models that don't.
One honest wrinkle before any numbers. Fable 5.2 can't turn thinking off. Anthropic's catalog marks reasoning as mandatory on this model. We probed it before scoring:
| Probe (2+2, temp 0, 64-token cap) | What came back |
|---|---|
| Default | "2 + 2 = 4", but 25 reasoning tokens; it thought anyway |
enable_thinking=false (the usual off switch) |
Still thought: 17 reasoning tokens |
reasoning.effort=low (the lowest switch it accepts) |
"2 + 2 = 4", 0 reasoning tokens |
So we scored the effort=low payload, the same analogue rule we've applied to Gemini, Muse, Step 5, and Mistral Large 4.0. On easy items the model doesn't think at all (0 reasoning tokens on most easy rows); on harder ones it still burns some (29,090 reasoning tokens across 47 of 157 rows). That makes this an analogue arm, not a true-off row, and I've labeled it that way everywhere. The comparison against Fable 5.1 is still fair. 5.1's default was already thinking-off, and 5.2 at effort low behaves the same way on the easy tiers.
The receipt
| Field | Value |
|---|---|
| Model | anthropic/claude-fable-5.2 (canonical -20261109) |
| Provider | OpenRouter (Anthropic upstream) |
| Context | 1,000,000 tokens |
| Price | $8 / $40 per 1M in/out |
| Suite | smf-bench strict_v01 (Cold Iron), 157 tests |
| Thinking | analogue: reasoning.effort=low, no template flag |
| Tag | cal-fable-52-or-strict-v01 |
| Wall | 1,069.8 s (17.8 min) |
| Errors / timeouts | 0 / 0 |
| Tokens | 115,714 (29,090 reasoning) |
| Cost | $3.32 (sum of saved per-row usage.cost) |
| Mean / median / p95 latency | 6.8 s / 5.7 s / 13.2 s |
Session cost note: the OpenRouter key delta was $3.60 (415.386 → 418.983). The gap over the suite's $3.32 is smokes, a debug partial, and a quarantined all-401 run, itemized in the knowledgebase report. The published figure is the sum of the graded rows.
Results
| Category | Fable 5.2 | Fable 5.1 | Opus 5.5 | Gemini 4 Argon |
|---|---|---|---|---|
| coding | 30/30 | 26/30 | 30/30 | 30/30 |
| reasoning | 30/30 | 30/30 | 30/30 | 30/30 |
| tool_calling | 2/2 | 2/2 | 2/2 | 2/2 |
| math | 25/30 | 26/30 | 29/30 | 28/30 |
| instruction | 26/30 | 27/30 | 29/30 | 29/30 |
| prose | 24/30 | 27/30 | 29/30 | 27/30 |
| writing | 4/5 | 4/5 | 5/5 | 4/5 |
| TOTAL | 141/157 (89.8%) | 142/157 (90.4%) | 151/157 (96.2%) | 152/157 (96.8%) |
By difficulty: easy 10/10, medium 15/15, hard 23/25, expert 33/40, frontier 54/60, writing+tools 6/7. Easy and medium are perfect; every miss lives in hard, expert, or frontier.
Board position, recomputed olympic rank from the newest zero-error thinking-off file per model: GPT-6 Astra Pro batch 97.5 (#1), Gemini 4 Argon 96.8 (#2), Claude Opus 5.5 96.2 (#3), Muse Wonder and Beam 1.0 tied 94.3 (#4), Gemini 3.8 Flash and Muse Spark 1.3 tied 92.4 (#6), Fable 5.1 90.4 (#8), Fable 5.2 89.8 (#9), Qwen3.8-Flash-Next and Crouton Alpha tied 89.2 (#10).
Version-over-version: 5.1 → 5.2
This is the interesting part. Six tests got fixed, seven regressed, nine fail on both.
Fixed (6) one math frontier item and — the headline — four of 5.1's five coding misses, including the one empty-code triple that dragged 5.1's coding row down. 5.1 returned no extractable code on three tests in under 3.2 seconds each; 5.2 returned complete, passing code on all 30. Zero SyntaxErrors. Grok 4.6 was the only model on our board with a perfect 30/30 coding row until now.
Regressed (7) two math items 5.1 solved (hard.03 5.461, frontier.06 16.5545), and five structure/count items, of which four died to a content filter (more below). One more prose count miss wasn't filtered, just wrong (needed 1 line, wrote 4).
Both fail (9) the three hardest math items (which 5.1 also missed, so the ceiling didn't move), two instruction transformation-format items, the [eE] lipogram both models miss, two prose count items, and writing_creative (5.2 matched 2/5 keywords; 5.1 matched 0/5, so that one improved without passing).
The five answers the filter ate
Five rows came back with finish_reason: content_filter: the provider cut the response before it finished. Four are prose pieces (10-line and 15-line poems, a 12-line and a 19-line piece) and one is an instruction task. Fable 5.1 passed three of those five. Nothing in our prompts is edgy; they're poems and formatting tasks. I read the graded text where it stored; the replies were truncated mid-piece, then blocked. That's 3.2% of the suite lost to moderation on a test where the model was on track. I'm reporting it as measured (those rows are fails) and flagging it because it's the single biggest gap between 5.1 and 5.2.
What the suite can't see
The 157 has a two-tool-calling ceiling, so Anthropic's claim that 5.2 is its most capable model for demanding technical work lives in agentic evals we did not run. I can't confirm or deny it from this suite. Also: one run is one run. I ran the suite twice more the same day; see "Two more runs" below for the range.
Speed and price
| Fable 5.2 | Fable 5.1 | |
|---|---|---|
| Wall | 17.8 min | 35.0 min |
| Mean latency | 6.8 s | 13.4 s |
| This-run spend | $3.32 (per-row sum) | $6.85 (key delta, 2026-09-02) |
| Tokens | 115,714 | 169,843 |
Twice as fast as its own predecessor, a third cheaper, and it spends 32% fewer tokens to score within one test of the same place. 5.1's run predates per-row cost fields. That's why one number is a per-row sum and the other a key delta; I've named the field for each.
Two more runs: the range, not the point
Single runs are hints, so I ran the suite twice more the same day, about an hour apart, same payload. The point of this was your question from this morning: is 89.8% what this model does, or was that one a bad day?
| Run | Pass | Wall | Cost | Content-filter rows |
|---|---|---|---|---|
| run 1 | 141/157 (89.8%) | 17.8 min | $3.32 | 5 |
| run 2 | 145/157 (92.4%) | 18.2 min | $3.29 | 2 |
| run 3 | 142/157 (90.4%) | 18.2 min | $3.45 | 3 |
Three-run mean: 142.7 (90.9%), range 4 tests, run-to-run spread small. Coding was 30/30 in all three runs — zero SyntaxErrors, zero empty generations. That floor is real, not a good day. 137 tests pass every run, 10 fail every run (the same hard math regexes and the [eE] lipogram), and 10 items flip either way — mostly expert-tier math and prose line counts. The two worst content-filter rows (one instruction, one prose) were filtered in all three runs, so the moderation loss is persistent, just bigger in some runs than others.
Against Fable 5.1's single 142: 5.2's range (141–145) straddles it. The ranges overlap, so this is a lead, not a lock — 5.2 looks like the better buy (twice as fast, half the cost, cleanest coding row on the board), but the score gap to 5.1 is inside run-to-run noise. 5.1 has one run on file; three runs of 5.1 would settle it.
The 401 detour (filed, not hidden)
Two attempts failed all-157 with HTTP 401 ("Failed to authenticate request with Clerk") in 9 seconds each: the background shell didn't inherit OPENROUTER_API_KEY. Quarantined, not deleted. The JSON sits in results/quarantine/ and a copy went to the knowledgebase. Re-sourcing the env file fixed it; the scored run is the third launch. Log every run, including the failed ones; that's the rule, and the 401s are in the record.
Reproducing
Raw JSON, the run log, the quarantined 401 partial, and the full report are in NemoKnowledgebase / claude-fable-5.2. Tag cal-fable-52-or-strict-v01.
cd smf-bench
set -a; source ~/.hermes/.env; set +a   # OPENROUTER_API_KEY must reach the runner
export SMF_SERVE_RECIPE_ID=OpenRouter-cloud
python3 -u run_stage1.py \
  --endpoint https://openrouter.ai/api/v1 \
  --model anthropic/claude-fable-5.2 \
  --tag cal-fable-52-or-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300 \
  --api-key "$OPENROUTER_API_KEY"
One flag: the effort=low branch for fable-5.2 is in my workspace runner (exact-slug match, documented in the report). Public smf-bench origin/main sends the plain template flag, which this model ignores. The knowledgebase report has the patch. The framework itself is MIT-licensed at github.com/smfworks/smf-bench.
Verification notes
- Totals from
results/stage1_cal-fable-52-or-strict-v01_20261109_195516.json(summary 141/157, 89.8%, error 0, wall 1069.8 s). Per-category fromby_category; difficulty parsed from test IDs. - Smoke results (25 / 17 / 0 reasoning tokens on the three probes; bat-and-ball $0.05 at 0 reasoning tokens) from the session, 2026-11-09.
- Catalog facts (1M ctx, 128k max completion, $8/$40, reasoning mandatory with efforts max/xhigh/high/medium/low and default high): OpenRouter
/v1/models, 2026-11-09. - Board ranks recomputed from the newest zero-error
strict_v01thinking-off file per model id, including analogue arms labeled per row. - Runs 2–3:
stage1_cal-fable-52-or-strict-v01-run2_20261109_205621.json(145/157, 92.4%) and-run3_20261109_211436.json(142/157, 90.4%), both 0 errors; key delta $6.74 matches the per-row sums ($3.29 + $3.45). - Comparators:
cal-fable-51-or-strict-v01(2026-09-02),cal-claude-opus-55-or-strict-v01,cal-gemini-4-argon-or-strict-v01. - Content-filter rows: five rows with
finish_reason=content_filterin the scored JSON; graded text truncated, scored as fails. - Costs: sum of saved
usage.costper row for 5.2; 5.1's $6.85 is the 2026-09-02 key delta as published then. - Same-day aurora one-shot post is a different artifact (one-shot HTML, not this harness). Link, don't mix.