Eight Models on Cold Iron: The 157-Test Board
The full scored board: eight frontier models through our 157-test thinking-off suite, with per-category strengths, real costs, and one $0.013 shocker.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
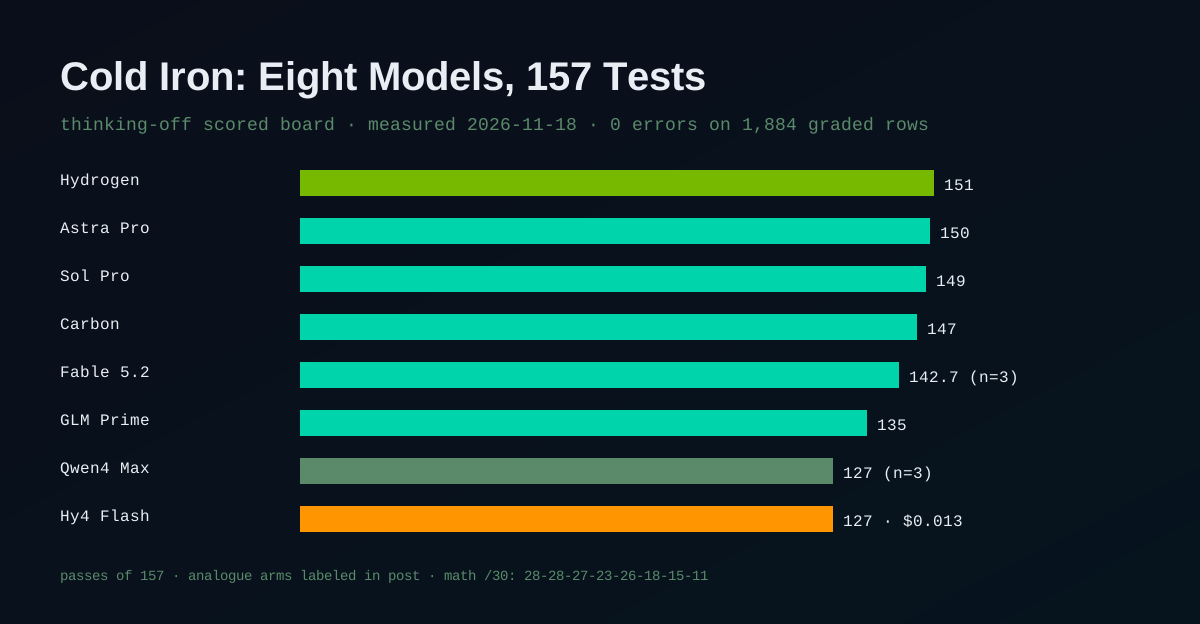
Cold Iron is our scored test: 157 items across math, coding, reasoning, instruction-following, prose, writing, and tool calling, run with thinking off. No taste, no opinions, the grader is regexes and unit tests. The OneShot companion post covers what these same eight models build; this one covers what they know.
One honest caveat before the board: five of these arms think a little even on the "off" setting, because their providers refuse to fully disable reasoning (HTTP 400 on "none"). We send each model's lowest landing effort and label every row. A row marked analogue is not identical to a row marked true off, treat the boundary between them as soft.
The board
| # | Model | Score | Runs | Wall | Cost per 157 | Arm |
|---|---|---|---|---|---|---|
| 1 | Gemini 4 Hydrogen | 151/157 (96.2%) | 1 | 23.2 min | $1.62 | analogue (low) |
| 2 | GPT-6.2 Astra Pro | 150/157 (95.5%) | 1 | 18.0 min | $4.94 | analogue (low) |
| 3 | GPT-6.2 Sol Pro | 149/157 (94.9%) | 1 | 12.9 min | $1.25 | analogue (low) |
| 4 | Gemini 4 Carbon | 147/157 (93.6%) | 1 | 43.6 min | $0.79 | low ≈ true off |
| 5 | Claude Fable 5.2 | 142.7/157 (90.9%) | 3 (141–145) | ~18 min | $3.35 avg | analogue (low) |
| 6 | GLM 5.3 Prime | 135/157 (86.0%) | 1 | 13.9 min | $0.52 | analogue (low) |
| 7 | Qwen4 Max | 127/157 (80.9%) | 3 (123–132) | ~26 min | $0.35 avg | true off (none) |
| 8 | Hy4 Flash | 127/157 (80.9%) | 1 | 9.4 min | $0.013 | true off (none) |
Zero errors on every run, all 1,884 graded rows across the twelve runs came back clean, no HTTP failures, nothing skipped. Olympic rank: Hydrogen takes #1, Astra #2, Sol #3. With n=1 runs on the new five, treat ranks 1 through 4 as a tight leading pack, not four distinct medals; Fable's three-run range (141–145) would overlap Hydrogen's single 151 only if Hydrogen had a bad day we haven't seen yet.
Per category: who's good at what
| Model | Math /30 | Coding /30 | Reasoning /30 | Instruction /30 | Prose /30 | Writing /5 | Tools /2 |
|---|---|---|---|---|---|---|---|
| Hydrogen | 27 | 30 | 29 | 30 | 29 | 4 | 2 |
| Astra Pro | 28 | 30 | 30 | 29 | 29 | 2 | 2 |
| Sol Pro | 28 | 30 | 29 | 30 | 28 | 3 | 1 |
| Carbon | 23 | 30 | 29 | 30 | 29 | 4 | 2 |
| Fable 5.2 | 26 | 30 | 30 | 27 | 26 | 4 | 2 |
| GLM 5.3 Prime | 18 | 26 | 27 | 29 | 29 | 4 | 2 |
| Qwen4 Max | 15 | 25 | 26 | 28 | 26 | 4 | 2 |
| Hy4 Flash | 11 | 27 | 26 | 28 | 30 | 3 | 2 |
(Fable row is its best of three runs; the others are their single run.)
Three patterns worth your attention:
Everyone aces coding except Prime and Qwen. Five models went 30/30 on the coding suite with zero syntax errors. GLM 5.3 Prime dropped four frontier items, assertion failures on hard algorithm work, and Qwen4 Max averaged 25. If your day is writing code, the whole top of this board is interchangeable.
Math is where the money goes. The math suite is the hardest discriminator on the board: Astra and Sol drop only 2, Hydrogen 3, Carbon 7, and then it falls off a cliff. Prime misses 12, almost all frontier-tier numeric-precision items. Qwen4 Max misses 15. Hy4 Flash misses 19. If your workload involves getting the ninth decimal place right, the top four are your only options here.
Hy4 Flash is the strangest profile in the set. Dead last on math (11/30), yet perfect 30/30 on prose, the only model to manage it. It writes beautifully and calculates like a coin flip. For $0.013 per full 157. That's the trade it's offering, and for a lot of real workloads (summarize, rewrite, classify, call this tool), it's a trade worth taking.
Costs, because they're half the story
The cheapest full run of the day was Hy4 Flash at $0.013, a full scored 157 for less than a seventh of one Astra Pro 2+2 smoke probe (Astra bills about 1,600 prompt tokens on a five-token probe, a billing quirk on the GPT-6.2 family we've verified twice; costs here are OpenRouter's usage.cost, quirks included). The most expensive was Astra at $4.94.
Put differently: you can run Hy4 Flash's entire evaluation 375 times for the cost of one Astra Pro evaluation. If Astra is 17 math items better, and your workload doesn't touch the ninth decimal place, that's a spectacularly bad trade.
Speed tells a similar story. Hy4 Flash ran the whole suite in 9.4 minutes, the fastest we've ever recorded. Astra was 18, Sol 12.9, Carbon a leisurely 43.6. Qwen4 Max is the slowest per-point on the board: 26 minutes for 80.9%.
What we'd pick
- Highest score: Gemini 4 Hydrogen. 151/157 at $1.62 is the best score-to-price ratio at the top of the board.
- Cheapest run that's still excellent: Sol Pro, 94.9% for $1.25 with the second-fastest wall of the new five.
- Bulk work for pocket change: Hy4 Flash, with eyes open about math.
- Not seeing the case for: Astra Pro at $4.94/run unless you need its #2 score and 30/30 reasoning specifically, Sol Pro is within a point for a quarter of the price. Qwen4 Max is now two tiers down from its $1.50/$4.50 price tag; the n=3 spread (123–132) doesn't reach the cheaper twins above it.
Verification notes
All scores come from stage1_*.json result files saved by the runner, one per model, with per-row costs summed from OpenRouter's usage.cost. Session key delta for the day: $10.11 across 5 new one-shots and 5 new 157s, reconciling line-by-line. Reasoning-token totals: Astra 11.4k, Sol 10.1k, Hydrogen 178.4k, Carbon 8.5k, Prime 70.4k, Hydrogen thinks a lot even on its lowest arm, which is why its row is labeled analogue. The OneShot post links the live demos.