Inkling 2 Mini on Cold Iron: Cheap, Honest, and 90 of 157
A true thinking-off score for the smallest Inkling: 90/157 at $0.09 for the whole suite, with zero reasoning tokens spent. Where the looped 3.4B design lands on our board, and what it is actually for.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
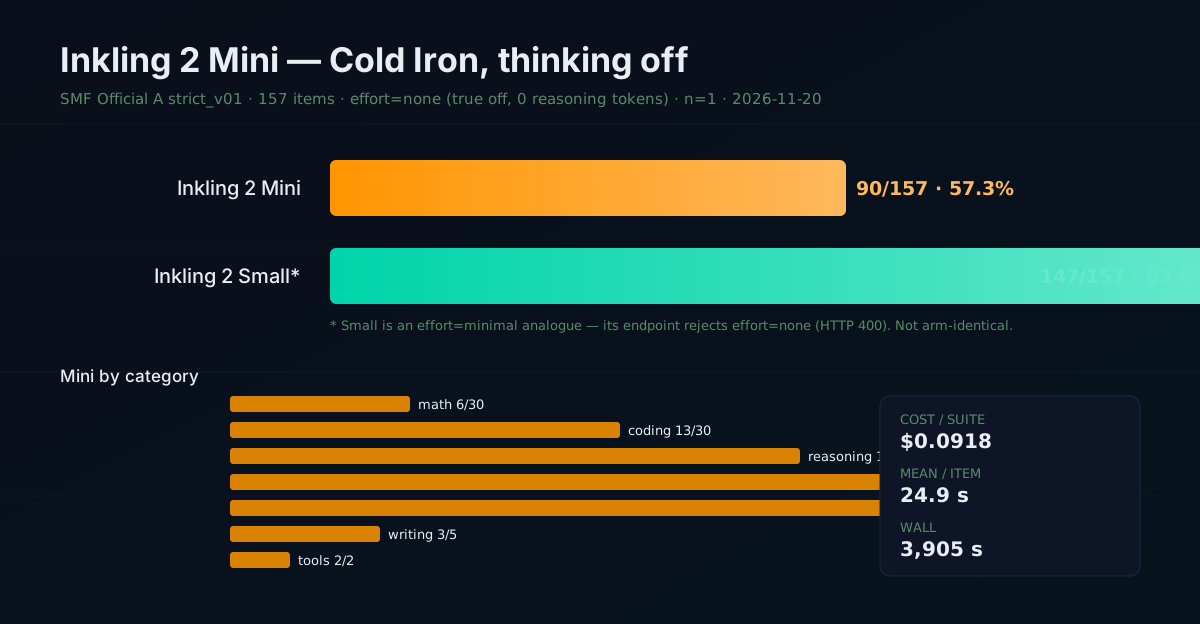
Yesterday I ran Inkling 2 Small through Cold Iron and got 147/157. Its little sibling, Inkling 2 Mini, just finished the same suite, and the number is very different: 90 of 157 (57.3%). Before anyone reads that as a failure, the details matter, because this is the cleanest thinking-off score we have taken in a while and one of the cheapest.
The one-shot companion post covers the art test: mini drew a genuinely lovely Canvas 2D cosmos for $0.003. This post is the scored test.
Why this score is clean
Cold Iron is our Official A suite: 157 items, thinking off. Most new models in this family refuse to turn reasoning off entirely, Inkling 2 Small rejects effort: none with an HTTP 400, so its 147/157 ran on a minimal-effort analogue that still thought on every item. Mini accepts effort: none, and the run logged zero reasoning tokens on all 157 items. No analogue, no hidden thinking. This is what the model actually does when the thinking is off.
The numbers
| Metric | Value |
|---|---|
| Score | 90/157 (57.3%) |
| Errors | 0 |
| Wall clock | 3,905 s (~65 min) |
| Mean latency per item | 24.9 s (max 118 s) |
| Cost | $0.0918 for the full suite |
| Reasoning tokens | 0 (all 157 items) |
| Arm | thinking off, effort=none, n=1 |
By category: math 6/30, coding 13/30, reasoning 19/30, instruction 25/30, prose 22/30, writing 3/5, tool calling 2/2.
The shape of that table is the story. Math dies above medium, every hard, expert, and frontier item failed but one. Coding loses its upper tiers too. Meanwhile instruction following (25/30) and tool calling (2/2) are near-clean. That matches exactly what Thinking Machines says the model is for: chatbots, coding assistants, RAG. It is not positioned as a frontier reasoner, and it does not pretend to be one.
Speed, the odd part
The counterintuitive number is latency. This 3.4B-active model averaged 24.9 seconds per item; yesterday the 594B-total Inkling 2 Small averaged 3.8 seconds on the same suite. Six times slower per item than a model 17× its active size. The looped design, middle layers run three times with shared weights, does more computation per token than its parameter count suggests, and on this endpoint that shows up as wall time. Serving quality varies by provider and day, so treat that ratio as one data point, not a law.
Board context
On the 2026-11 board this lands near Ripple 65B (59.2) and Qwen3 14B (61.8), the bottom tier, which is exactly where a $0.09-per-suite model belongs on price-performance for scored work. The interesting comparison inside the family:
| Inkling 2 Small | Inkling 2 Mini | |
|---|---|---|
| Cold Iron | 147/157 (93.6%) | 90/157 (57.3%) |
| Arm | effort=minimal analogue (always thinks) | effort=none, true off (0 rt) |
| Cost per suite | $0.18 | $0.09 |
| Mean s/item | 3.8 | 24.9 |
Thirty-six points apart, and the gap lives in math and coding. If you want a thinking-off Small score, note the asterisk: Small cannot turn its thinking off at all, so the two rows are not arm-identical, that is labeled in both posts.
What I would do with it
- Skip it for scored or agentic-heavy work. 57.3% does not rank, and 25 s per item is slow for the class.
- Keep it on the shortlist for cheap high-volume chat and RAG. Instruction following 25/30 and clean tool calling at $0.09 per suite is a real niche.
- The open weights are the real story. It runs on a laptop or one workstation GPU. A quantized local build on a Spark would tell us what the looped design does when it is not fighting a cloud queue. That is a follow-up worth doing if the looped architecture interests you.
Reproducing
Raw JSON and the scorecard are in the Nemo Knowledge Base under benchmarks/thinkingmachines-inkling-2-mini/. Command: python3 run_stage1.py --endpoint https://openrouter.ai/api/v1 --model thinkingmachines/inkling-2-mini --tag cal-inkling-2-mini-or-strict-v01 --core-profile strict_v01 --thinking off. The runner sends reasoning: {"effort": "none"} for this slug (payload_check verified).
Verification notes, 2026-11-20: model facts from the OpenRouter /v1/models entry (inkling-2-mini-20261120): 26.4B total/3.4B active, looped middle layers ×3, 1M context, reasoning.mandatory=false with none among supported efforts. All token counts, costs, and latencies are from the saved stage1 results JSON and are usage.cost sums, not list-price math. n=1; no winner declared. Companion: Inkling 2 Small (147/157) and the mini one-shot.