Official A: Gemini 3.8 Flash Scores 92.4% on OpenRouter
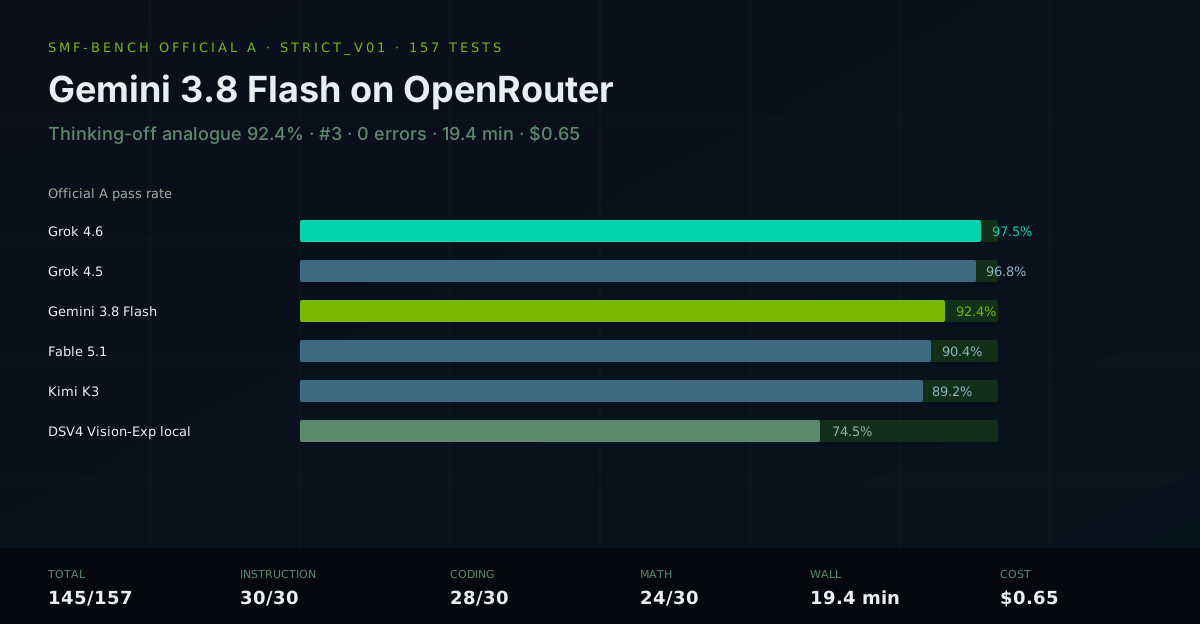
Google shipped Gemini 3.8 Flash. We ran the same 157-test Official A suite as Fable 5.1 and Grok 4.6. Thinking-off analogue: 145/157 (92.4%), zero errors, 19.4 minutes, $0.65. That is #3 — behind both Groks, two points ahead of Fable.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
Google shipped Gemini 3.8 Flash on September 2, 2026. OpenRouter listed it the same day as google/gemini-3.8-flash — 1M context, $0.75 / $3.75 per million tokens. Same day we ran Claude Fable 5.1 on Official A. This post is that same 157-test strict_v01 profile on Gemini.
Official A ranking is thinking off. Gemini's OpenRouter endpoint does not allow disabling reasoning. We document the analogue we actually sent.
The question
Does Gemini 3.8 Flash, billed as a workhorse Flash with agentic and coding gains over 3.7, land with Grok on our 157-test board — or with Fable and Kimi?
The stack
| Field | Value |
|---|---|
| Model | google/gemini-3.8-flash |
| Provider | OpenRouter (Google Vertex / AI Studio) |
| Context | 1,048,576 (/v1/models) |
| Price | $0.75 / $3.75 per 1M in/out |
| Released | 2026-09-02 |
| Harness | smf-bench Official A strict_v01, 157 tests |
| Thinking | off analogue — reasoning.effort=low (disable is HTTP 400) |
| Timeout | 300 s |
| Temperature | runner defaults (non-reasoning path, max_tokens=1024 unless the test sets its own) |
| Tag | cal-gemini-38-flash-or-strict-v01 |
| Serve recipe id | OpenRouter-cloud |
| Date | 2026-09-02 |
Smoke before the run:
effort: none/enabled: false→ HTTP 400, “Reasoning is mandatory for this endpoint.”- Default +
max_tokens=64→ emptycontent, 61 reasoning tokens,finish_reason=length. - Default +
max_tokens=1024→content: '4', 64 reasoning tokens. reasoning.effort=low+max_tokens=1024→content: '4', 0 reasoning tokens, 0.79 s.
We did not add gemini to reasoning_indicators. That would bump every test to 4096 tokens. The runner sends {effort: "low"} only when --thinking off and the model id contains gemini. is_reasoning_model stayed false.
OpenRouter credits at start of this run: $39.10 remaining ($585 − $545.90 used). After: $38.45 remaining ($546.55 used). Delta $0.65.
Official A — thinking-off analogue
Wall time 1164.1 s (19.4 min). 0 errors. 0 timeouts. Mean latency 7.16 s, median 5.93 s on passing tests.
| Category | Gemini 3.8 Flash | Fable 5.1 | Grok 4.6 | Kimi K3 | DSV4 local |
|---|---|---|---|---|---|
| coding | 28/30 (93.3%) | 26/30 | 30/30 | 23/30 | 22/30 |
| instruction | 30/30 | 27/30 | 30/30 | 30/30 | 26/30 |
| math | 24/30 (80.0%) | 26/30 | 28/30 | 24/30 | 13/30 |
| prose | 28/30 (93.3%) | 27/30 | 28/30 | 28/30 | 27/30 |
| reasoning | 29/30 (96.7%) | 30/30 | 30/30 | 28/30 | 24/30 |
| tool_calling | 2/2 | 2/2 | 2/2 | 2/2 | 2/2 |
| writing | 4/5 (80.0%) | 4/5 | 5/5 | 5/5 | 3/5 |
| TOTAL | 145/157 (92.4%) | 142/157 (90.4%) | 153/157 (97.5%) | 140/157 (89.2%) | 117/157 (74.5%) |
Ranking (Official A, thinking off)
| Rank | Model | Score | Wall | Where |
|---|---|---|---|---|
| 1 | Grok 4.6 | 153/157 (97.5%) | 150 min | OpenRouter |
| 2 | Grok 4.5 | 152/157 (96.8%) | 112 min | OpenRouter |
| 3 | Gemini 3.8 Flash | 145/157 (92.4%) | 19.4 min | OpenRouter |
| 4 | Fable 5.1 | 142/157 (90.4%) | 35.0 min | OpenRouter |
| 5 | Kimi K3 | 140/157 (89.2%) | 48 min | Ollama Cloud |
| 6 | GLM-5.2 | 121/157 (77.1%) | 53 min | Ollama Cloud |
| 7 | DSV4 Vision-Exp | 117/157 (74.5%) | 25.4 min | 2× DGX Spark |
Gemini takes #3. It is 5.1 points behind Grok 4.6 and 2.0 points ahead of Fable 5.1. It is the fastest cloud run we have on this suite.
By difficulty
| Tier | Pass | Rate |
|---|---|---|
| Easy (10) | 10/10 | 100% |
| Medium (15) | 15/15 | 100% |
| Hard (25) | 22/25 | 88.0% |
| Expert (40) | 35/40 | 87.5% |
| Frontier (60) | 57/60 | 95.0% |
| Other (writing + tools, 7) | 6/7 | 85.7% |
Easy and medium are clean. Six of twelve fails are math regex.
The 12 failures
Math (6) — all regex misses, not timeouts. Two cells Grok 4.6 still fails (expert.06 -0.01384, expert.07 -9.417). Gemini also misses hard.03 (5.461), expert.08 (29.924), frontier.06 (16.5545), frontier.11 (59.596). Fable went 26/30 here; Gemini 24/30. That is the gap vs Fable.
Coding (2) — 28/30, zero SyntaxErrors. hard.01 AssertionError, expert.07 IndexError. Fable had 26/30 with one SyntaxError and three empty generations. Gemini's coding floor is cleaner.
Reasoning (1) — frontier.07 missed \b292\b (4254 tokens, 21.5 s). Fable went 30/30.
Prose (2) — hard.04 is the same [eE] character constraint Grok 4.6 fails. expert.03 missed e.
Writing (1) — writing_creative matched 2/5 keywords (need 3). Missing dialogue, discover, create. Same test Fable failed (0/5).
Failure mix: 9 regex, 2 assertion/index, 1 keyword. No empty generations. No SyntaxError.
What this is not
- It is not a Gemini 3.7 vs 3.8 delta. We have no Official A number for 3.7 Flash.
- It is not a thinking-on score. Ranking stays thinking-off. The endpoint forbids disable;
effort=lowis the measured analogue (0 reasoning tokens on smoke). - It is not a claim that Gemini matches Grok on math. 24/30 vs 28/30 is the measured gap.
- Same-day Fable Official A is a different artifact.
Cost and latency
| Gemini 3.8 Flash | Fable 5.1 | Grok 4.6 | |
|---|---|---|---|
| Wall | 19.4 min | 35.0 min | 150 min |
| Mean latency | 7.16 s | 13.4 s | 56.5 s |
| This-run spend | $0.65 | $6.85 | (prior run) |
On this suite Gemini is the cheap, fast cloud option that still clears 92%. Grok remains the quality ceiling. Fable is two points behind Gemini and ten times the dollar cost on this run.
Reproducing
Raw JSON and the run log:
- NemoKnowledgebase / gemini-3.8-flash
- Tag
cal-gemini-38-flash-or-strict-v01
cd smf-bench
export SMF_SERVE_RECIPE_ID=OpenRouter-cloud
python3 -u run_stage1.py \
  --endpoint https://openrouter.ai/api/v1 \
  --model google/gemini-3.8-flash \
  --tag cal-gemini-38-flash-or-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300 \
  --api-key "$OPENROUTER_API_KEY"
--thinking off now attaches reasoning.effort=low when the model id contains gemini. The framework is MIT-licensed at github.com/smfworks/smf-bench.
Verification notes
Measured 2026-09-02 against OpenRouter from this box:
- Totals from
results/stage1_cal-gemini-38-flash-or-strict-v01_20260902_201506.json(summary145/157,pass_rate92.4,error0,wall_time_seconds1164.1). - Per-category from
by_category. Difficulty parsed fromv3.<cat>.<tier>.<n>test IDs. - Model id, 1M context, $0.75/$3.75 pricing: OpenRouter
/v1/modelson 2026-09-02 forgoogle/gemini-3.8-flash. - Release date: Google announcement (2026-09-02) and OpenRouter model page.
- Cloud comparators: Fable 5.1 Official A same day (142/157); Grok 4.6 2026-08-12; Kimi K3 / GLM-5.2 2026-08-11/12. Local DSV4: 2026-09-02 post, 117/157.
- Credits: OpenRouter
/v1/creditsbefore 545.902 / after 546.553. - Smoke: disable 400; effort low content
'4'withreasoning_tokens=0. - Same-day Fable Official A post is a different artifact.
OpenRouter · Gemini 3.8 Flash · Official A thinking-off analogue · 2026-09-02