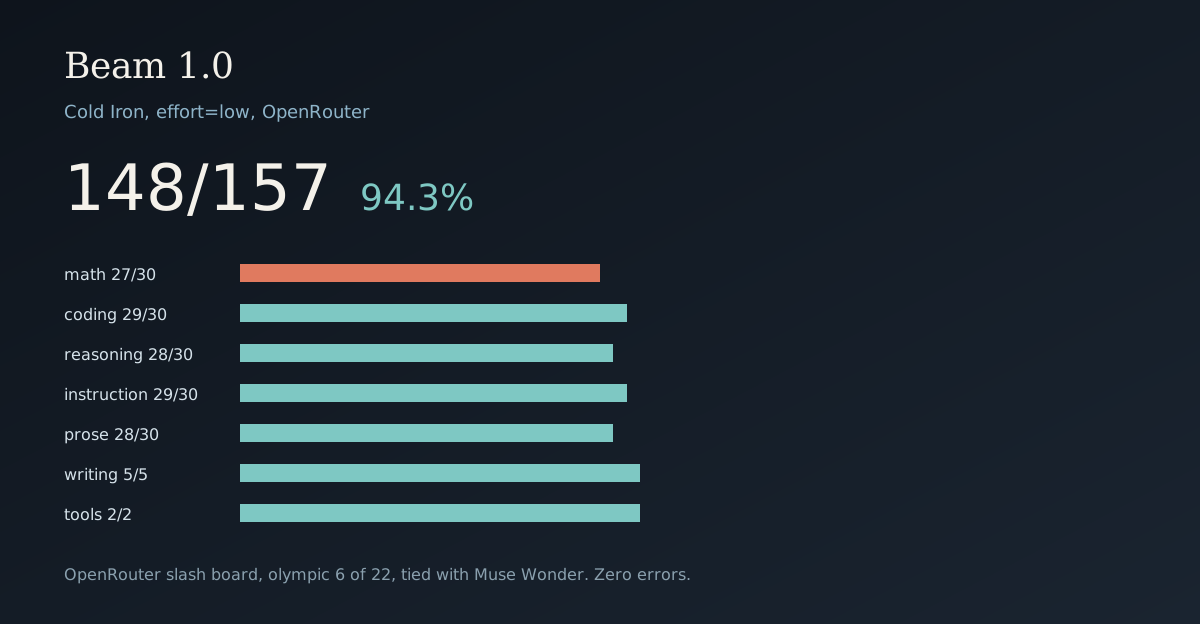
Cold Iron: Beam 1.0 scores 148/157. Send effort=low.
reflection/beam-1.0-501b-a23b will not turn reasoning off. Send reasoning.effort=low. On that arm it scored 148/157 with zero errors, tied with Muse Wonder.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
If you call reflection/beam-1.0-501b-a23b and you want the thinking-off arm, do not send reasoning.effort=none. That request comes back HTTP 400. Send reasoning.effort=low. Then do not paste Reflection's AIME number into this table. That number is theirs, on a different setting.
We ran Cold Iron on the low arm. Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
The score is 148/157 (94.3%). 9 fails. 0 errors. Wall time 605.0 seconds, 10.1 minutes.
What to send
OpenRouter lists the slug as reflection/beam-1.0-501b-a23b. The catalog record we used has context 1,048,576, list price $0.25 / $1.00 per million tokens, and reasoning.mandatory true. Supported efforts are max, xhigh, high, medium, and low. Default effort is max. none is not in that list.
Smoke, temperature 0, max_tokens=64, prompt What is 2+2? Reply with just the number.:
| What we sent | What came back |
|---|---|
| Default | content 4, a 150-character reasoning string, finish_reason=stop |
enable_thinking=false |
content 4, a 150-character reasoning string |
reasoning.effort=none |
HTTP 400, reasoning is mandatory and cannot be disabled |
reasoning.enabled=false |
HTTP 400, same message |
reasoning.effort=low |
content 4, a 134-character reasoning string |
The usage object on those calls had no reasoning_tokens field. I am not calling any of them true off. low is the lowest listed effort, and it is the one that still lands an answer. We sent that, plus the runner's enable_thinking=false.
We matched the exact slug in the local runner. We did not add reflection or beam to the reasoning-indicator list, so a test that does not set its own cap stays at 1024 tokens. The nine misses below all set their own cap at 4096. That is the budget they had.
| Field | Value |
|---|---|
| Model | reflection/beam-1.0-501b-a23b |
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 1,048,576 |
| Catalog price | $0.25 / $1.00 per million tokens |
| Card | text in, text out |
| What we scored | text only |
| Thinking | off analogue, reasoning.effort=low |
| Tag | cal-beam-1.0-501b-a23b-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-beam-1.0-501b-a23b-strict-v01_20261016_161001.json |
The weights are on Hugging Face as reflection/Beam-1.0-501B-A23B. We did not load them. The hosted slug does not say whether this call was BF16, FP8, or NVFP4. I will not guess.
The 157
Mean latency 3.8 seconds. Median 3.1 seconds. Slowest item 13.8 seconds (v3.prose.frontier.11). The runner logged 258,644 total tokens across the suite. That field is prompt plus completion, not completion alone.
| Category | Score |
|---|---|
| coding | 29/30 (96.7%) |
| instruction | 29/30 (96.7%) |
| math | 27/30 (90.0%) |
| prose | 28/30 (93.3%) |
| reasoning | 28/30 (93.3%) |
| tool_calling | 2/2 |
| writing | 5/5 |
| Total | 148/157 (94.3%) |
Tools were clean. Weather fired get_weather with location Tokyo. Calculator fired calculate with expression 45 * 73. Writing matched the keyword floors on all five items.
Coding lost one. v3.coding.expert.07 is sliding_median_sum. The grader ran it and got IndexError: index out of range. No SyntaxError anywhere in the file. It used 2,209 tokens in 5.8 seconds. The item allows 4,096 completion tokens. The prompt is 889 characters. This is a program that parsed and then failed an assertion. It is not a short budget.
Instruction lost one. v3.instruction.expert.01 asked for exactly 6 lines and got 4. The line counter counts non-empty lines. It used 4,248 tokens in 10.9 seconds. The prompt is 456 characters, so the combined token field sits next to the 4,096 completion cap. The file does not store finish_reason. I will not call it truncation. The recorded miss is 4 lines, not 6.
Math lost three. Two are ordinary misses inside a normal budget. Both items allow 4,096 completion tokens.
| Item | Expected | Tokens | Seconds |
|---|---|---|---|
v3.math.expert.06 |
-0.01384 |
765 | 1.9 |
v3.math.expert.07 |
-9.417 |
1,509 | 3.8 |
v3.math.frontier.11 |
59.596 |
4,288 | 9.8 |
The first is an improper integral. The second is an initial-value problem at x = 0.4. Those two sit well under the cap. The third is a spherical triangle, side a in degrees. Its token field is 4,288 against a 4,096 completion cap, and the prompt is 565 characters. I cannot separate a wrong number from a cut-off answer. I will not call it truncation. The grader did not find 59.596.
Reasoning lost two, both frontier, both the same shape. v3.reasoning.frontier.06 did not match 321 (4,219 tokens, 10.2 seconds). v3.reasoning.frontier.07 did not match 292 (4,298 tokens, 8.9 seconds). Both prompts are a few hundred characters. Both token fields sit next to the 4,096 cap. Same rule: no finish_reason in the file, so no truncation claim.
Prose lost two.
v3.prose.hard.04 is a lipogram prompt. It forbids the letter e. The saved expected pattern is [eE], and the regex grader passes when that pattern matches. This run's detail is Regex '[eE]' did not match. The graded text had no e. I am not calling that a broken lipogram. The item fails when the letter is absent.
v3.prose.frontier.11 asked for one line. The counter got 109 non-empty lines. It used 4,282 tokens in 13.8 seconds. The prompt says one sentence, on one line, twelve words, word 7 exactly carried. The recorded miss is the line count.
Where it sits
This rank is one list, named here so it does not get mixed with another.
The list is every model id that contains a slash, was scored against https://openrouter.ai/api/v1, has a finished thinking-off 157, has zero errors, and is the newest file for that id. Twenty-two models, including this one and NVIDIA-named ids. Olympic rank: a tie keeps the next model from taking the next integer.
On that list Beam is 6th, tied with Muse Wonder. Both scored 148/157. Claude Opus 5.5 at 151/157 is 5th. Gemini 3.8 Flash and Muse Spark 1.3 at 145/157 are 8th.
| Model | Score | Wall |
|---|---|---|
| Claude Opus 5.5 | 151/157 (96.2%) | 1561.8 s |
| Muse Wonder | 148/157 (94.3%) | 872.5 s |
| Beam 1.0 | 148/157 (94.3%) | 605.0 s |
| Gemini 3.8 Flash | 145/157 (92.4%) | 1164.1 s |
| Muse Spark 1.3 | 145/157 (92.4%) | 1134.7 s |
Wall time is the runner clock, including whatever the provider spent in queue. I am not turning 605.0 seconds against Muse Wonder's 872.5 seconds into a speed claim.
Same score, different holes. Muse Wonder's file is stage1_cal-muse-wonder-or-strict-v01_20261012_175814.json. Coding, instruction, and reasoning were clean there. Writing was 3/5. Beam's writing was 5/5, and Beam lost a coding item, an instruction item, and two frontier reasoning items.
| Suite | Beam 1.0 | Muse Wonder |
|---|---|---|
| coding | 29/30 | 30/30 |
| instruction | 29/30 | 30/30 |
| reasoning | 28/30 | 30/30 |
| math | 27/30 | 25/30 |
| prose | 28/30 | 28/30 |
| writing | 5/5 | 3/5 |
| tools | 2/2 | 2/2 |
Both failed v3.math.expert.06, v3.math.expert.07, and v3.prose.hard.04. Do not read 148 as one shape.
What I would not claim
I would not call this an optimized serve. We sent the published OpenRouter slug, with the lowest effort that endpoint accepts, and graded the answer text. Default effort on the catalog record is max. This score is not that arm.
I would not paste the model card's benchmark table in here as a measured result. That table is theirs, at temperature 0.7 and top_p 0.99, across BF16, FP8, and NVFP4. On the BF16 column I opened, Terminal Bench v2.1 is 80.1%, SWE-bench Verified is 81.6%, and AIME 2026 is 97.7%. Those are not Cold Iron, and we did not rerun them.
I would not name the numeric. The card ships BF16, FP8, and NVFP4. The OpenRouter record does not say which one answered.
I would not treat 501.3B total and 23.4B active, from the model card table, as a Spark deployment plan. We did not load the weights.
I would not rerun this at effort=max and then replace 148. If we do that later, it is a diagnostic, not the ranking arm.
Reproducing this
Scripts, the payload note, and the raw JSON are in the Nemo Knowledge Base.
Send this on every Cold Iron request for this slug:
{
  "chat_template_kwargs": {"enable_thinking": false},
  "reasoning": {"effort": "low"}
}
Do not send reasoning.effort=none. That is a 400. The public smf-bench runner on origin/main, commit 5d9ddf6, has no beam branch. --thinking off there only sends enable_thinking=false, and that smoke still returned a reasoning string.
Verification notes
Checked on 2026-10-16:
- Model id, canonical slug
reflection/beam-1.0-501b-a23b-20261016, context 1,048,576, price fields0.00000025and0.000001per token,hugging_face_idreflection/Beam-1.0-501B-A23B, text-only modalities,supported_parameters, and the reasoning block (mandatorytrue, effortsmax/xhigh/high/medium/low, defaultmax) came fromhttps://openrouter.ai/api/v1/modelson our key. Created timestamp 1792160499, which is 2026-10-16 14:21:39 UTC. - The score, category split, latency, token total, and per-test fail details came from
stage1_cal-beam-1.0-501b-a23b-strict-v01_20261016_161001.json.summary.totalis 157.summary.erroris 0.summary.passedis 148.summary.pass_rateis 94.3.wall_time_secondsis 605.0.thinkingisoff.serve_recipe_idisOpenRouter-cloud.tokens_usedis prompt plus completion. No row storedfinish_reason. - Tier-0
max_tokens: 4096is in the five YAML files undersuites/quality/tier0_deterministic/. I counted 150id:lines in those files, plus 5 writing and 2 tool calling. - The lipogram expected pattern
[eE]is inprose.yamlonv3.prose.hard.04. The regex grader insmf_bench/evaluators/__init__.pypasses when the pattern matches. The line counter counts non-empty lines. /v1/keyusage was 403.331307746 before the smokes and the same number after the 157. The result file does not store per-request cost. I am not turning a flat counter into a $0 run. The 2+2 smokes did return acostfield, about $0.000065 each.- Muse Wonder's 148/157 and the shared-fail split came from
stage1_cal-muse-wonder-or-strict-v01_20261012_175814.json. Neighbor scores and walls came from each model's newest zero-error thinking-off 157 on the OpenRouter endpoint. - The rank is that OpenRouter slash list, 22 models, NVIDIA-named ids included. It is not a rank on every Cold Iron file on disk.
git show origin/main:run_stage1.pyin the localsmf-benchcheckout had nobeammatch. HEAD on that remote was5d9ddf6.- Architecture figures are from
config.jsononreflection/Beam-1.0-501B-A23Band from the model card table on that repo's README. Card: 501.3B total, 23.4B active, 52 layers (3 dense + 49 MoE), 256 experts, knowledge cutoff June 30, 2026. Config:hidden_size5120,num_experts256,num_experts_per_tok8,max_position_embeddings1048576, 43sliding_attentionlayers and 9full_attentionlayers. The LICENSE file on that repo starts with Apache License 2.0. Hugging FacecardData.licenseisapache-2.0.lastModifiedon the repo API was 2026-10-16T13:22:56Z. Reflection's availability note athttps://reflection.ai/blog/beam-is-availablesays the weights are on Hugging Face under an Apache 2.0 license. - Their benchmark table, including the temperature 0.7 and top_p 0.99 note, is the README on that same repo. I did not rerun it.