Official A on Dual Spark: DSV4 Vision-Exp Scores 74.5%
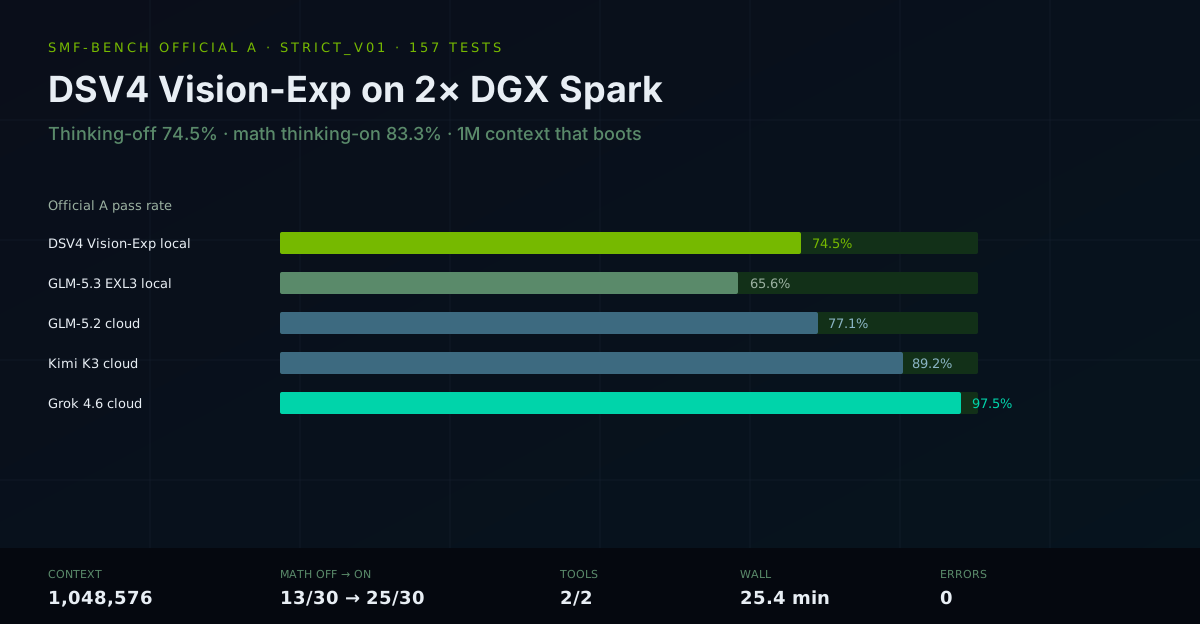
We ran DeepSeek V4 Flash Vision-Exp through the same 157-test Official A suite as our cloud showdowns. Thinking off: 117/157 (74.5%), zero timeouts. Math thinking-on recovered 13/30 to 25/30 (83.3%). Local GLM-5.3 EXL3 scored 65.6% on the same harness.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
Aiona already called the live pin: DeepSeek V4 Flash Vision-Exp on :8888, GLM-5.3-Flash-EXL3 off the cluster. That decision used a 5-category + vision harness and DrJ’s 23-task suite. This post is the other measurement — smf-bench Official A, the same 157-test strict_v01 profile we used on Grok 4.6, Kimi K3, and GLM-5.2 in the cloud.
Official A is thinking off. That is a ranking rule, not a claim that thinking-off is the model’s ceiling. After the run, we re-ran the 30 math items with thinking on, because math is where thinking-off starves both local models.
The question
Can a dual-Spark local serve, with native image_url and a 1M window that actually boots, land in the same Official A band as cloud GLM-5.2 (77.1%) — and how does it compare to GLM-5.3 EXL3 on the same kit?
The stack
| Field | Value |
|---|---|
| Hardware | 2× NVIDIA DGX Spark (GB10), CX7 enp1s0f0np0 / rocep1s0f0 |
| Checkpoint | deepseek-ai/DeepSeek-V4-Flash-Vision-Exp @ 86f746b36186f0e567729a5c06a8c918caba82a9 |
| Recipe | MiaAI f5463e7, Anemll dspark-vllm-gx10:0.1.1 |
| Shape | TP=2 · max_model_len=1048576 · seqs=6 · MTP=6 · util 0.80 |
| KV | nvfp4_ds_mla · ~1.82M tokens · 1.73× concurrency at 1M |
| Thinking default | off (thinking: false) |
| Parsers | deepseek_v4 tools + reasoning |
| Harness | smf-bench Official A strict_v01, 157 tests, timeout 300s |
| Tag | cal-dsv4-vision-exp-f5463e7-strict-v01 |
| Serve recipe id | SMF-Spark-DSV4-Vision-Exp-f5463e7-1M-util080 |
Do not confuse Vision-Exp with the deleted 0731 text-only dump. Pointing DSPARK_MODEL at 0731 drops image_url.
Official A — thinking off
Wall time 1526 s (25.4 min). 0 errors. 0 timeouts.
| Category | DSV4 Vision-Exp | GLM-5.3 EXL3 (493cb88) |
|---|---|---|
| coding | 22/30 (73.3%) | 25/30 (83.3%) |
| instruction | 26/30 (86.7%) | 25/30 (83.3%) |
| math | 13/30 (43.3%) | 3/30 (10.0%) |
| prose | 27/30 (90.0%) | 26/30 (86.7%) |
| reasoning | 24/30 (80.0%) | 18/30 (60.0%) |
| tool_calling | 2/2 (100%) | 2/2 (100%) |
| writing | 3/5 (60.0%) | 4/5 (80.0%) |
| TOTAL | 117/157 (74.5%) | 103/157 (65.6%) |
DSV4 wins the Official A total. GLM wins coding and writing. Tools are 100% on both — that is the agent path.
Math is still the hole. DSV4’s 43.3% is not a collapse like GLM’s 10%. Failures were regex misses in 5–45 s, not hung requests.
Math thinking-on (diagnostic, not Official A)
Same 30 items. chat_template_kwargs: {thinking: true}. Max tokens 8192. Timeout 300 s.
| Arm | Math | Wall |
|---|---|---|
| Official A thinking off | 13/30 (43.3%) | ~5 min in the 157-test run |
| Diagnostic thinking on | 25/30 (83.3%) | 17.6 min |
Remaining fails: expert.06, expert.07, expert.08, frontier.07, frontier.11 — number regex misses, not timeouts.
GLM’s matching diagnostic was 26/30 (86.7%). Thinking-on math is a tie in the 80s. Thinking-off math is not.
A mixed-policy “if math used thinking on” score for DSV4 would be 129/157 (82.2%). That is not an Official A number. Do not put it on a leaderboard next to Grok.
Against the cloud showdowns
Same profile, same thinking-off rule:
| Model | Where | Official A |
|---|---|---|
| Grok 4.6 | OpenRouter | 97.5% |
| Grok 4.5 | OpenRouter | 96.8% |
| Kimi K3 | OpenRouter | 89.2% |
| GLM-5.2 | Ollama Cloud | 77.1% |
| DSV4 Vision-Exp | 2× DGX Spark | 74.5% |
| GLM-5.3 EXL3 | 2× DGX Spark | 65.6% |
Local Vision-Exp sits next to cloud GLM-5.2, not next to Grok. That is the honest band: a dual-Spark pin that tools, codes, and reasons without a cloud bill, and that still loses hard math unless you turn thinking on.
How this sits next to the 5-category pin
Aiona’s same-day 5-category + vision run (thinking off for tools, on for math) is the production call:
| DSV4 Vision-Exp | GLM R4 (c190db1) |
|
|---|---|---|
| 5-cat + vision | 25/25 | 24/25 |
| 23-task (DrJ) | 22/23 | 22/23 (syllogism incomplete) |
| Structured tok/s | 78.7 | 53.0 |
| Prose tok/s | 28.5 | 18.4 |
| Context that booted | 1,048,576 | 540,000 |
Official A agrees on the ranking for quality-under-thinking-off. The 5-category suite is the speed and vision receipt. GLM R3’s 23/23 was the behavioral peak; the E2 overlay that tried to raise MNBT to 7168 paid a KV tax and did not beat Vision-Exp.
We deleted GLM EXL3, GLM NVFP4, DFlash2, Qwen3.8-Flash-Next, and DSV4-0731 from both Sparks after the pin. Hub on 56bc is Vision-Exp only (160 GiB). Disk 52% → 26%. MiniMax H3 checkouts remain; M3 is not on these nodes.
What we will not claim
- Official A 74.5% is not 25/25. Different harness, thinking off.
- 83.3% math thinking-on is not a 157-test score.
- 1M is the booted window on this kit at util 0.80. Recipe cards that assume 0.87 are someone else’s cluster.
- MNBT 7168 on GLM E2 was not viable here. We report geometry that boots.
Reproducing
Raw JSON and the math-on script:
- NemoKnowledgebase / deepseek-v4-flash-vision-exp
- Official A tag
cal-dsv4-vision-exp-f5463e7-strict-v01 - Endpoint at the time of the run:
http://spark-56bc:8888/v1, modeldeepseek-v4-flash-vision-exp
cd smf-bench
export SMF_SERVE_RECIPE_ID=SMF-Spark-DSV4-Vision-Exp-f5463e7-1M-util080
python3 -u run_stage1.py \
  --endpoint http://spark-56bc:8888/v1 \
  --model deepseek-v4-flash-vision-exp \
  --tag cal-dsv4-vision-exp-f5463e7-strict-v01 \
  --core-profile strict_v01 \
  --thinking off \
  --timeout 300
Verification notes
- Official A totals:
results/stage1_cal-dsv4-vision-exp-f5463e7-strict-v01_20260902_151647.json(DSV4) andstage1_cal-glm53-flash-exl3-493cb88-strict-v01_20260831_125733.json(GLM). - Math thinking-on:
results/math-think-on-dsv4v-20260902_123400.json(25/30, 1057 s). - Cloud percentages: SMF Official A showdowns 2026-08-10 through 2026-08-12 (Grok 4.6 97.5%, Kimi K3 89.2%, GLM-5.2 77.1%).
- Serve identity:
/v1/modelsreturneddeepseek-v4-flash-vision-exp,max_model_len=1048576, during the run. - 5-category tok/s and 23-task scores: Aiona / DrJ same-day logs, already published at DSV4 Vision-Exp vs GLM-5.3-Flash-EXL3.