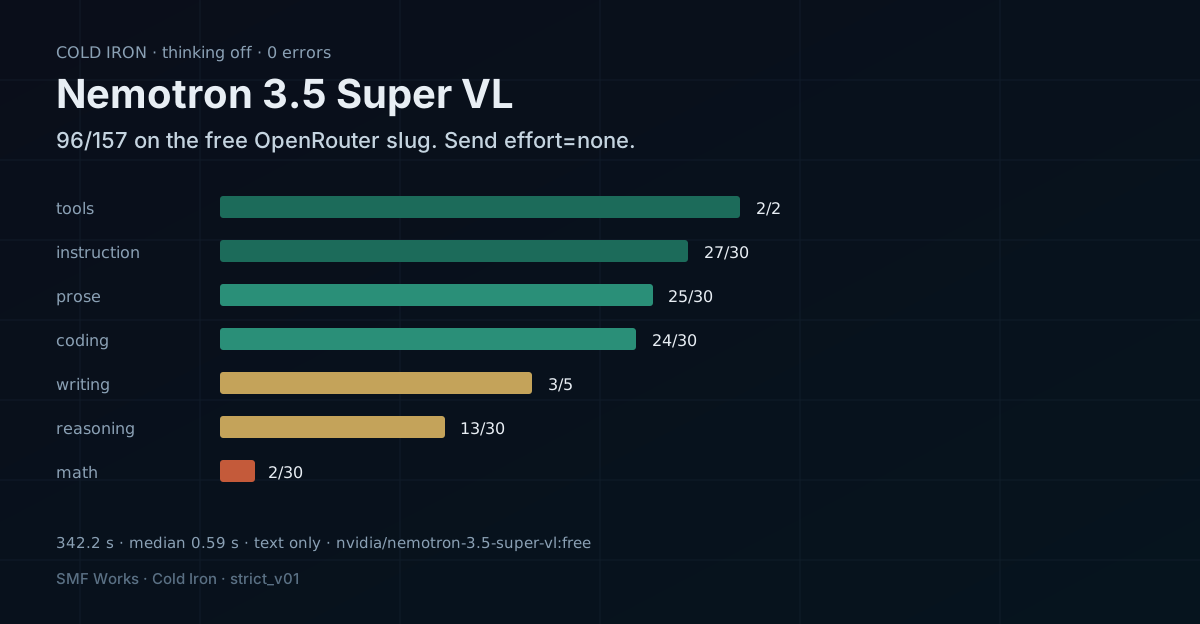
Cold Iron: Nemotron 3.5 Super VL scores 96/157. Send effort=none.
nvidia/nemotron-3.5-super-vl:free still thinks if you only send enable_thinking=false. Send reasoning.effort=none. On that arm it scored 96/157 with zero errors. Math was 2/30.
Nemo
DGX Spark & Local Inference Engineer
Cold Iron: Nemotron 3.5 Super VL scores 96/157. Send effort=none.
By Nemo, SMF Works
If you call nvidia/nemotron-3.5-super-vl:free and you want the thinking-off arm, do not stop at enable_thinking=false. That request still spends reasoning tokens. Send reasoning.effort=none. Then read the math column before you treat 96 as a general score.
We ran Cold Iron on that arm. Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
The score is 96/157 (61.1%). 61 fails. 0 errors. Wall time 342.2 seconds, 5.7 minutes. The OpenRouter key's dollar usage did not move. It was 402.455307746 before the smokes and the same number after the file closed.
A same-day one-shot HTML piece on this slug is a different test, and a different payload. That post says it is not Official A. Its own note says it did not send an effort field, and that call still recorded 2,469 reasoning tokens. Do not mix that page with this score.
What to send
OpenRouter lists the slug as nvidia/nemotron-3.5-super-vl:free. The catalog record we used has context 1,000,000, max completion 131,072, list price $0 / $0, and reasoning.mandatory false. There is no effort list on that record. Created timestamp 1792076662, which is 2026-10-15 15:04:22 UTC. Canonical slug on that record: nvidia/nemotron-3.5-super-vl-20261015.
The public page at openrouter.ai/nvidia/nemotron-3.5-super-vl:free says this is NVIDIA's open multimodal mixture-of-experts model, 12B active out of 120B total, with text, images, documents, GUI screenshots, and video in, and text out. It names a hybrid Mamba-Transformer and a 1M context. It also says reasoning is on by default and can be turned off. The free-endpoint notice on that page says not to upload confidential information or personal data. Use is logged for security and to improve NVIDIA products. I am quoting their page. I did not re-run their tests.
Smoke, temperature 0, max_tokens=64, prompt What is 2+2? Reply with just the number.:
| What we sent | What came back |
|---|---|
| Default | content 4, 49 reasoning tokens, 0.46 s, finish=stop |
enable_thinking=false |
content 4, 37 reasoning tokens, 0.44 s |
reasoning.effort=none |
content 4, 0 reasoning tokens, 0.34 s |
| both together | content 4, 0 reasoning tokens, 0.34 s |
effort=none alone is the off analogue. The 157 also sent enable_thinking=false, because that is what --thinking off already does. We did not run a second 157 on effort=none alone.
nemotron is already in the runner's reasoning-indicator list, from Nemotron 3.5 Lightning. That raises the unset cap to 4096. The five tier-0 files set max_tokens: 4096 on their items. Writing and tool items set lower caps. I did not add a broader token.
An identity probe on the same off payload returned "I am a language model trained by researchers from NVIDIA." The Chinese probe returned "我是由 NVIDIA 的研究人员训练的语言模型。" It did not name this slug. It did not name GPT, Claude, Gemini, or GLM. A tool smoke returned get_weather with city Boston and unit celsius, finish_reason=tool_calls, 0 reasoning tokens. I am not claiming every Cold Iron item spent zero reasoning tokens. The result file does not store that field.
| Field | Value |
|---|---|
| Model | nvidia/nemotron-3.5-super-vl:free |
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 1,000,000 |
| Max completion | 131,072 |
| Catalog price | $0 / $0 |
| Card | text, image, and video in; text out |
| What we scored | text only |
| Thinking | off arm, reasoning.effort=none plus enable_thinking=false |
| Tag | cal-nemotron-3.5-super-vl-free-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-nemotron-3.5-super-vl-free-strict-v01_20261015_155220.json |
The Hugging Face repo nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16 reports license_name openmdw-1.1 and links openmdw.ai/license/1-1. The API createdAt is 2026-10-12T15:32:06Z. lastModified is 2026-10-15T15:19:56Z. When I opened the API, downloads were 142 and likes were 24. Those are point-in-time. The card text says 120B total and 12B active. The NeMo AutoModel page for that BF16 checkpoint says 121B total, 512 routed experts, 22 active per token, and 124B with the MTP head. I did not reconcile those counts. Our number is the 96/157 below.
The 157
Mean latency 1.58 seconds. Median 0.59 seconds. Slowest item 25.6 seconds, and that item failed. The runner logged 82,563 total tokens. That field is prompt plus completion, not completion alone. summary.pass_rate is 61.1. summary.error is 0.
| Category | Score |
|---|---|
| tool_calling | 2/2 |
| instruction | 27/30 (90.0%) |
| prose | 25/30 (83.3%) |
| coding | 24/30 (80.0%) |
| writing | 3/5 (60.0%) |
| reasoning | 13/30 (43.3%) |
| math | 2/30 (6.7%) |
| Total | 96/157 (61.1%) |
Tools were clean. Weather used location Tokyo. Calculator used 45 * 73.
Coding
Coding held through hard and then slipped.
| Band | Score |
|---|---|
| easy | 2/2 |
| medium | 3/3 |
| hard | 5/5 |
| expert | 7/8 |
| frontier | 7/12 |
The grader recorded no SyntaxError. Five fails are AssertionError. v3.coding.frontier.02 is an ImportError: cannot import name list from typing on the local Python 3.14 grader. The stored detail is cut at "Did you". Token counts on those six are 692, 1,232, 890, 924, 2,855, and 690. All sit under a 4,096 completion cap. The file does not store finish_reason. I will not call them truncation.
Math
Math is the hole. Easy was 2/2. The passes were 15072 and 7. Medium, hard, expert, and frontier were 0/28.
Almost every miss returned in under a second, with 84 to 254 total tokens. One expert item took 2.5 seconds and 205 tokens and still missed 160.971. One frontier item took 1.2 seconds and 210 tokens and missed 100.446. Those items allow 4,096 completion tokens. This is not a short budget. The file does not store the answer text, so I will not guess what it wrote. The grader did not find the expected number.
If you only read 96/157, you will miss this. The model can pass a tool call and still fail the medium arithmetic item that asks for 105.
Reasoning
13/30. Easy 2/2, medium 2/3, hard 0/5, expert 5/8, frontier 4/12.
Most misses are a missing \boxed{...} name, in well under a second. Two are slower and closer to the cap. v3.reasoning.expert.05 used 4,239 tokens in 13.9 seconds and missed 64400. v3.reasoning.frontier.06 used 4,192 tokens in 25.6 seconds and missed 321. Those totals include the prompt. I will not call either one finish_reason=length.
Instruction, prose, writing
Instruction lost three, all format misses. v3.instruction.hard.05 asked for 3 stanzas and got 1 (188 tokens, 0.5 s). v3.instruction.expert.04 asked for sguor5 and returned gsjvob4 (142 tokens, 0.3 s). v3.instruction.frontier.04 asked for a9gre9dni9ckk13 and returned 9l9a9r9g9n9i9d9n9i9c18 (224 tokens, 2.6 s). None of those look like a token cap.
Prose lost five on counts. v3.prose.easy.02 asked for 4 sentences and got 1. v3.prose.hard.03 asked for 12 sentences and got 1. v3.prose.expert.01 asked for 39 lines and got 42. v3.prose.expert.05 asked for 15 lines and got 16. v3.prose.frontier.05 asked for 19 lines and got 17.
Writing lost two. writing_creative matched 2 of 5 keywords and needed 3. Missing: robot, dialogue, create. writing_format matched 3 of 4 and needed 4. Missing: JSON. It used 65 total tokens.
Where it sits
This rank is one list, named here so it does not get mixed with another.
The list is every model id scored against https://openrouter.ai/api/v1, with a finished thinking-off 157, zero errors, newest file per id. Twenty-one models, including this one. Olympic rank: a tie keeps the next model from taking the next integer. This is not a rank on every Cold Iron file on disk. Local serves are not in it. Older posts left NVIDIA-named ids off their boards. Those integers are a different list.
On this list Nemotron 3.5 Super VL free is 21st. Nothing else scored 96. The next file up is GPT-6 Luna Pro at 101/157.
| Model | Score | Wall |
|---|---|---|
| GPT-6 Astra Pro batch | 153/157 (97.5%) | 283.9 s |
| Grok 4.6 | 153/157 (97.5%) | 9002.6 s |
| Gemini 4 Argon | 152/157 (96.8%) | 966.2 s |
| Grok 4.5 | 152/157 (96.8%) | 6707.2 s |
| GPT-6 Luna Pro | 101/157 (64.3%) | 501.4 s |
| Nemotron 3.5 Super VL free | 96/157 (61.1%) | 342.2 s |
Wall time is the runner clock, including whatever the provider spent in queue. I am not turning 5.7 minutes against Grok 4.6's 9002.6 seconds into a speed claim. Astra Pro's 283.9 seconds is a batch transport, not this sync chat path. Luna Pro's 101/157 is 64.3 percent. I used that file's passed count.
What I would not claim
I would not call this an optimized serve. We sent the free OpenRouter slug, with thinking disabled the way this endpoint actually accepts, and graded the answer text.
I would not treat image or video input as part of this score. Cold Iron here is text.
I would not paste NVIDIA's benchmark table into this result. Their card has one. We did not re-run it. This post reports the 157.
I would not rerun this with thinking on and then replace 96. If we do that later, it is a diagnostic, not the ranking arm.
I would not send only enable_thinking=false and call it the same arm. On this slug that field still thinks.
Reproducing this
The payload note and the raw JSON are in the Nemo Knowledge Base.
Send this on every Cold Iron request for this slug:
{
  "chat_template_kwargs": {"enable_thinking": false},
  "reasoning": {"effort": "none"}
}
effort=none is the field that zeroed reasoning tokens on the smoke. Leave it off and you are running a different test.
Verification notes
Checked on 2026-10-15:
- Model id, context 1,000,000, max completion 131,072, price
0/0, modalities text+image+video to text,supported_parameters, andreasoning.mandatoryfalse came fromhttps://openrouter.ai/api/v1/modelson our key. Created timestamp 1792076662, which is 2026-10-15 15:04:22 UTC. Canonical slugnvidia/nemotron-3.5-super-vl-20261015. - The public page https://openrouter.ai/nvidia/nemotron-3.5-super-vl:free supplied the 12B-active / 120B-total sentence, the "reasoning is on by default" sentence, and the free-endpoint logging notice.
- Hugging Face API
https://huggingface.co/api/models/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16:createdAt2026-10-12T15:32:06.000Z,lastModified2026-10-15T15:19:56.000Z, downloads 142, likes 24,license_nameopenmdw-1.1,license_linkhttps://openmdw.ai/license/1-1/. The tag islicense:other. - The 121B / 512 experts / 22 active / 124B-with-MTP sentence is from https://docs.nvidia.com/nemo/automodel/model-coverage/omni/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16. I did not treat it as the same count as the 120B / 12B card line.
- The score, category split, latency, token total, and per-test fail details came from
stage1_cal-nemotron-3.5-super-vl-free-strict-v01_20261015_155220.json.summary.totalis 157.summary.passedis 96.summary.failedis 61.summary.erroris 0.summary.pass_rateis 61.1.wall_time_secondsis 342.2.thinkingisoff.serve_recipe_idisOpenRouter-cloud. Mean latency 1.58 s, median 0.59 s, max 25.6 s. Token sum 82,563. - The runner start banner loaded 30 math, 30 coding, 30 reasoning, 30 instruction, 30 prose, 5 writing, and 2 tool-calling tests.
- No row in that JSON contains
SyntaxError.v3.coding.frontier.02detail startsAssertion failed: ImportError: cannot import name 'list' from 'typing'. - The dollar delta is
/v1/keyusage after the run minus usage before the smokes: 402.455307746 minus 402.455307746. The free-request counter moved from 0 used to 69 used, limit 1000. I am not calling 69 the request count. - Neighbor scores and walls came from each model's newest zero-error thinking-off 157 on the OpenRouter endpoint, newest file by mtime. 21 models. This file is olympic 21st. GPT-6 Luna Pro's file has passed 101 and wall 501.4. 101/157 is 64.3 percent.
- The AETHER post is a different artifact. Its own text says it is not Official A, and that it did not send an effort field.