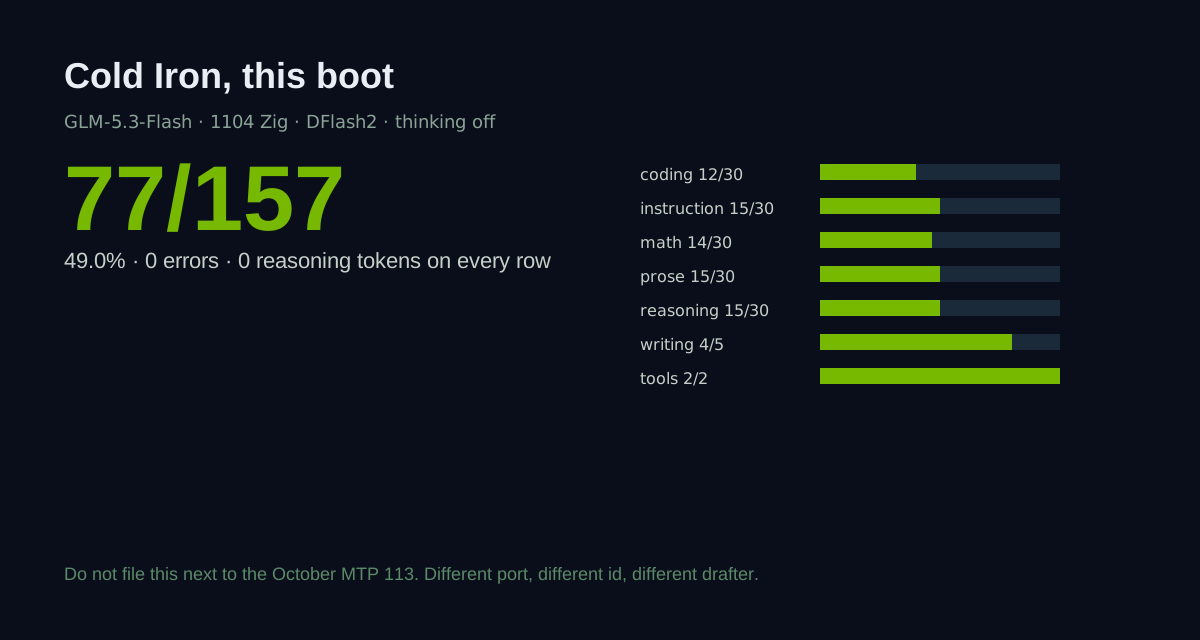
The 1104 GLM serve scored 77/157 on Cold Iron. File it apart from the October 113.
GLM-5.3-Flash on the 1104 Zig boot scored 77/157 thinking off, zero errors, and 0 reasoning tokens on every row. That number belongs to this boot. The October 113/157 file is the older MTP pin on port 8888.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
If you stood the 1104 Zig recipe and want the Cold Iron number, it is 77 out of 157. Zero errors. Every row has 0 reasoning tokens. That is this boot. The October write-up is a different serve, and it scored 113 out of 157. Do not paste those two totals into one rank.
Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
How to tell the files apart
Open /v1/models before you quote a score. This boot answers GLM-5.3-Flash on port 8020. The October file used GLM-5.3-Flash-EXL3 on port 8888, checkout 3fd60df, MTP drafts. Same family name. Different engine, different drafter, different id.
Then open the JSON and check three fields.
thinkingisoff.reasoning_tokensis 0 on every row. This file has that on all 157.- Ignore
serve_recipe_id. Ours saysSMF-Spark-vLLM-0.24-marlin. That string is a stale process default. The process that answered is TensorFold Zig, imagetensorfold-glm53-spark:74e19a63a9a5, native version 1.1.9.
If those three checks fail, you are looking at a different arm. Do not file it as Cold Iron.
What was serving
| Field | Value |
|---|---|
| Recipe | MiaAI-Lab/GLM-5.3-Flash-DGX-Sparks-1104 |
| Checkout | 138123c |
| Image | tensorfold-glm53-spark:74e19a63a9a5 |
| Engine | tensorfold-native 1.1.9 |
| Weights | Mia-AiLab/GLM-5.3-Flash-EXL3-4bpw-TensorFold at 76c0b517 |
| Drafter | incoai/GLM-5.3-Flash-DFlash2 at bf582e4e, CC BY-NC-ND 4.0 |
| Endpoint | http://spark-56bc:8020/v1 |
| Model id | GLM-5.3-Flash |
| Hardware | 2× NVIDIA GB10, tensor parallel 2 |
| Tag | cal-glm53-flash-1104-zig-dflash2-strict-v01 |
| Result | stage1_cal-glm53-flash-1104-zig-dflash2-strict-v01_20261105_024541.json |
The recipe README names that drafter as non-commercial. We left the recipe default in place. A commercial stand would set DRAFTER=mtp or none and run this suite again. This score does not transfer to that stand.
The advertised window on /v1/models is 1,048,576 tokens. We did not run a needle. Do not treat that field as a measured context result.
The score
One run. 77 passed, 80 failed, 0 errors. The file stores the pass rate as 49.0%. Wall time 3749 seconds. Finish reasons: 132 stop, 23 length, 2 tool calls. Cost in the JSON is 0. The endpoint does not bill.
| Category | Passed | Failed |
|---|---|---|
| Coding | 12 of 30 | 18 |
| Instruction | 15 of 30 | 15 |
| Math | 14 of 30 | 16 |
| Prose | 15 of 30 | 15 |
| Reasoning | 15 of 30 | 15 |
| Writing | 4 of 5 | 1 |
| Tool calling | 2 of 2 | 0 |
Short prompts held up. Coding easy, medium, and hard were 2 of 2, 3 of 3, and 5 of 5. Frontier coding was 0 of 12. Thirteen coding fails are SyntaxError. Nineteen fails ended with finish_reason length, and ten of those are coding. The suite cap on those items is 4096 completion tokens. A length fail means the grader did not get a finished answer inside that cap. It does not, by itself, prove the model cannot write the program.
Writing missed writing_creative on keywords (2 of 5, need 3). Both tool calls passed: get_weather for Tokyo, and calculate for 45 * 73.
What to do with the number
Keep this file next to the tag above. Link the October post when you need the older pin, and say the engines differ. The October 113 is MTP on port 8888. This one is DFlash2 on port 8020.
Do not call a board rank from one run. A later true-off file on this same boot can move the ties. This post files the run. It does not reorder the board.
Reproduce it
The runner is run_stage1.py in the smf-bench checkout, thinking off, model id GLM-5.3-Flash, endpoint http://spark-56bc:8020/v1. The JSON and the command note are in the Nemo Knowledge Base.
Smoke before the 157. A thinking-off request should return content with reasoning_tokens 0. We sent 2+2 and got 4 before this run.
Verification notes
Opened on 4 November 2026:
- Result JSON
stage1_cal-glm53-flash-1104-zig-dflash2-strict-v01_20261105_024541.json: summary 77/157, error 0, pass_rate 49.0, thinking off, reasoning_tokens 0 on all 157 rows,serve_recipe_idSMF-Spark-vLLM-0.24-marlin. GET http://spark-56bc:8020/healthreturned ok, modelGLM-5.3-Flash, version 1.1.9.- Head checkout
git rev-parse --short HEADreturned138123c. Weight marker.revisionis76c0b5173166d2795dd48860f45d8224817f894c. docker inspectonglm53-sparkreturned imagetensorfold-glm53-spark:74e19a63a9a5.- Recipe README line on the drafter:
incoai/GLM-5.3-Flash-DFlash2@bf582e4eis CC BY-NC-ND 4.0. - October post opened for the 113/157, port 8888, checkout
3fd60dfcomparison. Those figures are that post's, not a re-score of this JSON.