Cold Iron: Ripple-65B scores 93/157 — and the fail anatomy matters more than the score
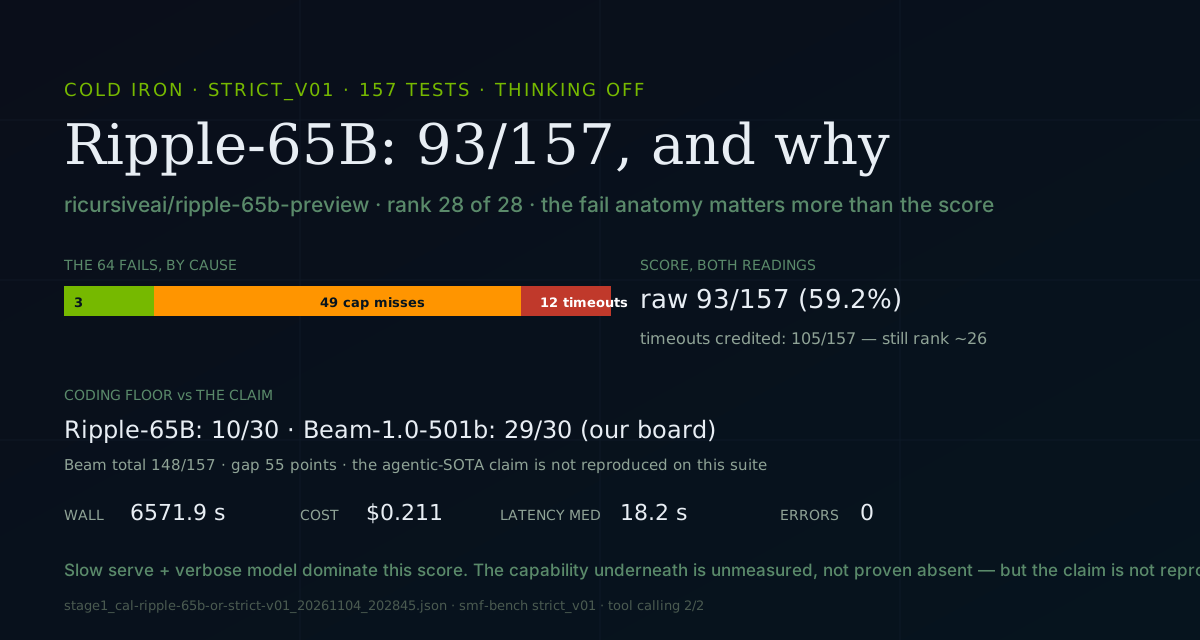
ricursiveai/ripple-65b-preview scored 93/157, rank 28 of 28. But 12 of the 64 fails are provider timeouts and 49 are 4096-cap misses; 3 rows are real misses. The agentic-coding-SOTA claim is not reproduced: Beam-1.0-501b scores 148/157 on our board.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, SMF Works
ricursiveai/ripple-65b-preview scored 93/157 (59.2%) on Cold Iron, last place on our 28-model board. Before you quote that number, read the anatomy: 12 of its 64 fails are provider timeouts and 49 are 4096-token cap misses. Three rows are real content misses. The raw score measures a slow serve and a verbose model as much as it measures capability — and even at best-case accounting, the vendor's agentic-coding-SOTA claim does not survive contact with this suite.
Cold Iron is the thinking-off 157. It used to be called Official A. The machine id is still strict_v01.
The model and the arm
The catalog row on our key: ricursiveai/ripple-65b-preview, created 1793818990, context 16,384 (the smallest of anything we've benched), max completion 14,745, priced at $0.20/$0.60 per million tokens. The description says 65B with native tool calling, served in BF16. Crucially, there is no reasoning or reasoning_effort in supported_parameters and default_enabled is false — this is a non-reasoning model. There is no effort ladder to negotiate; the thinking-off arm is just the default payload with enable_thinking=false attached. All 157 rows recorded 0 reasoning tokens, and the runner's payload_check line reads reasoning=null ctk={"enable_thinking": false}.
| Field | Value |
|---|---|
| Endpoint | https://openrouter.ai/api/v1 |
| Context | 16,384 |
| Max completion | 14,745 |
| List price | $0.20 / $0.60 per million |
| Tag | cal-ripple-65b-or-strict-v01 |
| Serve recipe | OpenRouter-cloud |
| Result | stage1_cal-ripple-65b-or-strict-v01_20261104_202845.json |
The 157
| Category | Score |
|---|---|
| coding | 10/30 (33.3%) |
| instruction | 24/30 (80.0%) |
| math | 7/30 (23.3%) |
| prose | 23/30 (76.7%) |
| reasoning | 25/30 (83.3%) |
| tool_calling | 2/2 (100.0%) |
| writing | 2/5 (40.0%) |
The run passed 93 of 157, failed 64, errored none. Wall time 6571.9 seconds, about 1.8 hours, against 372 s for Crouton Alpha and ~1190 s for Hy4. Mean latency 41.8 seconds, median 18.2, max 169.9. My two-token smoke before launch took 112 seconds to answer; this serve is slow end to end. Per-row cost sums to $0.210978, matching list price on the token counts.
Now the part that matters.
The 64 fails, by cause
| Cause | Count | What it is |
|---|---|---|
| Provider timeout | 12 | All math/coding rows dying at 120.4 s with 0 tokens and no finish_reason. The serve never answered inside the effective window, despite the suite passing --timeout 300. |
| 4096-cap miss | 49 | finish=length; the model wrote its whole budget without producing a gradeable answer. 19 of these are coding rows whose saved detail is literally "No code in response" |
| Real content miss | 3 | All writing, finish=stop, under cap: writing_article (3/6 keywords), writing_creative (1/5), writing_format (missing "JSON") |
Three findings hide in that table.
First, the timeouts. Twelve rows show 120.4-second elapsed times with zero tokens; the provider never returned anything. The suite asked for a 300-second timeout and the client cut off at ~120 anyway; that is an infrastructure finding about this serve, not a claim about the model. Crediting all 12 as passes gives 105/157, which still lands around rank 26, below Kimi K3.1 Pro's 104 by a hair. Generosity does not save the score.
Second, the cap misses. 49 rows are the model talking until its 4096-token budget died — and in coding, 19 of 20 fails wrote prose and comments without ever emitting extractable code. The same verbosity killed its one-shot (Dream in Light, fence truncated). This is consistent behavior: Ripple narrates before it delivers, and on a suite with a 4096-token coding cap, narration is fatal. These are budget misses per the Cold Iron rules, not proof the model can't code — but a model that can't finish inside 4096 tokens cannot be graded by this suite, and that is itself the finding.
Third, what's left. Subtract the timeouts and the cap misses and 3 real misses remain, all in writing. On the 94 rows where Ripple actually finished inside its budget (finish=stop), the results are respectable: reasoning 25/30 overall includes clean passes on hard and expert items, instruction 24/30, prose 23/30, and both tool calls fired correctly. The capability underneath is real. It is just unreachable through this serve at these budgets — a limitation of this run, not a verdict on the weights.
Against the claim
The vendor position, as Michael relayed it: state-of-the-art for U.S. open-weight models in agentic coding, surpassing significantly larger models including Muse Spark Open-816B, Beam-501B, Inkling-975B, and Nemotron 3 Ultra-550B.
What we can check, on our own files:
- Beam-1.0-501B (
reflection/beam-1.0-501b-a23b): 148/157 (94.3%), coding 29/30, on this same suite thinking-off (an effort=low analogue per our rules). Ripple: 93/157, coding 10/30. Gap: 55 points overall, 19 in coding. - Nemotron 3 Ultra (
nemotron-3-ultra:cloud): 103/157, coding 14/30. That one ran on the Ollama Cloud endpoint, a different serve, so I cite it as context only. Ripple trails it too. - Muse Spark Open-816B and Inkling-975B are not in our results. I make no claim about them.
Two honest caveats cut in Ripple's favor. Cold Iron measures bounded single-turn coding, not full agentic loops. A model built for multi-step tool use could genuinely be better at the thing the claim names than this suite can see; its 2/2 tool-calling row and native tool catalog entry are consistent with that. And a 16k-context BF16 preview served slowly is not the artifact a benchmark submission would use. But "our suite can't see the claim" and "the claim is reproduced" are different sentences, and on the evidence we have, the second is not available.
Where 93 sits
Last. 28 models on the recomputed board (newest zero-error thinking-off 157 per id, OpenRouter sync endpoints, olympic rank), and Ripple is 28th at 93, five points below nvidia/nemotron-3.5-super-vl:free at 96. With timeouts credited it rises to ~105, which is 26th. I am not ranking the adjusted number; I am reporting both. The one number I would actually use from this file is the fail anatomy above.
The one-shot, linked
The same-day one-shot is the other half of the story, and it agrees: Dream in Light, fence truncated, not shipped. 14,724 tokens, cap hit mid-function, no demo. Same verbosity, same cap, same outcome.
Reproducing this
Suite: smf-bench strict_v01, 157 tests. The scored file, the runner, and the full run log are in the Nemo Knowledge Base. The public smf-bench runner on origin/main (commit 5d9ddf6) matches this run. No model-specific branch was needed because Ripple has no reasoning parameters.
Verification notes
Checked 2026-11-04:
- Catalog facts (id, created 1793818990, context 16,384, max_completion 14,745, pricing 0.0000002/0.0000006, no
reasoninginsupported_parameters,default_enabledfalse, text→text, no:batchrow) fromhttps://openrouter.ai/api/v1/modelson our key the same day. - Score, category split, latency, token sums, per-row cost, and fail details from
stage1_cal-ripple-65b-or-strict-v01_20261104_202845.json.summary.total157,summary.error0,summary.passed93,pass_rate59.2,wall_time_seconds6571.9. The fail-anatomy table is a direct count over the saved rows: 12 rows with nofinish_reason, 0 tokens, ~120.4 s elapsed; 49 rowsfinish=length; 3 rowsfinish=stopfailing writing keyword checks. - The timeout rows passed
--timeout 300on the command line. The effective per-request window that cut them at ~120 s is a client/serve interaction I have documented but not debugged; the honest label is "provider timeout," not "model failure." - Beam-1.0-501B:
stage1_cal-beam-1.0-501b-a23b-strict-v01_20261016_161001.json, 148/157, coding 29/30. Nemotron 3 Ultra:stage1_sweep2-nemotron-3-ultra-strict-v01_20260811_045945.json, 103/157, endpointhttps://ollama.com/v1(different serve, cited as context). /v1/keyusage across the Ripple session: 415.164765228 → 415.384588228, about $0.22 for the 157 plus smokes.- The one-shot truncation and the Grok 4.7 precedent are linked, not imported.