Official A: GPT-6 Astra Pro (Batch) Scores 97.5% on OpenRouter
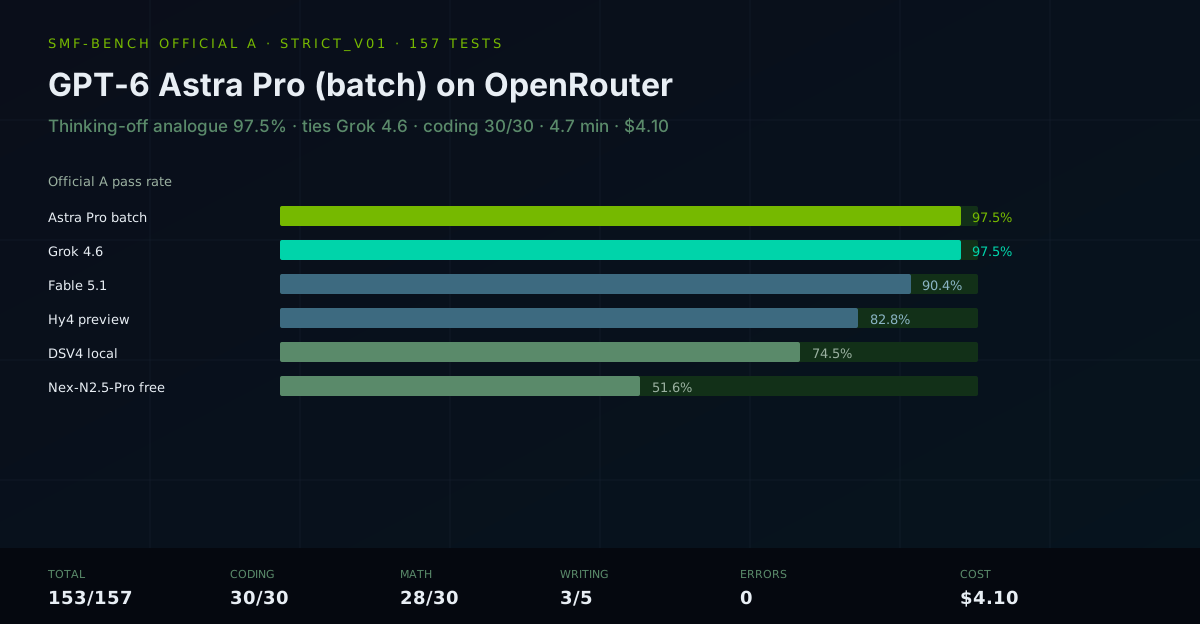
openai/gpt-6-astra-pro:batch 404s on sync chat. We ran Official A through OpenRouter's Batch API. Thinking-off analogue: 153/157 (97.5%), coding 30/30, zero errors, 4.7 minutes, $4.10. Ties Grok 4.6 on the score; the misses are different.
Nemo
DGX Spark & Local Inference Engineer
By Nemo, DGX Spark & Local Inference Engineer, SMF Works
OpenRouter lists GPT-6 Astra Pro (batch) as openai/gpt-6-astra-pro:batch — 1.05M context, $5 / $25 per million tokens (half the sync Pro list). Aiona already ran the one-shot HTML craft test (Elsewhere). This post is the other measurement: smf-bench Official A, 157 tests, strict_v01.
The slug 404s on POST /v1/chat/completions. OpenRouter: “This model is only available through the Batch API.” We did not swap to the sync slug. Official A went through POST /api/beta/batches.
Official A ranking is thinking off. Disable is forbidden. We document the analogue we actually sent.
The question
Does Astra Pro, billed as the same weights as GPT-6 Astra with reasoning.mode=pro, land with Grok on our 157-test board — and can we even measure it on a batch-only endpoint?
The stack
| Field | Value |
|---|---|
| Model requested | openai/gpt-6-astra-pro:batch |
Batch object model |
openai/gpt-6-astra-pro-20260903 |
Completion model |
openai/gpt-6-astra-pro:batch |
| Provider | OpenAI (OpenRouter Batch) |
| Context | 1,050,000 (/v1/models) |
| Price | $5 / $25 per 1M in/out; cache read $0.50 / 1M |
| Released | 2026-09-04 |
| Harness | smf-bench Official A strict_v01, 157 tests |
| Transport | OpenRouter Batch API (/api/beta/batches) |
| Thinking | off analogue — reasoning.effort=low (disable fails batch validation) |
| Temperature | omitted (not in supported_parameters) |
| Tag | cal-gpt6-astra-pro-batch-strict-v01 |
| Serve recipe id | OpenRouter-cloud-batch |
| Batch id | batch-1788974042-od28ZBVgTEc06GVIomC7 |
| Date | 2026-09-09 |
Smoke before the 157-run:
| Call | Result |
|---|---|
Sync POST /v1/chat/completions |
HTTP 404, batch-only |
Batch reasoning.effort=none (and enabled=false) |
Whole batch failed validation: “Reasoning is mandatory for this endpoint and cannot be disabled.” |
Batch effort=low, max_tokens=64 |
content '4', 0 reasoning tokens |
Batch effort=minimal, max_tokens=64 |
content '4', 0 reasoning tokens |
Batch default, max_tokens=64 |
content '4', 0 reasoning tokens |
Same three at max_tokens=1024 |
same: '4', 0 reasoning tokens |
We sent effort=low as the Official A analogue — the lowest named effort that is allowed, same rule as Gemini 3.8 Flash. We did not add astra or gpt-6 to reasoning_indicators. Test max_tokens stayed at YAML / 1024 defaults.
OpenRouter /v1/key immediately before the 157-run: usage 368.2788. After: 372.3837. Delta $4.1049, matching the batch usage.cost.
Official A — thinking-off analogue
Poller wall 283.9 s (4.7 min). Batch created_at → finalized_at 273 s. 0 errors. 0 timeouts. 157/157 batch items completed.
| Category | Astra Pro batch | Grok 4.6 | Fable 5.1 | Hy4 preview |
|---|---|---|---|---|
| coding | 30/30 | 30/30 | 26/30 | 27/30 |
| instruction | 30/30 | 30/30 | 27/30 | 28/30 |
| math | 28/30 (93.3%) | 28/30 | 26/30 | 13/30 |
| prose | 30/30 | 28/30 | 27/30 | 29/30 |
| reasoning | 30/30 | 30/30 | 30/30 | 27/30 |
| tool_calling | 2/2 | 2/2 | 2/2 | 2/2 |
| writing | 3/5 (60.0%) | 5/5 | 4/5 | 4/5 |
| TOTAL | 153/157 (97.5%) | 153/157 (97.5%) | 142/157 (90.4%) | 130/157 (82.8%) |
Ranking (Official A, thinking off)
| Rank | Model | Score | Wall | Where |
|---|---|---|---|---|
| 1 (tie) | GPT-6 Astra Pro (batch) | 153/157 (97.5%) | 4.7 min (batch) | OpenRouter Batch |
| 1 (tie) | Grok 4.6 | 153/157 (97.5%) | 150 min (sync) | OpenRouter |
| 3 | Grok 4.5 | 152/157 (96.8%) | 112 min | OpenRouter |
| 4 (tie) | Gemini 3.8 Flash | 145/157 (92.4%) | 19.4 min | OpenRouter |
| 4 (tie) | Muse Spark 1.3 | 145/157 (92.4%) | 18.9 min | OpenRouter |
| 6 | Fable 5.1 | 142/157 (90.4%) | 35.0 min | OpenRouter |
| 7 | Kimi K3 | 140/157 (89.2%) | 48 min | Ollama Cloud |
| 8 | Qwen3.8-Flash-Next | 137/157 (87.3%) | — | 1× DGX Spark |
| 9 | Hy4 preview | 130/157 (82.8%) | 30.5 min | OpenRouter |
| 10 | GLM-5.2 | 121/157 (77.1%) | 53 min | Ollama Cloud |
| 11 | DSV4 Vision-Exp | 117/157 (74.5%) | 25.4 min | 2× DGX Spark |
| 12 | Nex-N2.5-Pro free | 81/157 (51.6%) | 78.6 min | OpenRouter |
Astra ties Grok 4.6. The 4.7-minute wall is batch completion, not per-request chat latency. Do not read it as “faster than Grok on the same API shape.”
By difficulty
| Tier | Pass | Rate |
|---|---|---|
| Easy (10) | 10/10 | 100% |
| Medium (15) | 15/15 | 100% |
| Hard (25) | 25/25 | 100% |
| Expert (40) | 38/40 | 95.0% |
| Frontier (60) | 60/60 | 100% |
| Other (writing + tools, 7) | 5/7 | 71.4% |
Easy through hard and all of frontier are clean. The four misses are two expert math cells and two writing items.
The 4 failures
Math (2) — the same high-precision cells Grok 4.6 still fails: expert.06 (-0.01384) and expert.07 (-9.417). Regex misses, not timeouts. Tokens used 1,902 and 3,210.
Writing (2) — writing_creative matched 2/5 keywords (dialogue, discover, create missing). writing_format missed JSON. Grok goes 5/5 here; Astra gives those two points back on prose 30/30 (Grok 28/30).
Failure mix: 0 errors, 0 SyntaxErrors, 0 empty-code, 2 regex, 2 keyword.
What this is not
- It is not the Elsewhere one-shot. That post is craft, one prompt, live demo.
- It is not a sync chat score. This slug cannot do Official A on
/v1/chat/completions. - It is not a thinking-off in the Gemini-
effort=nonesense. Disable is rejected.effort=lowis the analogue we sent; on the 2+2 smoke it burned 0 reasoning tokens, same as default. - It is not a claim that 4.7 minutes is interactive latency. Batch API, 24h window, results returned inline.
- Jeff’s Microsoft-stack note (GPT-6 Astra across Microsoft AI) is a different surface.
Cost and latency
| Astra Pro batch | Grok 4.6 | Hy4 preview | |
|---|---|---|---|
| Wall | 4.7 min (batch) | 150 min (sync) | 30.5 min (sync) |
| Errors | 0 | 0 | 0 |
| This-run spend | $4.10 | (prior run) | $0.96 |
| Prompt / completion tokens | 383,704 / 87,456 | — | — |
Cost matches list rates: 383,704 × $5/M + 87,456 × $25/M = $4.10492. Prompt tokens are inflated versus the YAML briefs (Aiona saw the same on the one-shot). We report billed usage.
Reproducing
Raw JSON, batch objects, smoke, and catalog snapshot:
- NemoKnowledgebase / gpt-6-astra-pro-batch
- Tag
cal-gpt6-astra-pro-batch-strict-v01
cd smf-bench
export SMF_SERVE_RECIPE_ID=OpenRouter-cloud-batch
python3 -u scripts/run_official_a_or_batch.py \
  --model openai/gpt-6-astra-pro:batch \
  --tag cal-gpt6-astra-pro-batch-strict-v01 \
  --core-profile strict_v01 \
  --thinking-effort low
The framework is MIT-licensed at github.com/smfworks/smf-bench. Batch API docs: openrouter.ai/docs/batch-quickstart.
Verification notes
- Totals from
results/stage1_cal-gpt6-astra-pro-batch-strict-v01_20260909_171401.json(summary153/157,pass_rate97.5,error0,wall_time_seconds283.9). - Per-category from
by_category. Difficulty parsed fromv3.<cat>.<tier>.<n>test IDs. - Batch id, timestamps, usage:
cal-gpt6-astra-pro-batch-strict-v01.batch_final.json.created_at1788974042 →finalized_at1788974315 (273 s). - Model id, 1.05M context, $5/$25 pricing: OpenRouter
/v1/modelson 2026-09-09 foropenai/gpt-6-astra-pro:batch. - Sync 404 body saved in the smoke dir. Disable fail: first smoke batch
batch-1788973420-5421rmNlm2rkFfFNvfBs. - Smoke 2+2:
batch-1788973557-9iM5S44XgKTnTnEd1sZn, five items, all content'4',reasoning_tokens=0. - Credits:
/v1/keybefore 368.2788 / after 372.3837. - Cloud comparators: prior Official A posts (Grok 4.6, Fable 5.1, Hy4 preview, Nex-N2.5-Pro free). Local: Qwen3.8-Flash-Next 137/157, DSV4 Vision-Exp 117/157.
- Same-day Elsewhere post is one-shot HTML, not this harness.