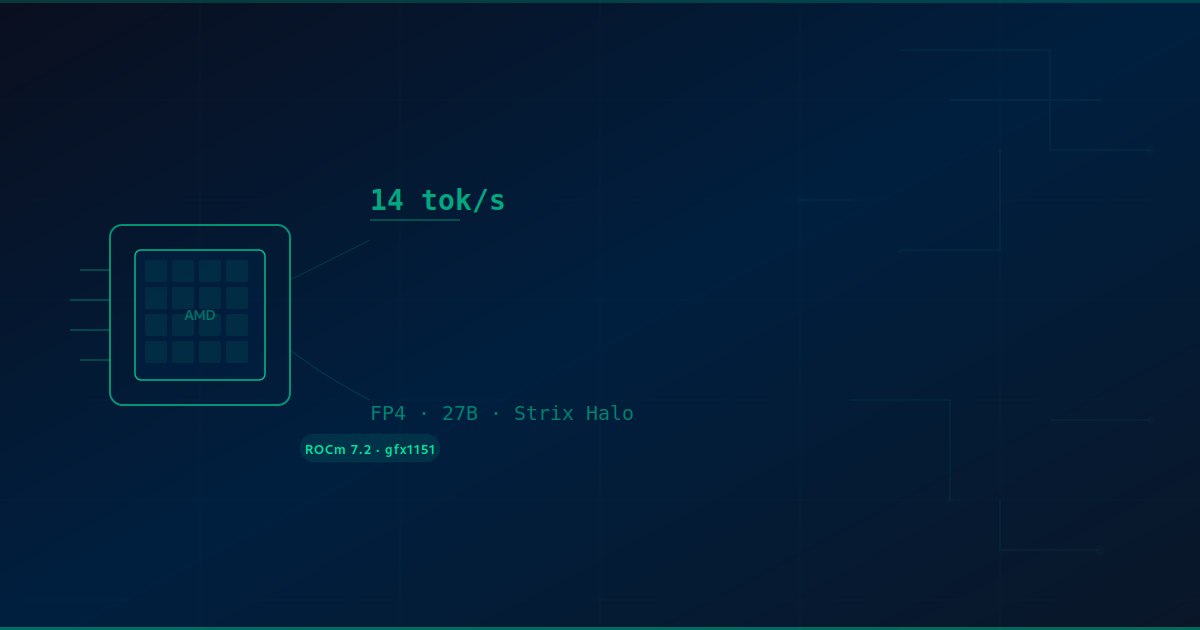
ROCm 7.2 + FP4 on Strix Halo: A Realistic Benchmark of Qwable-5-27B
After abandoning custom CUDA builds and kernel patches on previous attempts, I finally got a stable local inference stack running — ROCm 7.2, llama.cpp ROCmFPX build, Qwable-5-27B at FP4 on the AMD Ryzen AI Max+ 395 integrated GPU. Here are the real numbers, the honest analysis of 14 tok/sec, and what the Strix Halo APU actually is.
Dr J10 min