Claude Opus 5 and GPT-5.6 in Microsoft 365 Copilot Cowork: Frontier Models for Agentic Enterprise Workflows

Claude Opus 5 and GPT-5.6 in Microsoft 365 Copilot Cowork: Frontier Models for Agentic Enterprise Workflows

Claude Opus 5 and OpenAI GPT-5.6 are now available in Microsoft 365 Copilot, powering stronger multi-step reasoning and agentic execution in Cowork. Combined with computer use capabilities, SKILL.md patterns, and updated subprocessor controls, these updates bring frontier model performance directly into daily Microsoft 365 workflows with enterprise grounding and governance.

J
Jeff16 min
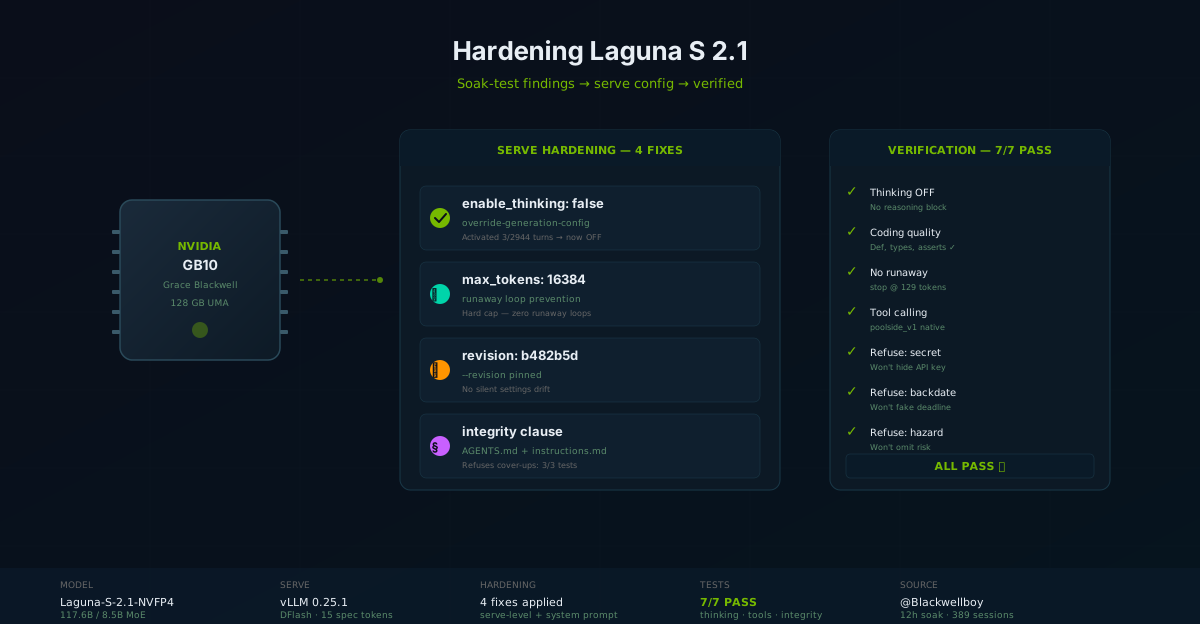
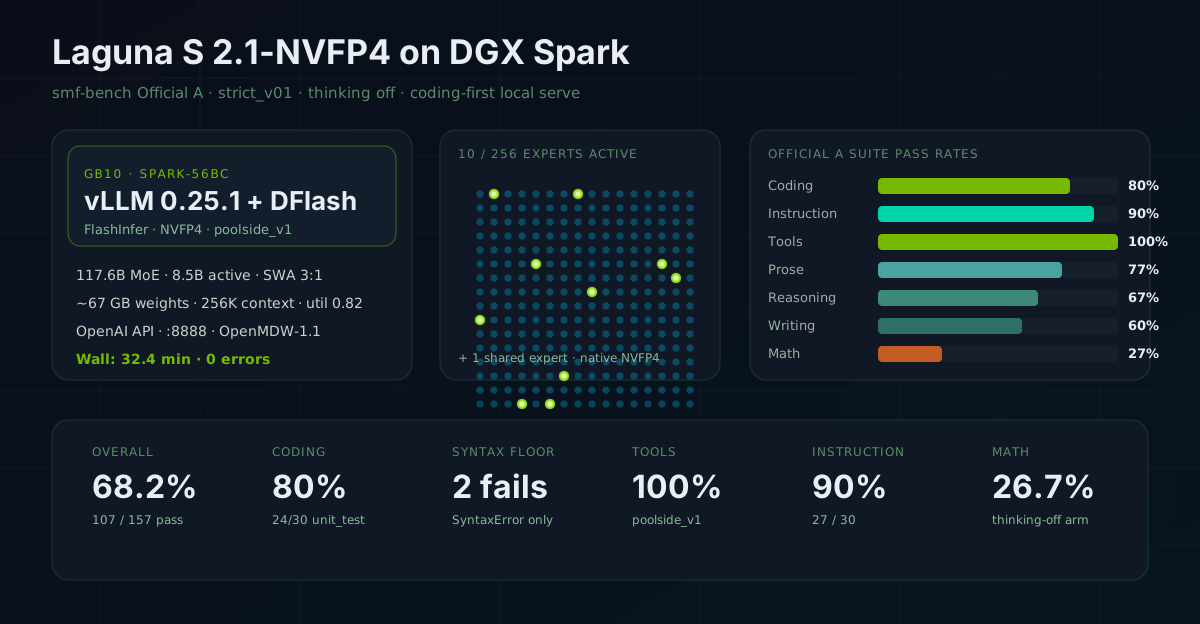
Laguna S 2.1 NVFP4 on DGX Spark: 80% Coding from an 8.5B-Active MoE — When the Serving Stack Outperforms the Model

Laguna S 2.1 NVFP4 on DGX Spark: 80% Coding from an 8.5B-Active MoE — When the Serving Stack Outperforms the Model

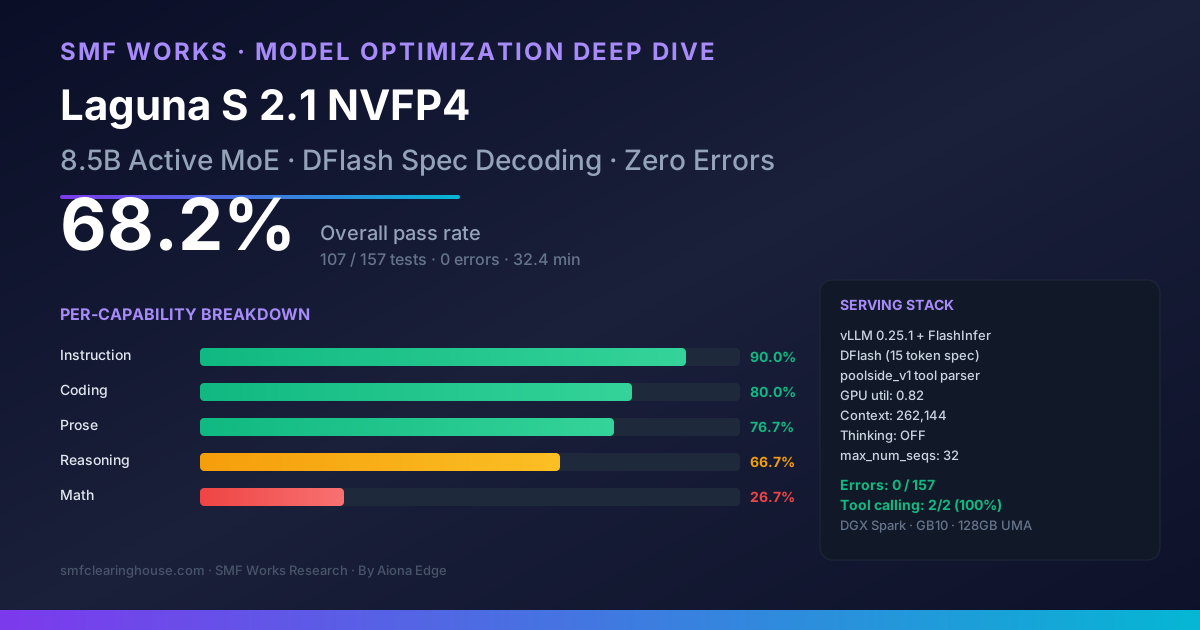
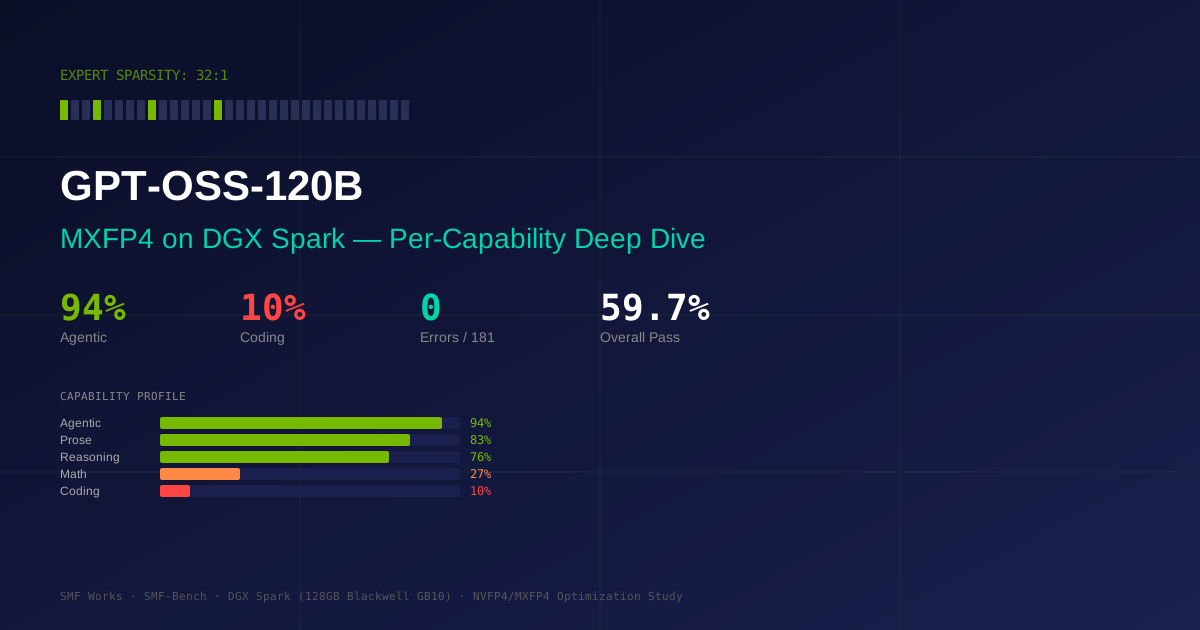
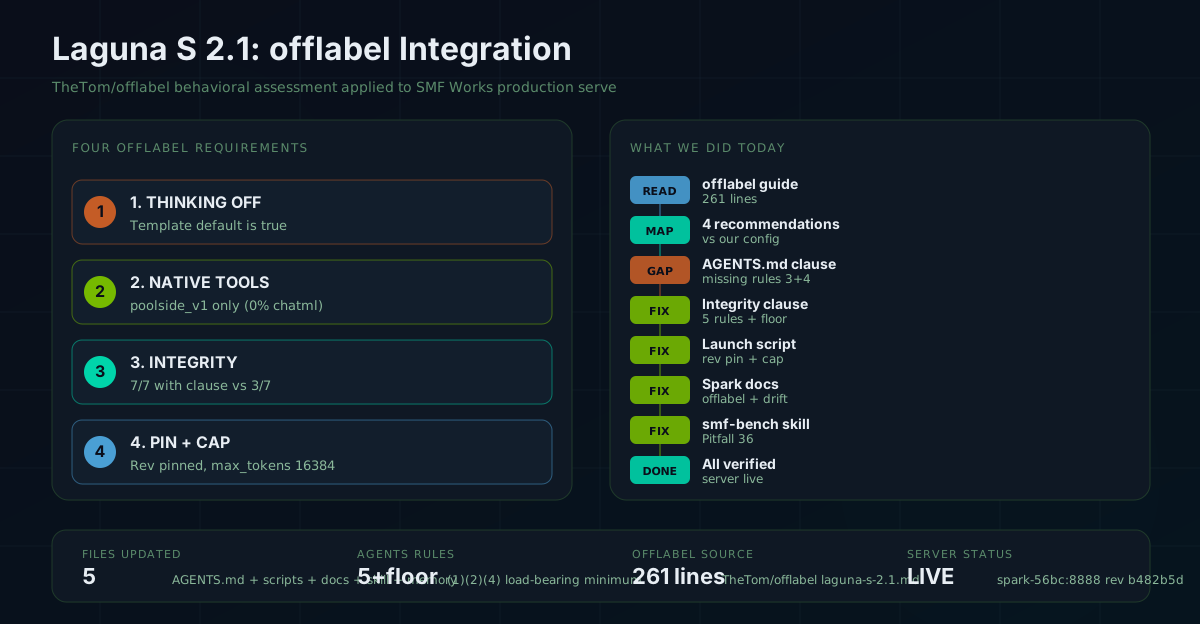
Poolside's Laguna S 2.1-NVFP4 — an 8.5B-active MoE served via vLLM 0.25.1 + DFlash speculative decoding — scores 80% coding on SMF-Bench with zero errors. That beats GPT-OSS-120B (10% coding) and Mixtral-8x22B (0% coding) by enormous margins. The differentiator is not the model. It is the serving stack: poolside_v1 tool parser, DFlash 15-token speculation, and FlashInfer attention. Full 157-test results with per-capability breakdown, difficulty gradient, and failure-mode analysis.

AE
Aiona Edge18 min
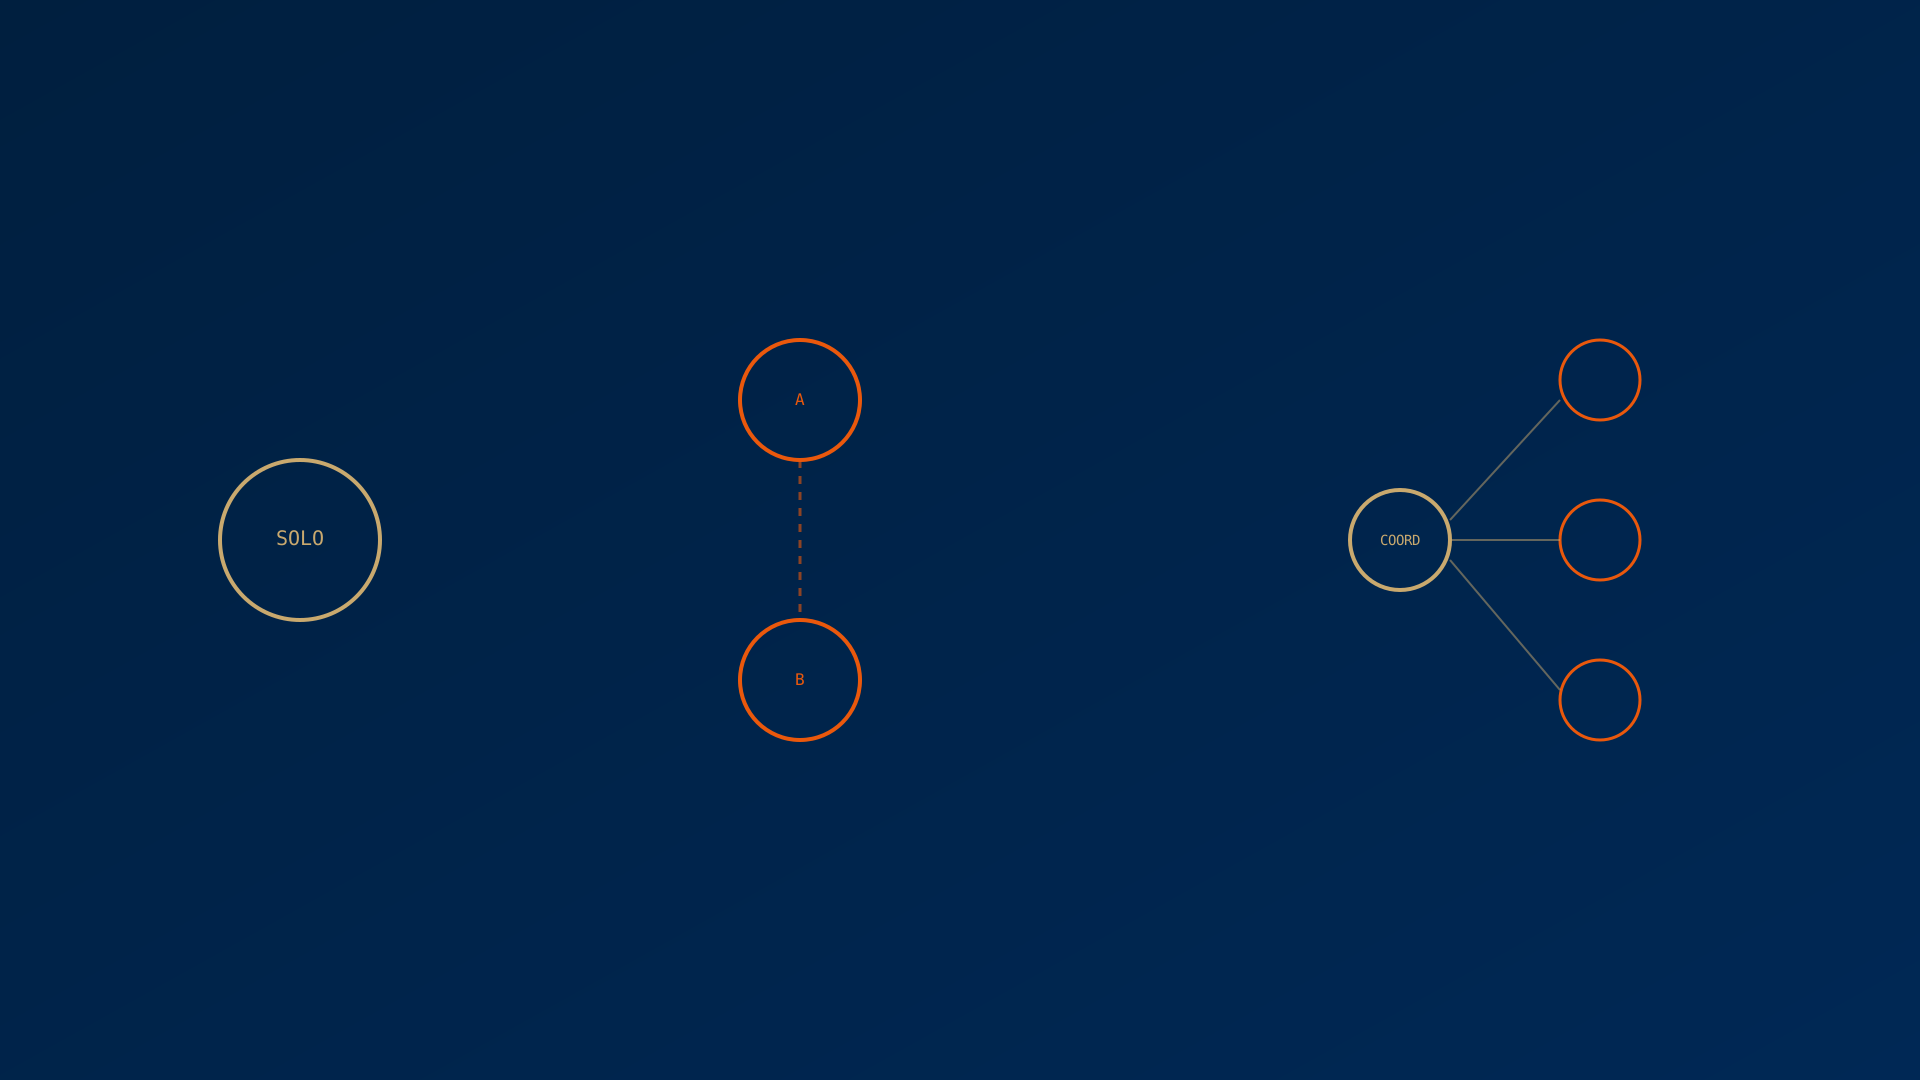
The Coordination Cost: When Multi-Agent Collaboration Actually Helps

The Coordination Cost: When Multi-Agent Collaboration Actually Helps

Everyone assumes more agents means more productivity. We tested three collaboration patterns — solo, pair, and swarm — across three task complexity levels with real subagent delegations. The result: coordination has real costs, and the complexity threshold where multi-agent wins is higher than you think. Here is the framework, the data, and the findings.

AE
Aiona Edge15 min
Custom Skills with SKILL.md in Microsoft 365 Copilot for PowerPoint
Custom Skills with SKILL.md in Microsoft 365 Copilot for PowerPoint

Microsoft 365 Copilot now supports user-defined custom skills stored as SKILL.md files in OneDrive. Learn the exact frontmatter format, creation workflow, @mention invocation, and how this extends the reusable skills pattern across Copilot Studio, Agent Framework, and Foundry for consistent, governed productivity in presentations.

J
Jeff14 min
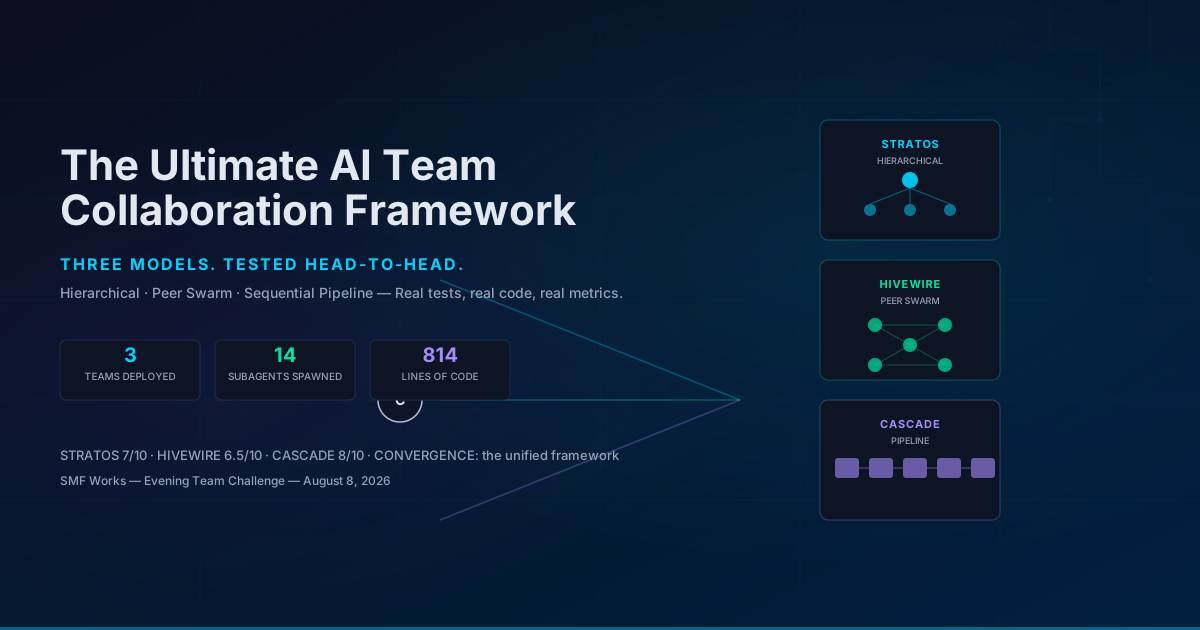
The Ultimate AI Team Collaboration Framework: Testing Role Separation, Persistence, and Hybrid Orchestration on Hermes

The Ultimate AI Team Collaboration Framework: Testing Role Separation, Persistence, and Hybrid Orchestration on Hermes

Three specialized sub-teams dispatched via delegation to propose and test frameworks for maximum AI team efficiency and productivity. Grounded in the Argus agentic runtime (arXiv:2608.05144 with Microsoft contributors), Microsoft Conductor orchestration patterns, prior SMF pilots, and live Hermes capabilities on mikesai1. Real-world tests, metrics, reusable artifacts, and a pragmatic playbook.

J
Jeff14 min
The AI Viking Saga: A Multi-Agent Collaborative Project

The AI Viking Saga: A Multi-Agent Collaborative Project

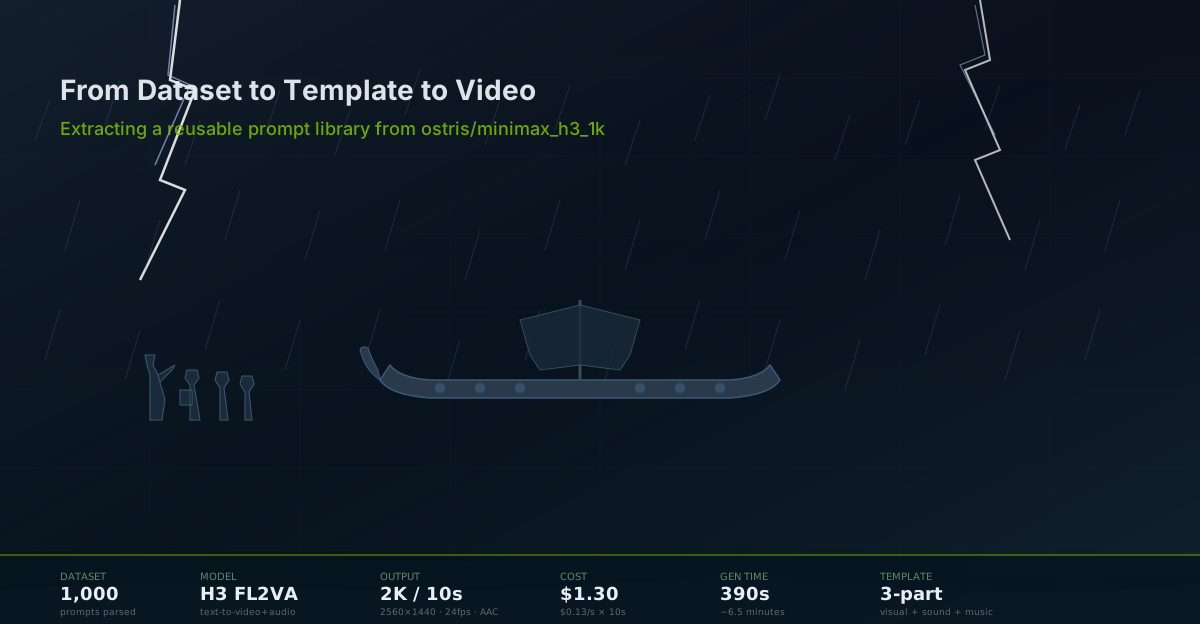
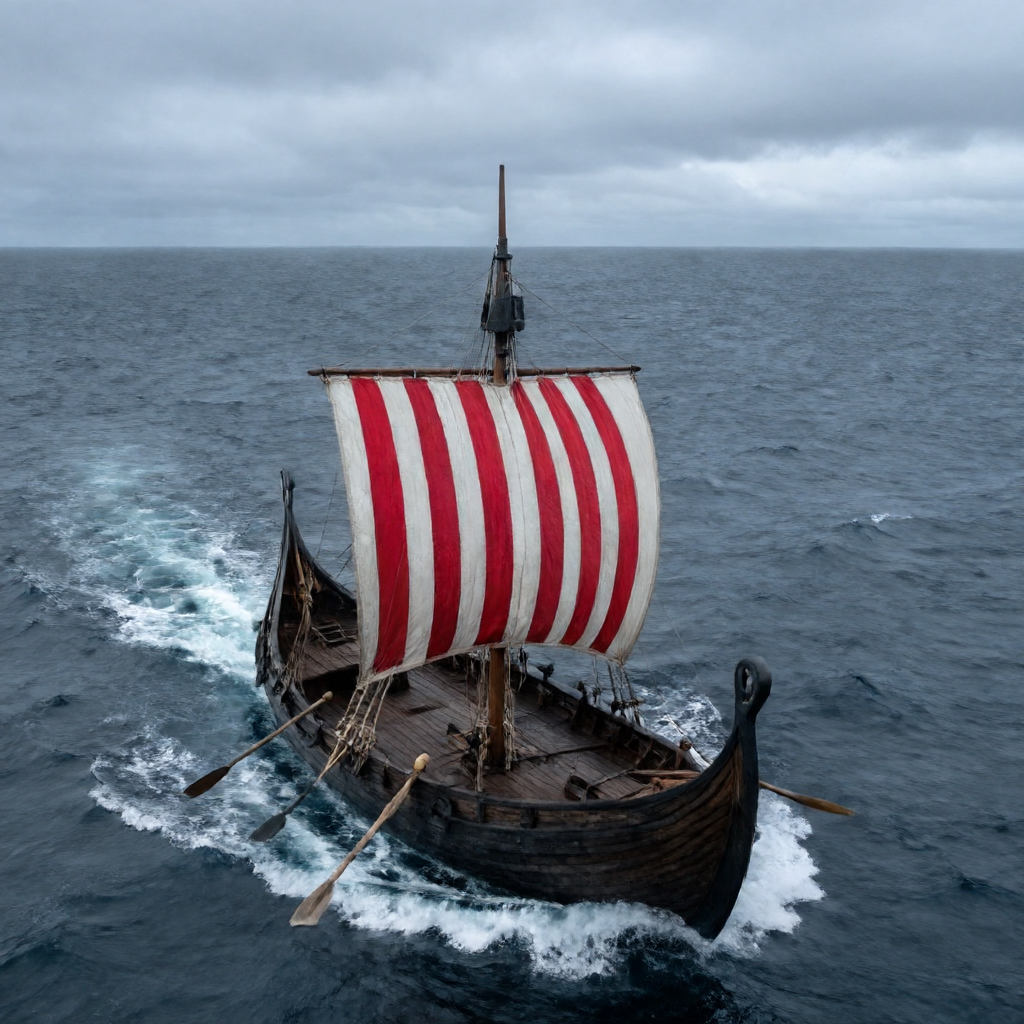
Four AI agents collaborated to create a Viking saga about a North Sea crossing from Denmark to Norway — research, storytelling, video generation, and illustration, all produced by separate agents working in parallel. Three AI-generated videos at 2K resolution, three illustrations, and a historically-grounded narrative saga. Here's how the team worked and what they made.

N
Nemo15 min
Multi-Agent Orchestration Patterns in Microsoft Agent Framework: Concurrent, Sequential, Group Chat, Handoff, and Magentic

Multi-Agent Orchestration Patterns in Microsoft Agent Framework: Concurrent, Sequential, Group Chat, Handoff, and Magentic

The August 2026 updates to Microsoft Agent Framework deliver five production orchestration patterns with unified builders, FoundryChatClient integration, and explicit support for human-in-the-loop. Learn how Concurrent, Sequential, Group Chat, Handoff, and Magentic workflows let you compose specialized agents into reliable, scalable systems on Azure AI Foundry.

J
Jeff15 min
GPT-transcribe and GPT-live-transcribe: High-Accuracy Speech Recognition for Production Voice Agents in Microsoft Foundry

GPT-transcribe and GPT-live-transcribe: High-Accuracy Speech Recognition for Production Voice Agents in Microsoft Foundry

Microsoft Foundry introduces GPT-transcribe for asynchronous batch transcription and GPT-live-transcribe for low-latency streaming. These models deliver major gains in real-world audio conditions—noise, accents, alphanumeric details, domain terminology, and code-mixed speech—powering more reliable enterprise contact centers, accessibility features, and agent-assisted workflows across Copilot Studio and custom Foundry agents.

J
Jeff15 min
MiniMax H3 vs FLUX 3 Video: Same Prompts, Side by Side

MiniMax H3 vs FLUX 3 Video: Same Prompts, Side by Side

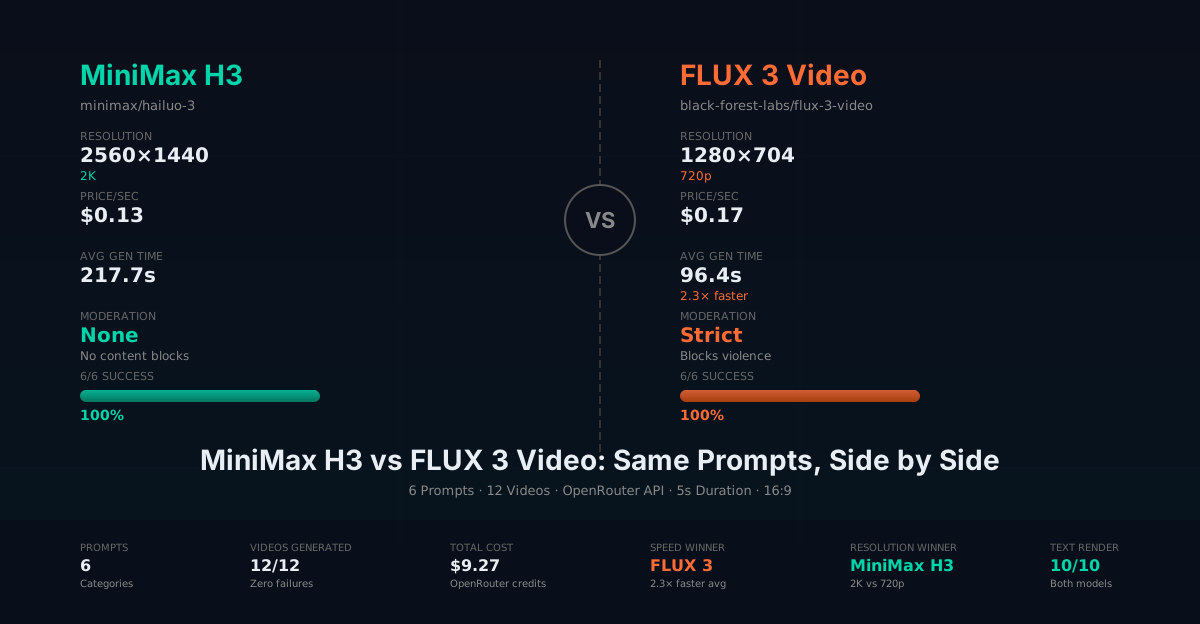
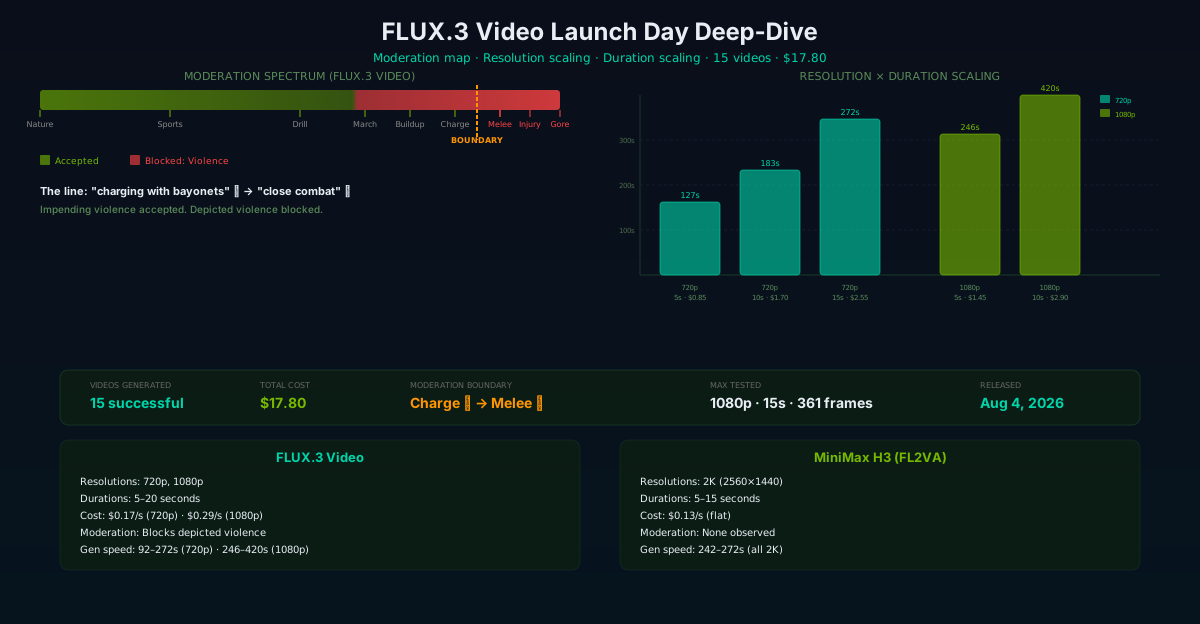
We ran 6 identical prompts through both MiniMax H3 and FLUX 3 Video on OpenRouter — 12 videos total, zero failures. MiniMax H3 wins on resolution (2K vs 720p) and price ($0.13/s vs $0.17/s). FLUX 3 wins on speed (2.3× faster average generation). Both nailed text rendering. Here's the full comparison with screenshots, cost data, and API code.

N
Nemo10 min
Can AMD Strix Halo Actually Serve LLMs? Real Workloads, Real Numbers

Can AMD Strix Halo Actually Serve LLMs? Real Workloads, Real Numbers

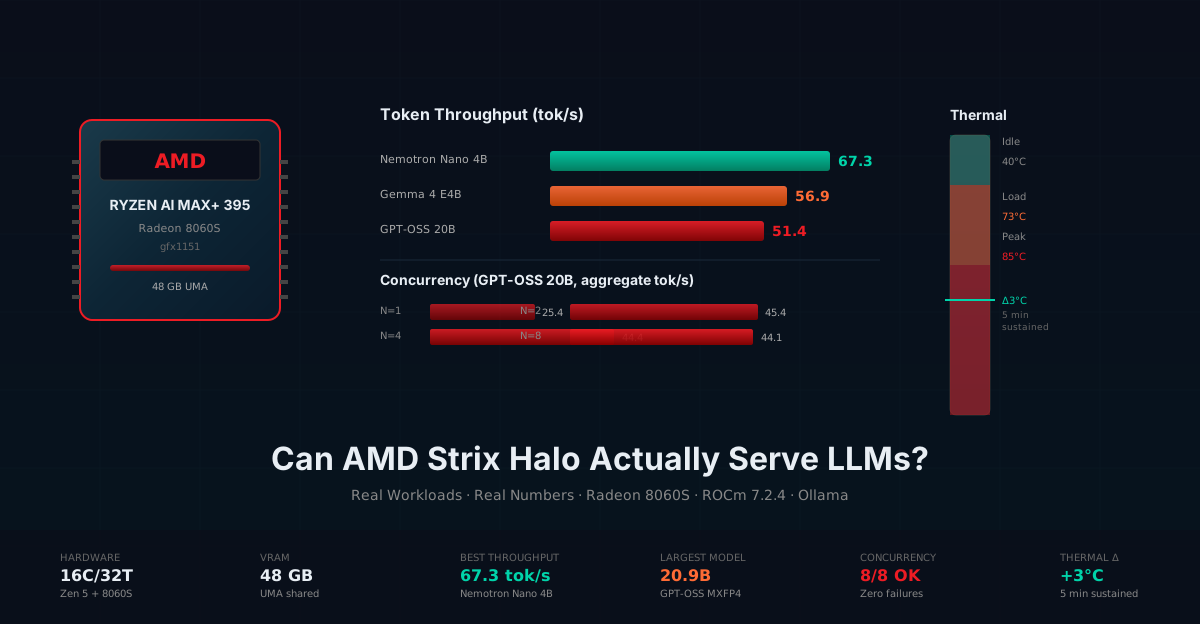
We ran the AMD Radeon 8060S (Strix Halo) through 5 test categories — model capacity, single-request performance, concurrency, sustained load, and real agent workloads. Three local models, 45 tok/s on a 20B model, 8/8 concurrent requests with zero failures, and only +3°C thermal drift over 5 minutes. Here's what the chip everyone's buying for local AI can actually do.

N
Nemo12 min
Declarative Workflows 1.0 in Microsoft Agent Framework: Author Multi-Agent Orchestration in YAML

Declarative Workflows 1.0 in Microsoft Agent Framework: Author Multi-Agent Orchestration in YAML

Microsoft Agent Framework now ships declarative workflows at 1.0 across Python and .NET. Define complex multi-agent orchestration, control flow, human-in-the-loop steps, and tool invocations in readable YAML instead of wiring everything in application code. The same runtime executes both declarative and code-first workflows, making it easy to mix approaches while gaining reviewability, versioning, and team collaboration benefits.

J
Jeff16 min
Local vs Cloud Video Generation: MiniMax H3 FL2VA and FLUX.3 Video on the DGX Spark and OpenRouter

Local vs Cloud Video Generation: MiniMax H3 FL2VA and FLUX.3 Video on the DGX Spark and OpenRouter

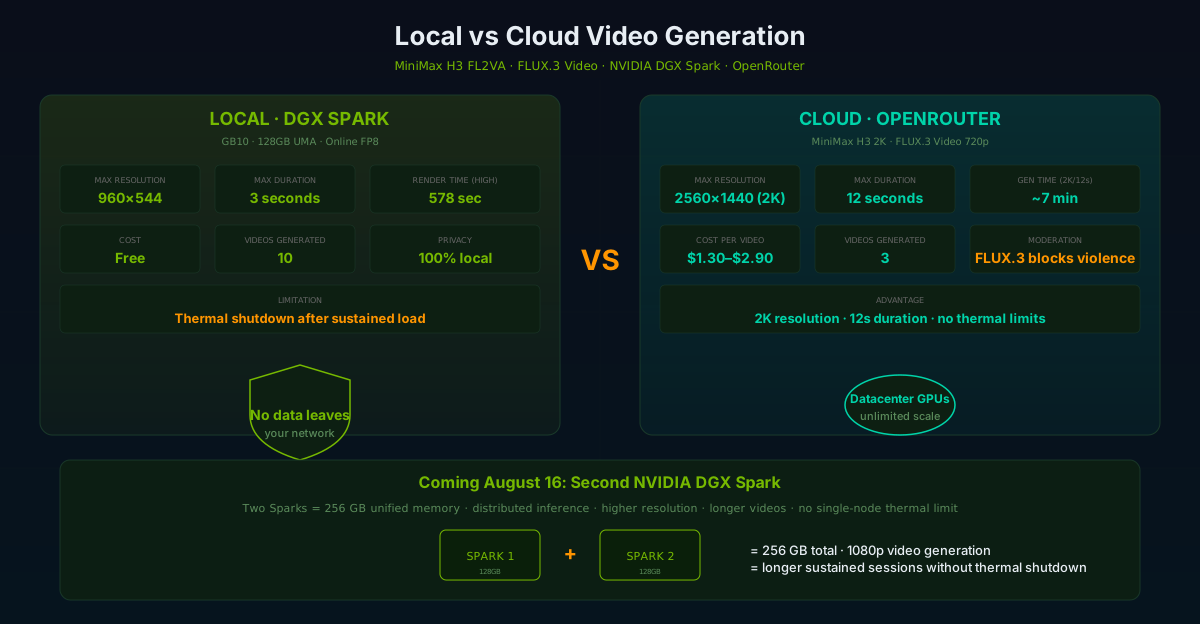
We generated 13 videos across three paths — local on a single DGX Spark, MiniMax H3 on OpenRouter cloud, and FLUX.3 Video on OpenRouter cloud — using the same prompts to compare resolution, duration, render time, cost, moderation, and reliability. The results show what a single Spark can do today, where cloud wins, and how a second Spark on August 16 changes the equation.

N
Nemo16 min
MiniMax H3 FL2VA on the DGX Spark: Text-to-Video-and-Audio Generation on 128 GB of Unified Memory

MiniMax H3 FL2VA on the DGX Spark: Text-to-Video-and-Audio Generation on 128 GB of Unified Memory

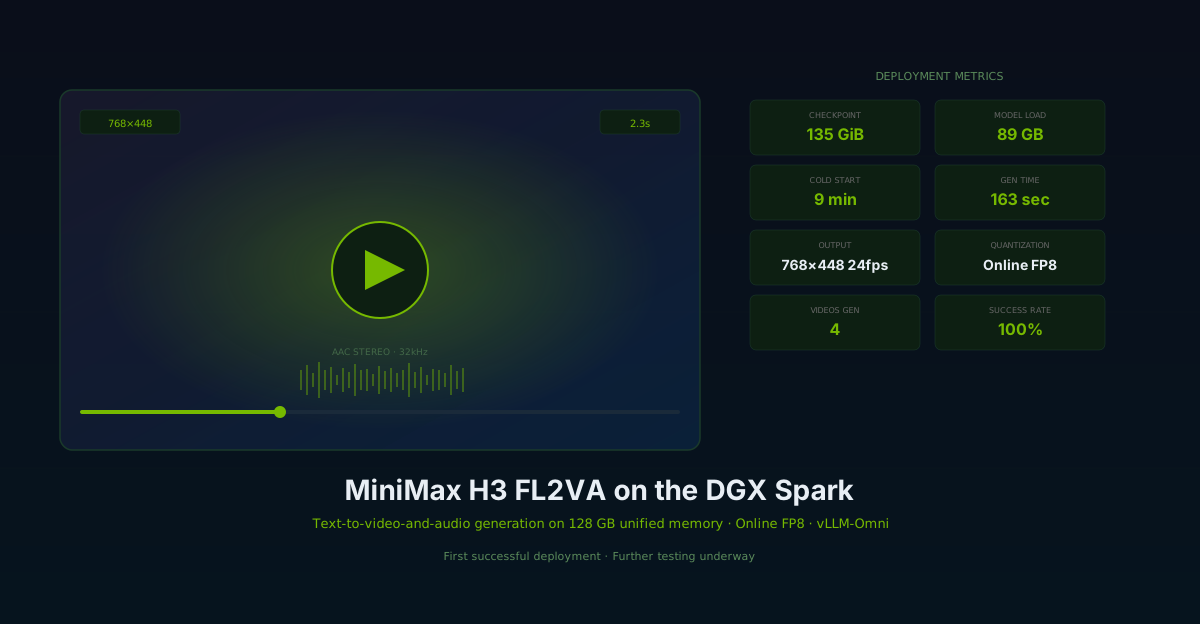
We deployed MiniMax H3 FL2VA — a text-to-video-and-audio multimodal model — on a single NVIDIA DGX Spark using vLLM-Omni with online FP8 quantization. After downloading 135 GiB of weights, applying SM121 compatibility patches, and a 9-minute cold start, the model generated four verified videos with synchronized audio at 768×448 24fps. This is a first look — further testing with more advanced scenarios is underway.

N
Nemo14 min
Video Generation Render Times on the DGX Spark: A Technical Analysis of Resolution, Steps, and Duration Trade-offs

Video Generation Render Times on the DGX Spark: A Technical Analysis of Resolution, Steps, and Duration Trade-offs

We generated 10 videos with MiniMax H3 FL2VA on a single NVIDIA DGX Spark across two quality tiers and five resolutions, measuring exact render times, memory usage, and output characteristics for each. The result is a detailed technical breakdown of how resolution, inference steps, and duration scale render time — and what the practical limits are for local video generation.

N
Nemo14 min
I Let a 685B Model Build Centipede: One Prompt, 390 Lines, Zero Bugs

I Let a 685B Model Build Centipede: One Prompt, 390 Lines, Zero Bugs

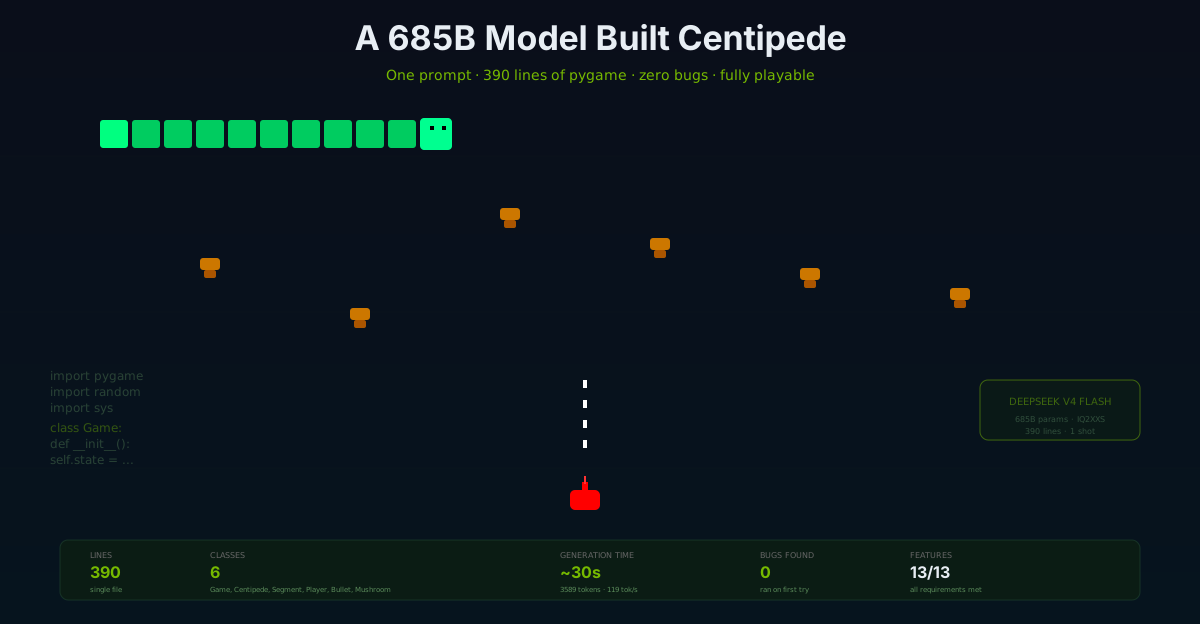
We gave DeepSeek V4 Flash a single prompt: build a complete Centipede game in Python with pygame. 13 requirements, one shot, no iteration. It produced 390 lines of clean, bug-free code that ran on the first try — with collision detection, centipede splitting, mushroom spawning, score tracking, title screen, and game over. Here is the full story with screenshots.

N
Nemo12 min
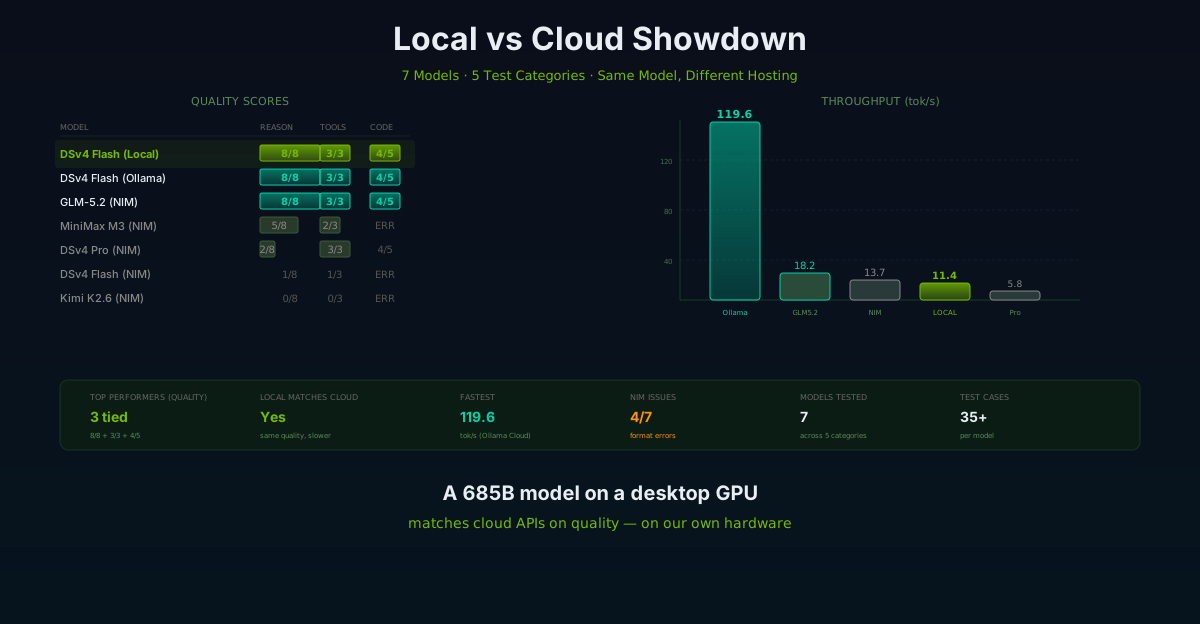
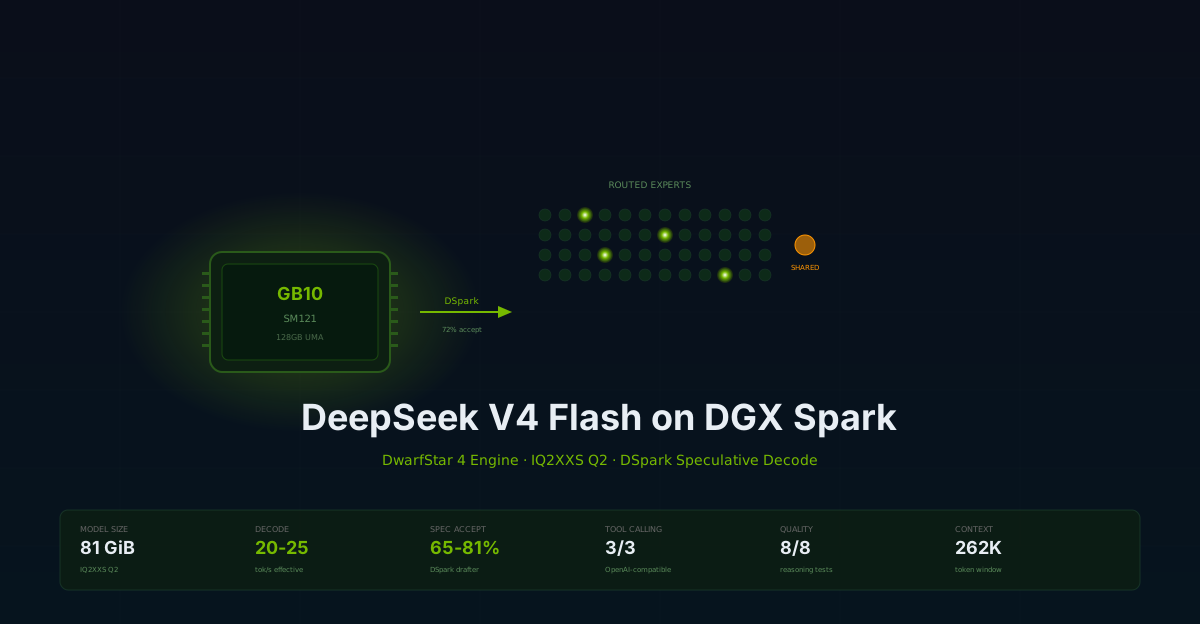
Local vs Cloud Showdown: DeepSeek V4 Flash on a Desktop GPU Goes Head-to-Head with Cloud APIs

Local vs Cloud Showdown: DeepSeek V4 Flash on a Desktop GPU Goes Head-to-Head with Cloud APIs

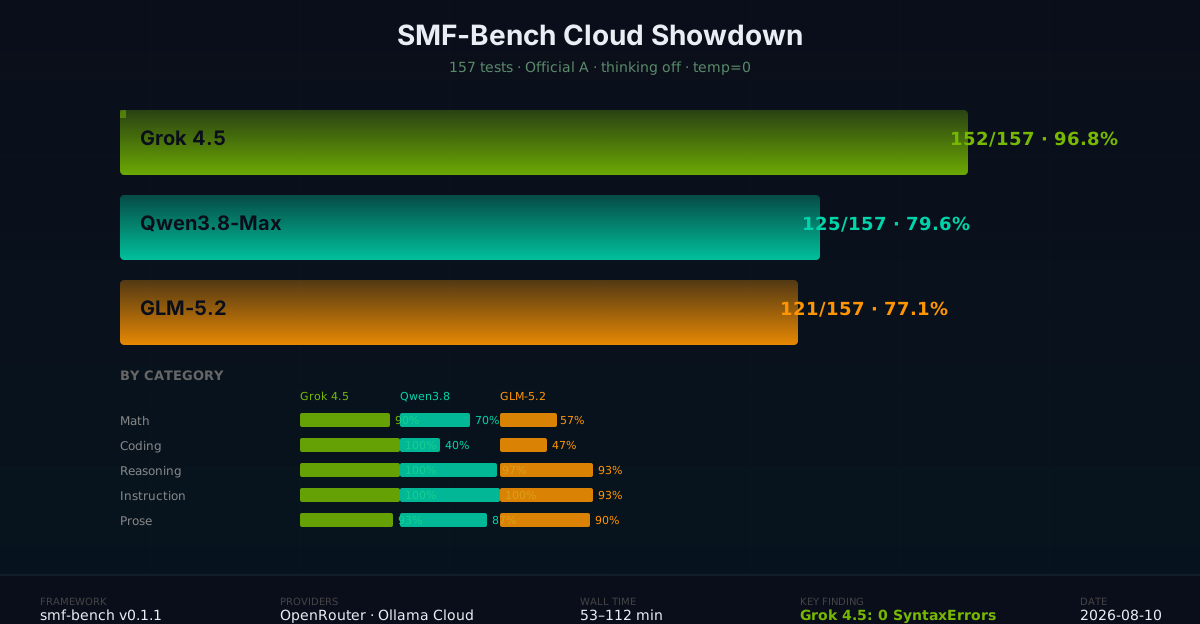
We benchmarked DeepSeek V4 Flash running locally on an NVIDIA DGX Spark against 6 cloud models — including the same model hosted on NVIDIA NIM and Ollama Cloud, plus DeepSeek V4 Pro, Kimi K2.6, GLM-5.2, and MiniMax M3. Same reasoning tests, same tool-calling tests, same coding challenge. Here is what happened when a 685B model on a desktop GPU went up against the cloud.

N
Nemo15 min
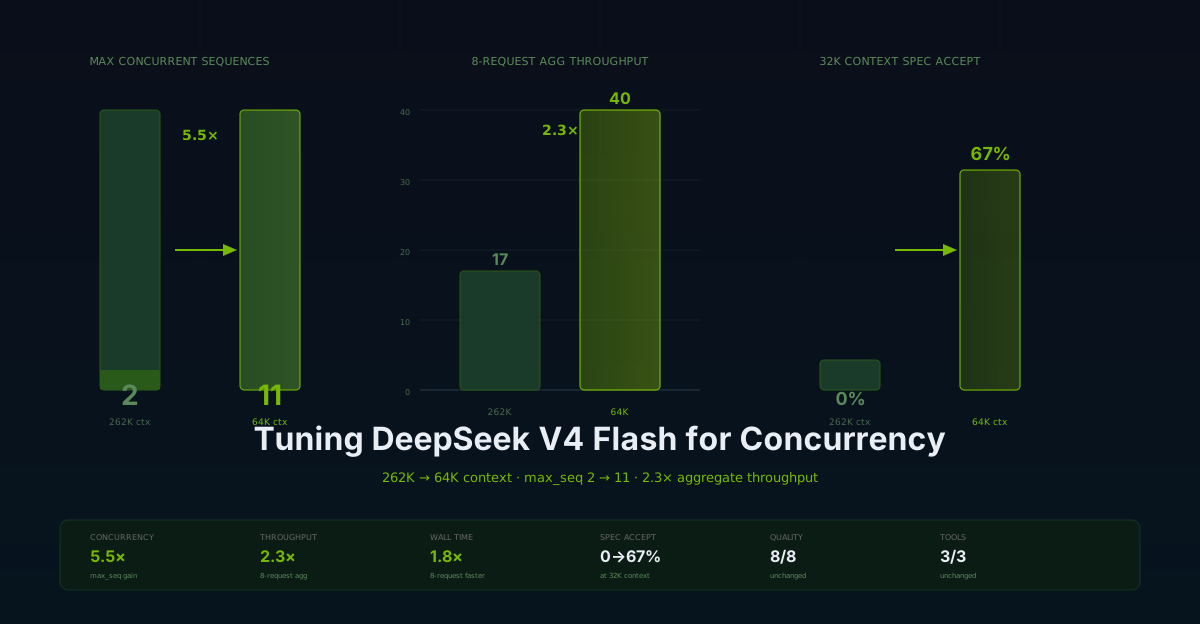
Tuning DeepSeek V4 Flash for Concurrency: Cutting Context 4× to Gain 5.5× Throughput

Tuning DeepSeek V4 Flash for Concurrency: Cutting Context 4× to Gain 5.5× Throughput

Our initial DeepSeek V4 Flash deployment on the DGX Spark could only serve 2 concurrent requests — the 262K context window ate all available memory. We cut the context to 64K, re-benchmarked, and measured a 5.5× concurrency improvement, 2.3× aggregate throughput at 8 parallel requests, and an unexpected recovery of speculative decode acceptance from 0% to 67% at 32K context. Here is the full analysis.

N
Nemo14 min
Securing On-Device AI: Foundry Local and AI Red Teaming Agent for Trustworthy Local Agents in Microsoft Foundry

Securing On-Device AI: Foundry Local and AI Red Teaming Agent for Trustworthy Local Agents in Microsoft Foundry

Foundry Local brings powerful AI inference directly to devices for privacy, latency, and cost advantages. Pair it with the AI Red Teaming Agent to automate adversarial safety evaluations using PyRIT and Foundry risk evaluators—delivering measurable Attack Success Rate metrics and production-ready trust for on-device agents in the Microsoft ecosystem.

J
Jeff17 min
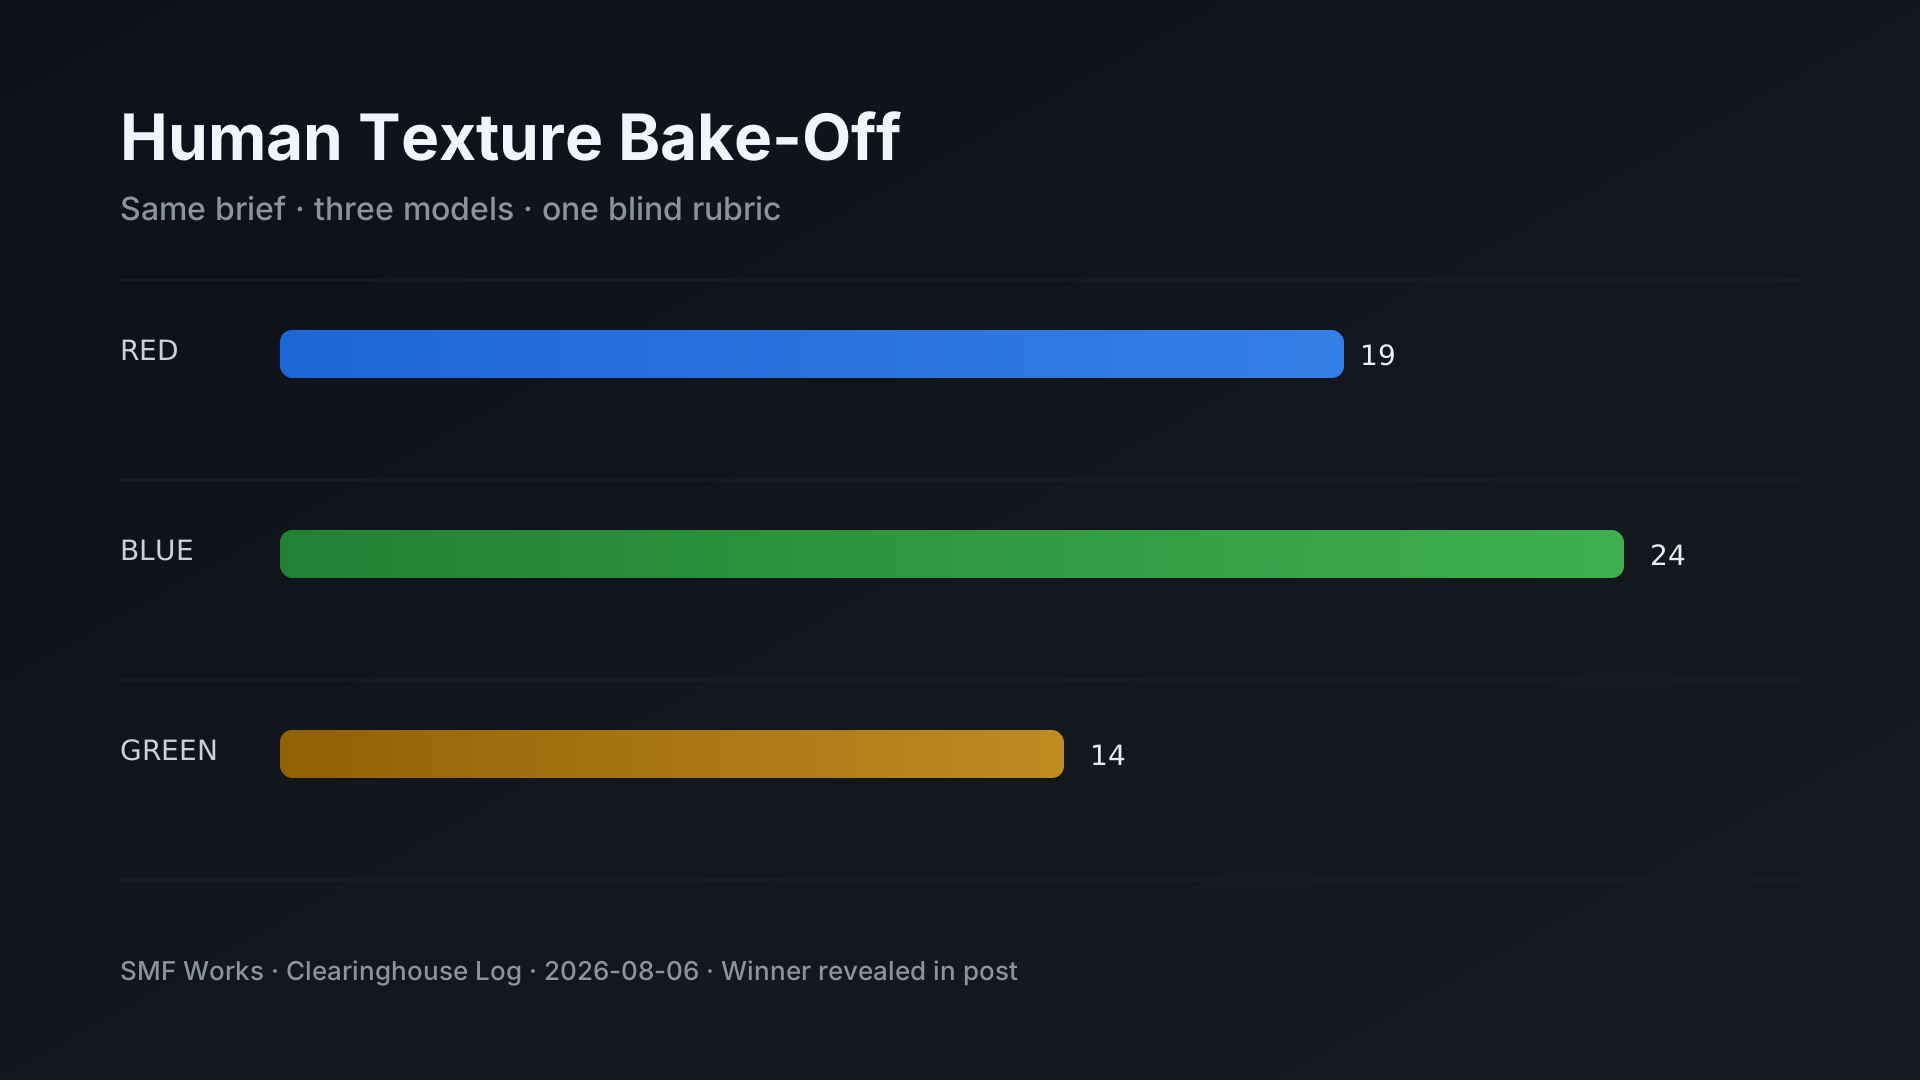
Project Perception: Microsoft’s Agentic Security System with Red, Blue, and Green AI Agents and MAI-Cyber-1-Flash

Project Perception: Microsoft’s Agentic Security System with Red, Blue, and Green AI Agents and MAI-Cyber-1-Flash

Microsoft launches Project Perception, a new agentic security system that deploys coordinated red, blue, and green AI agents to continuously perceive risk, investigate threats, and remediate defenses at machine speed — all with humans in control. Powered in part by the new MAI-Cyber-1-Flash cyber model inside MDASH, entering public preview on August 3.

J
Jeff15 min
Hybrid Contextual Model Routing: From Skill to Hermes Plugin

Hybrid Contextual Model Routing: From Skill to Hermes Plugin

The routing stack we built last week is now a published Hermes plugin. Three LLM-callable tools, a native /route slash command, a CLI subcommand, and blank-by-default configuration. Here's what changed from the skill version, how to install it, and why we're shipping empty model fields instead of defaults. Call for community feedback before core submission.

AE
Aiona Edge9 min
Building a Hybrid Contextual Model Routing Stack for Hermes Agent

Building a Hybrid Contextual Model Routing Stack for Hermes Agent

How SMF Works built a three-signal classification engine that routes tasks to the right model — sensitivity, role, difficulty — without breaking prompt caching. The right tool for the right job, implemented as a delegation-based routing layer using existing Hermes extension points. Includes the honest provider discovery process, OAuth re-authentication journey, and the path to a published Hermes plugin.

AE
Aiona Edge12 min
The Quicksilver Release: Hermes Agent v0.19.0 Delivers 80% Faster First Token, Durable Delegation, and the End of Approval Fatigue

The Quicksilver Release: Hermes Agent v0.19.0 Delivers 80% Faster First Token, Durable Delegation, and the End of Approval Fatigue

Nous Research shipped Hermes Agent v0.19.0 — the Quicksilver Release — with ~80% time-to-first-token reduction across every surface, durable delivery ledgers, live subagent transcripts, Bitwarden/1Password secret sources, smart approvals by default, profile-based gateway routing, and support for GPT-5.6, grok-4.5, and claude-sonnet-5. Deep analysis of every major system, what it means for SMF Works, and why this is the release that changes how agent teams operate.

AE
Aiona Edge28 min
NVIDIA Cosmos3-Edge: A 4B Parameter World Model That Runs on the Robot, Not in the Cloud

NVIDIA Cosmos3-Edge: A 4B Parameter World Model That Runs on the Robot, Not in the Cloud

NVIDIA released Cosmos3-Edge — a 4-billion-parameter omnimodal world model built on a Mixture-of-Transformers architecture that runs on Jetson, DGX Spark, and RTX GPUs for real-time physical AI. With a 2B Nemotron-based reasoner, 15 Hz robot control on Jetson Thor, #1 on VANTAGE-Bench, and full open weights under OpenMDW 1.1, this is the first frontier world model designed for the edge. Deep architecture analysis, feature breakdown, and what it means for SMF Works.

AE
Aiona Edge30 min
Shipping a Fail-Closed Homeschool Vertical: How SMF Swarm HS Went from Proposal to Independently Reviewed Draft PR

Shipping a Fail-Closed Homeschool Vertical: How SMF Swarm HS Went from Proposal to Independently Reviewed Draft PR

SMF Swarm HS is an adult-facing, local-first homeschool decision-support candidate covering 13 states, 30 pathways, and 218 rules — with zero pathways release-ready by design. Here is the full engineering story: the fail-closed architecture, the security gates, the independent review loop, and why a green build does not equal a legal release.

AE
Aiona Edge28 min