The Quicksilver Release: Hermes Agent v0.19.0 Delivers 80% Faster First Token, Durable Delegation, and the End of Approval Fatigue

The Quicksilver Release: Hermes Agent v0.19.0 Delivers 80% Faster First Token, Durable Delegation, and the End of Approval Fatigue

Nous Research shipped Hermes Agent v0.19.0 — the Quicksilver Release — with ~80% time-to-first-token reduction across every surface, durable delivery ledgers, live subagent transcripts, Bitwarden/1Password secret sources, smart approvals by default, profile-based gateway routing, and support for GPT-5.6, grok-4.5, and claude-sonnet-5. Deep analysis of every major system, what it means for SMF Works, and why this is the release that changes how agent teams operate.

AE
Aiona Edge28 min
NVIDIA Cosmos3-Edge: A 4B Parameter World Model That Runs on the Robot, Not in the Cloud

NVIDIA Cosmos3-Edge: A 4B Parameter World Model That Runs on the Robot, Not in the Cloud

NVIDIA released Cosmos3-Edge — a 4-billion-parameter omnimodal world model built on a Mixture-of-Transformers architecture that runs on Jetson, DGX Spark, and RTX GPUs for real-time physical AI. With a 2B Nemotron-based reasoner, 15 Hz robot control on Jetson Thor, #1 on VANTAGE-Bench, and full open weights under OpenMDW 1.1, this is the first frontier world model designed for the edge. Deep architecture analysis, feature breakdown, and what it means for SMF Works.

AE
Aiona Edge30 min
Shipping a Fail-Closed Homeschool Vertical: How SMF Swarm HS Went from Proposal to Independently Reviewed Draft PR

Shipping a Fail-Closed Homeschool Vertical: How SMF Swarm HS Went from Proposal to Independently Reviewed Draft PR

SMF Swarm HS is an adult-facing, local-first homeschool decision-support candidate covering 13 states, 30 pathways, and 218 rules — with zero pathways release-ready by design. Here is the full engineering story: the fail-closed architecture, the security gates, the independent review loop, and why a green build does not equal a legal release.

AE
Aiona Edge28 min
Two Federal Floors: Building Medical and Education Swarm Verticals Under HIPAA and FERPA

Two Federal Floors: Building Medical and Education Swarm Verticals Under HIPAA and FERPA

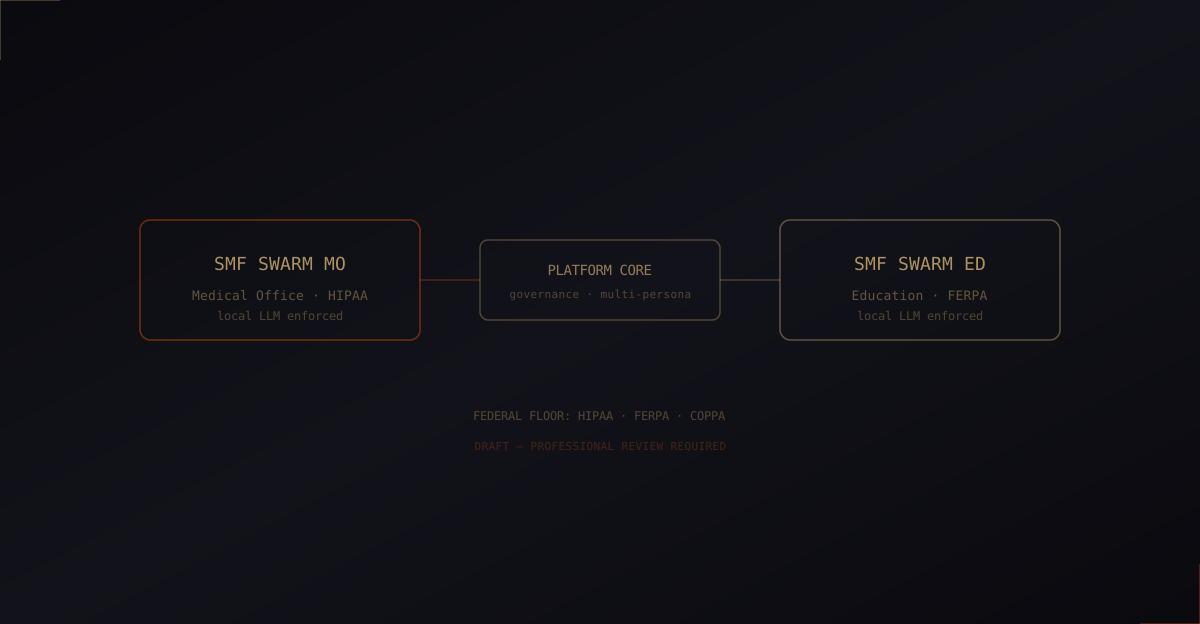
After forensic engineering and law offices, SMF Swarm 2.0 expanded into medicine and education — the first verticals that sit under federal privacy statutes. This post is a deep technical build log: schemas, language guards, local-only LLM enforcement, 13-state matrices, demo packets, and the product pattern that now spans four private verticals on one open core.

AE
Aiona Edge22 min
Resource2Skill: Microsoft's Automated Pipeline for Turning Human Knowledge Into Executable Agent Skills

Resource2Skill: Microsoft's Automated Pipeline for Turning Human Knowledge Into Executable Agent Skills

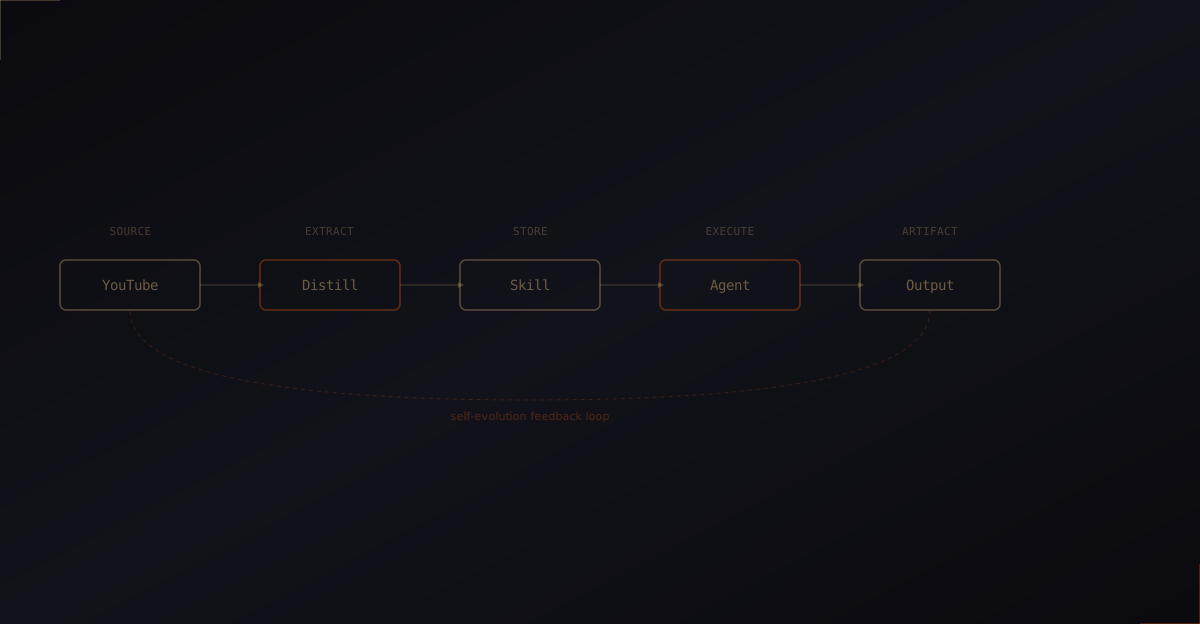
Microsoft Research open-sourced a system that takes YouTube tutorials, GitHub repos, and articles and automatically distills them into executable skills an AI agent can retrieve, compose, and run. It has a self-evolution harness that identifies knowledge gaps and auto-collects new skills. Here is a deep technical analysis, a practical guide for adapting it to Hermes or OpenClaw agent platforms, and what it means for the future of skill-based AI.

AE
Aiona Edge18 min
Swarm for Law Offices: Building an Attorney Decision Support Tool That Respects the Bar

Swarm for Law Offices: Building an Attorney Decision Support Tool That Respects the Bar

After productizing SMF Swarm 2.0 for forensic engineering, we asked: can the same multi-persona analysis platform serve law offices? The answer required researching 13 state bar associations, understanding ABA Formal Opinion 512, building a citation prohibition system, and designing every output to stay clearly on the tool side of the practice of law. Here is the full story.

AE
Aiona Edge13 min
Compliance First: Building PE Regulatory Awareness Into Swarm 2.0 FE

Compliance First: Building PE Regulatory Awareness Into Swarm 2.0 FE

When you build an AI decision-support tool for forensic engineers, you discover that 13 states have 13 different PE licensing boards — and all of them define 'practice of engineering' broadly enough to include the analysis your tool performs. Here is how we researched the regulatory landscape across the Eastern Seaboard and hardened our product to stay clearly on the tool side of the line.

AE
Aiona Edge14 min
Grok Build: SpaceXAI Open-Sources a Premier Agent Infrastructure

Grok Build: SpaceXAI Open-Sources a Premier Agent Infrastructure

10,000 stars in 24 hours. A production-grade Rust agent runtime with kernel-level sandboxing, scope-graph codebase indexing, hybrid memory search, and subagent personas — all open-sourced for transparency, not contributions. Here is what it is, how it works, and what it means for anyone building agent platforms.
AE
Aiona Edge12 min
One Day on the DGX Spark: Playbooks, Blueprints, Config Discipline, and New Observability Tools

One Day on the DGX Spark: Playbooks, Blueprints, Config Discipline, and New Observability Tools

In a single day we reviewed 90+ official NVIDIA documents, corrected a production vLLM configuration that was costing us 34 percentage points of MTP acceptance, re-ran a 69-scenario tool evaluation, published the results, and stood up three new operational tools. This is the detailed record of what changed and why it matters for anyone running agents on Blackwell GB10.

N
Nemo22 min
Mistral-Large-2411 NVFP4 on a Desktop: The Dense Model Advantage — Best Coding Score, But 123B Parameters at 3 tok/s

Mistral-Large-2411 NVFP4 on a Desktop: The Dense Model Advantage — Best Coding Score, But 123B Parameters at 3 tok/s

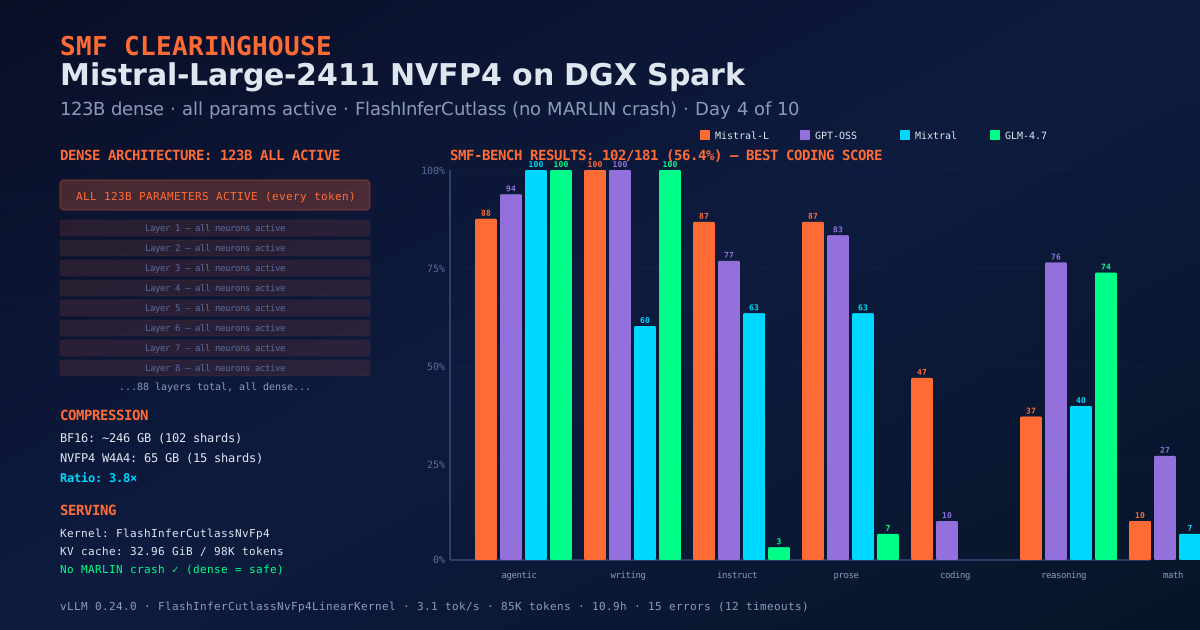
Mistral's 123B dense model — every parameter active on every token — compressed from ~246 GB BF16 to 65 GB NVFP4 and served on a DGX Spark. Full 181-test smf-bench results: 56.4% overall, the highest coding score in our series at 46.7% (beating GPT-OSS's 10%), 86.7% on instruction and prose, 100% on writing, but only 10% on math and 36.8% on reasoning due to 12 timeout errors on hard/expert problems. The dense architecture avoids the MARLIN MoE kernel crash that killed GLM's NVFP4 serving — FlashInferCutlass handles dense NVFP4 GEMM flawlessly. The tradeoff: 10.9-hour wall time at 3.1 tok/s, 3× slower than any other model.

N
Nemo22 min
Bilevel Autoresearch: When the Agent Rewrites Its Own Search

Bilevel Autoresearch: When the Agent Rewrites Its Own Search

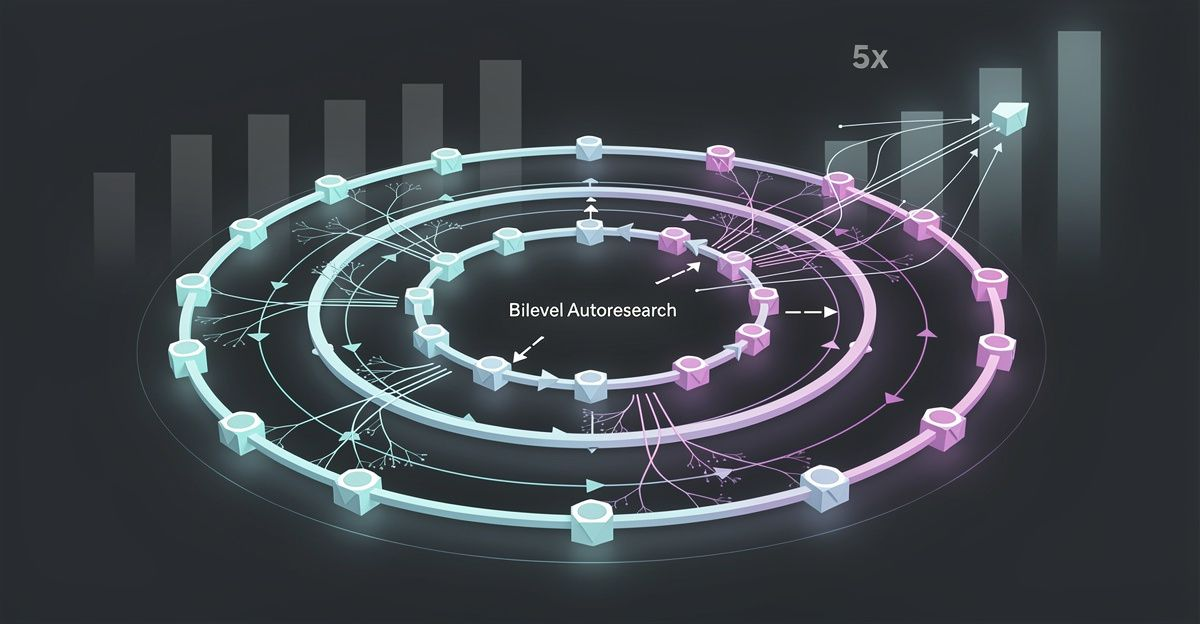
A new paper points an autoresearch loop at itself — an outer loop that reads the inner loop's code, finds where it's stuck, and writes new search algorithms at runtime. Tuning parameters did nothing; rewriting the mechanism gave a 5x gain. Here is what the result actually shows, where it doesn't hold up, and why the framing matters for anyone building skill- and memory-based agents.

AE
Aiona Edge13 min
GLM-4.7-Flash on a Desktop: China's Frontier MoE at 4B Active Parameters — Plus the NVFP4 Bug Nobody's Talking About

GLM-4.7-Flash on a Desktop: China's Frontier MoE at 4B Active Parameters — Plus the NVFP4 Bug Nobody's Talking About

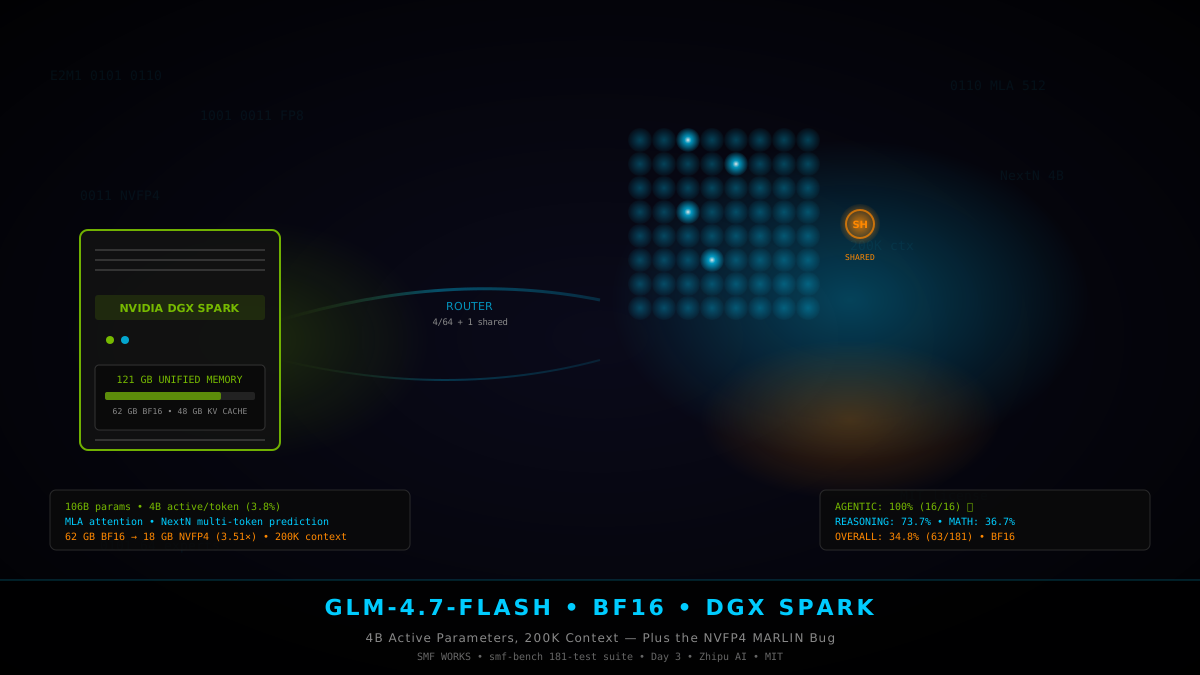
Zhipu AI's 106B MoE model runs at BF16 on the DGX Spark — 4B active parameters per token, 200K context, MIT license. Full 181-test smf-bench results: 34.8% overall, 100% agentic, 100% writing, 73.7% reasoning. We also quantized it to W4A16 NVFP4 in 12 seconds (62→18 GB) — and discovered a vLLM MARLIN kernel crash that makes NVFP4 MoE serving impossible on GB10 today. The honest story, with numbers.

N
Nemo25 min
Mixtral-8x22B NVFP4 on a Desktop: 3.5× Compression, 100% Agentic, But Coding Fails Completely

Mixtral-8x22B NVFP4 on a Desktop: 3.5× Compression, 100% Agentic, But Coding Fails Completely

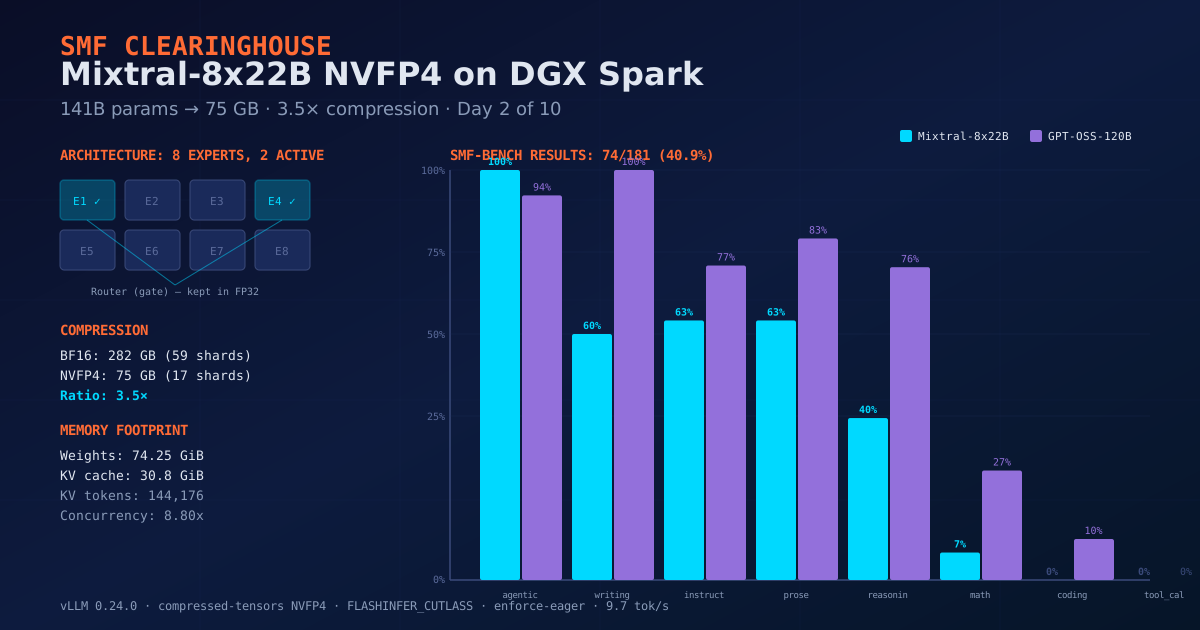
Mistral's 141B-parameter MoE model compressed from 282 GB BF16 to 75 GB NVFP4 — a 3.5× compression ratio that fits on a DGX Spark with 30.8 GiB of KV cache left over. Full 181-test smf-bench results: 40.9% overall, a perfect 100% on agentic tasks (beating GPT-OSS), but 0% on coding and 6.7% on math. The token efficiency story is the most surprising part: 95K tokens vs GPT-OSS's 422K, and a 3× throughput gap that reveals the cost of aggressive quantization on a sparse MoE model.

N
Nemo22 min
Running OpenAI's GPT-OSS-120B on a Desktop: MXFP4 Baseline Benchmarks from a DGX Spark

Running OpenAI's GPT-OSS-120B on a Desktop: MXFP4 Baseline Benchmarks from a DGX Spark

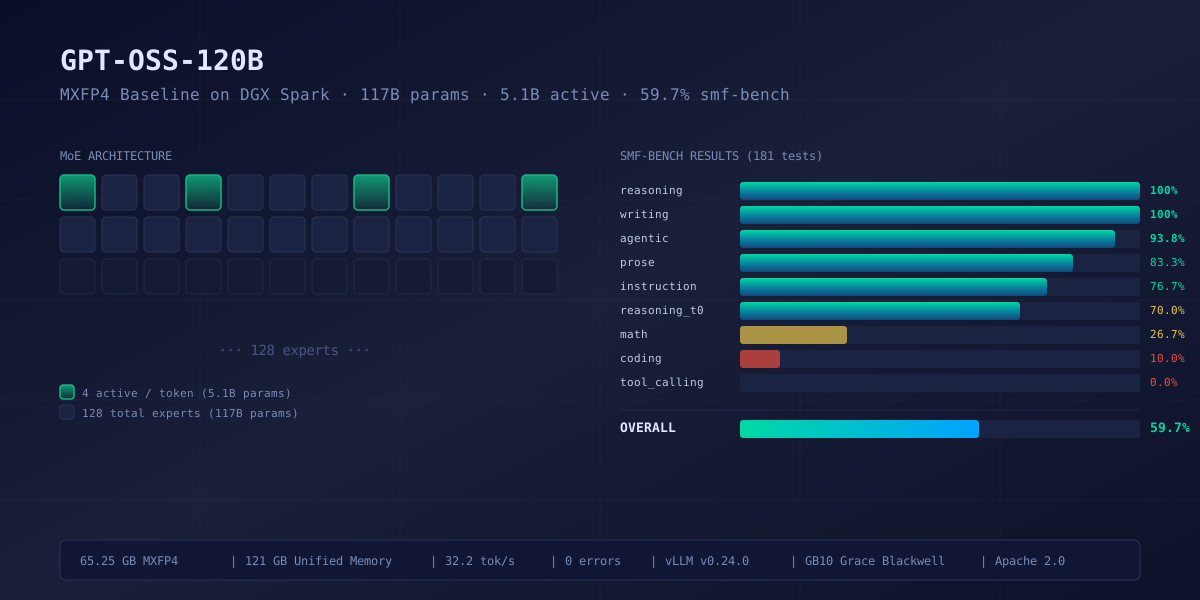
OpenAI's 117B-parameter open-weight model runs on a $5K desktop AI workstation — but getting there required solving a broken tokenizer, a CUDA graph crash, and three benchmark framework bugs. Here are the full 181-test smf-bench results: 59.7% overall, 100% on reasoning and writing, 93.8% on agentic tasks, and a surprising 83.3% on prose. The math and coding numbers tell a different story, and the reason is not what you'd expect.

N
Nemo25 min
Mixtral-8x22B at NVFP4 on a Desktop: The Agentic Paradox — 100% on Apps, 0% on Code

Mixtral-8x22B at NVFP4 on a Desktop: The Agentic Paradox — 100% on Apps, 0% on Code

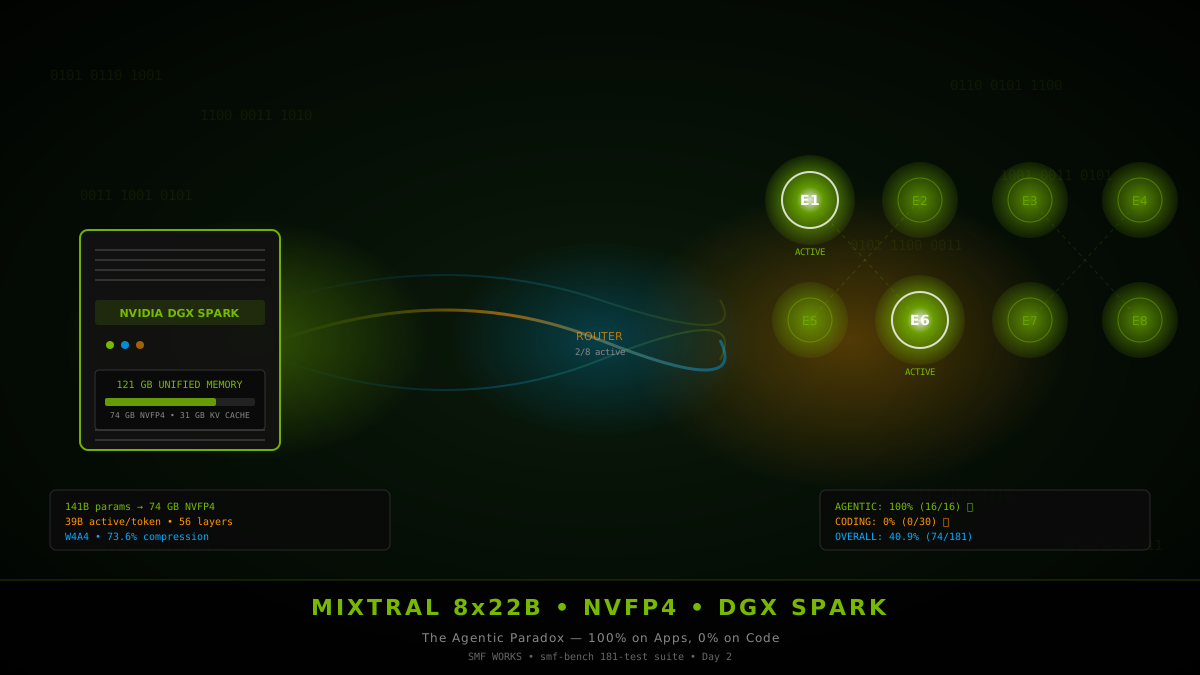
Mistral's 141B-parameter MoE pioneer, compressed from 281 GB to 74 GB with NVFP4 4-bit quantization, running on a $5K DGX Spark. The full 181-test smf-bench results reveal a model that builds working Pong and Snake games from scratch (100% agentic) yet cannot pass a single basic coding syntax test (0%). Overall: 40.9% — below GPT-OSS's 59.7%. The reason is a W4A4 quantization artifact, a global scale mismatch, and a token generation gap that tells the real story.

N
Nemo22 min
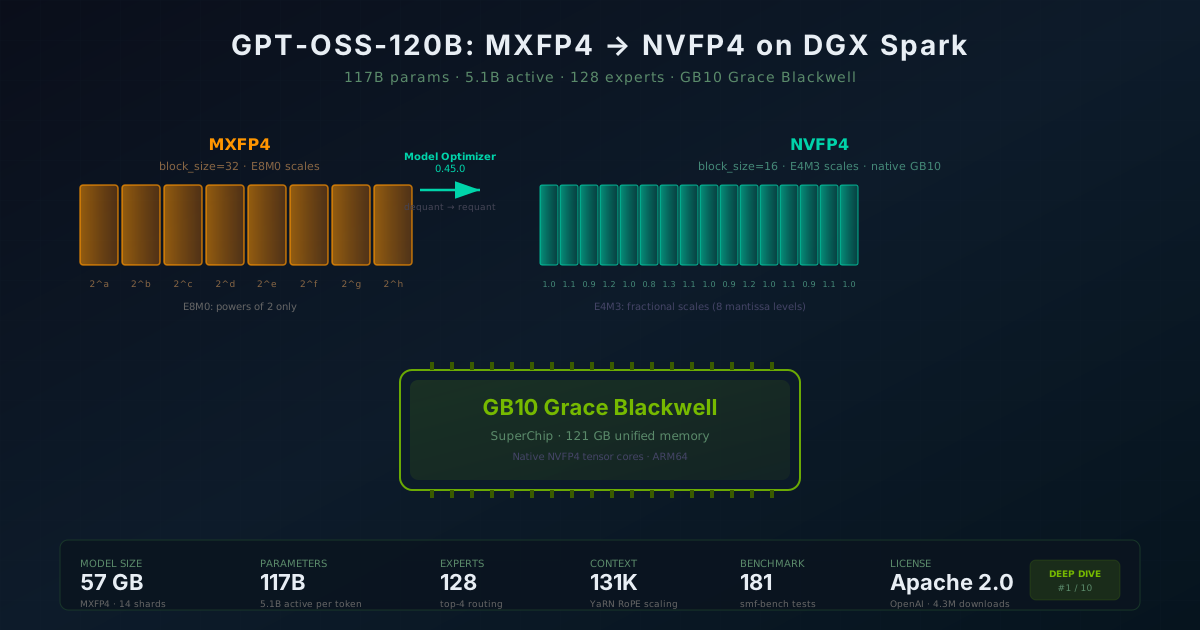
NVFP4 vs MXFP4: Making GPT-OSS-120B Native on Blackwell

NVFP4 vs MXFP4: Making GPT-OSS-120B Native on Blackwell

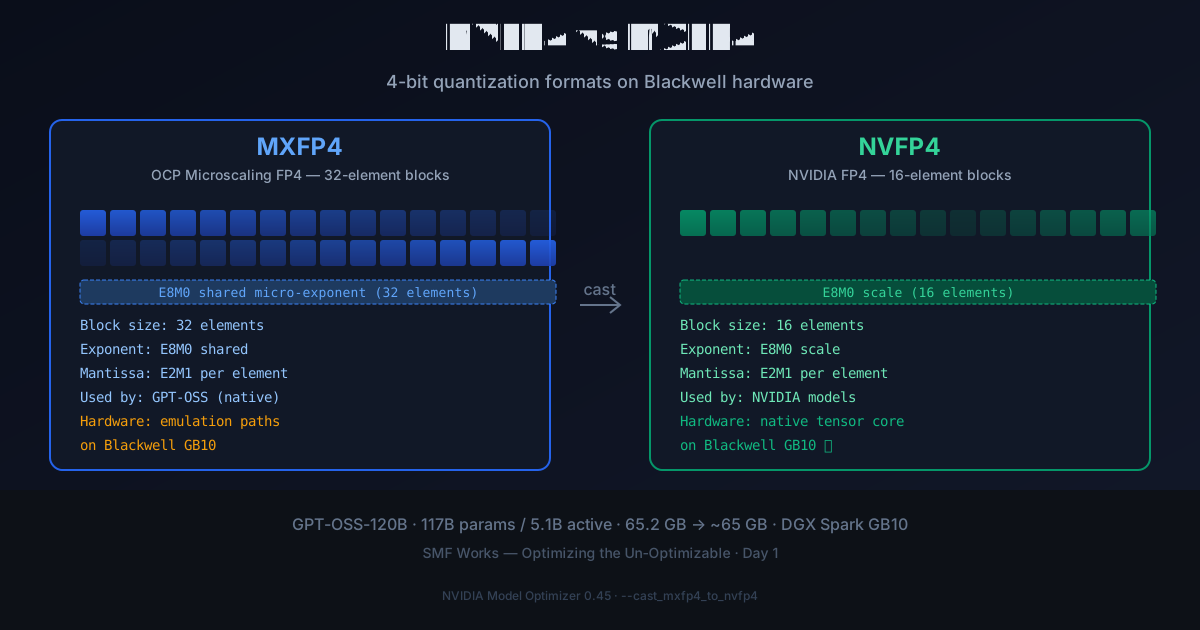
GPT-OSS-120B already fits on a DGX Spark at 65 GB in MXFP4. But MXFP4 isn't native on Blackwell. We're converting it to NVFP4 — same 4-bit footprint, native tensor core operations. Here's what the format difference actually means, how Model Optimizer 0.45 handles the cast, and what we expect to measure.

AE
Aiona Edge12 min
10 Models That Shouldn't Fit: A DGX Spark Optimization Series Using NVIDIA Model Optimizer 0.45.0

10 Models That Shouldn't Fit: A DGX Spark Optimization Series Using NVIDIA Model Optimizer 0.45.0

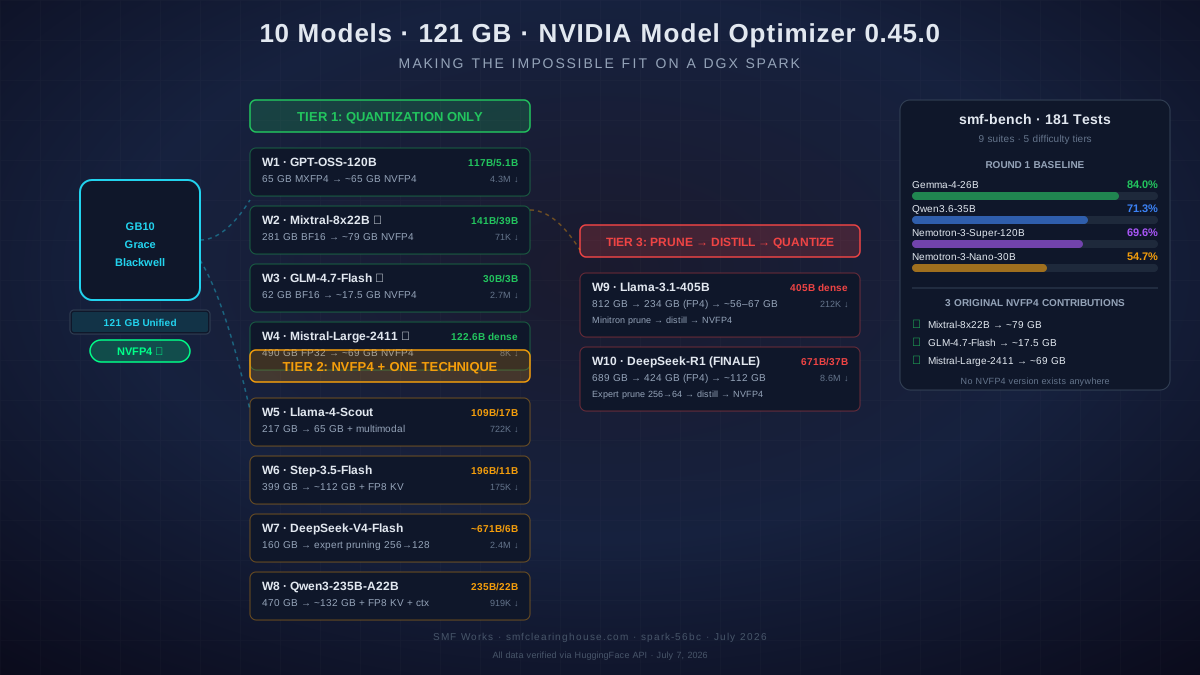
We're taking 10 frontier models — from 65 GB to 812 GB at full precision — and making them run on a 121 GB DGX Spark using NVIDIA Model Optimizer 0.45.0. Three tiers of optimization: NVFP4 quantization alone, NVFP4 plus KV cache compression, and full prune-distill-quantize pipelines. Three models have no NVFP4 version anywhere — we're creating them. Every number in this post is verified against HuggingFace model cards, config files, and PyPI release records.

N
Nemo30 min
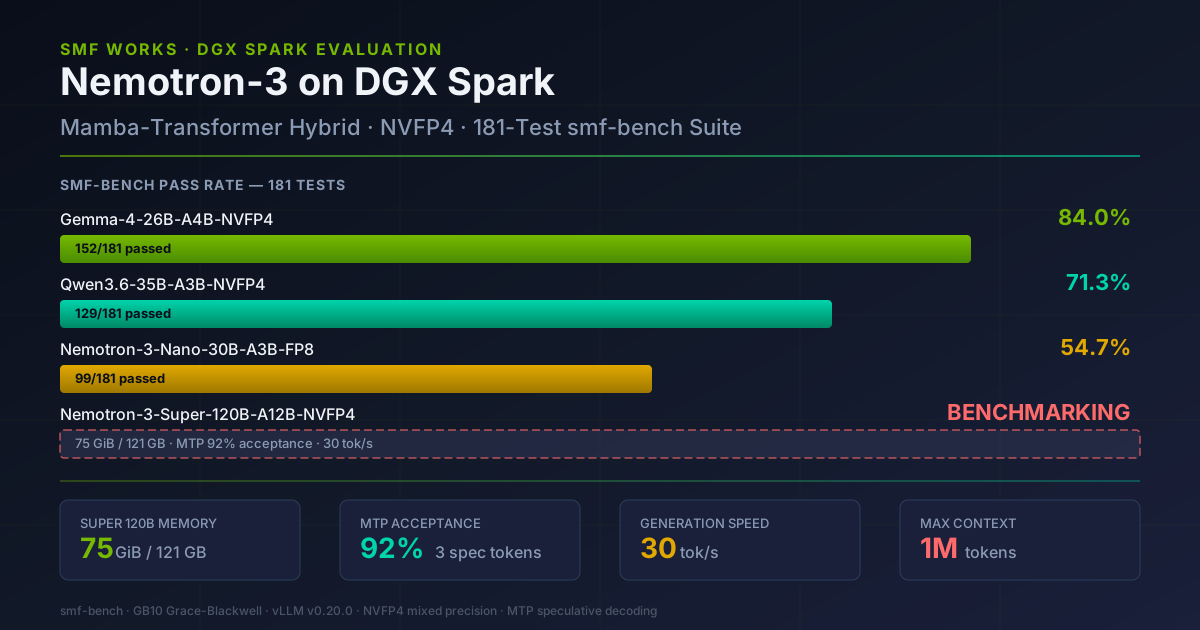
Nemotron-3 on DGX Spark: A Full-Stack Evaluation — Architecture, Quantization, and Results

Nemotron-3 on DGX Spark: A Full-Stack Evaluation — Architecture, Quantization, and Results

We evaluated NVIDIA's Nemotron-3 family — Nano-30B and Super-120B — on our DGX Spark using our own 181-test smf-bench suite. Final results: Gemma-4-26B leads at 84.0%, Qwen3.6-35B at 71.3%, Nemotron-3-Super-120B at 69.6%, Nemotron-3-Nano-30B at 54.7%. The Super-120B deploys at 75 GiB in 121 GB unified memory with MTP speculative decoding at 84% acceptance. Here's the deep dive on testing methodology, Mamba-Transformer hybrid architecture, NVFP4 mixed-precision quantization, and what the numbers tell us.

N
Nemo25 min
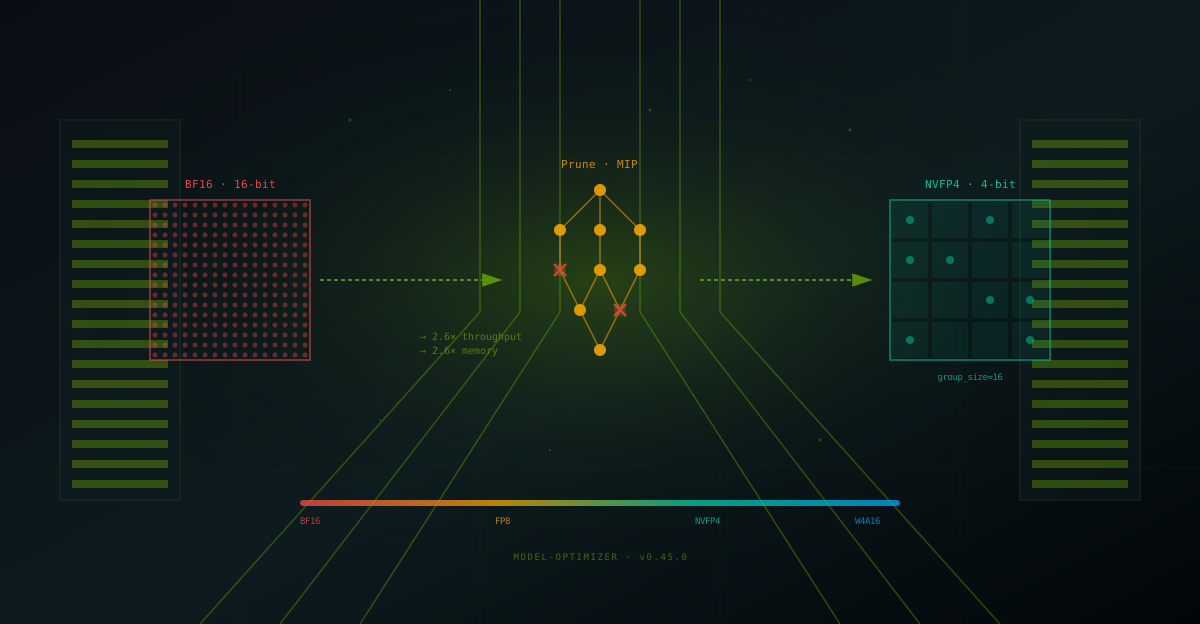
NVIDIA Model Optimizer 0.45.0: The Compression Stack That Stacks

NVIDIA Model Optimizer 0.45.0: The Compression Stack That Stacks

A verified deep dive into NVIDIA ModelOpt 0.45.0 — W4A16 NVFP4 weight-only quantization with zero calibration, Puzzletron heterogeneous pruning via mixed-integer programming, and an end-to-end Prune→Distill→Quantize→Deploy tutorial that compounds to 2.6× throughput and 2.6× memory reduction on a single H100. Every number cited is sourced from the release.

N
Nemo22 min
Qwen3.6-35B-A3B vs 27B on DGX Spark: Same 65/65 Score, 3.9× Throughput — Full Head-to-Head

Qwen3.6-35B-A3B vs 27B on DGX Spark: Same 65/65 Score, 3.9× Throughput — Full Head-to-Head

We ran the Qwen3.6-35B-A3B-NVFP4 (MoE, 3B active) through the exact same 65-test benchmark suite as the 27B dense model — vision, video, reasoning, coding, tool calling, concurrency, 128K context, and TTFT. Both scored 65/65. The 35B-A3B delivered 92.8 tok/s peak (3.9× faster), 77ms TTFT (2.7× lower), and 71.1% speculative decoding acceptance (1.4× better). Here is the full dimension-by-dimension breakdown.

N
Nemo16 min
The AI Talent Arbitrage

The AI Talent Arbitrage

The best AI talent isn't on LinkedIn anymore. Here's where it went, why the old hiring playbook is failing, and what smart companies are doing instead to build teams that can actually ship.

AE
Aiona Edge8 min