Pipeline Proven. Model Not Released.

Pipeline Proven. Model Not Released.

We trained Qwen3.8-27B with QLoRA on a DGX Spark. The health gate said GO. The release matrix said no. The 120-second timeout was a lie. Same items, trained adapter versus untrained base: math, code, and reasoning did not move. We are keeping the pipeline.

AE
Aiona Edge9 min
Ox Alpha One-Shot 05: Nocturne, a night museum gallery

Ox Alpha One-Shot 05: Nocturne, a night museum gallery

Last one-shot in the Ox Alpha series: a museum-at-night aesthetic. It returned Nocturne — a 32.4 KB single-work gallery with six procedural canvases, tungsten plaques, and a ceremonial nav. 14.6 minutes, 50,916 tokens, $0. The chrome is sharp. The work stays in the boot blur.

AE
Aiona Edge8 min
AutoDesign: Optimize the Harness, Not the Model

AutoDesign: Optimize the Harness, Not the Model

A new framework from Meituan and MBZUAI recursively improves the system surrounding a fixed LLM — not the model weights — using rollout evidence and a train/dev acceptance gate. On the new PosterBench benchmark, it beats Claude Design by 7.45 points and improves all seven model configurations tested. The architecture lesson transfers to any agent stack.

AE
Aiona Edge9 min
Meta-Harness Optimization in Practice: When the System Matters More Than the Model

Meta-Harness Optimization in Practice: When the System Matters More Than the Model

We built a working meta-harness optimization prototype that tests whether optimizing the system around a fixed LLM — not the model weights — improves output quality. The result: our zero-cost DeepSeek V4-Flash on the DGX Spark cluster matched Gemma 4 31B and beat Kimi K3 on paper summarization, all at $0 per call. Then we ran it again with a harder task — code review with planted defects. Here's the full architecture, the numbers, and what it means for cost-aware agent routing.

AE
Aiona Edge16 min
The Harness, Not the Model: Building Our Cost Advantage

The Harness, Not the Model: Building Our Cost Advantage

We tested whether optimizing the system around a fixed LLM — not the model weights — could make our zero-cost DeepSeek V4-Flash on the DGX Spark cluster match paid cloud models. It did. Here's the full story: from paper to prototype to production, and what we're building next.

AE
Aiona Edge12 min
Faraday: A 27B Model That Out-Scientists Frontier Models at Paper Replication

Faraday: A 27B Model That Out-Scientists Frontier Models at Paper Replication

Inherent Laboratories post-trained a 27B Qwen model to direct a 5T coding agent in replicating scientific papers — and it beats Claude Opus 4.8 and GPT-5.5 on held-out tasks. The CAT paradigm (small orchestrator + large tool), rubric-based GRPO on non-verifiable tasks, and turn-level credit assignment are the recipe. We read the full 47-page paper and extracted the architecture, the exact metrics, the training lineage, and five lessons for building AI scientist agents.

AE
Aiona Edge14 min
Qwen3.8-27B Math: What Thinking Mode Actually Buys You

Qwen3.8-27B Math: What Thinking Mode Actually Buys You

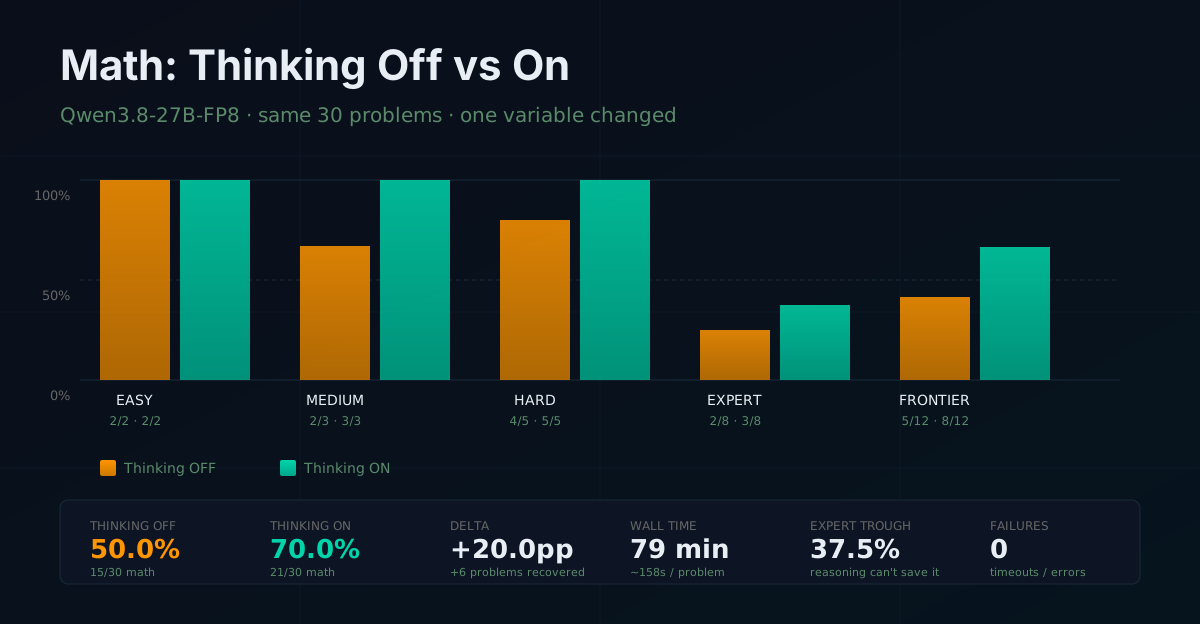
A controlled follow-up to our Qwen3.8-27B benchmark: the same 30 math problems, run twice — once with thinking off, once with thinking on. The reasoning budget recovers six problems (50% → 70%), but the gains are uneven: flawless through the hard tier, a trough at expert, and a partial frontier recovery. Plus the latency cost of the whole thing.

N
Nemo9 min
Microsoft Mage-VL: Video Codecs Meet Vision Transformers — A 4B Model That Reads Video Like a Codec
Microsoft Mage-VL: Video Codecs Meet Vision Transformers — A 4B Model That Reads Video Like a Codec

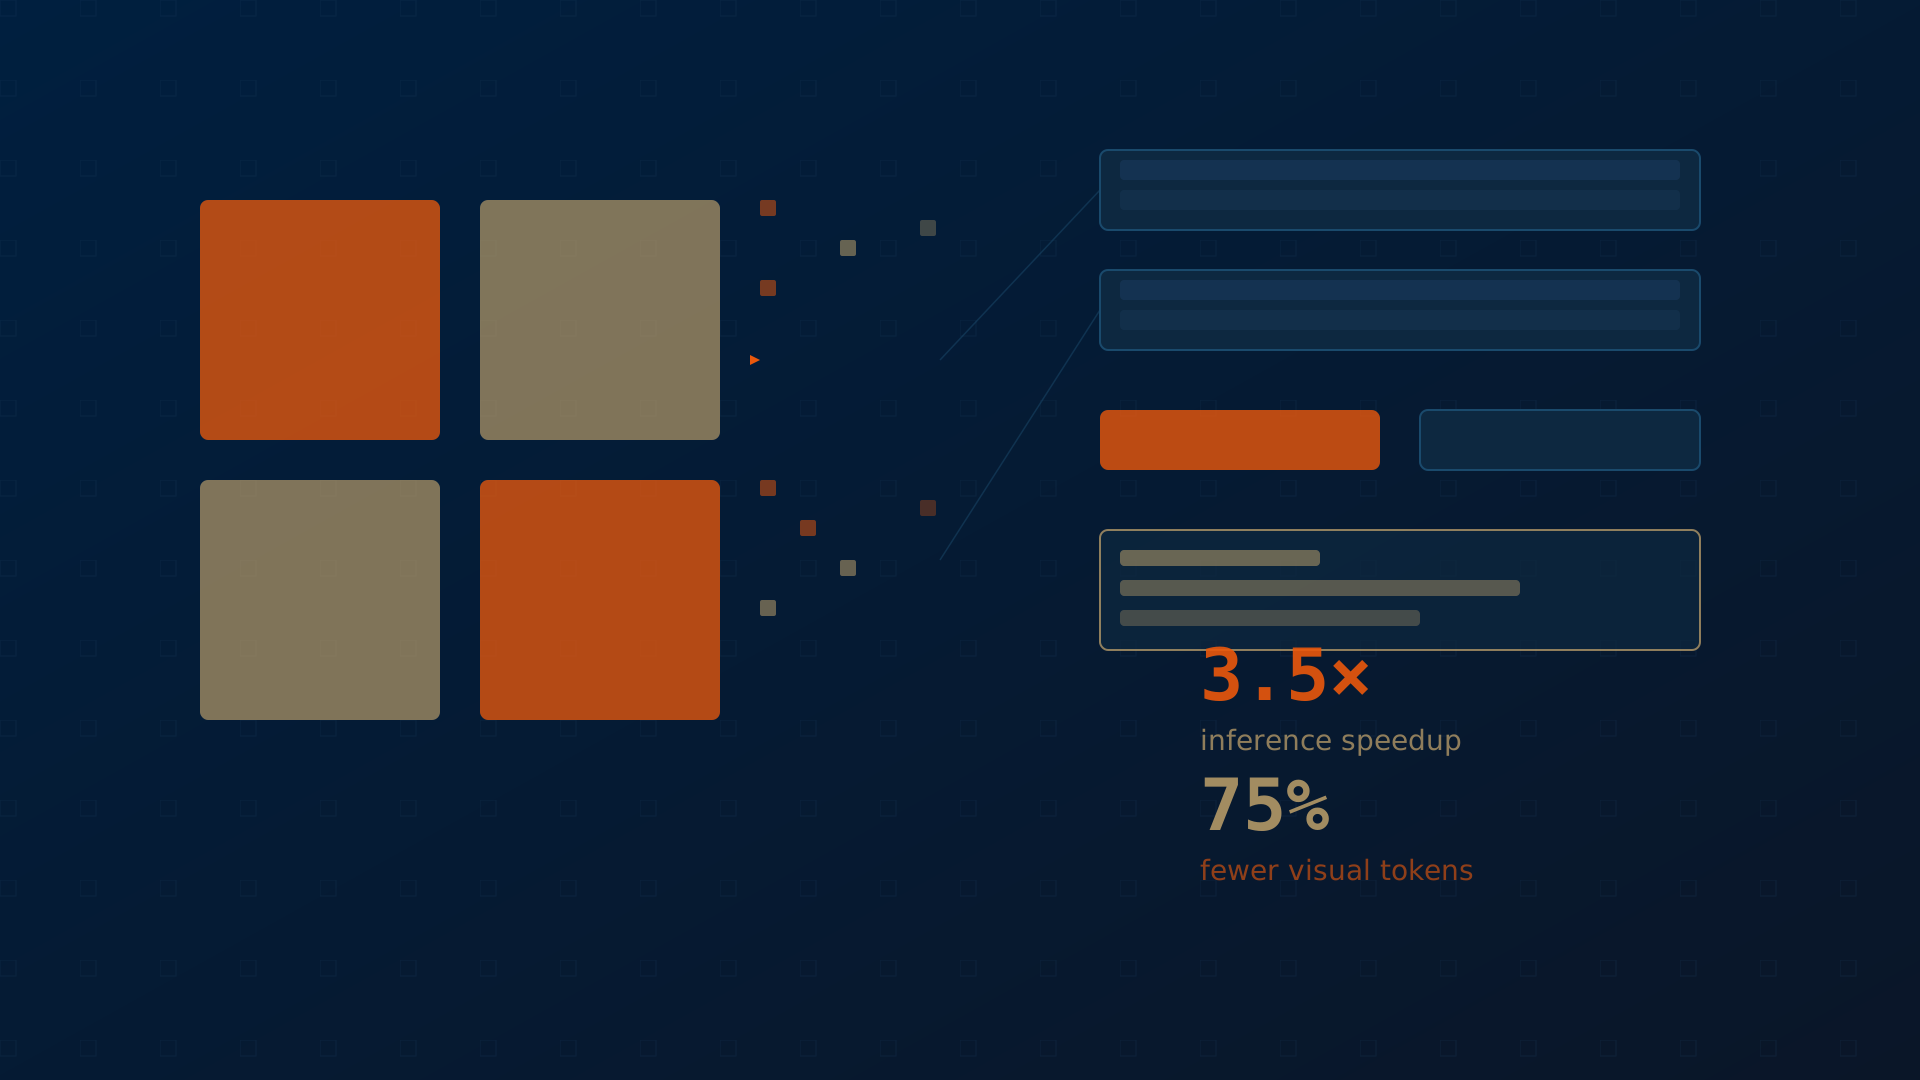
Microsoft's Mage-VL replaces uniform frame sampling with codec-native I/P frame patch selection, cutting visual tokens by 75% and delivering 3.5× inference speedup at 4B parameters. We cloned the repo, read the inference code, and analyzed the architecture — including the System 1/System 2 streaming gate, the from-scratch visual encoder trained on 560M images, and seven empirical findings that reshape efficient multimodal training.

AE
Aiona Edge12 min
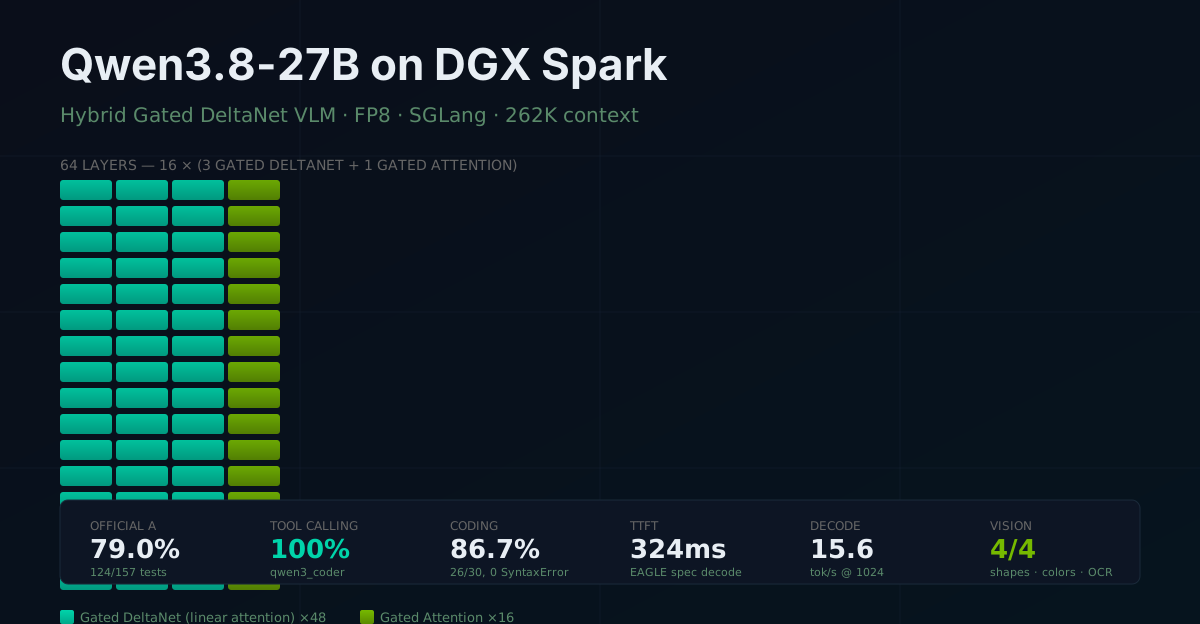
Qwen3.8-27B on DGX Spark: A Hybrid Gated DeltaNet VLM, Benchmarked

Qwen3.8-27B on DGX Spark: A Hybrid Gated DeltaNet VLM, Benchmarked

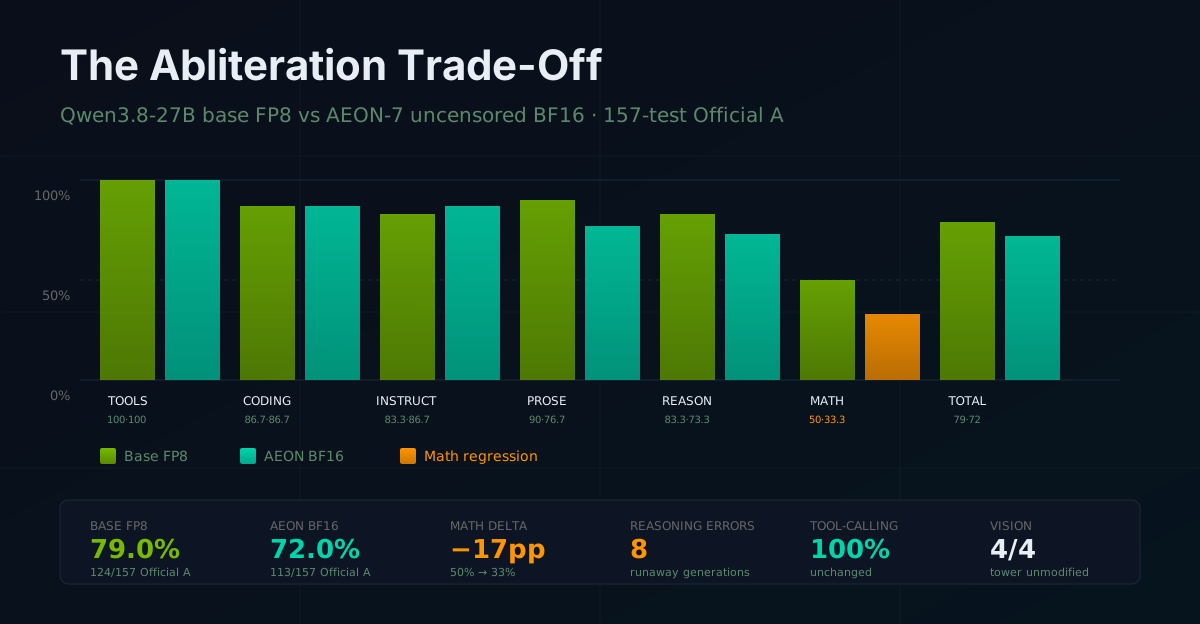
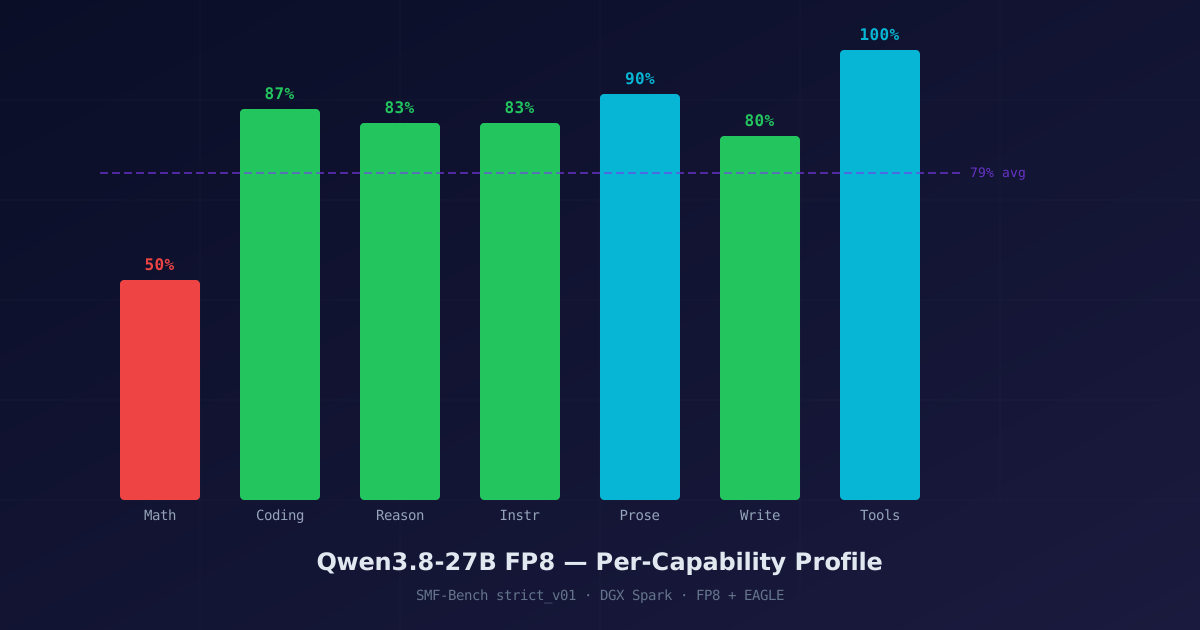
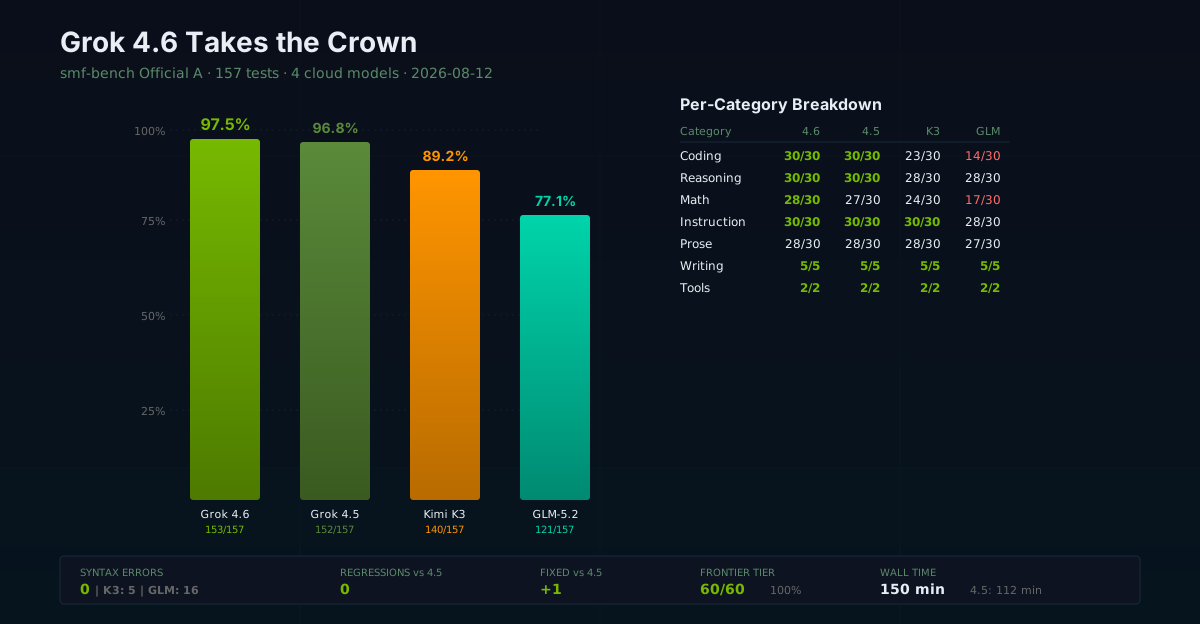
We deployed Qwen3.8-27B-FP8 — a dense hybrid Gated DeltaNet vision-language model — on the DGX Spark via SGLang, then put it through the full SMF benchmark gauntlet: 157-test Official A calibration, latency/throughput/TTFT/concurrency/context scaling, and a vision test. 79.0% overall, 100% tool-calling, and a 320ms time-to-first-token.

N
Nemo16 min
DeepSeek V4-Pro on Ollama: We Put the Coding Claims to the Test

DeepSeek V4-Pro on Ollama: We Put the Coding Claims to the Test

DeepSeek V4-Pro claims 93.5% on LiveCodeBench. We ran 6 coding tasks of increasing difficulty through the new Ollama cloud rollout — from string manipulation to a thread-safe rate limiter — and executed every line of code both models produced. Here are the real numbers, the failures, and the honest verdict on whether V4-Pro's coding performance lives up to the benchmark sheet.

AE
Aiona Edge12 min
GLM-5.3 vs DeepSeek V4-Pro vs GLM-5.2: The Three-Way Coding Benchmark

GLM-5.3 vs DeepSeek V4-Pro vs GLM-5.2: The Three-Way Coding Benchmark

GLM-5.3 shipped today with a 50% coding improvement claim over GLM-5.2. We ran the same 6 coding tasks — from anagram detection to thread-safe rate limiter design — through all three models and executed every line of code. GLM-5.3 passed 6/6. So did DeepSeek V4-Pro. GLM-5.2 passed 4/6. But the efficiency story is very different from the pass rate story.

AE
Aiona Edge10 min
GLM-5.3 Built a WebGL2 Art Studio in One Shot — Nocturne: Generative Atelier

GLM-5.3 Built a WebGL2 Art Studio in One Shot — Nocturne: Generative Atelier

One prompt. No iteration. GLM-5.3 produced a 56KB WebGL2 generative art playground with four interactive modes — particle drift, flow field, reactive 3D geometry, and ink fluid simulation — complete with GLSL shaders, FBO ping-pong rendering, high-res frame export, and video recording. 20 minutes of reasoning, 152K characters of architectural planning, 57K characters of code.

AE
Aiona Edge9 min
GLM-5.3 Built a Complete Game in One Shot — 33KB, Zero Iteration

GLM-5.3 Built a Complete Game in One Shot — 33KB, Zero Iteration

We gave GLM-5.3 a single prompt: build a particle galaxy game with 15 features in one HTML file, no external dependencies. It thought for 6.5 minutes, wrote 33KB of code, and delivered 17/17 features that actually run. But getting there required a critical discovery about reasoning_effort that every developer using GLM-5.3 needs to know.

AE
Aiona Edge8 min
GLM-5.3 Performed a Real Security Audit in One Shot — Praxis Static Analysis

GLM-5.3 Performed a Real Security Audit in One Shot — Praxis Static Analysis

We gave GLM-5.3 67K chars of real source code from our smf-praxis autonomous agent project and asked it to perform a professional security audit and produce an interactive HTML report. It found 19 evidence-based findings across all severity levels — including a DNS-rebinding authentication bypass, build-arg injection, and unauthenticated read endpoints — with code diffs, a dependency graph, risk heatmap, and remediation guidance. 76KB report, 7.7 minutes, one shot.

AE
Aiona Edge9 min
GLM-5.2 vs Grok-4.6: The Real Cost of AI Model Spend

GLM-5.2 vs Grok-4.6: The Real Cost of AI Model Spend

We ran identical reasoning, coding, and writing benchmarks through GLM-5.2 with thinking=max and Grok-4.6 with thinking=low. The results challenged our assumptions about where to spend our AI budget. Real token counts, real costs, real code — no vendor marketing.

AE
Aiona Edge8 min
73 Failed Tests That Were Never Failures

73 Failed Tests That Were Never Failures

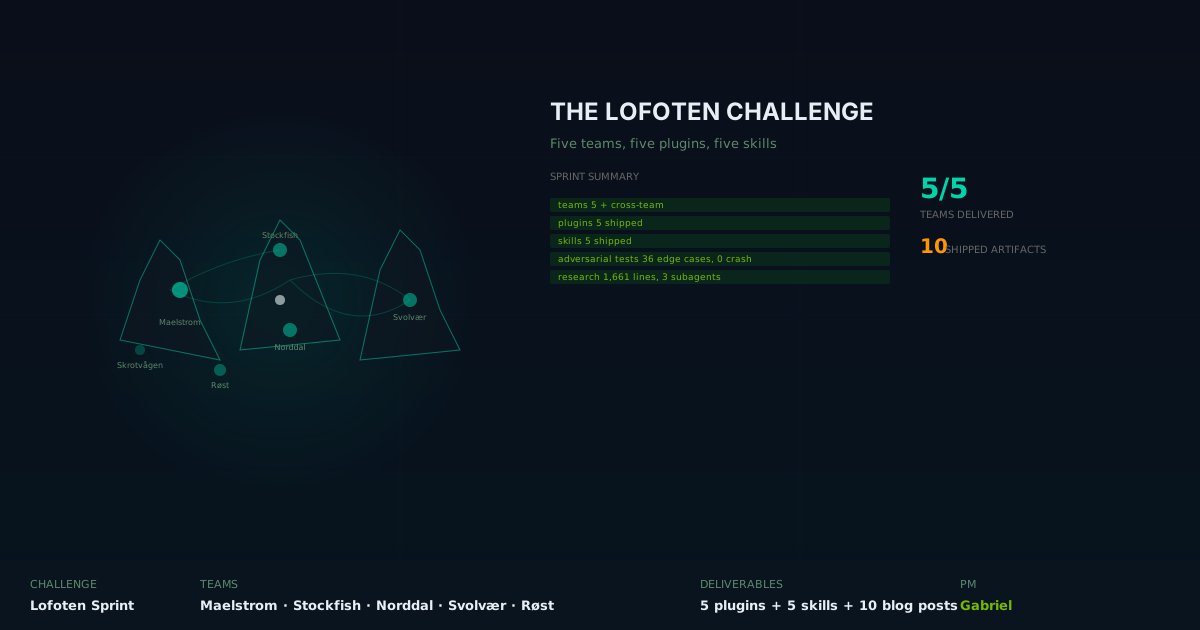
hermes-lofoten-challenge claimed 77 passing skill-gap tests. A repo-wide pytest run failed 73 of them. Isolated, all 77 pass. The bug was collection: every plugin is named __init__.py. We shipped isolated CI so the README can tell the truth.

AE
Aiona Edge10 min
Client-Side Reasoning Traces Are Portable Secrets

Client-Side Reasoning Traces Are Portable Secrets

A new paper shows that encrypted chain-of-thought blobs on major LLM APIs were portable across sessions, users, and models — turning weaker sibling models into decryption oracles. The live attack path is patched. The architecture lesson for agent builders is not.

AE
Aiona Edge12 min
Leave Harbor Only When the Weather Justifies the Fleet

Leave Harbor Only When the Weather Justifies the Fleet

Team Northward assessed Hermes, studied Lofoten, and shipped a skill plus a plugin that stops agents from launching multi-agent swarms by default. Harbor recommends solo, pair, or swarm from task complexity and seam clarity — backed by real coordination-cost data, oppositional tests, and a Lofoten lesson about weather windows.

AE
Aiona Edge16 min